Accelerating Video Generation with GEMM Quantization, Attention Quantization and Skip Softmax Attention in TensorRT-LLM#
By NVIDIA TensorRT-LLM Team
Introduction#
Video diffusion transformers (DiTs) repeatedly process long spatiotemporal token sequences across multiple denoising steps. Linear and attention layers therefore dominate much of the compute, making them the two most direct targets for reducing generation latency.
Figure 1 breaks down pipeline-forward time for Wan 2.2 T2V-A14B on a single NVIDIA B200. For an 81-frame, 1280×720 video with 40 denoising steps, attention and linear-layer GEMMs account for 70.3% and 21.0% of BF16 pipeline-forward time, respectively.

Figure 1. Diffusion pipeline-forward breakdown for Wan 2.2 T2V-A14B in BF16 on B200.
Our earlier post, Scaling Video Generation Across NVL72 Rack with TensorRT-LLM, showed how to accelerate video generation with multiple GPUs. This post focuses on three complementary techniques within one GPU: GEMM quantization, quantized attention, and sparse attention. The central question is how to reduce latency without giving up more visual quality than the application can tolerate.
Table of Contents#
GEMM Quantization#
GEMM quantization reduces the numerical precision of weights and activations so linear-layer GEMMs can use higher-throughput, low-precision Tensor Core paths. TensorRT-LLM VisualGen supports the following GEMM quantization paths:
|
Weight precision |
Weight scaling |
Activation precision |
Activation scaling |
|---|---|---|---|---|
|
FP8 E4M3 |
Per tensor (FP32) |
FP8 E4M3 |
Per tensor (FP32) |
|
FP8 E4M3 |
Per 128×128 block (FP32*) |
FP8 E4M3 |
Per 1×128 block (FP32*) |
|
FP8 E4M3 |
Per output channel (FP32) |
FP8 E4M3 |
Per token (FP32) |
|
FP4 E2M1 |
Per 16-element block (FP8 E4M3), plus a per-tensor scale (FP32) |
FP4 E2M1 |
Per 16-element block (FP8 E4M3), plus a per-tensor scale (FP32) |
* FP8 blockwise scale values use FP32 in the checkpoint and generic interface. On B200, weight scales are converted to UE8M0 and activation scales are generated in UE8M0 for the Blackwell block-scaled MMA.
There are two distinct quantization paths:
Static quantization: Weights are quantized offline. Meanwhile, some representative inputs are forwarded through the network to determine the static scaling factors for the activation. After this procedure of offline quantization and calibration, the quantized weights, weight scales and activation scales are stored in the checkpoint. But note that only per-tensor activation scales will be calibrated offline, such as the FP32 for per-tensor
FP8and the second-level per-tensor inNVFP4. Other activation scales, such as the block scales inNVFP4are still computed dynamically during runtime. In addition, accuracy-sensitive modules can be discovered and remained in higher precision during offline quantization.Dynamic quantization: The original BF16 checkpoint is directly loaded. The weights are quantized to the target precision during loading. The activation is always quantized dynamically during runtime, including the scaling factors, which might be more expensive compared to static quantization path, especially for the per-tensor scales. With dynamic quantization, it is easier to try the target quantization recipe without preparing a dedicated quantized checkpoint, but generally preserves less accuracy than static quantization that could calibrate activation scales and protect sensitive modules.
Static quantization has advantage over dynamic quantization in terms of both speed and accuracy, and should be preferred if possible. The public checkpoints used in this post were quantized with NVIDIA Model Optimizer (ModelOpt). The ModelOpt diffusion PTQ example shows how to calibrate and quantize diffusion models.
Attention Optimizations#
There are two orthogonal directions for accelerating attention: quantized attention lowers numerical precision, while sparse attention uses an attention-score criterion to omit selected KV-block contributions and their corresponding computation. The optimizations introduced in this section are available for the TRTLLM attention backend.
Quantized Attention#
An attention OP performs two matrix multiplications around softmax: QKᵀ produces attention scores, and PV linearly combines the V vectors with weights given by the softmax probabilities P. SAGE Attention quantizes the operands of both operations, allowing QKᵀ and PV to use 8-bit paths. TRTLLM SAGE recipe follows the SageAttention2 line of work, using INT8 or FP8 for QKᵀ and FP8 for PV.
A quantization block is a group of values that shares one scale. The five fields in quant_attention_config define the low-precision formats and scaling granularity used by SAGE Attention:
qk_dtypeselects the low-precision format forQKᵀ. TheTRTLLMSAGE attention kernels supportint8andfp8; this post usesint8.v_dtypeselects the low-precision format forPV. TheTRTLLMSAGE attention kernels currently only supportfp8(E4M3).q_block_sizeis the number of consecutive query tokens that share a Q scale. A value of1gives each query token its own scale.k_block_sizeis the number of consecutive key tokens that share a K scale. A value of16shares one scale across 16 key tokens.v_block_sizecontrols scaling along the hidden dimension of V. The value1gives each V channel within an attention head its own scale, computed across the tokens.
Sparse Attention with Skip Softmax#
Skip Softmax Attention, also known as BLASST, keeps the QKᵀ calculation but rejects score blocks that fall sufficiently below the running maximum. For query row \(i\) and KV block \(j\), the block is negligible when
where \(\tilde{m}_i^{(j)}\) is the maximum score in the current block, \(m_i^{(j)}\) is the running maximum, and \(\lambda\) is the threshold. A larger \(\lambda\) rejects more blocks. Rejected blocks skip exponentiation and the corresponding PV accumulation.
Because the score distribution depends on the input, a fixed threshold \(\lambda\) does not guarantee fixed sparsity. To make sparsity easier to control, NVIDIA ModelOpt can calibrate a formula that maps a desired target_sparsity to the threshold and store it in the checkpoint configuration. See the ModelOpt Wan 2.2 Skip Softmax example for the calibration workflow. With this metadata, two controls shape the quality-speed tradeoff:
target_sparsityexpresses how aggressively to skip as an intuitive target.disabled_until_timestepkeeps the early denoising steps dense before enabling Skip Softmax.
The mapping from disabled_until_timestep to actual denoising steps depends on the scheduler and is not linear. In the 40-step UniPC schedule used here, disabled_until_timestep=0.86 keeps the 14/40 steps dense and enables Skip Softmax for the remaining 26. See the VisualGen Skip Softmax Attention documentation for the scheduler-dependent mapping.
The ModelOpt checkpoints used in this experiment already include this calibration metadata. Without calibration, Skip Softmax can still be enabled by setting the threshold directly. See the VisualGen Skip Softmax Attention documentation for direct-threshold configuration.
Results#
Experimental setup#
We evaluate the three techniques on a fixed Wan 2.2 workload while varying GEMM precision, attention precision, and Skip Softmax settings.
Item |
Setting |
|---|---|
Checkpoints |
|
GPU |
NVIDIA B200 |
Generated video |
1280×720, 81 frames at 16 FPS |
Denoising |
40 steps; guidance 4.0 for the high-noise expert and 3.0 for the low-noise expert |
Attention paths |
Dense, or SAGE with INT8 |
The ModelOpt checkpoints have already included calibrated Skip Softmax metadata. For the BF16 Skip Softmax rows, the same metadata is added to the BF16 checkpoint.
We use compiled BF16 with standard attention and no Skip Softmax as the common baseline:
Quality: LPIPS compares each video with the BF16 generation from the same prompt and seed, with
torch.compileenabled.Speed: Speedup compares pipeline-forward latency with the same compiled BF16 baseline, whose mean latency is 412.6 seconds across the seven prompts. This excludes compilation’s own speedup and isolates the three optimizations studied here.
The 96 configurations are a characterization sweep, not a recommended per-model tuning cost:
{BF16 reference, FP8 per-tensor, NVFP4}
× {dense attention, SAGE}
× {no Skip Softmax, or
   target_sparsity {0.65, 0.70, 0.75}
   × disabled_until_timestep {0.86, 0.90, 0.94, 0.97, 1.00}}
Every setting uses the same seven prompt-and-seed pairs. Latency covers one complete 40-step pipeline forward; model loading, HTTP handling, and video encoding are outside the measurement. These 96 points form the quality-speed frontier shown next.
Quality-speed frontier#
Figure 2 organizes the 96 data points in two levels. Color identifies one of six GEMM/attention quantization families: three GEMM precisions, each with and without SAGE. Within each color, a square marks no Skip Softmax and the other 15 points sweep three target_sparsity values across five disabled_until_timestep values. We highlight two of these Skip Softmax configurations:
Conservative:
target_sparsity=0.75,disabled_until_timestep=0.86, shown as a star.Aggressive:
target_sparsity=0.75,disabled_until_timestep=1.00, shown as a triangle.
The aggressive point shows the upper-speed end of the sweep rather than a recommended setting. The remaining Skip Softmax configurations are circles, and the dashed line traces the global Pareto frontier across all six families.

Figure 2. Speedup–quality frontier across all 96 configurations. Both LPIPS and speedup are measured against compiled BF16 with standard attention and no Skip Softmax.
Frontier analysis#
The table condenses the 18 marked points into six GEMM/attention quantization families and three representative Skip Softmax settings. Each cell reports speedup / mean LPIPS; the star and triangle use the same Skip Softmax settings as Figure 2.
GEMM/attention quantization |
■ No Skip Softmax |
★ Conservative Skip Softmax |
▲ Aggressive Skip Softmax |
|---|---|---|---|
BF16 |
1.000× / 0.0000 |
1.098× / 0.1105 |
1.194× / 0.4948 |
BF16 + SAGE |
1.091× / 0.2907 |
1.191× / 0.3107 |
1.288× / 0.4884 |
FP8 per-tensor |
1.069× / 0.2516 |
1.202× / 0.2702 |
1.311× / 0.4938 |
FP8 per-tensor + SAGE |
1.210× / 0.3074 |
1.354× / 0.3253 |
1.475× / 0.4880 |
NVFP4 |
1.133× / 0.3701 |
1.275× / 0.3820 |
1.404× / 0.4867 |
NVFP4 + SAGE |
1.272× / 0.3653 |
1.427× / 0.3811 |
1.540× / 0.4887 |
With compiled BF16 as the common origin, conservative Skip Softmax on BF16 reaches 1.098× at 0.1105 LPIPS. Moving directly to FP8 per-tensor reaches 1.069× at 0.2516 LPIPS, while NVFP4 reaches 1.133× at 0.3701 LPIPS. For this workload, Skip Softmax offers the gentler first step; GEMM quantization opens a faster operating range with a larger quality tradeoff.
SAGE adds speed in all three GEMM families, but its quality effect depends on the precision: the LPIPS shift is substantial from BF16, modest from FP8 per-tensor, and nearly flat for NVFP4. This is why the combined frontier is more useful than prescribing a fixed order in which to enable the optimizations.
Skip Softmax then fills the space within each family. target_sparsity controls how much work can be rejected, while disabled_until_timestep controls how early that rejection begins. Together they provide a continuum between the conservative stars and aggressive triangles instead of a single all-or-nothing sparse mode.
This layering explains the shape of the Pareto frontier: its higher-speed region is dominated by configurations that combine SAGE with Skip Softmax, and no single technique reaches there alone.
Latency step-down#
Figure 3 isolates the attention optimizations within each GEMM precision. Each group starts with standard attention, adds SAGE, and then adds the conservative Skip Softmax setting from the frontier. The bars report absolute pipeline-forward latency, while their labels retain the common speedup against the compiled BF16 baseline.

Figure 3. Pipeline-forward latency after successively adding SAGE and conservative Skip Softmax within each GEMM precision. Lower is better.
Visual validation#
Figure 4 compares the generated videos for prompt P1 across the same six GEMM/attention quantization families used in the frontier. The compiled BF16 baseline is also the visual reference.
BF16 baseline |
|---|
|
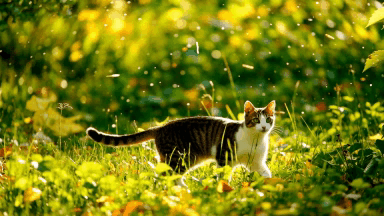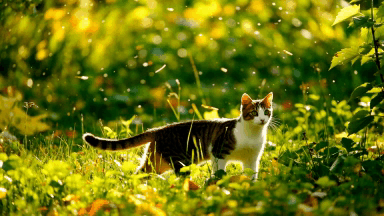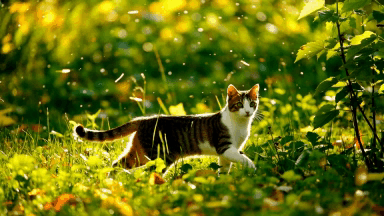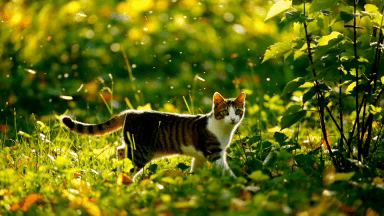
The six videos below are grouped by GEMM precision, with the SAGE variant on the right. All six use the Conservative Skip Softmax setting (★): target_sparsity=0.75 and disabled_until_timestep=0.86.
BF16 + Skip Softmax (1.10×) |
BF16 + SAGE + Skip Softmax (1.19×) |
|---|---|
|
|
FP8 per-tensor + Skip Softmax (1.20×) |
FP8 per-tensor + SAGE + Skip Softmax (1.35×) |
|
|
NVFP4 + Skip Softmax (1.27×) |
NVFP4 + SAGE + Skip Softmax (1.43×) |
|
|
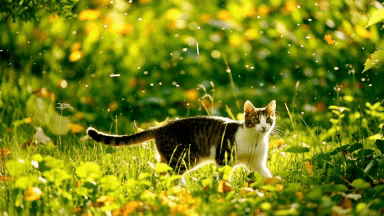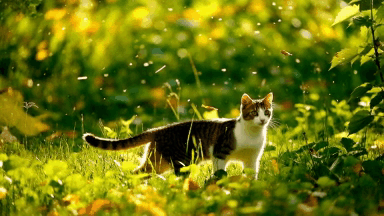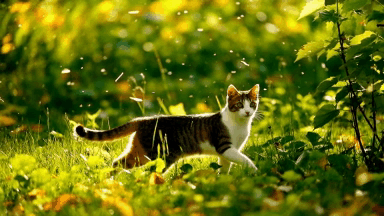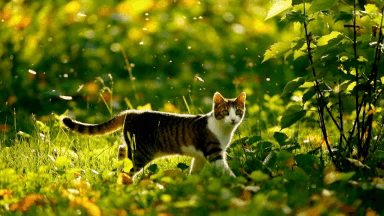
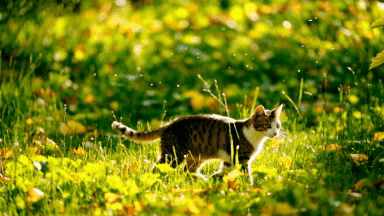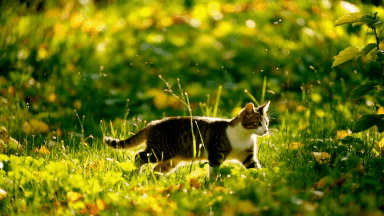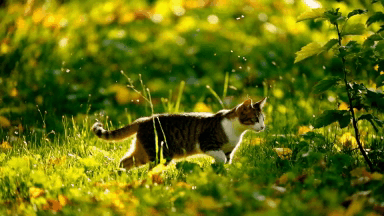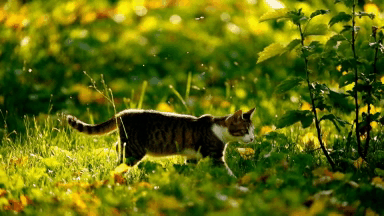
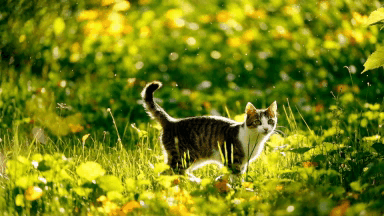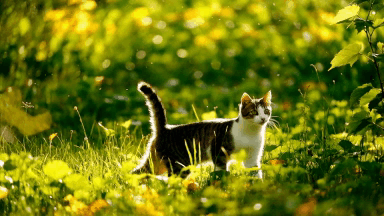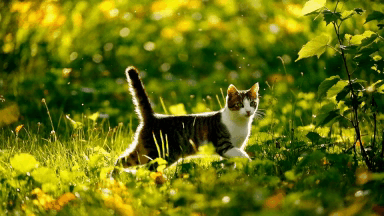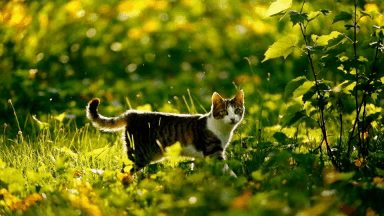
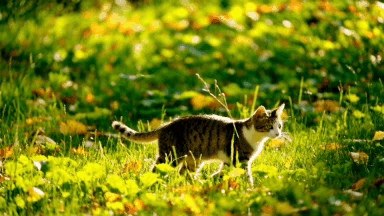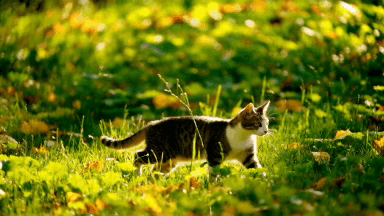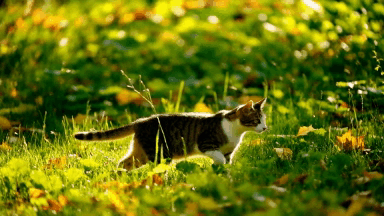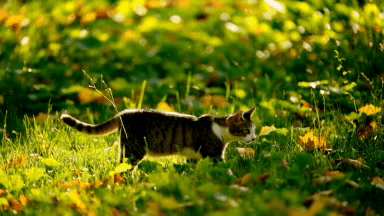
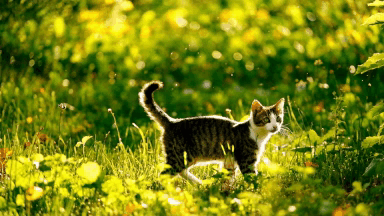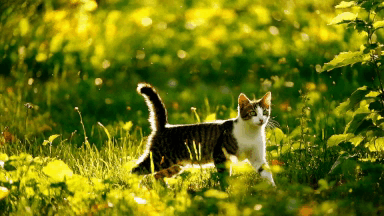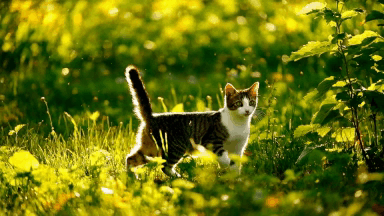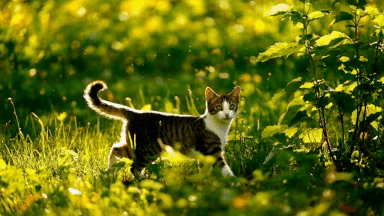
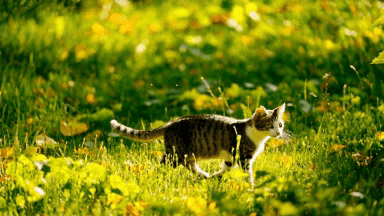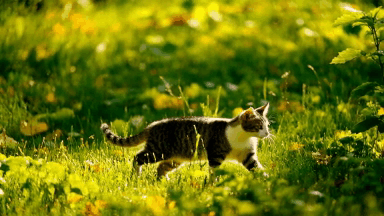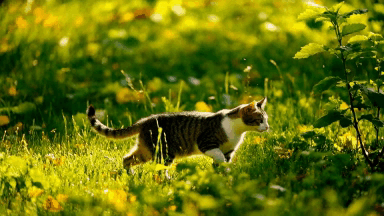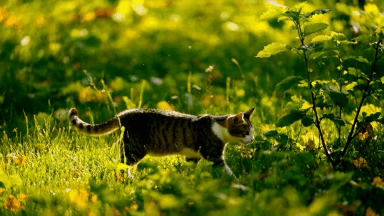
Figure 4. P1 video comparison across the BF16 baseline and six conservative Skip Softmax configurations.
Figure 5 expands the first-frame comparison to all seven prompts. Each row compares the BF16 baseline with the same six conservative configurations as Figure 4. The previews are downsampled from the original videos.


Figure 5. First-frame comparison across all seven prompts. Every Skip Softmax result uses `target_sparsity=0.75` and `disabled_until_timestep=0.86`, corresponding to the stars in Figure 2.
Reproduction#
The commands below target TensorRT-LLM 1.3.0rc26. The ModelOpt static FP8 per-tensor checkpoint or the static NVFP4 checkpoint has contained the Skip Softmax calibration config, and you may need to manually copy the configs into the official BF16 checkpoint for reproduction.
VisualGen configuration#
Save the following configuration as visual_gen.yaml. It enables SAGE and the conservative Skip Softmax setting used by the stars in Figure 2:
attention_config:
  backend: TRTLLM
  quant_attention_config:
    qk_dtype: int8
    v_dtype: fp8
    q_block_size: 1
    k_block_size: 16
    v_block_size: 1
  sparse_attention_config:
    algorithm: skip_softmax
    target_sparsity: 0.75
    disabled_until_timestep: 0.86

torch_compile_config:
  enable: true
  enable_autotune: false
SAGE Attention and Skip Softmax can be disabled independently by removing the quant_attention_config and sparse_attention_config blocks, respectively. See Attention Optimizations for the meaning of each option.
For a model that does not yet have a prequantized checkpoint, dynamic quantization can be applied to its BF16 checkpoint by adding a top-level quant_config block:
quant_config:
  quant_algo: NVFP4
  dynamic: true
Replace NVFP4 with others when the model supports that format. Dynamic quantization is an optional path and was not measured in this post.
Run with trtllm-serve#
Start trtllm-serve with the NVFP4 checkpoint and the configuration above. Replace the model ID with the FP8 checkpoint to switch the GEMM format without changing the YAML:
export MODEL=nvidia/Wan2.2-T2V-A14B-Diffusers-NVFP4
trtllm-serve "$MODEL" --visual_gen_args visual_gen.yaml
Then submit the P1 prompt from another shell. The synchronous endpoint returns the encoded video directly:
curl --fail --silent --show-error \
    --request POST http://localhost:8000/v1/videos/sync \
    --header 'Content-Type: application/json' \
    --output wan22_nvfp4_sage_skip.mp4 \
    --data '{
      "prompt": "A cat walking through a sunlit garden, gentle breeze rustling leaves, slow tracking shot",
      "width": 1280,
      "height": 720,
      "num_frames": 81,
      "frame_rate": 16,
      "num_inference_steps": 40,
      "guidance_scale": 4.0,
      "seed": 1001,
      "format": "mp4",
      "extra_params": {
        "guidance_scale_2": 3.0
      }
    }'
Seven-prompt evaluation manifest
ID |
Seed |
Prompt |
|---|---|---|
|
1001 |
A cat walking through a sunlit garden, gentle breeze rustling leaves, slow tracking shot |
|
1003 |
Children playing in a busy park, a golden retriever running between them, sunny afternoon, wide shot |
|
1004 |
Drone shot flying over a rugged coastline at sunset, waves crashing on cliffs below, golden hour lighting |
|
1005 |
A neon sign reading ‘OPEN’ flickering in a rainy alley at night, reflections on wet pavement, cinematic |
|
1006 |
A young woman smiling at the camera, soft studio lighting, slight head tilt, cinematic close-up portrait |
|
1007 |
A racehorse galloping on a dirt track, kicking up dust, side tracking shot, dramatic lighting |
|
1010 |
A bustling outdoor street market with people walking and vendors selling fresh fruit, Mediterranean style, midday sun |
For the reported latency, the pipeline forward is bracketed by CUDA synchronization and the seven prompt times are averaged. The compiled BF16 baseline enables torch.compile and disables quantization, SAGE, and Skip Softmax. AlexNet LPIPS is computed against its corresponding frames, averaged over all 81 frames and then over the seven prompts.
Conclusion#
Accelerating video diffusion is a process of trading off between the desired accuracy and speedup. TensorRT-LLM exposes GEMM quantization, quantized attention, and Skip Softmax as composable controls, so deployments can choose an operating point that matches their own quality bar instead of inheriting one fixed recipe.
That operating point is model-, prompt-, and hardware-dependent. A useful optimization workflow therefore combines representative prompts, deployment-relevant latency, aggregate quality metrics, and direct inspection of generated videos. In the future, we will explore agentic search to automate these experiments and navigate the speed-quality tradeoff.
These single-GPU techniques complement the multi-GPU methods described in Scaling Video Generation Across NVL72 Rack with TensorRT-LLM and can be combined with multi-GPU parallelism when the deployment requires higher throughput or larger workloads.
References#
Scaling Video Generation Across NVL72 Rack with TensorRT-LLM
SageAttention: Accurate 8-Bit Attention for Plug-and-play Inference Acceleration
SageAttention2: Efficient Attention with Thorough Outlier Smoothing and Per-thread INT4 Quantization
BLASST: Dynamic BLocked Attention Sparsity via Softmax Thresholding