Load#
cuda.coop.load() fills each thread’s ThreadData from a contiguous
tile in memory. The algorithm determines which thread reads each value and
whether a shared-memory exchange rearranges it afterward.
The explorer shows eight illustrative threads. For the warp-transpose algorithms, it groups them into two four-lane teaching warps. CUDA warps have 32 lanes; executable blocks using these algorithms must contain a multiple of 32 threads. All illustrated loads read a full tile.
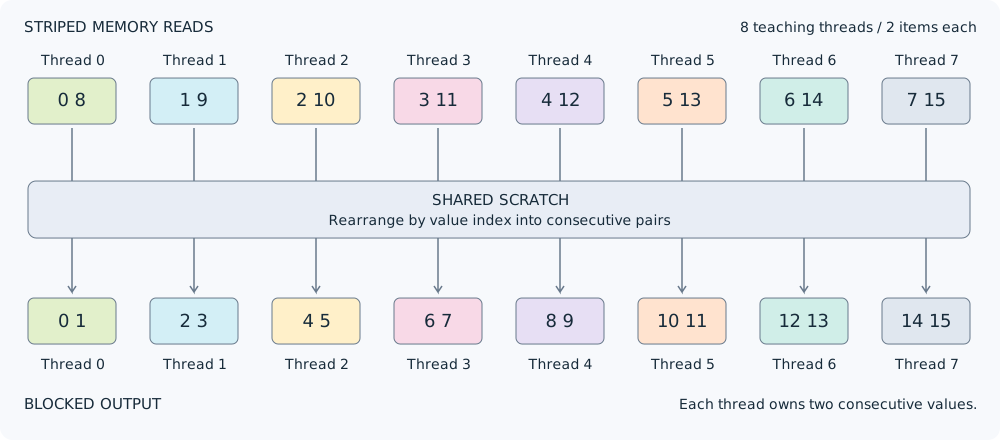
Transpose load with eight illustrative threads and two items per thread.#
Each column below belongs to one thread. Transpose first reads in striped order, then exchanges values to give each thread a consecutive pair.
Thread          0     1     2     3     4     5     6     7
Memory reads   0,8   1,9  2,10  3,11  4,12  5,13  6,14  7,15
After exchange 0,1   2,3   4,5   6,7   8,9  10,11 12,13 14,15
Reading the stages#
See blocked versus striped for a compact ownership table and the index formulas used here.
The memory row numbers values by their position in the tile. The next row shows the threads that read them. For algorithms with an exchange, shared scratch connects those readers to the final owners. Select a value to inspect its source index and destination thread slot.
direct and vectorize produce blocked ownership: thread t receives
K consecutive values starting at t * K, where K is the number of
items per thread. Vectorization can combine a thread’s adjacent values into
a wider access when the pointer, alignment, type, and item count permit it.
The diagram does not guarantee a vector instruction.
striped gives thread t the values at t + j * T for item slot
j and group size T. Neighboring threads read neighboring addresses
at each slot, and the output stays striped. transpose starts with those
same reads and exchanges the values into blocked ownership.
warp_transpose reads a separate striped tile within each physical warp
and exchanges it into blocked ownership. warp_transpose_timesliced uses
the same memory reads, then lets warps take turns through a shared scratch
region sized for one warp. The animation separates those exchange rounds;
it does not serialize the global-memory loads.
Using Load in a kernel#
This fragment uses the common API inside a Numba-CUDA-MLIR kernel that
accepts items_per_thread. Import cuda from numba_cuda_mlir,
numpy as np, and cuda.coop as coop. Launch with 128 threads and
provide at least 128 * items_per_thread source elements for each block.
block = coop.this_block()
items = coop.ThreadData(items_per_thread)
offset = cuda.blockIdx.x * 128 * items_per_thread
coop.load(block, source, items, algorithm="transpose", offset=offset)
# Each thread owns items_per_thread consecutive values. Load returns None.
For a partial final tile, supply valid_items and, when needed,
oob_default. See cuda.coop.load() for the full parameter contract
and a complete example, and the cuda.coop Programming Guide for backend
activation and thread groups.