
Electrostatics Benchmarks#
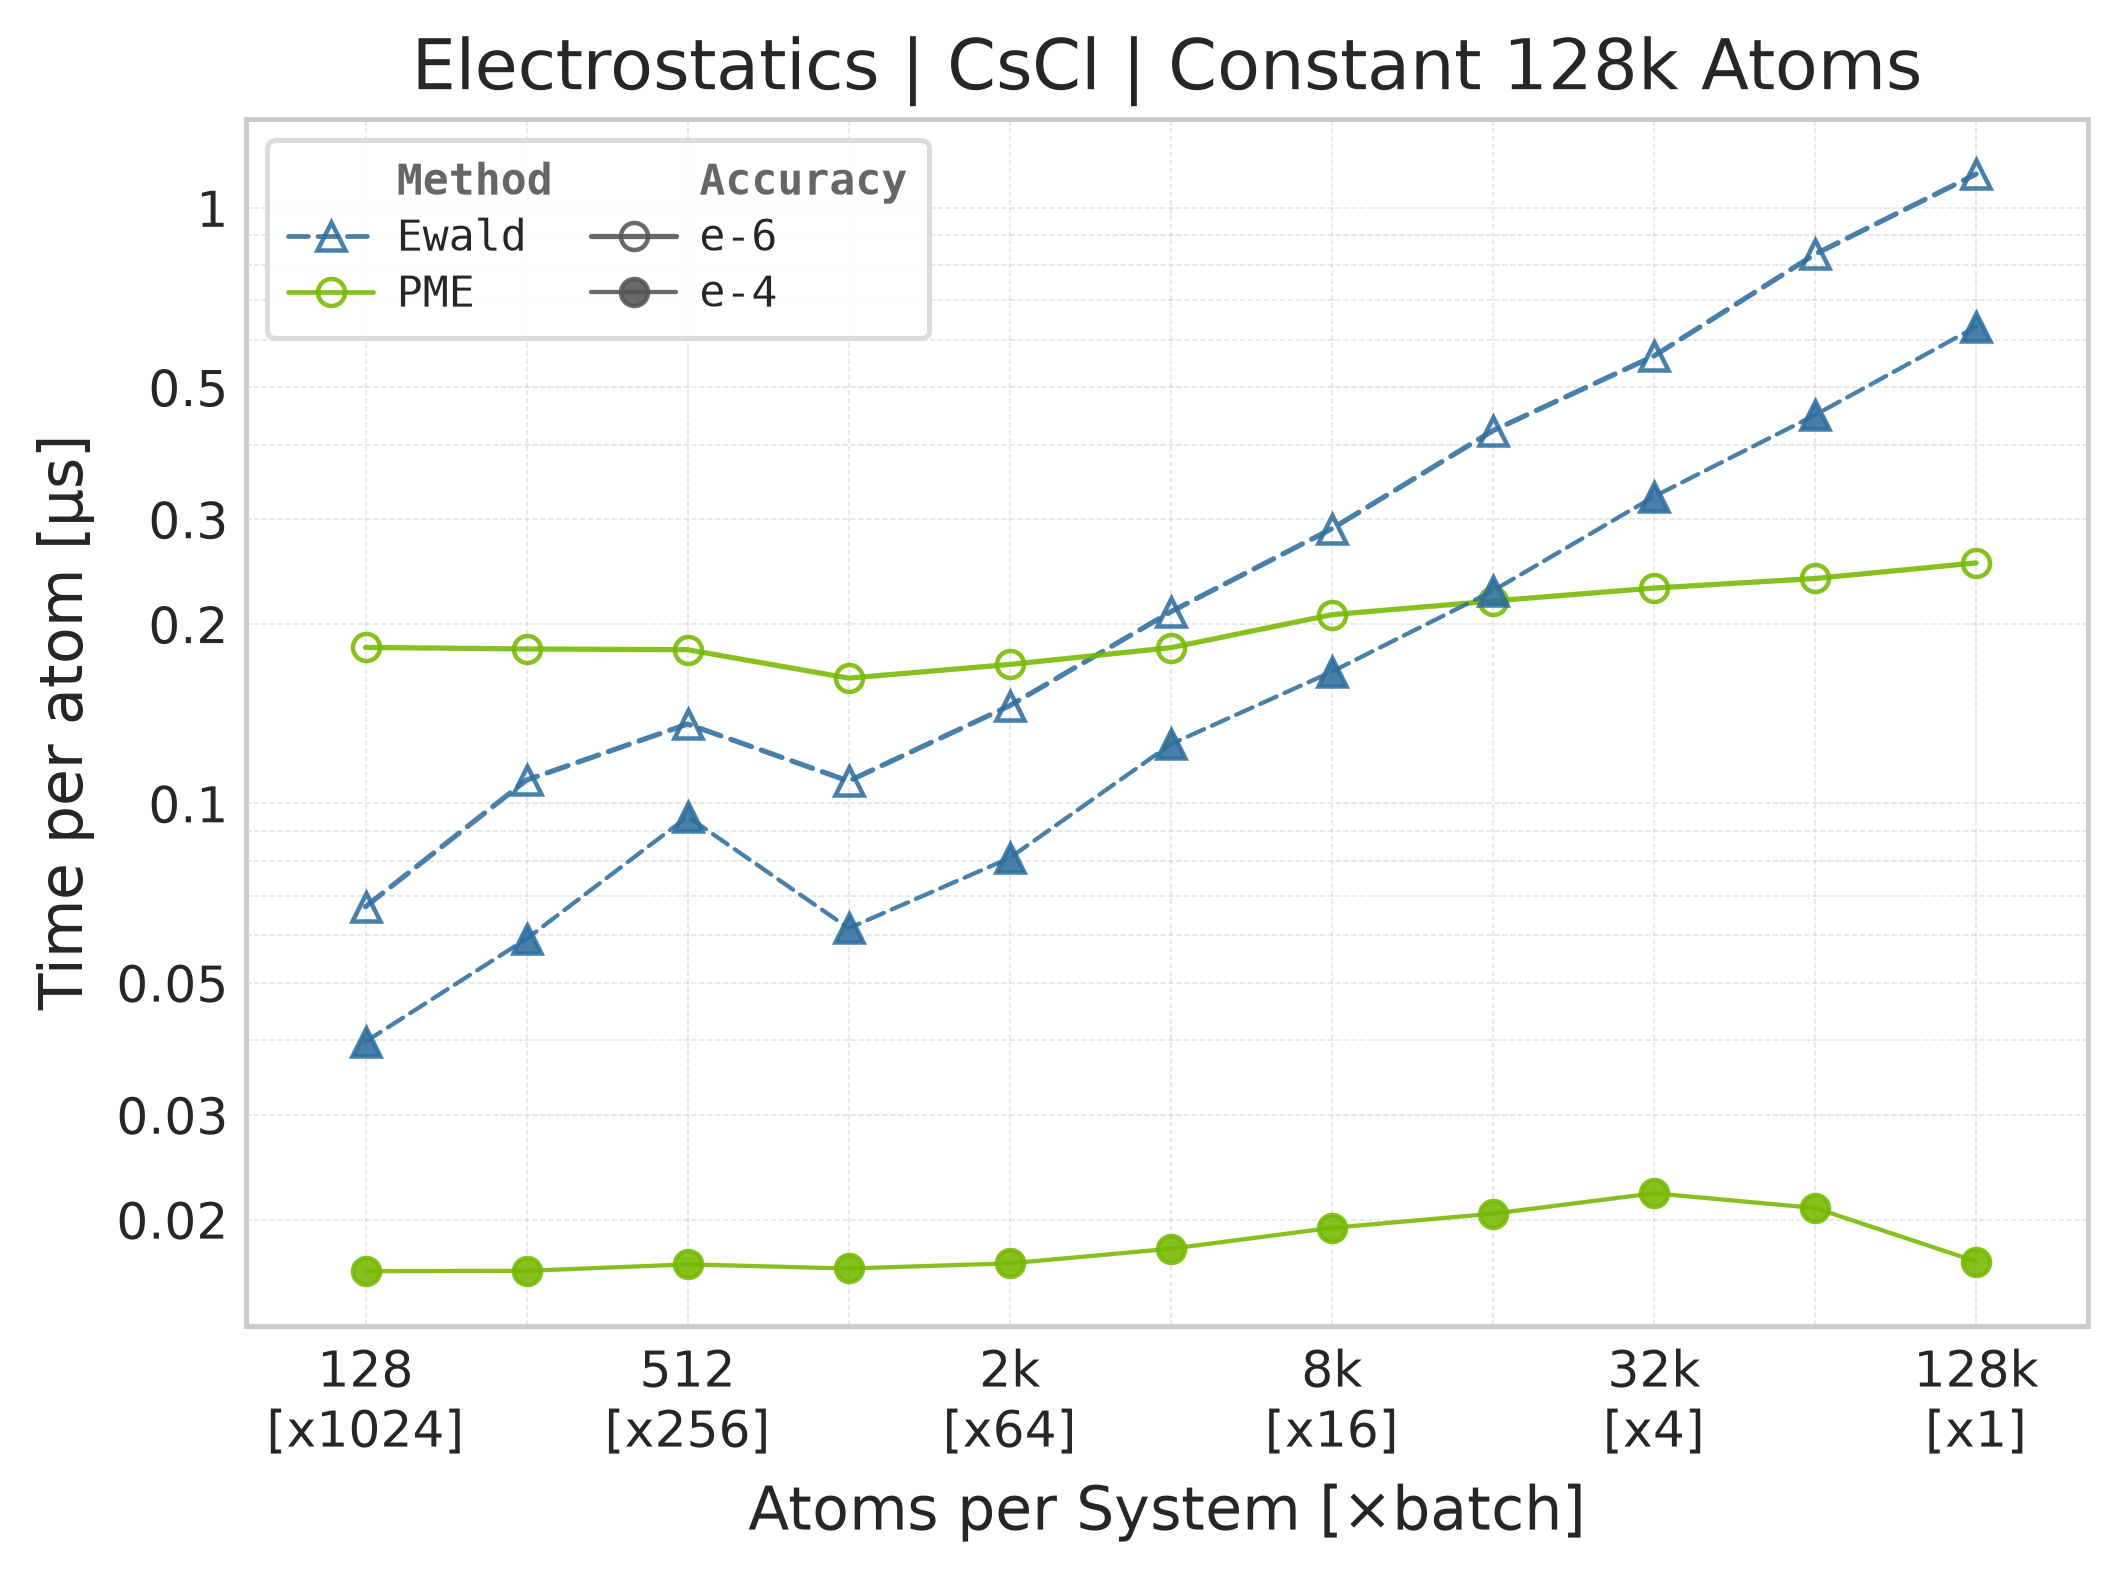
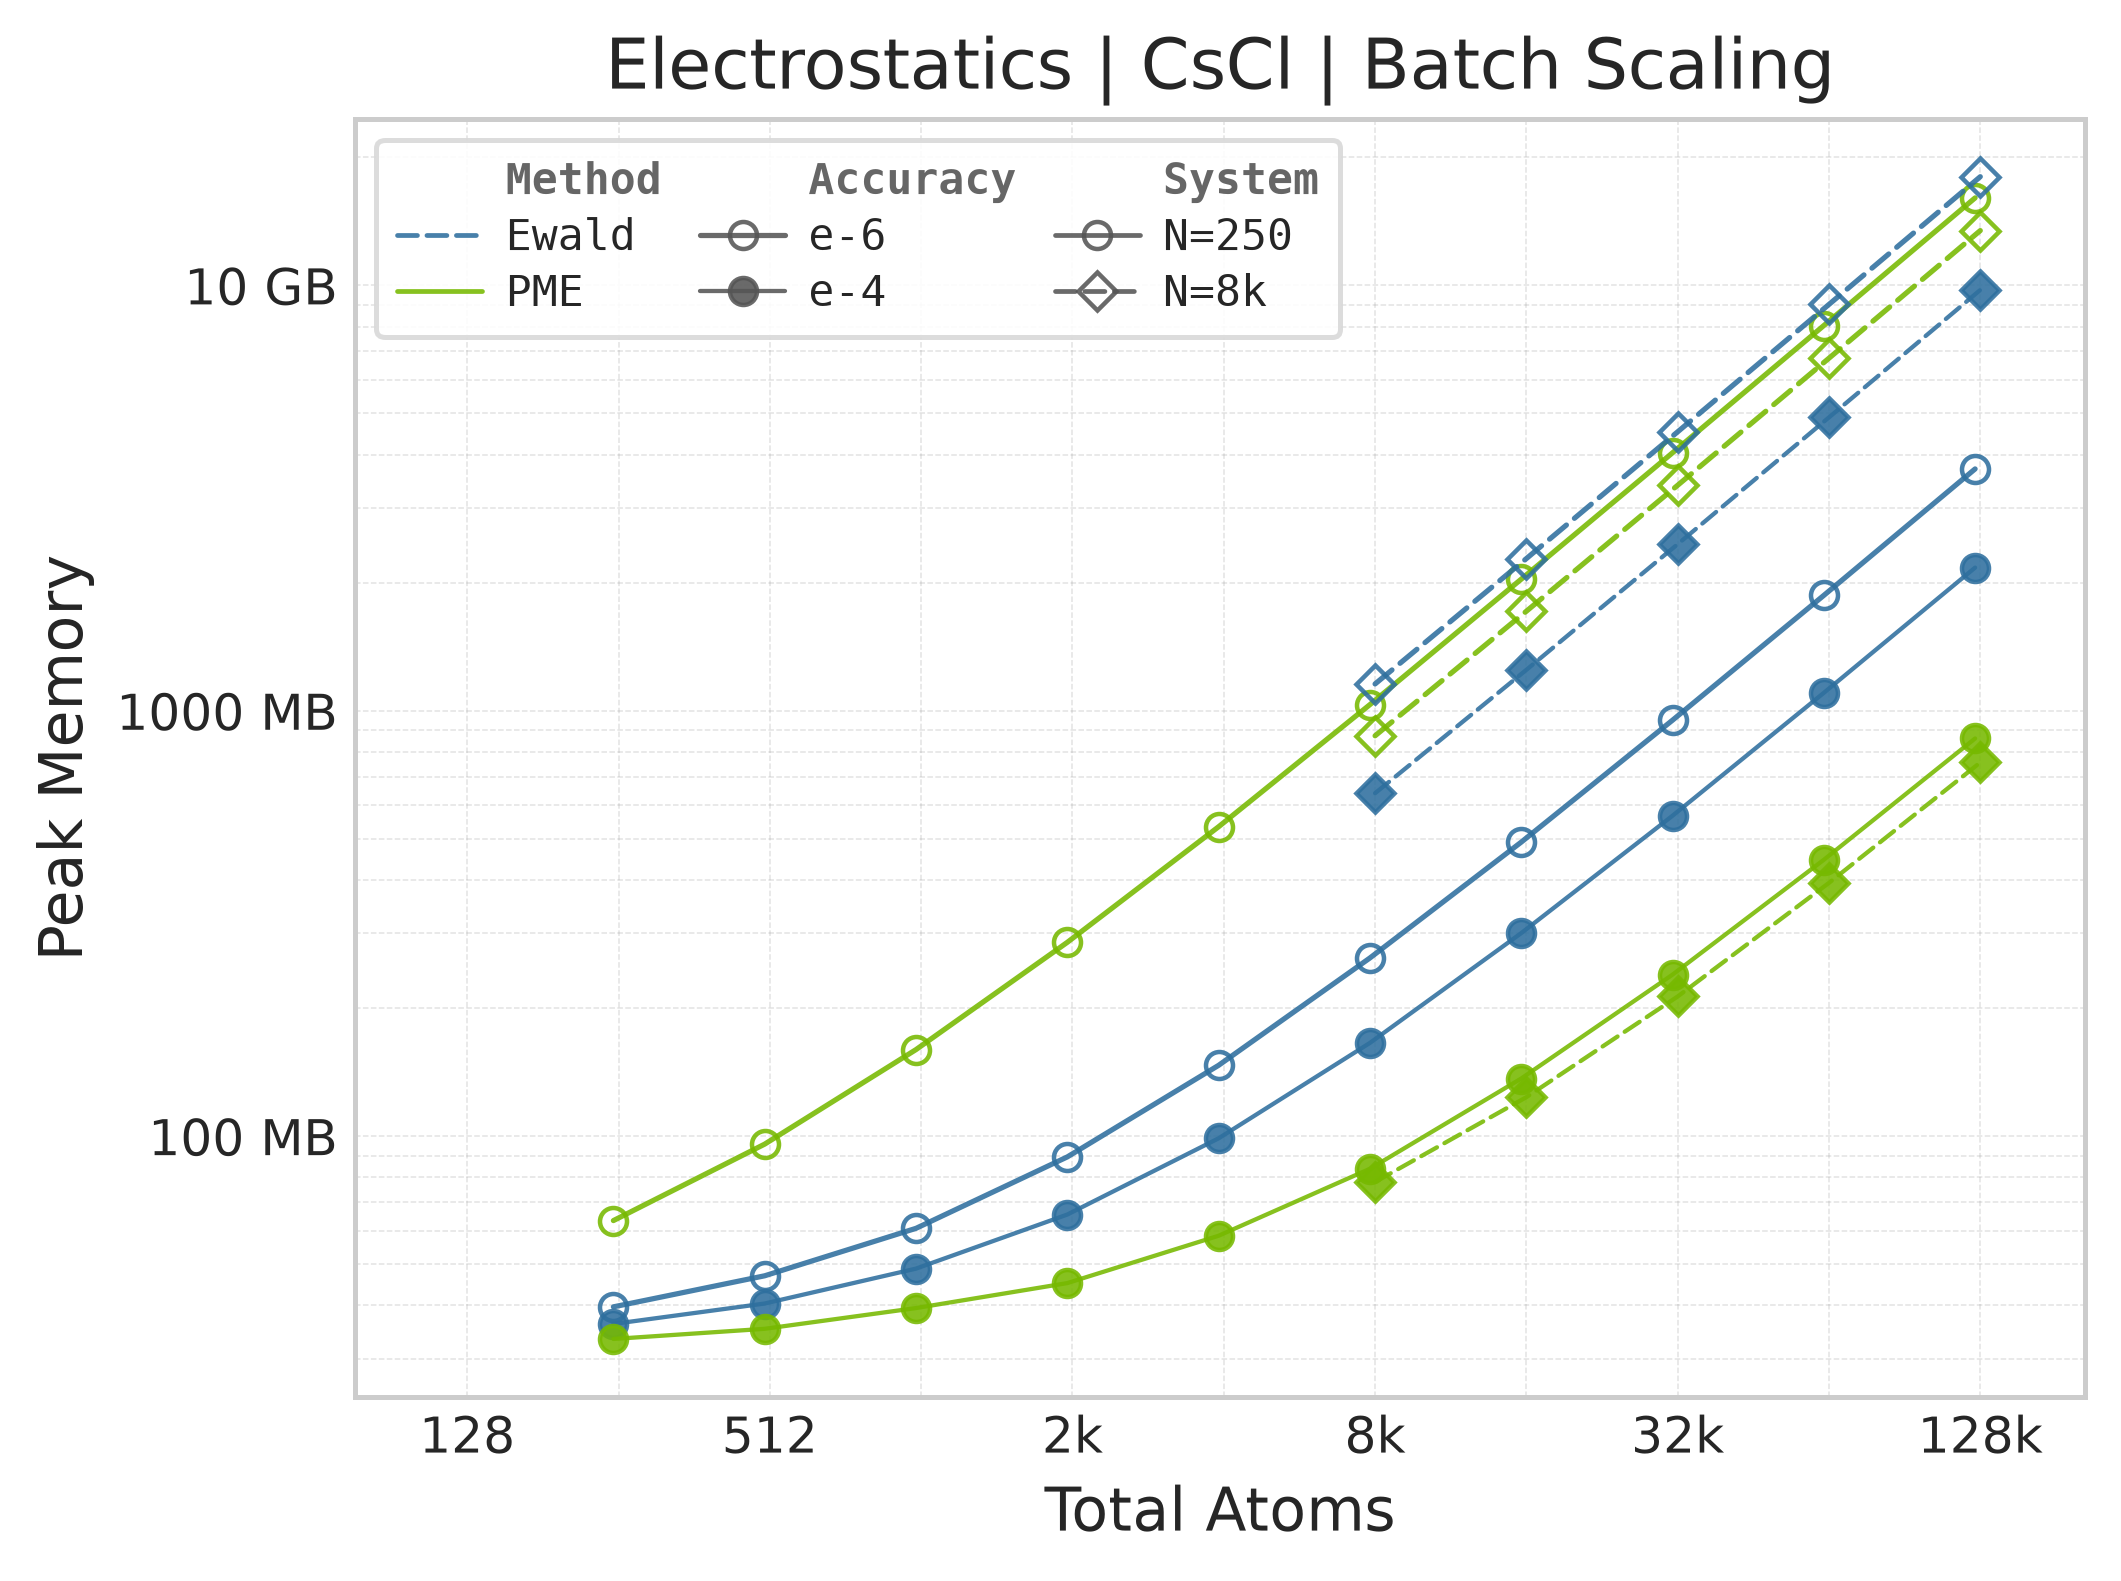
Performance benchmarks for electrostatic interaction methods in ALCHEMI Toolkit-Ops — Ewald summation and Particle Mesh Ewald (PME). Results show scaling behaviour across system sizes for both single-system and batched computations.
Warning
These results are intended to be indicative only: your actual performance may vary depending on the atomic system topology, software and hardware configuration and we encourage users to benchmark on their own systems of interest.
Note
Every measured PME and Ewald row uses the same complete differentiable workload:
evaluate energy, then derive forces (-dE/dR) and charge gradients
(dE/dq) through framework autodiff. The reportable default times this full
workload once; real/reciprocal component profiling is opt-in. Failed points
are retained as success=False CSV rows with their failure status. The JAX
tab below describes the completed Ewald collection and its capacity limits.
How to Read These Charts#
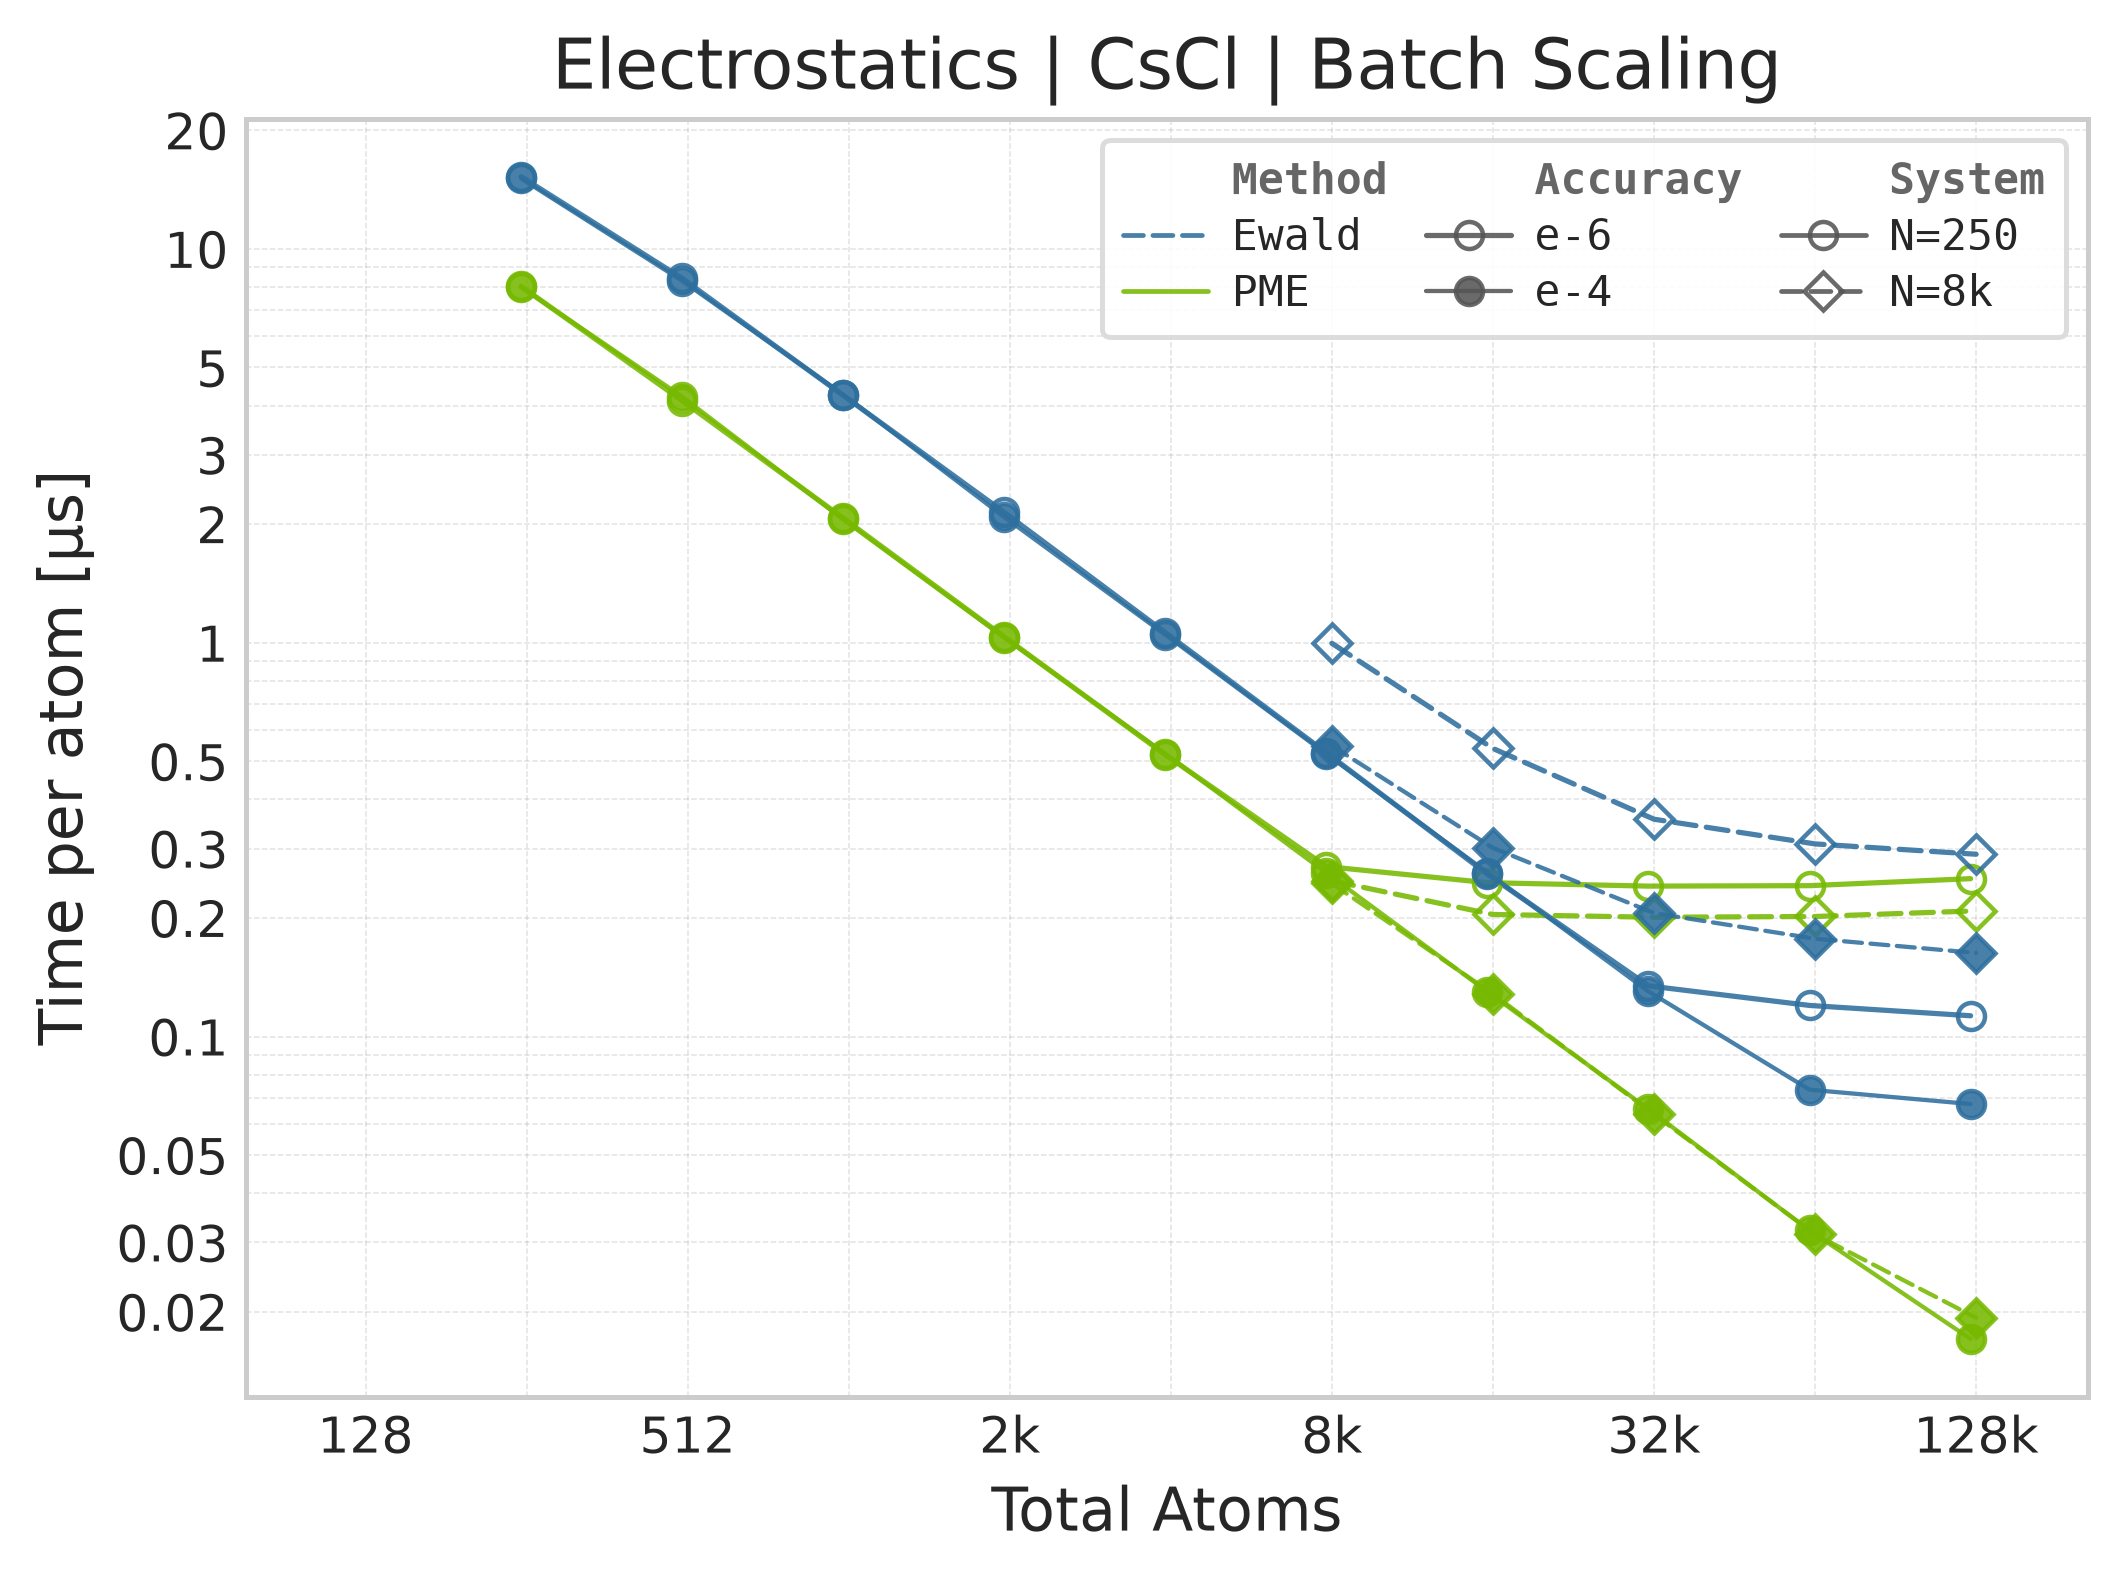
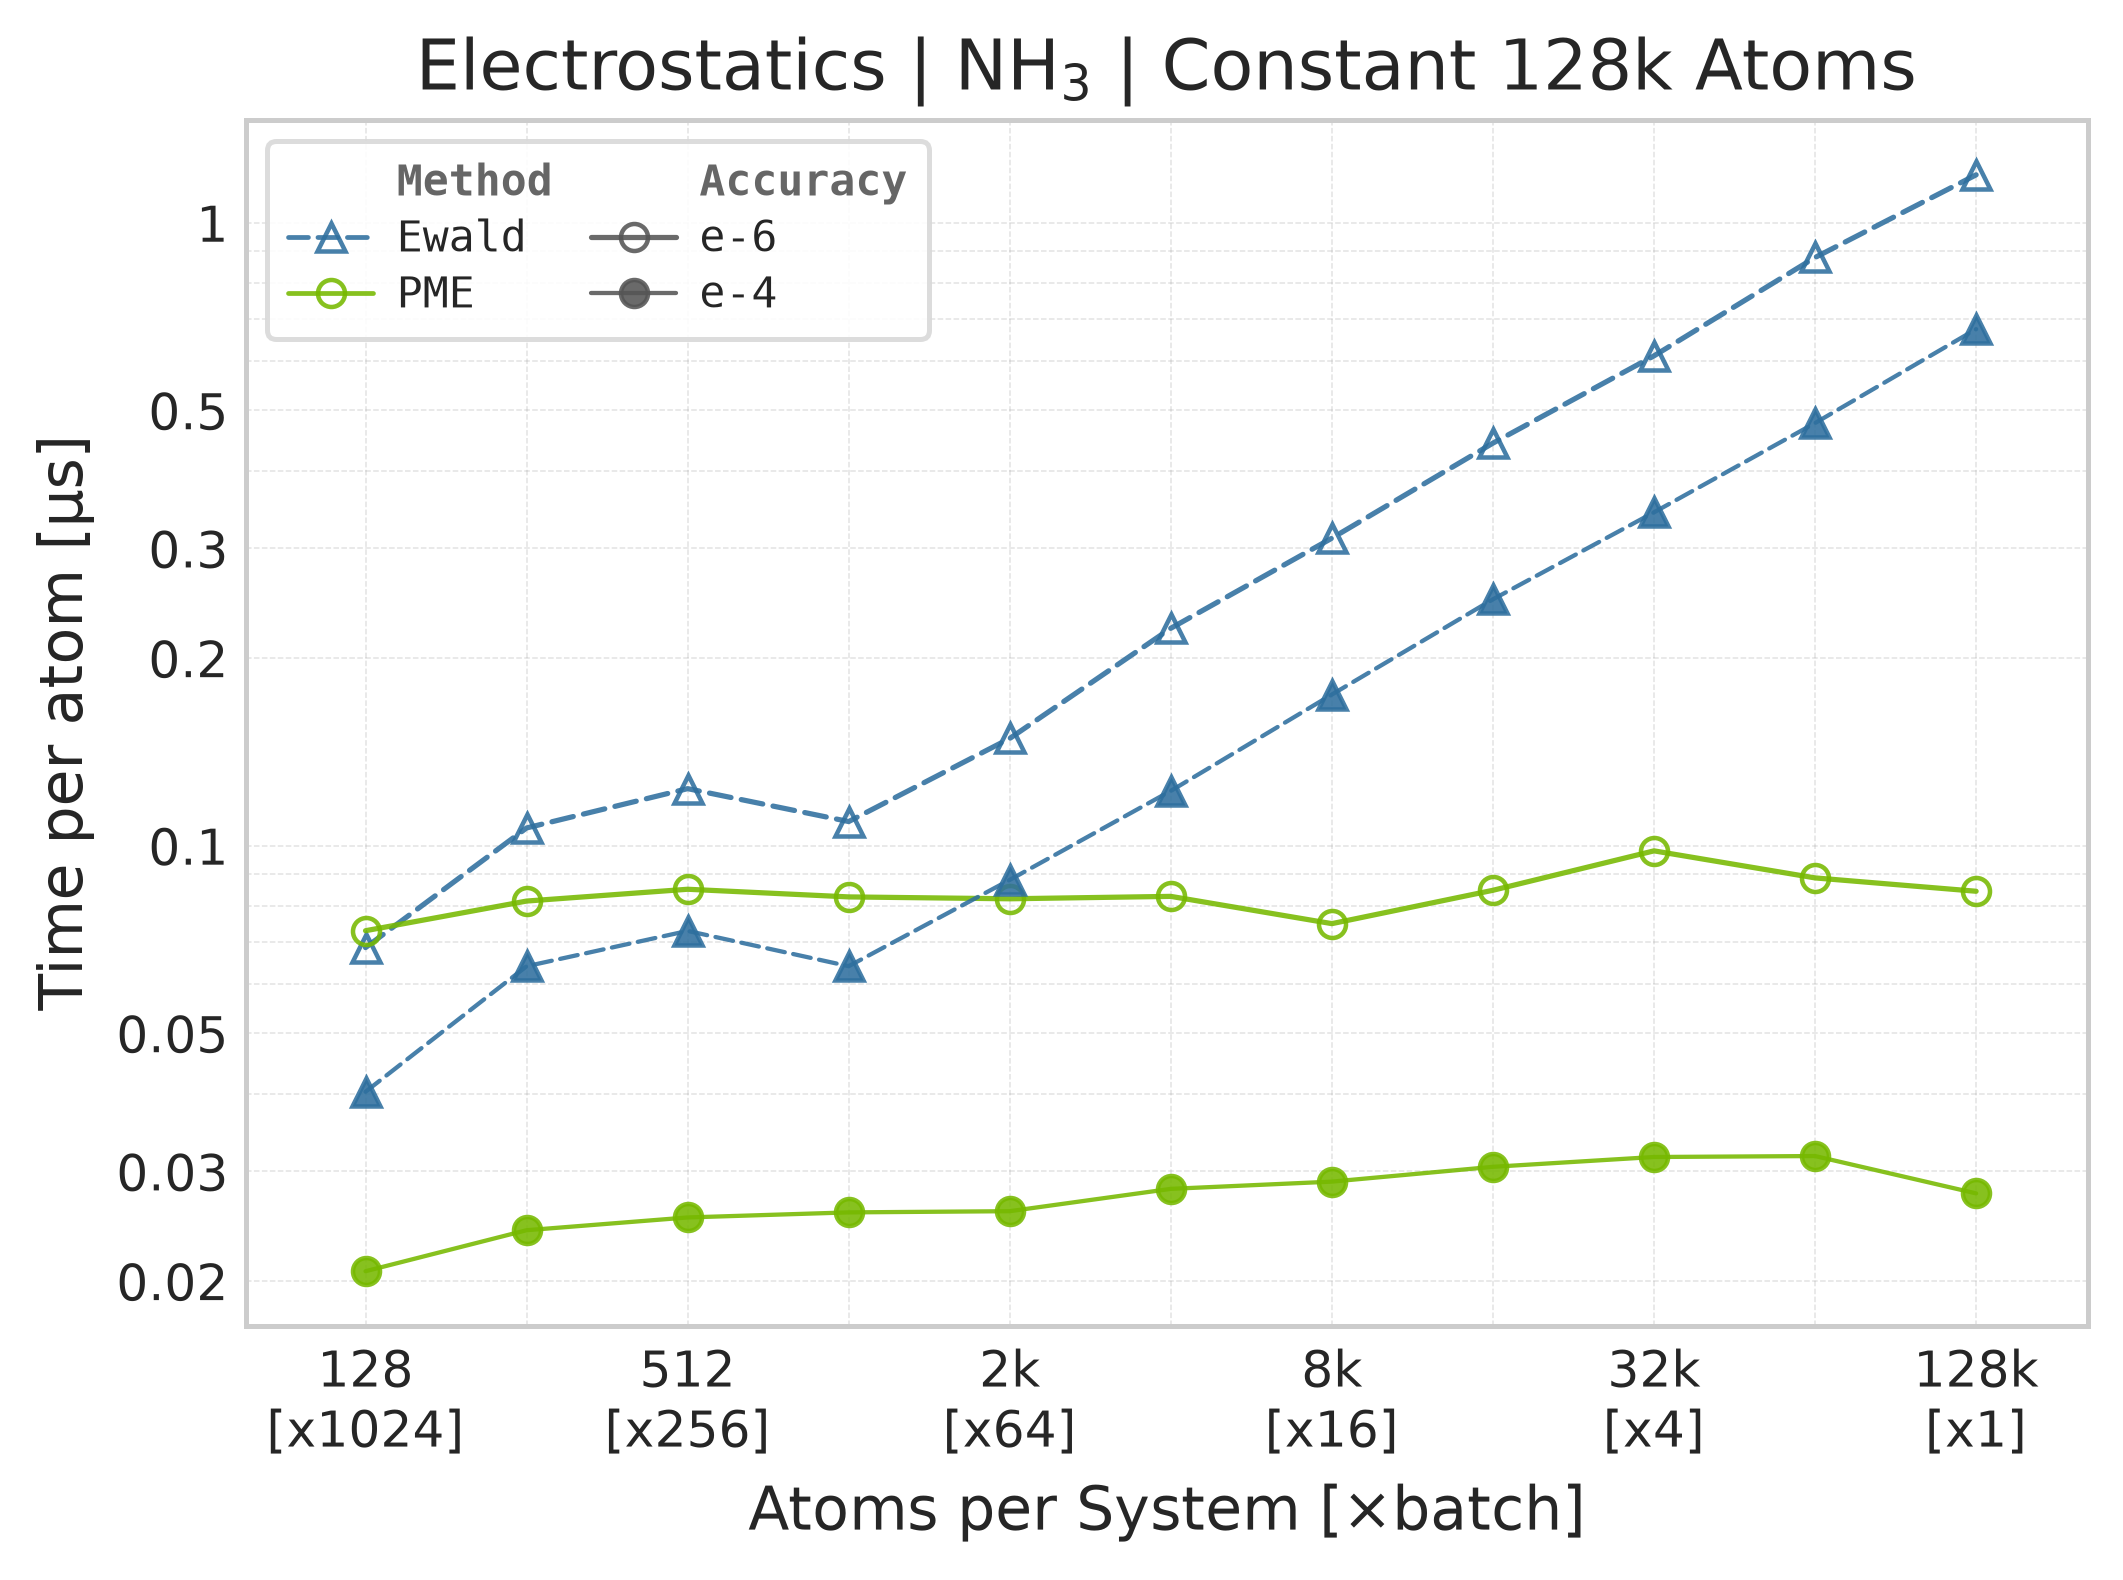
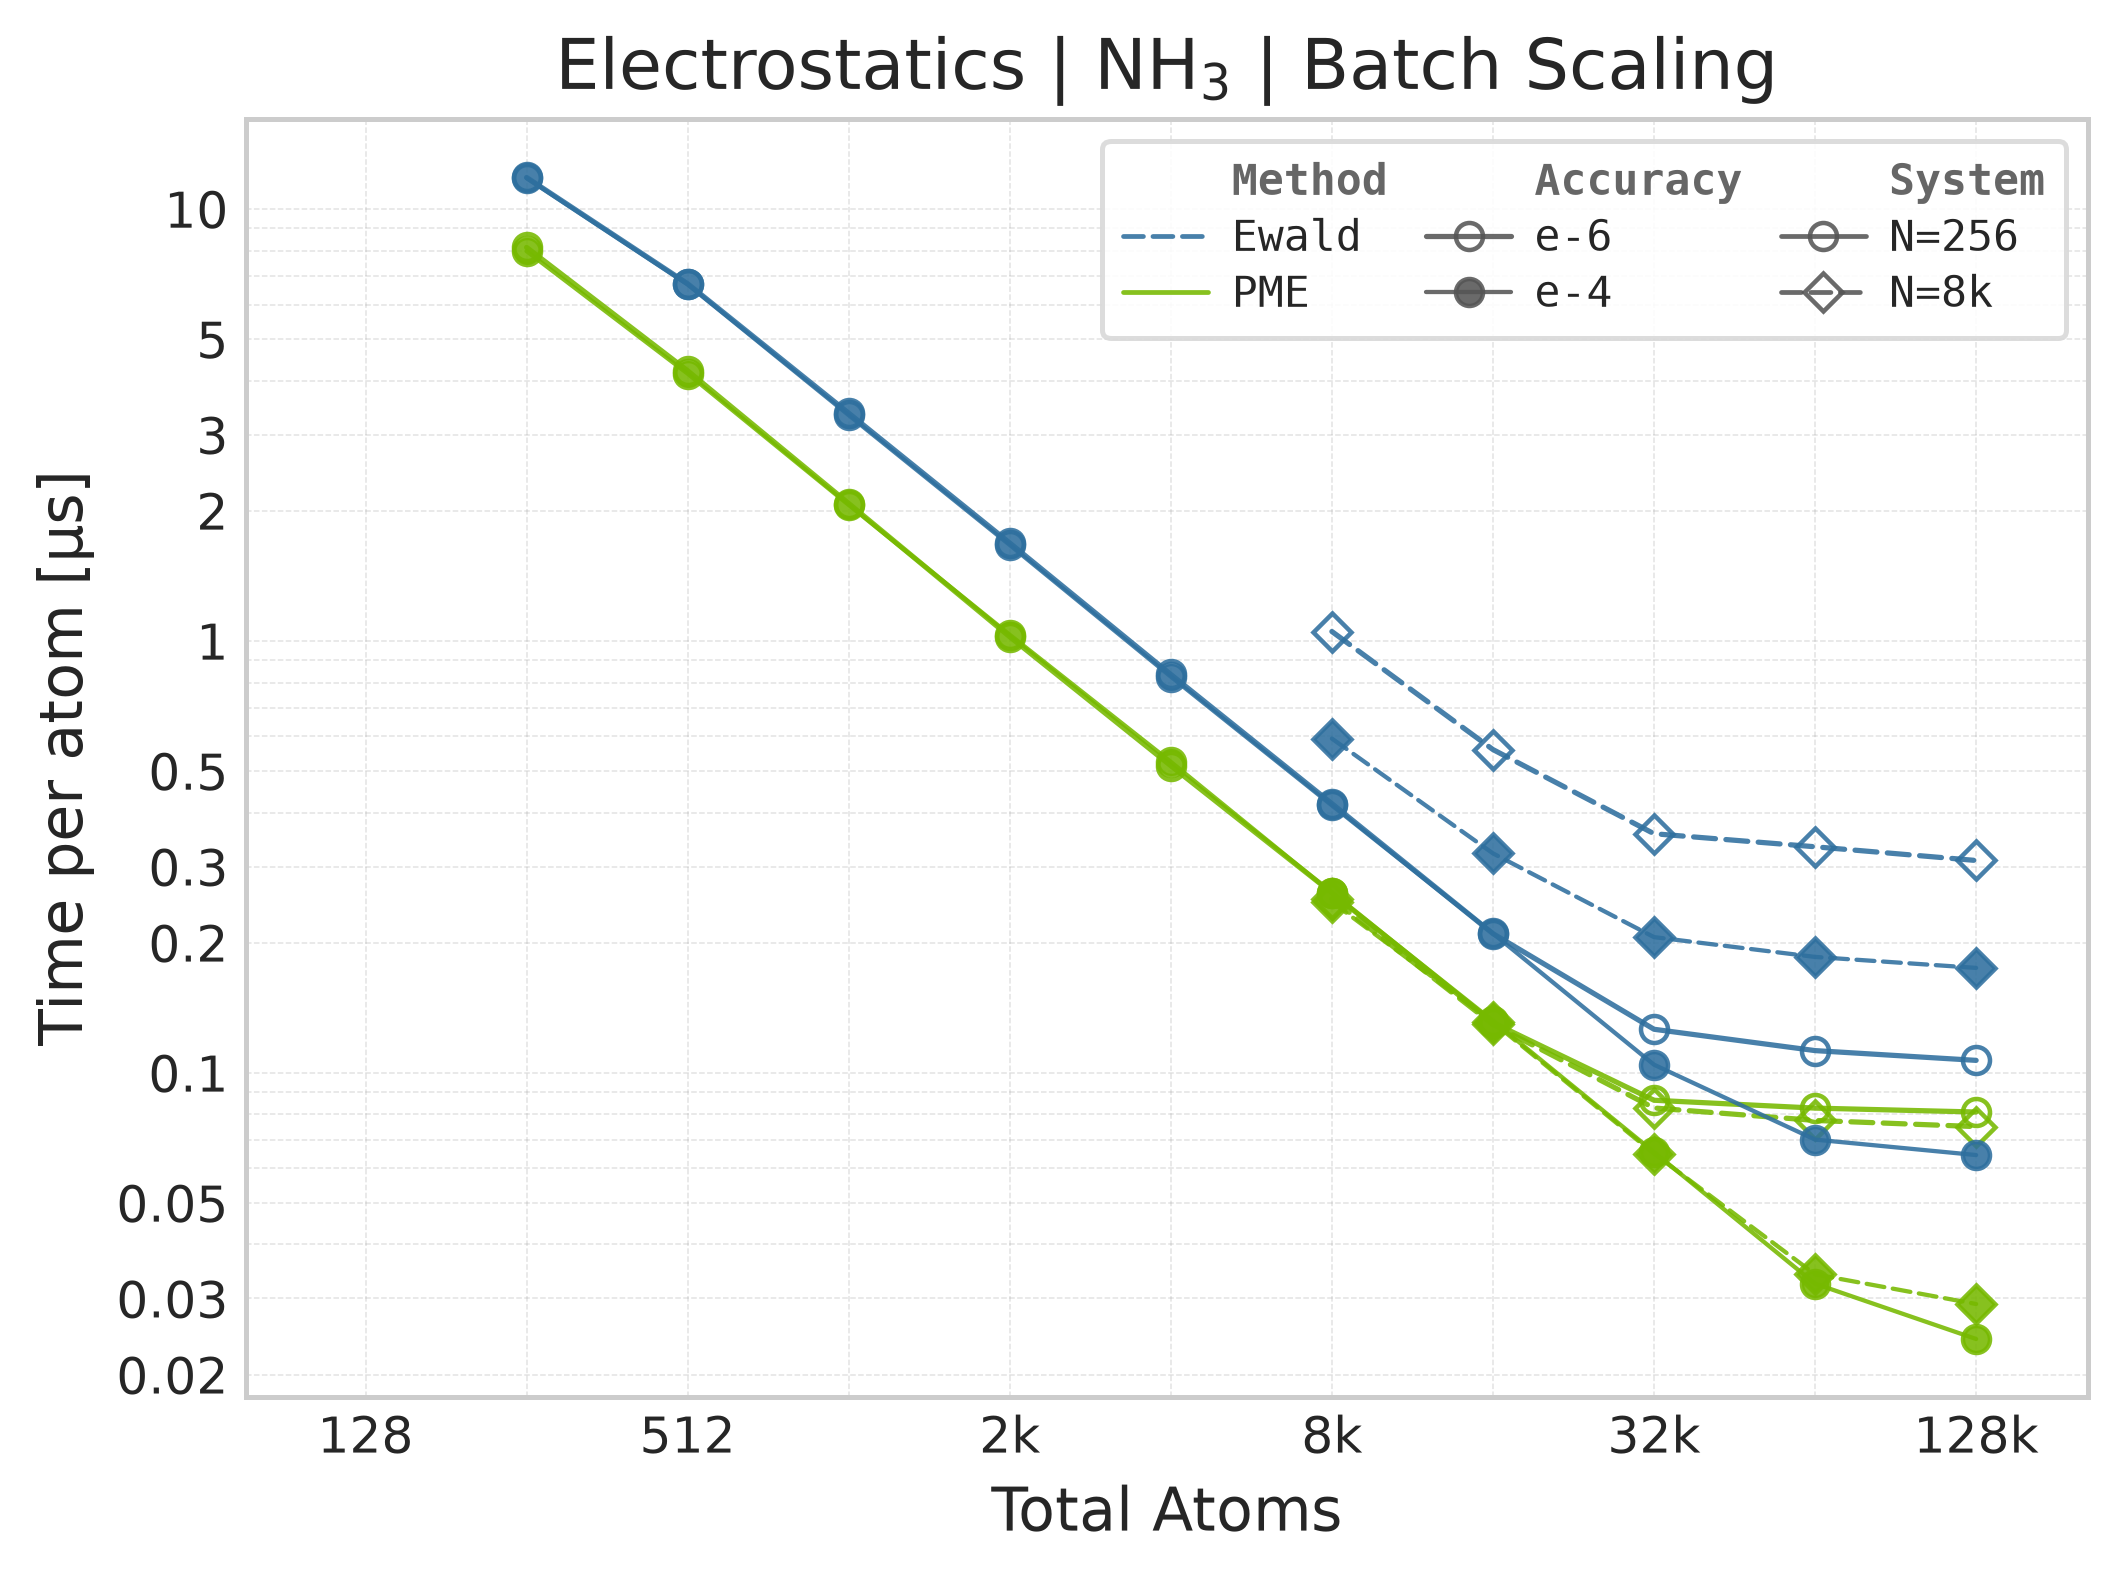
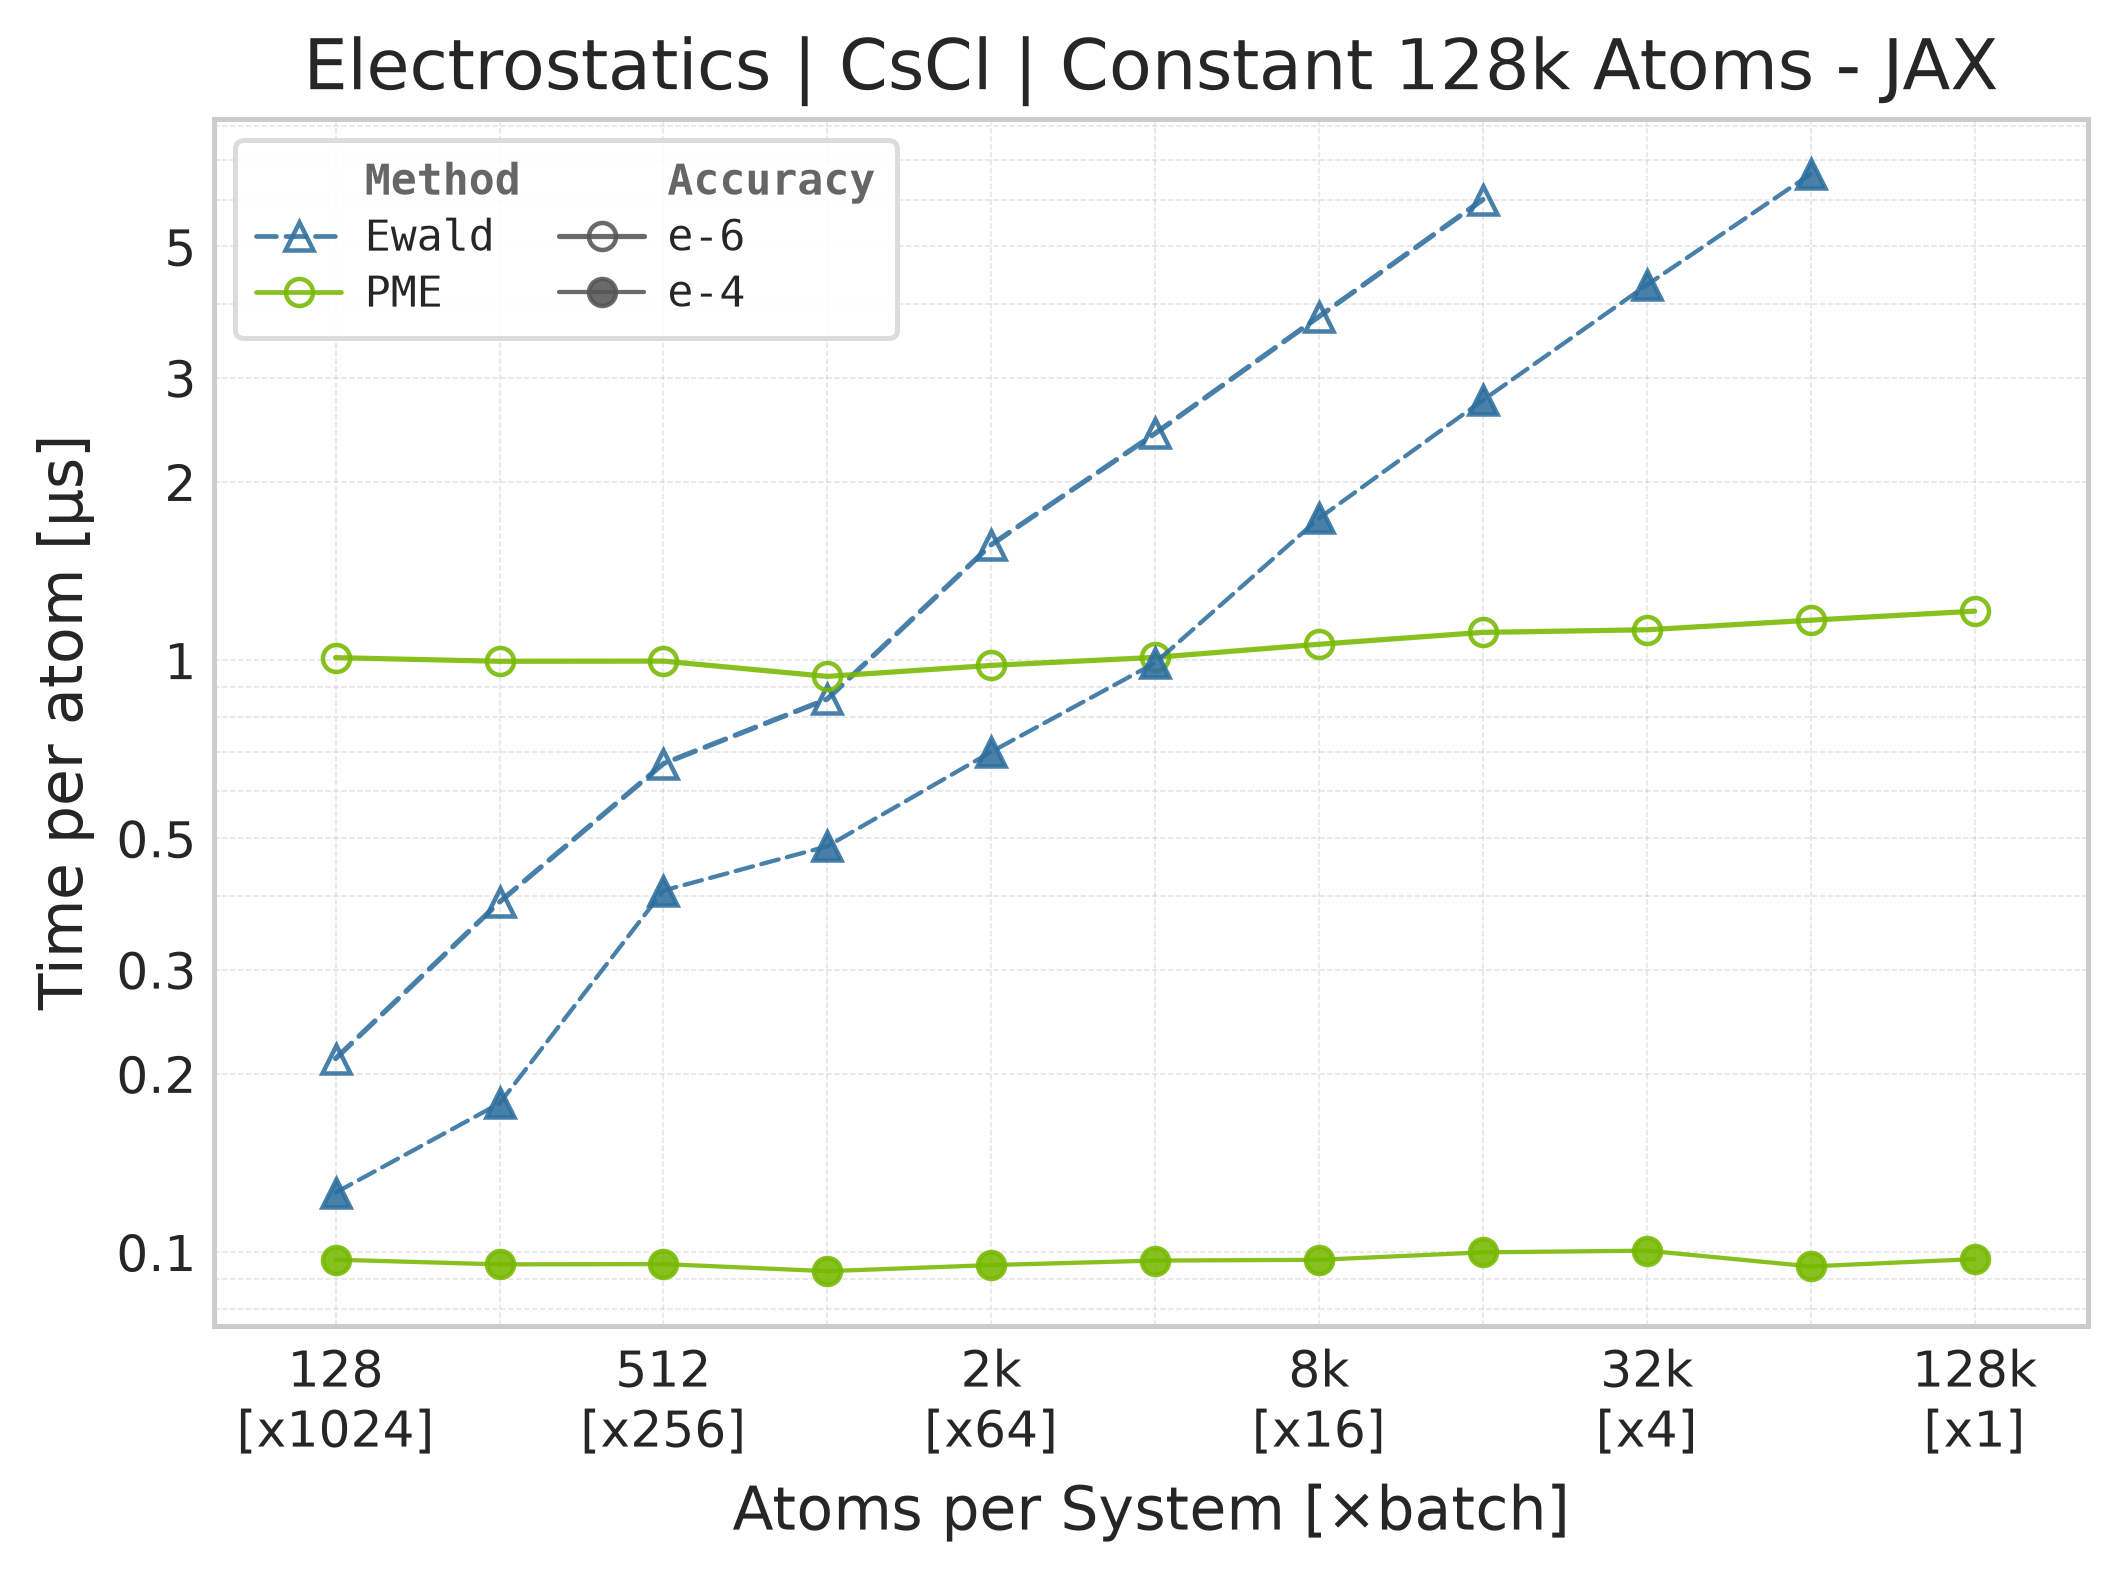
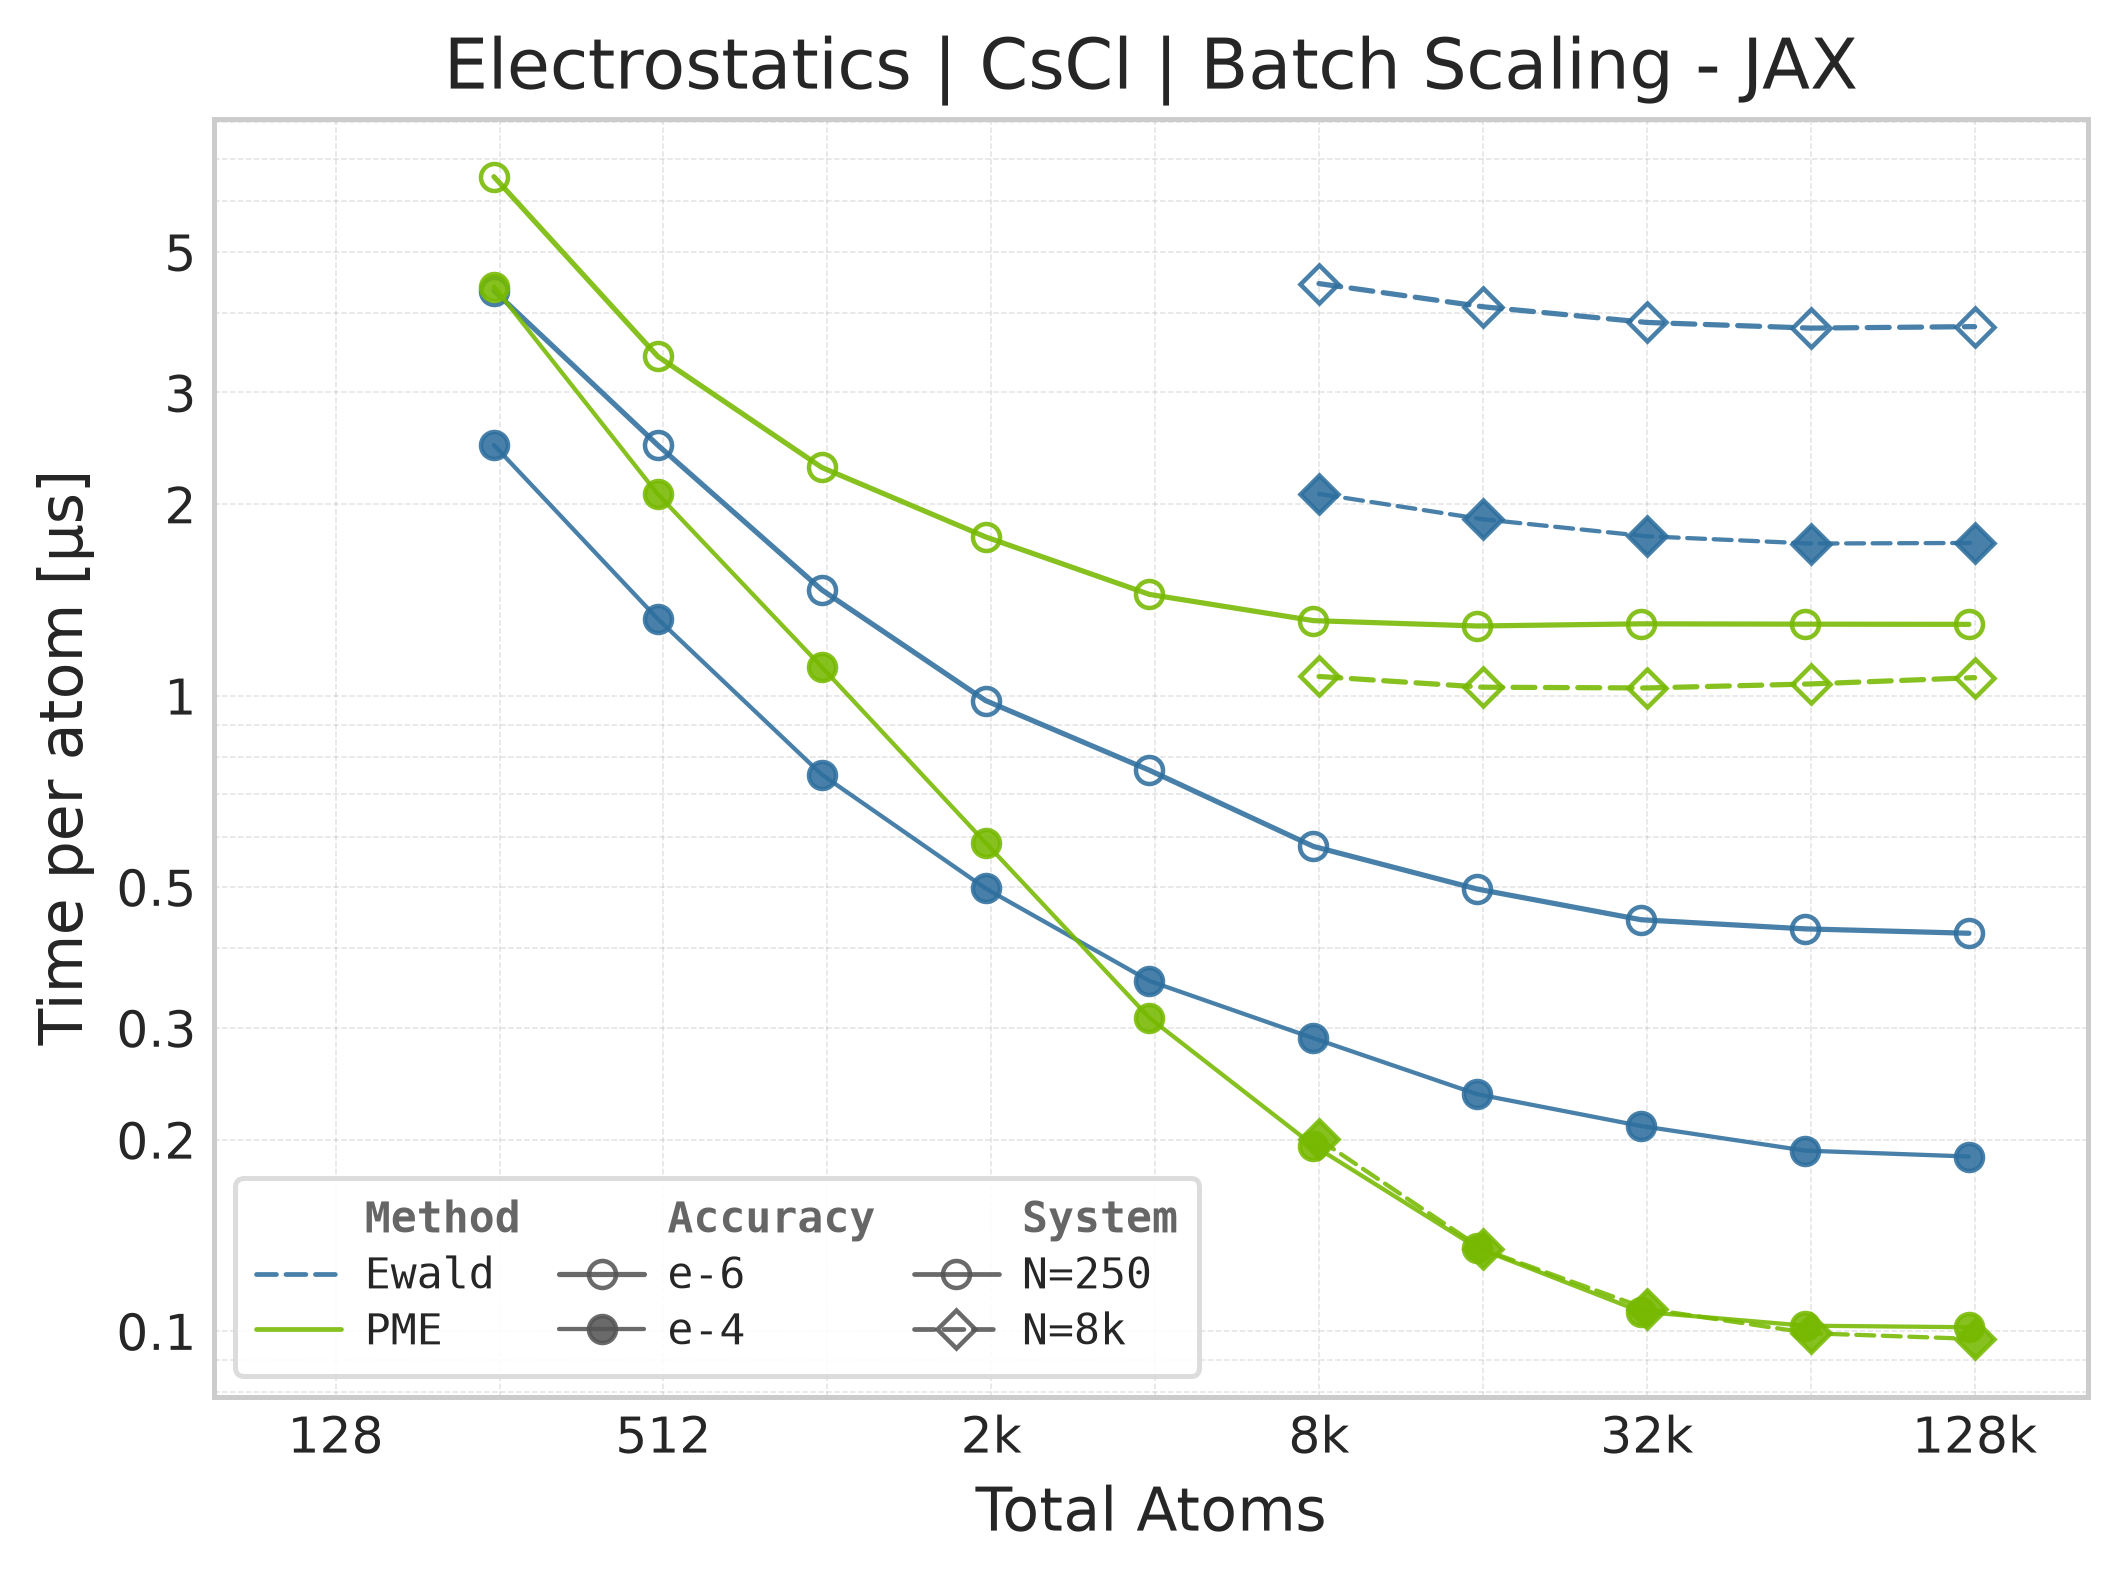
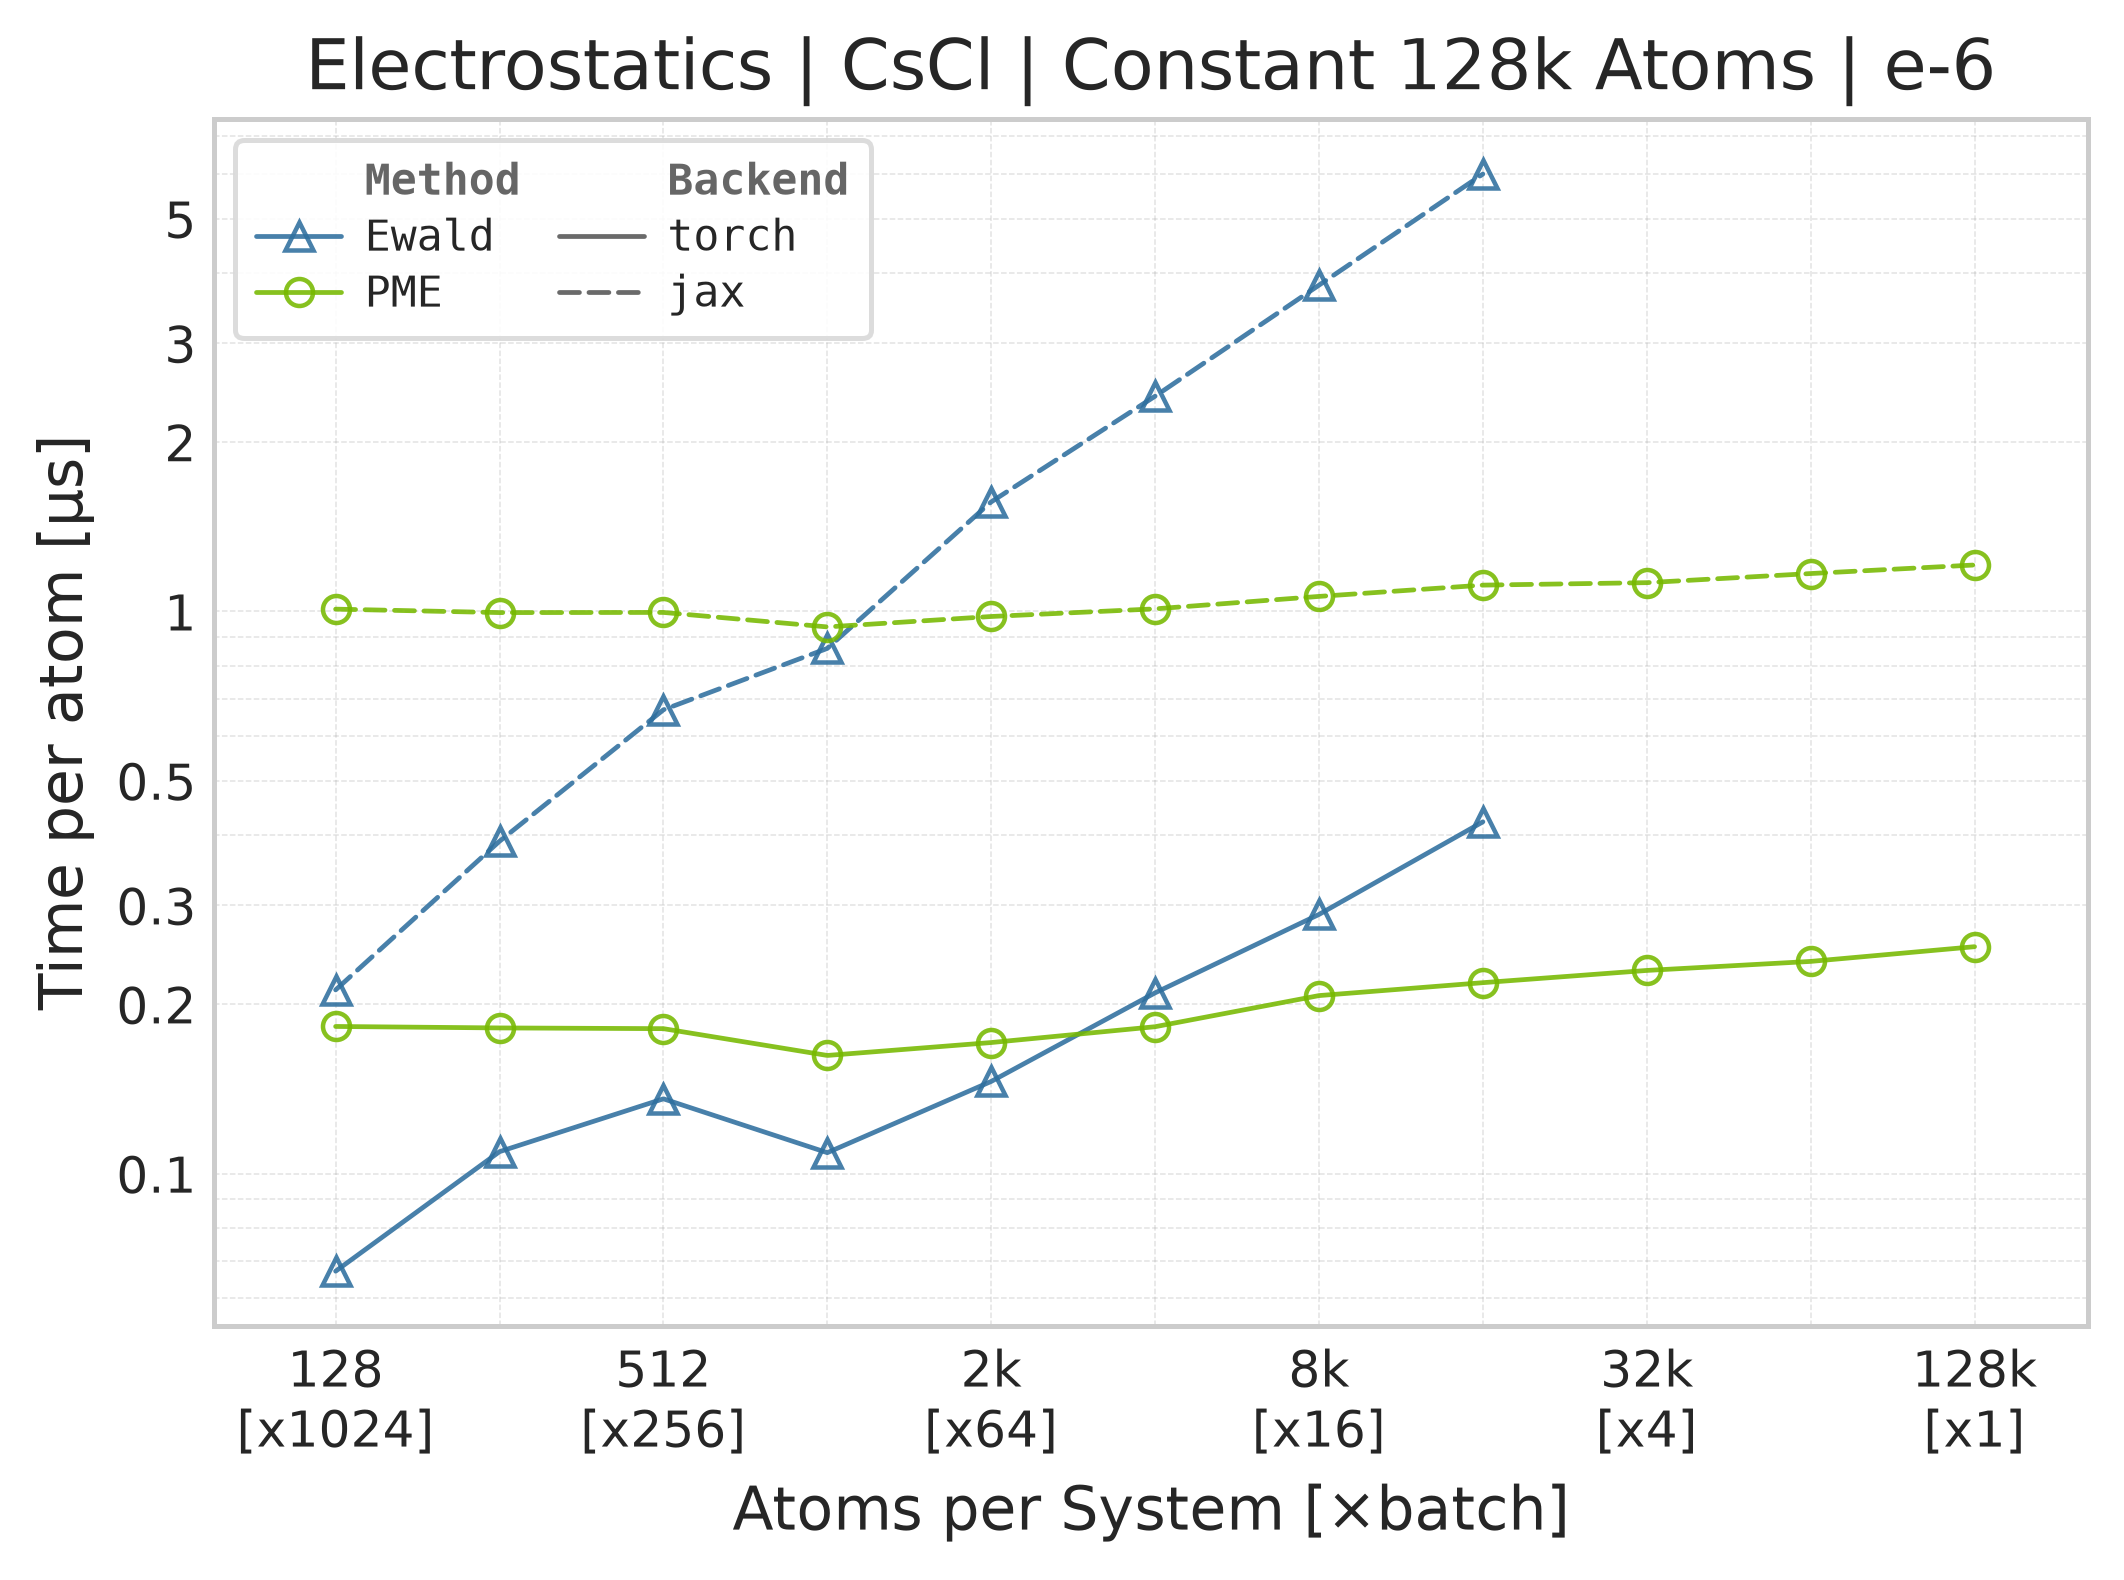
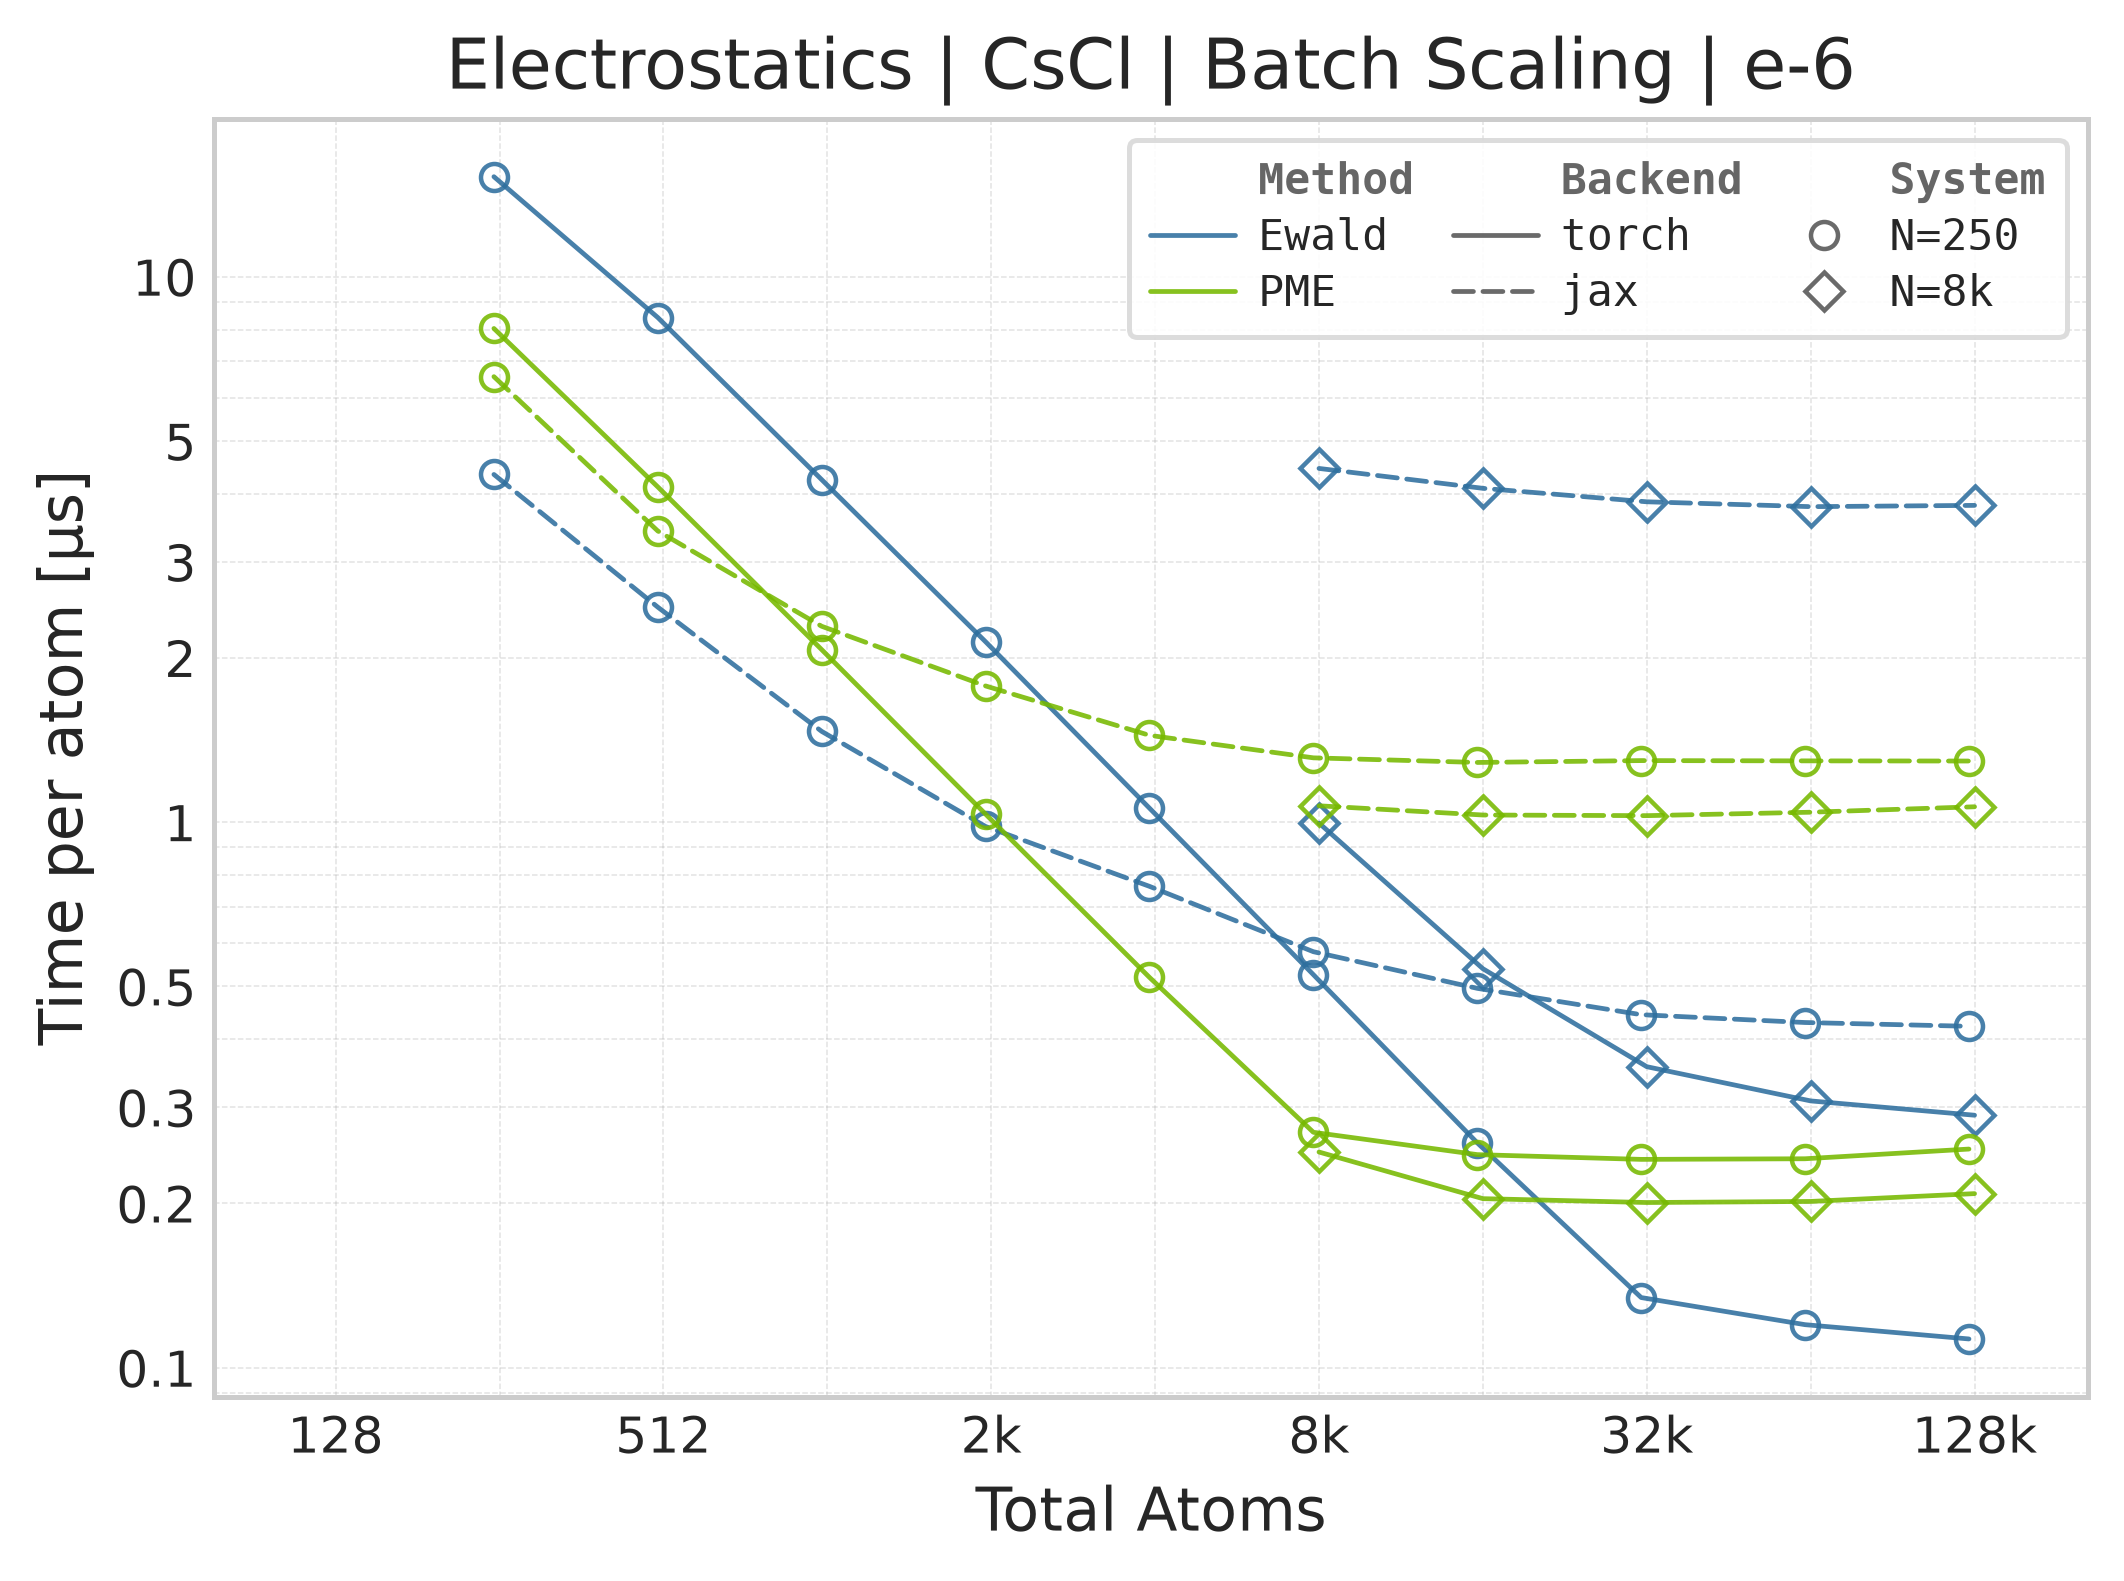
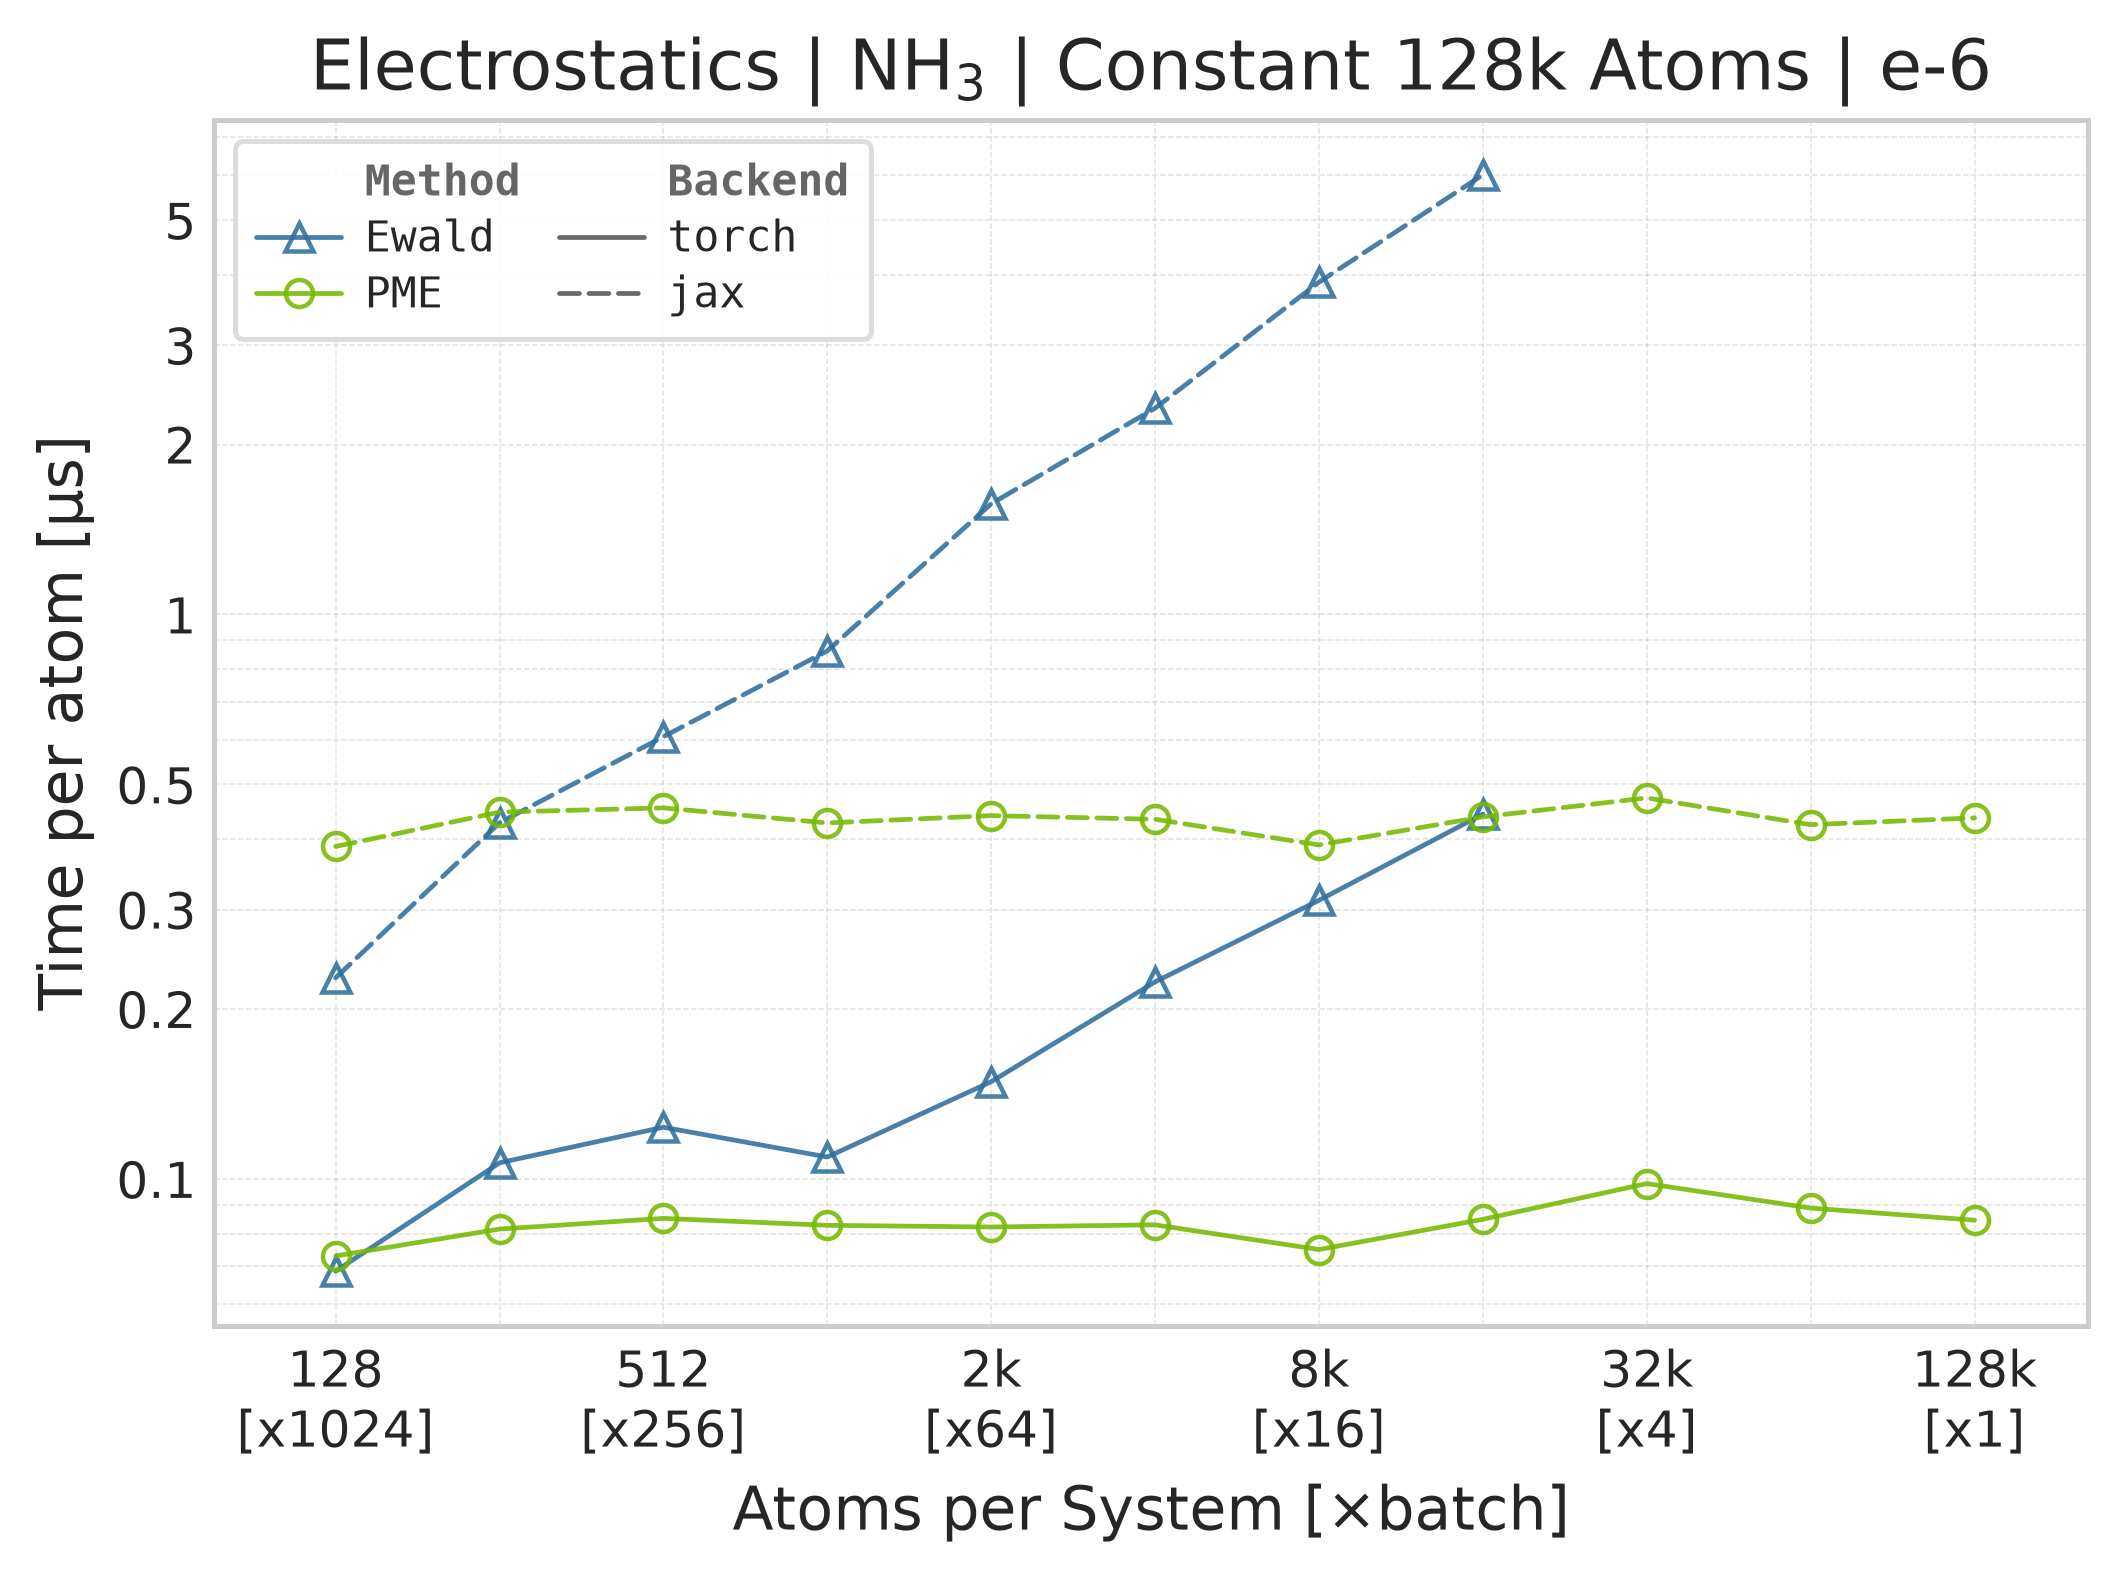
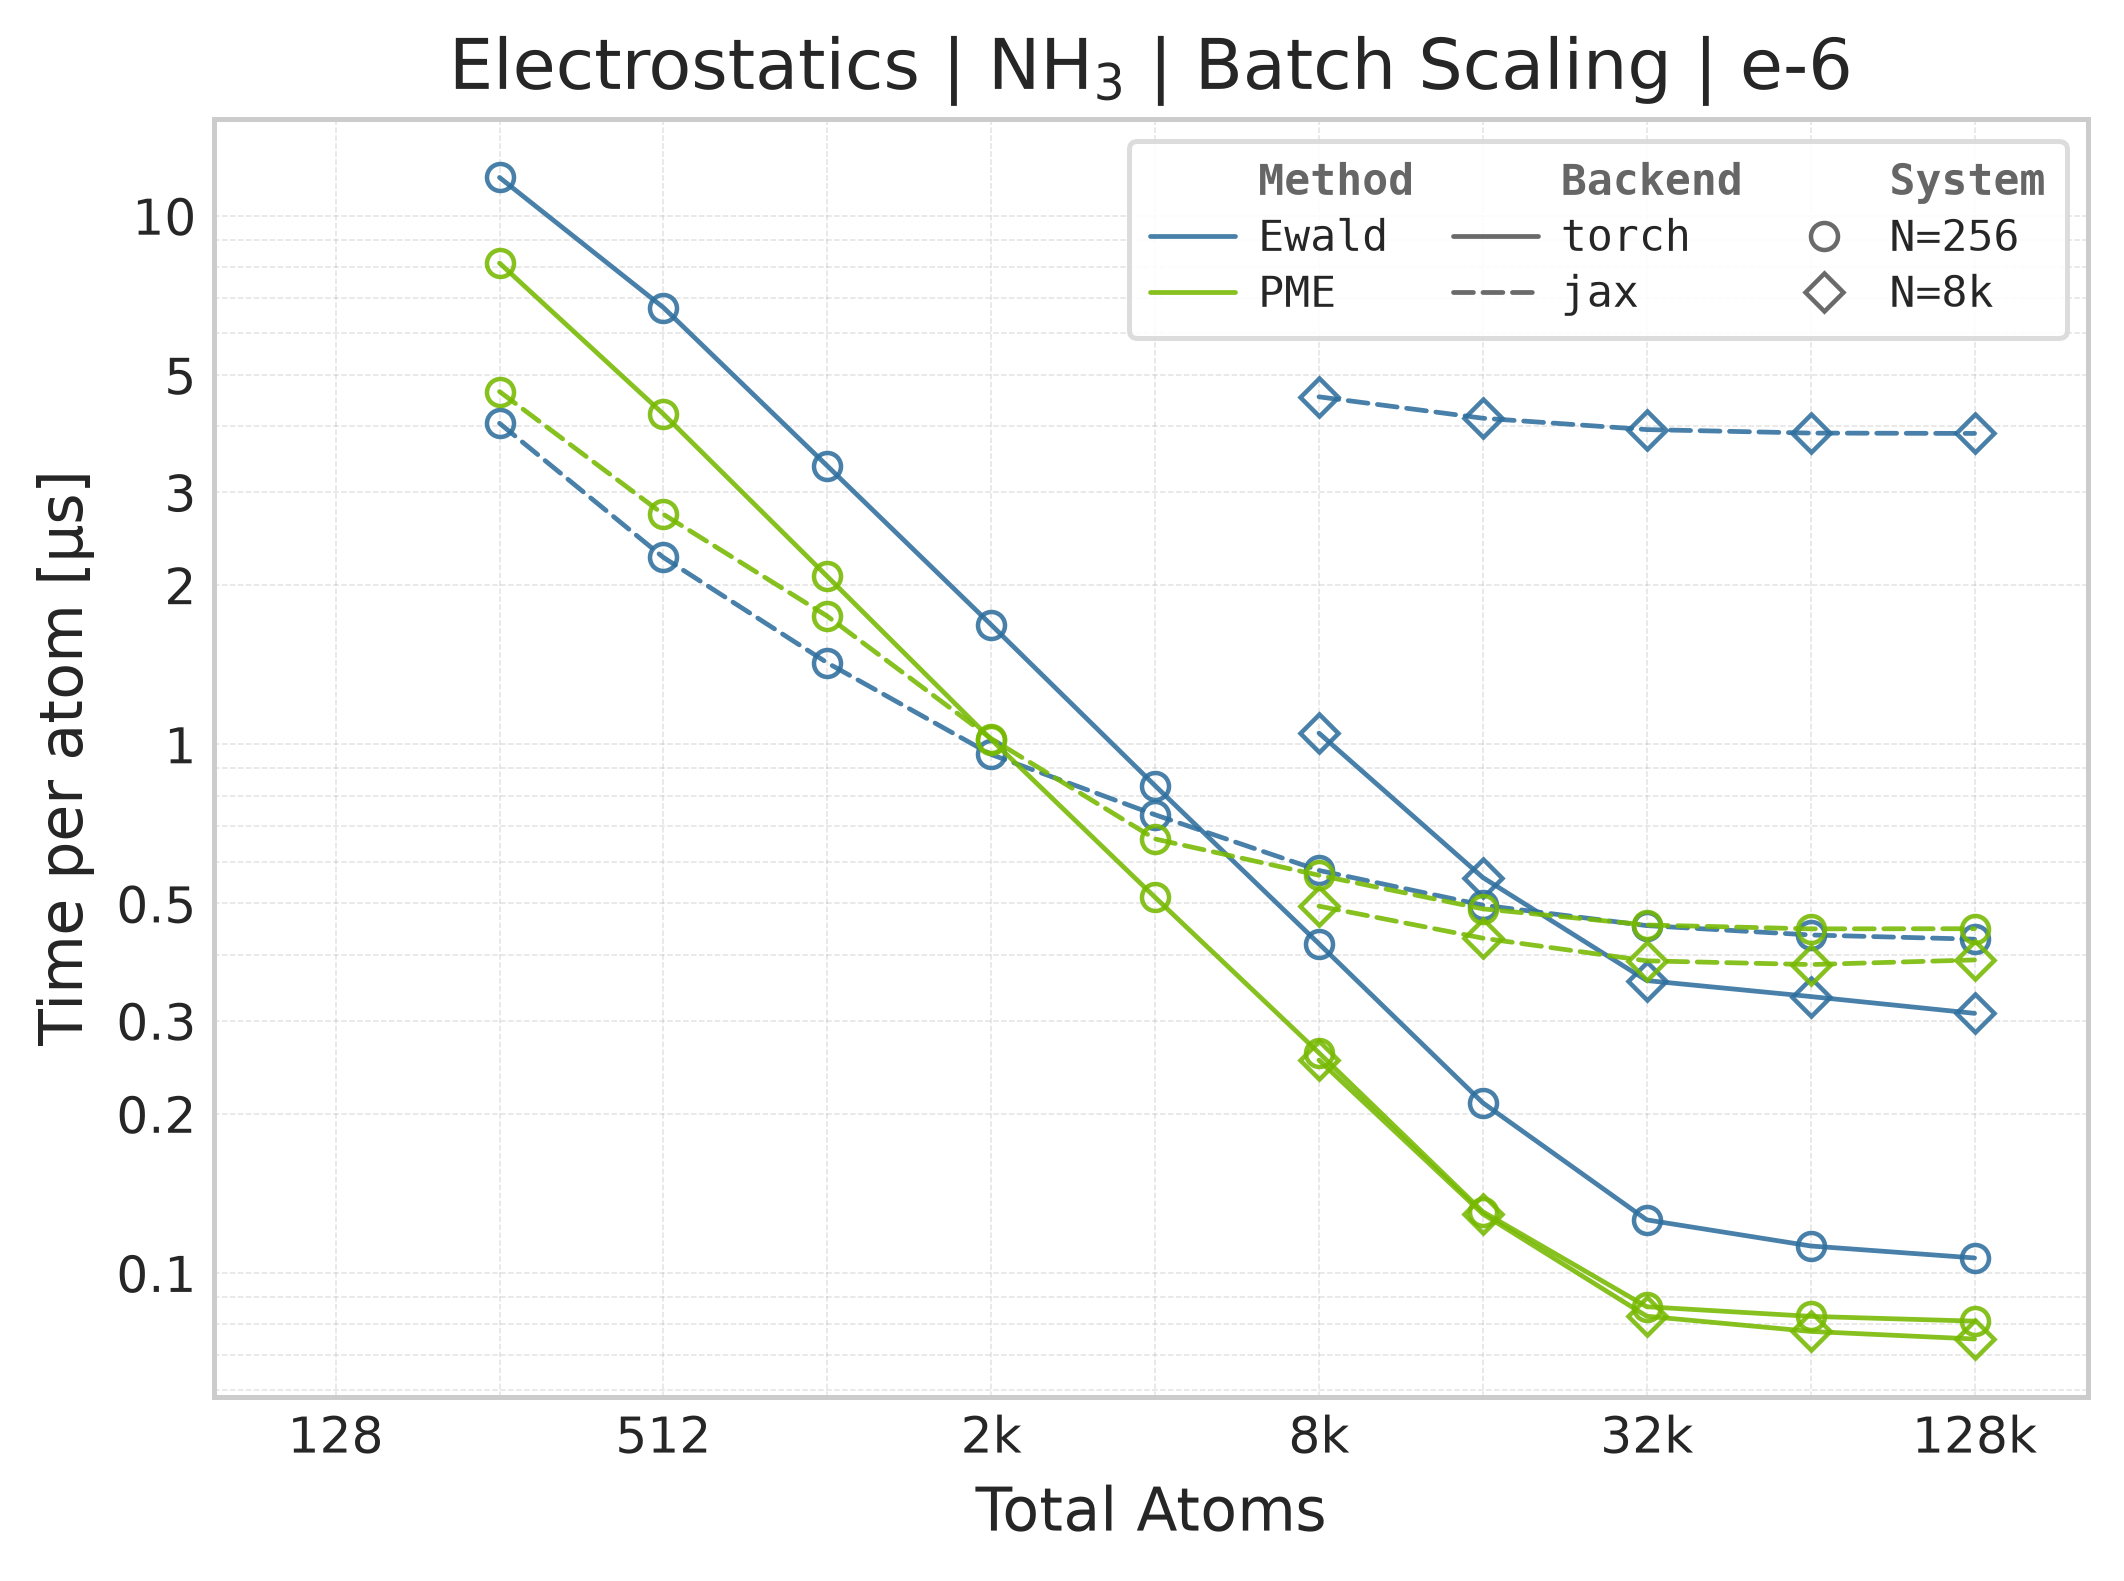
Time Scaling : Mean execution time (µs/atom) vs. system size. Lower is better. Timings include both real-space and reciprocal-space contributions when running “full” mode.
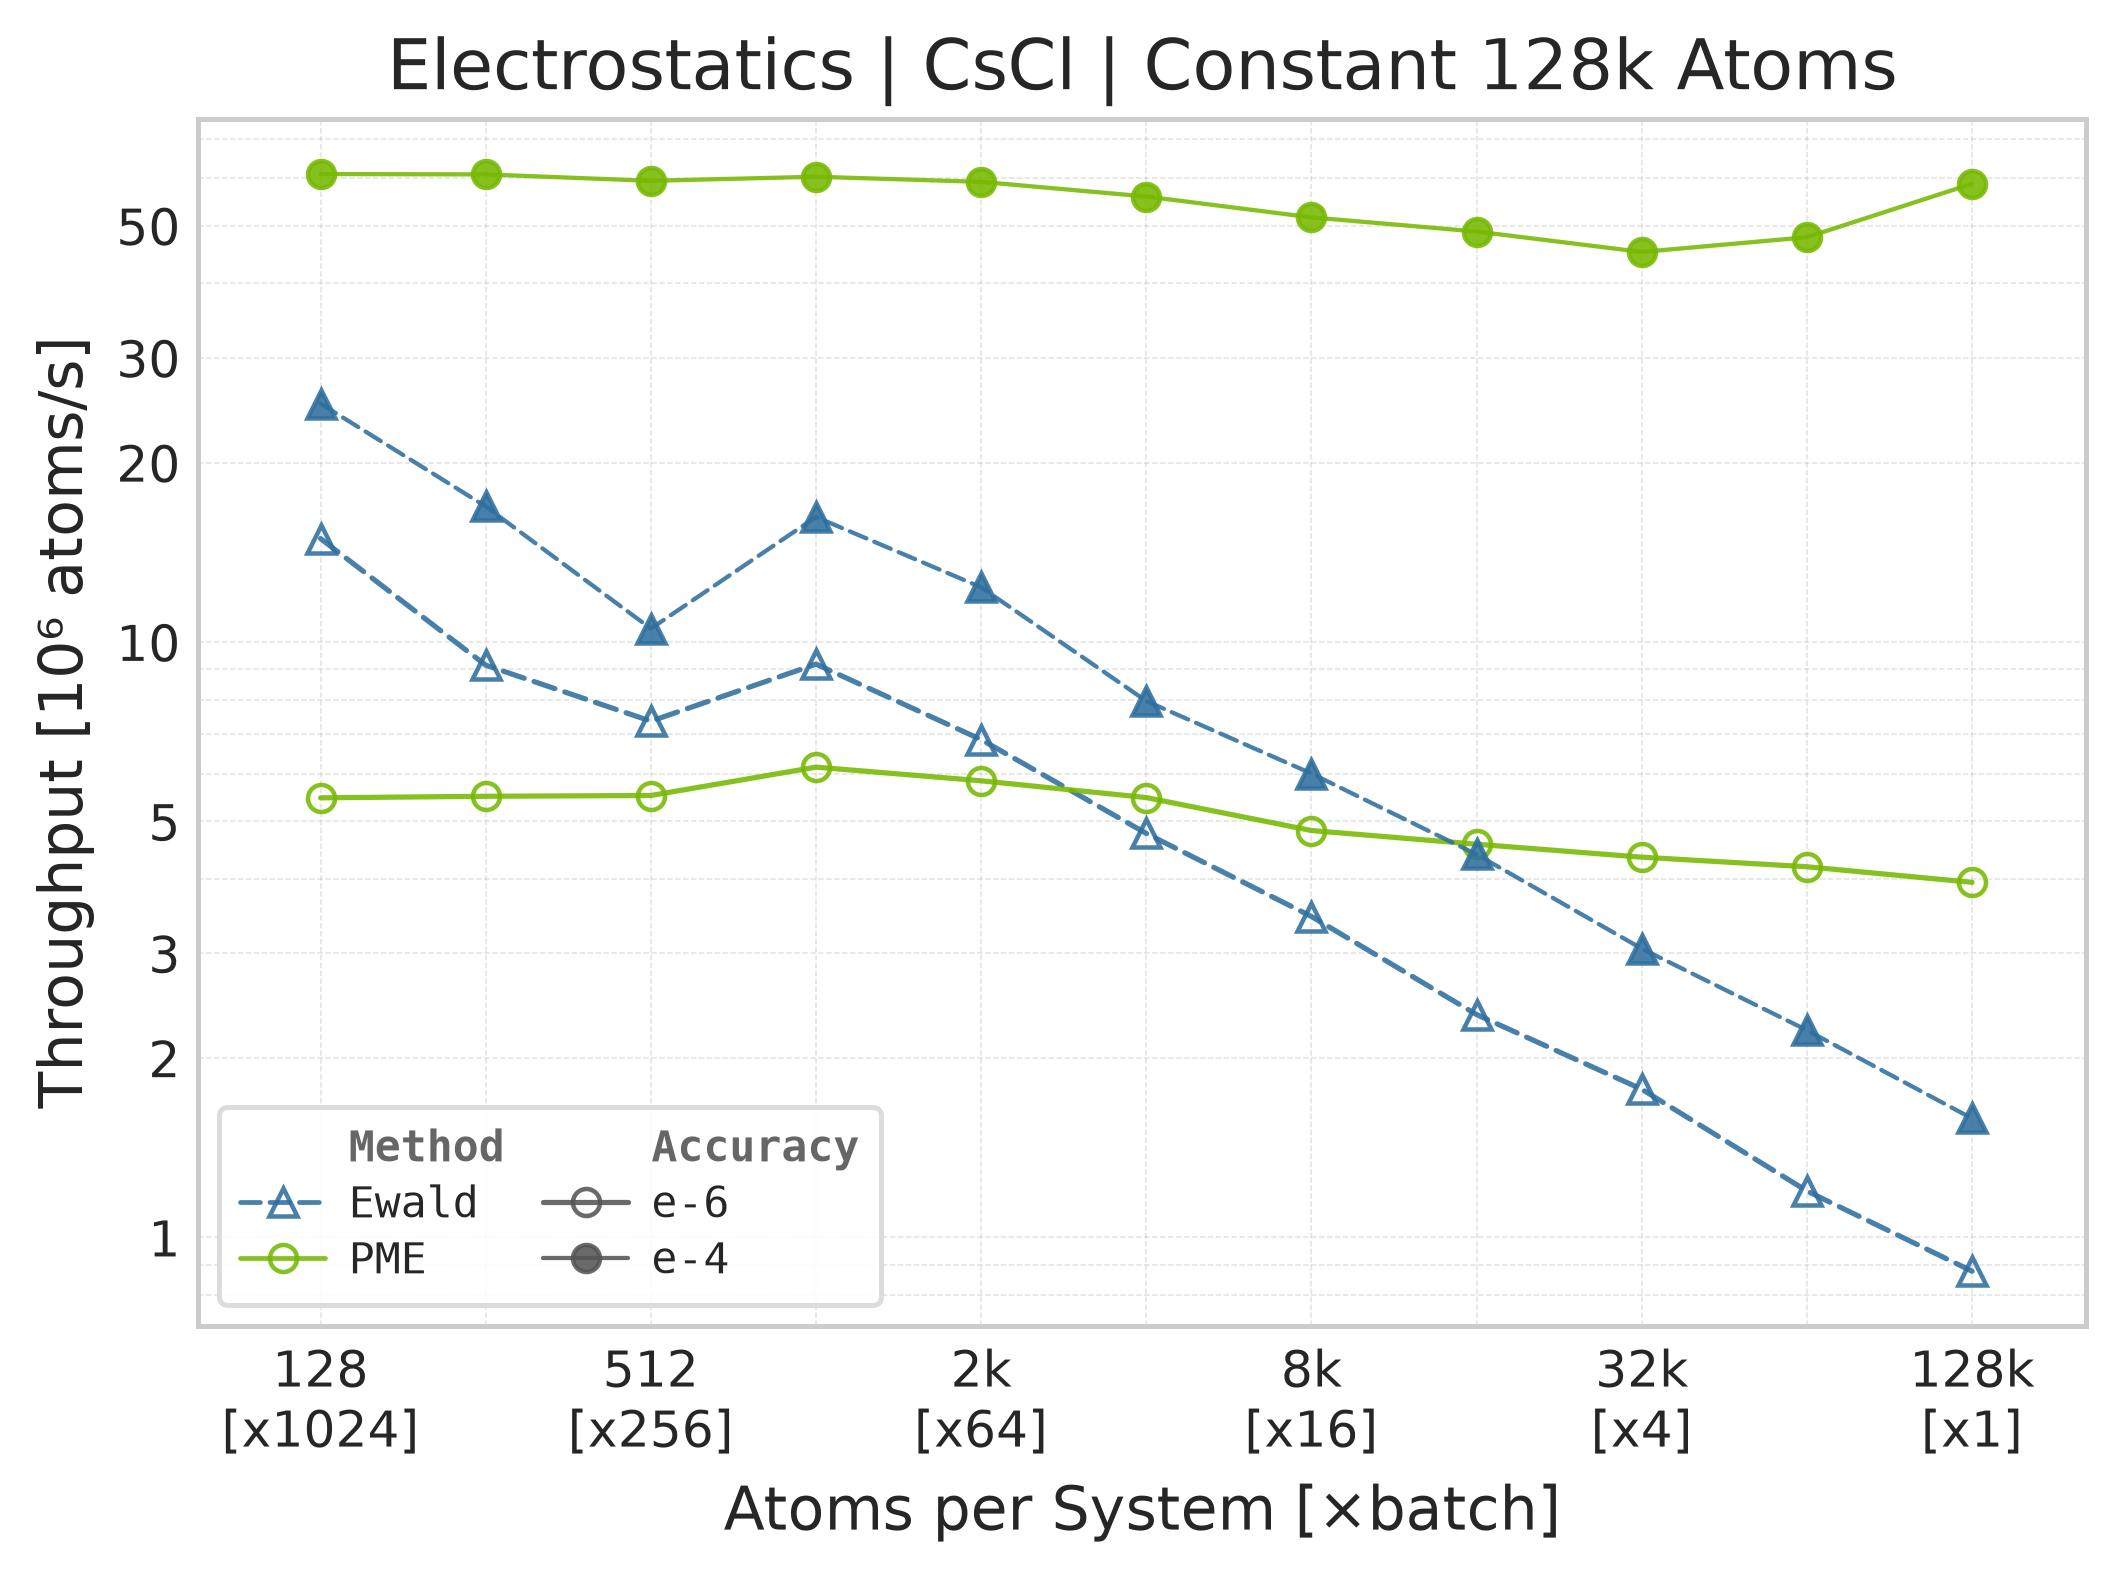
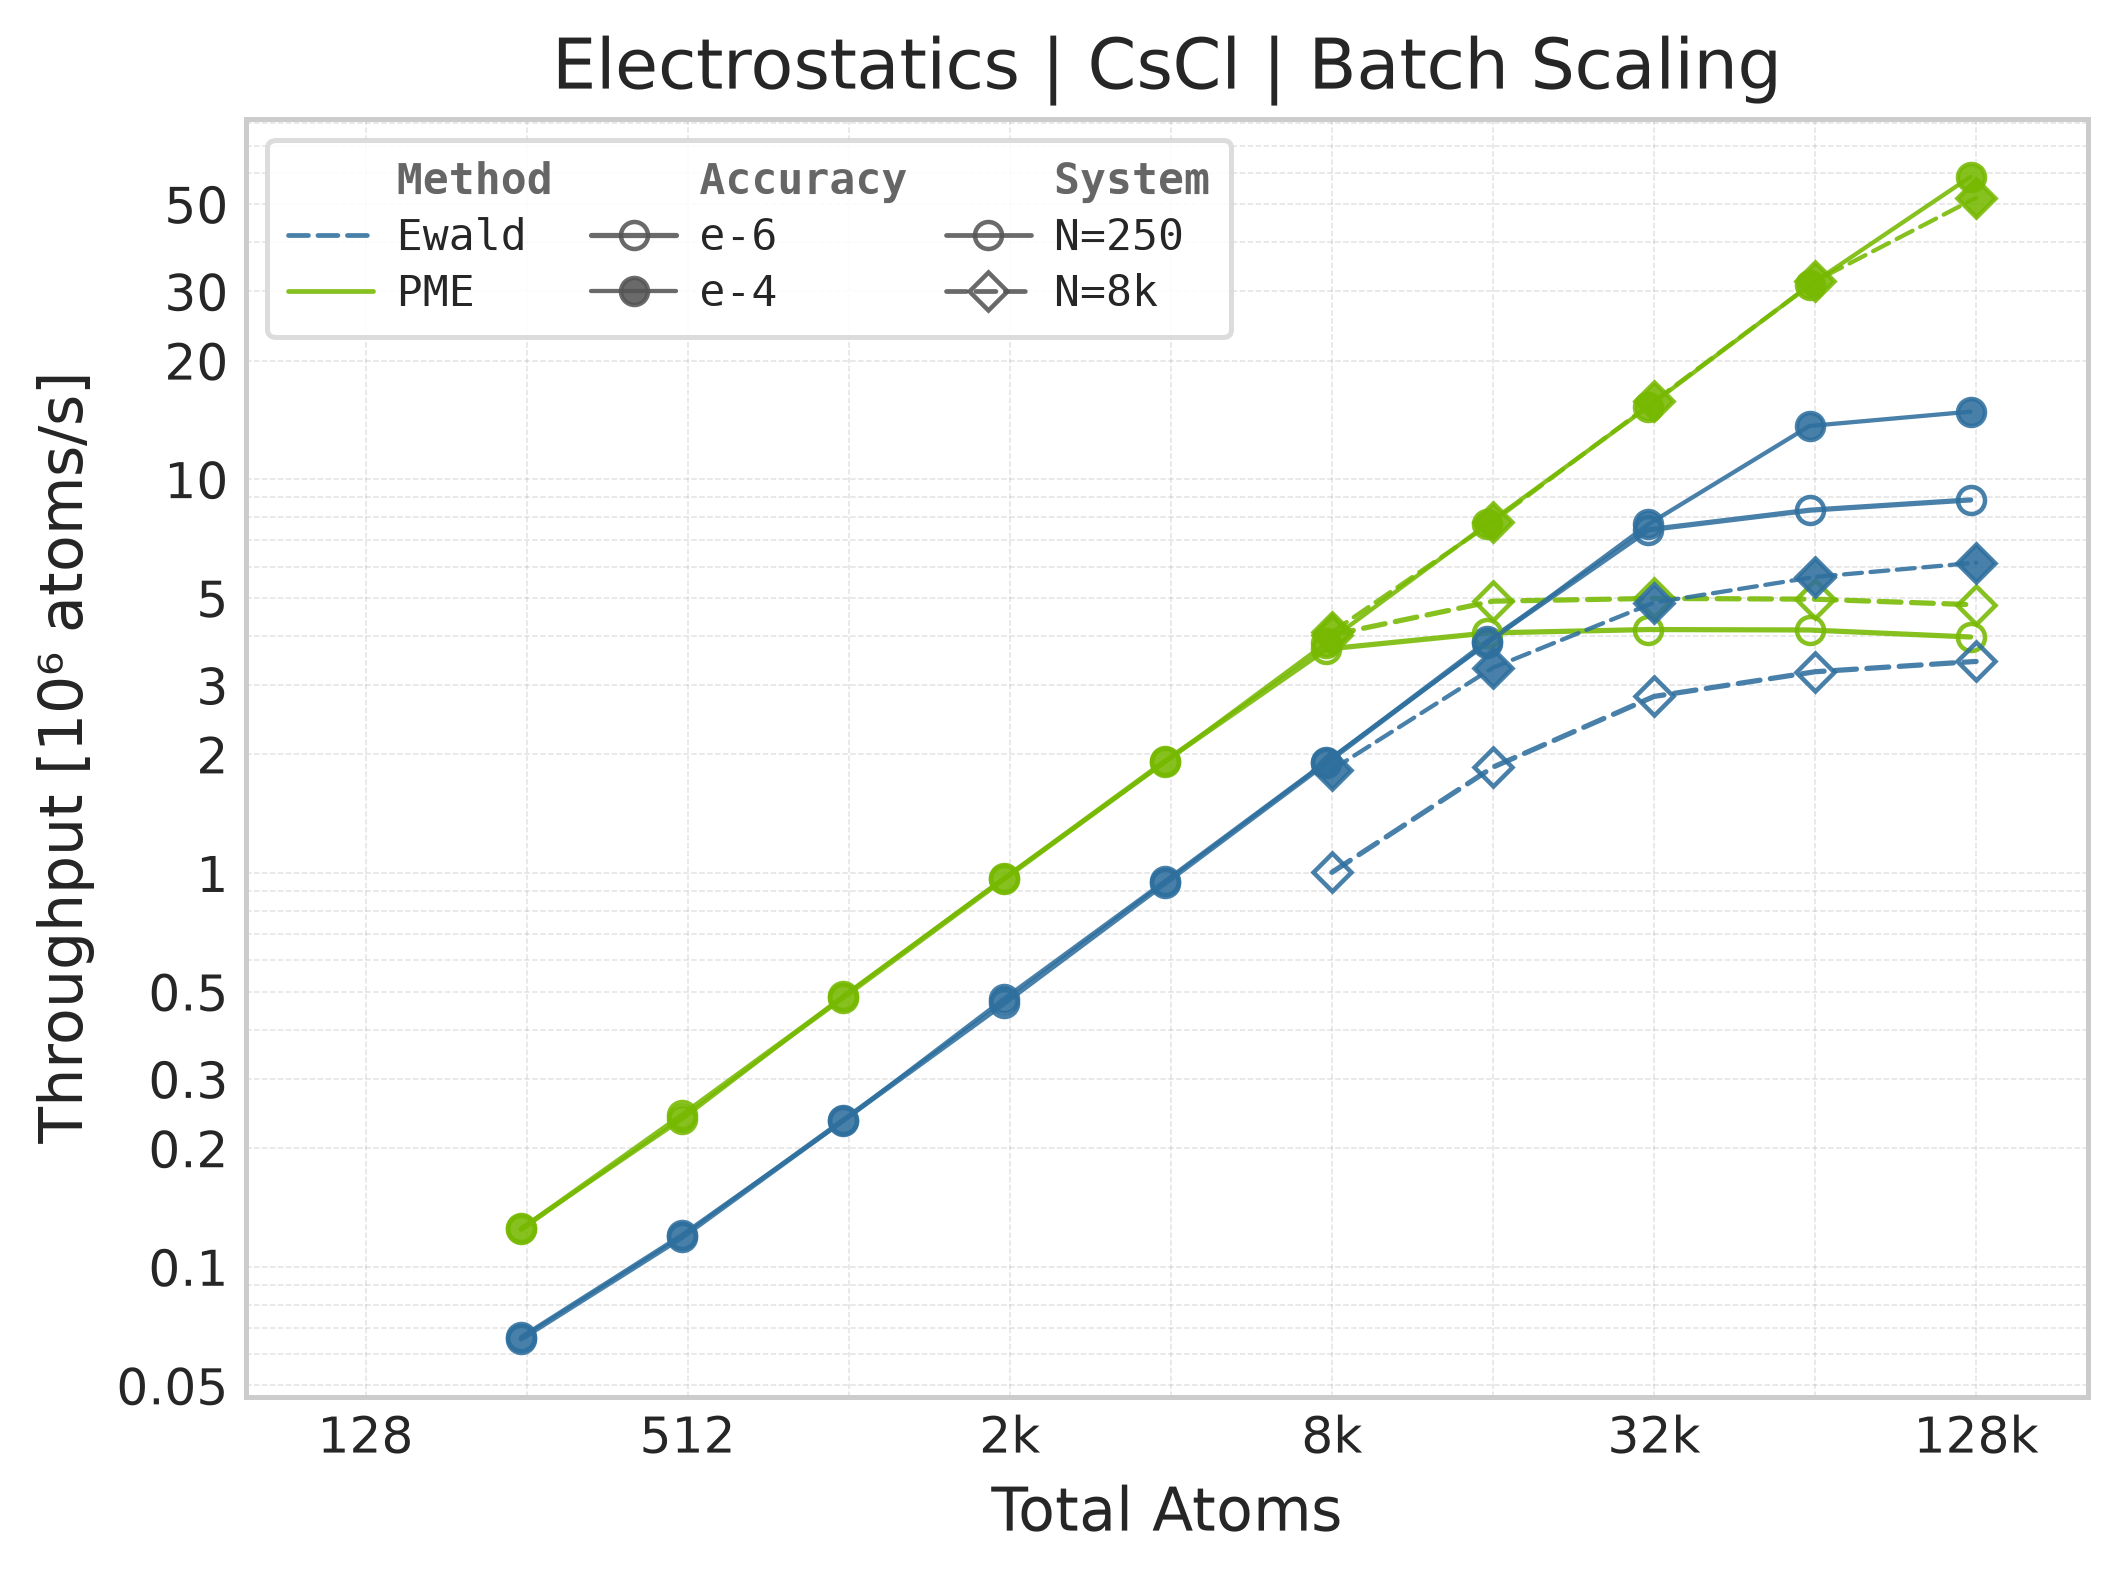
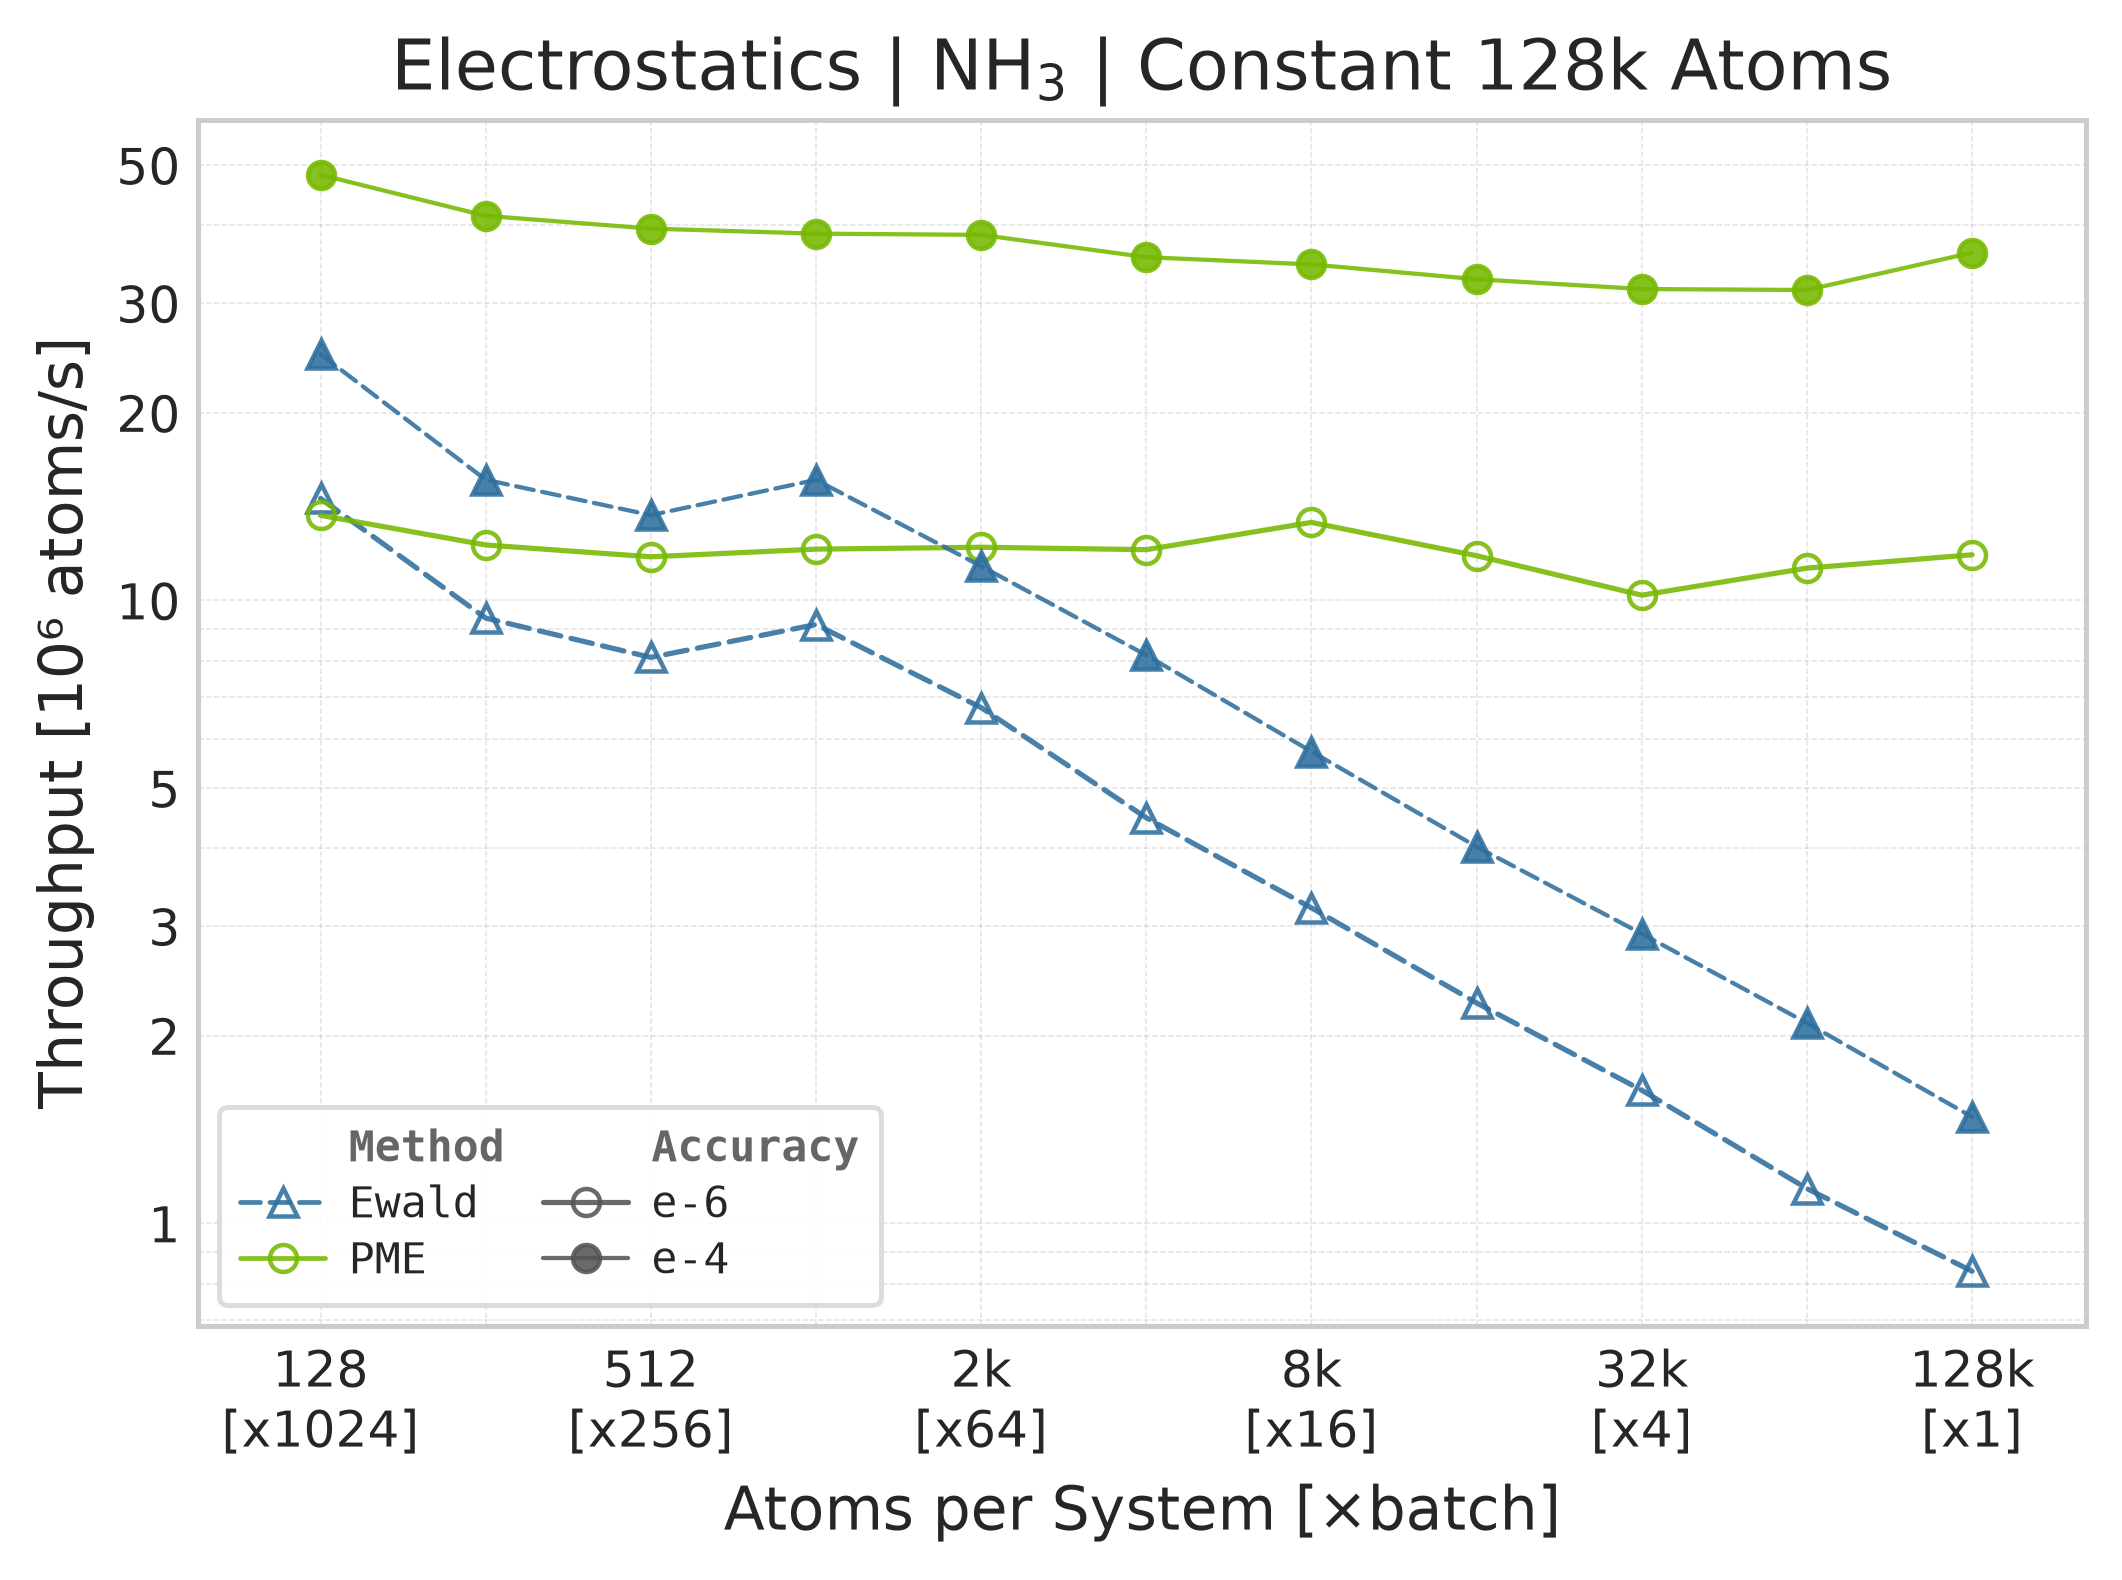
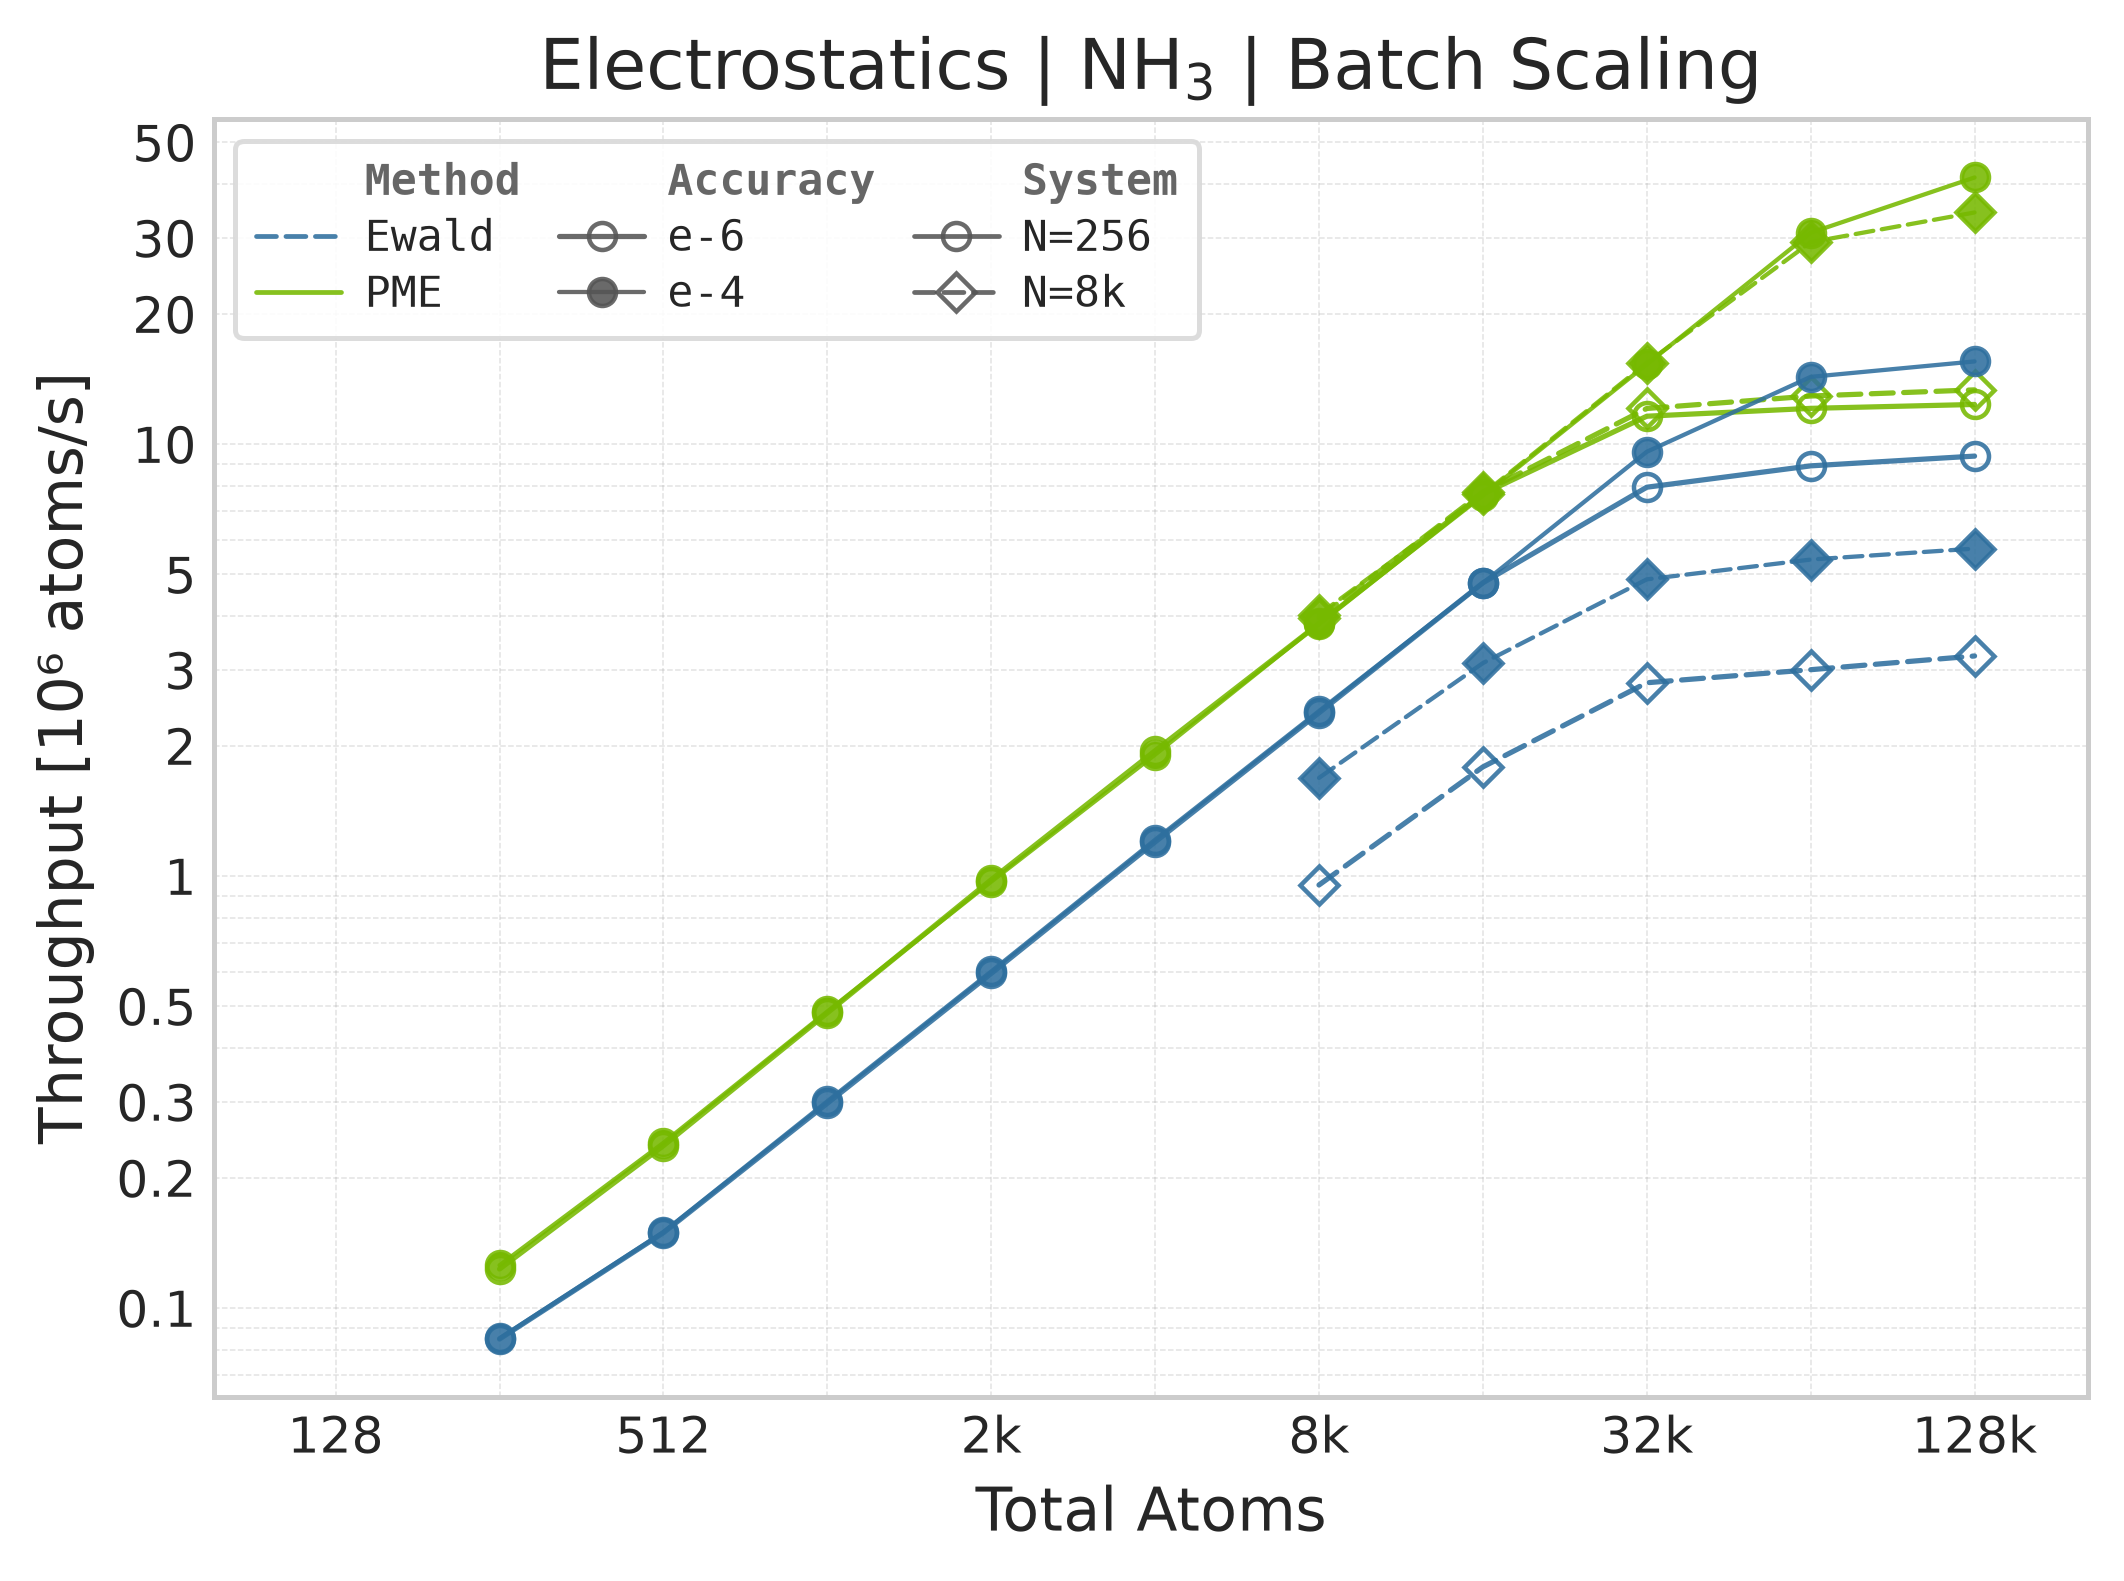
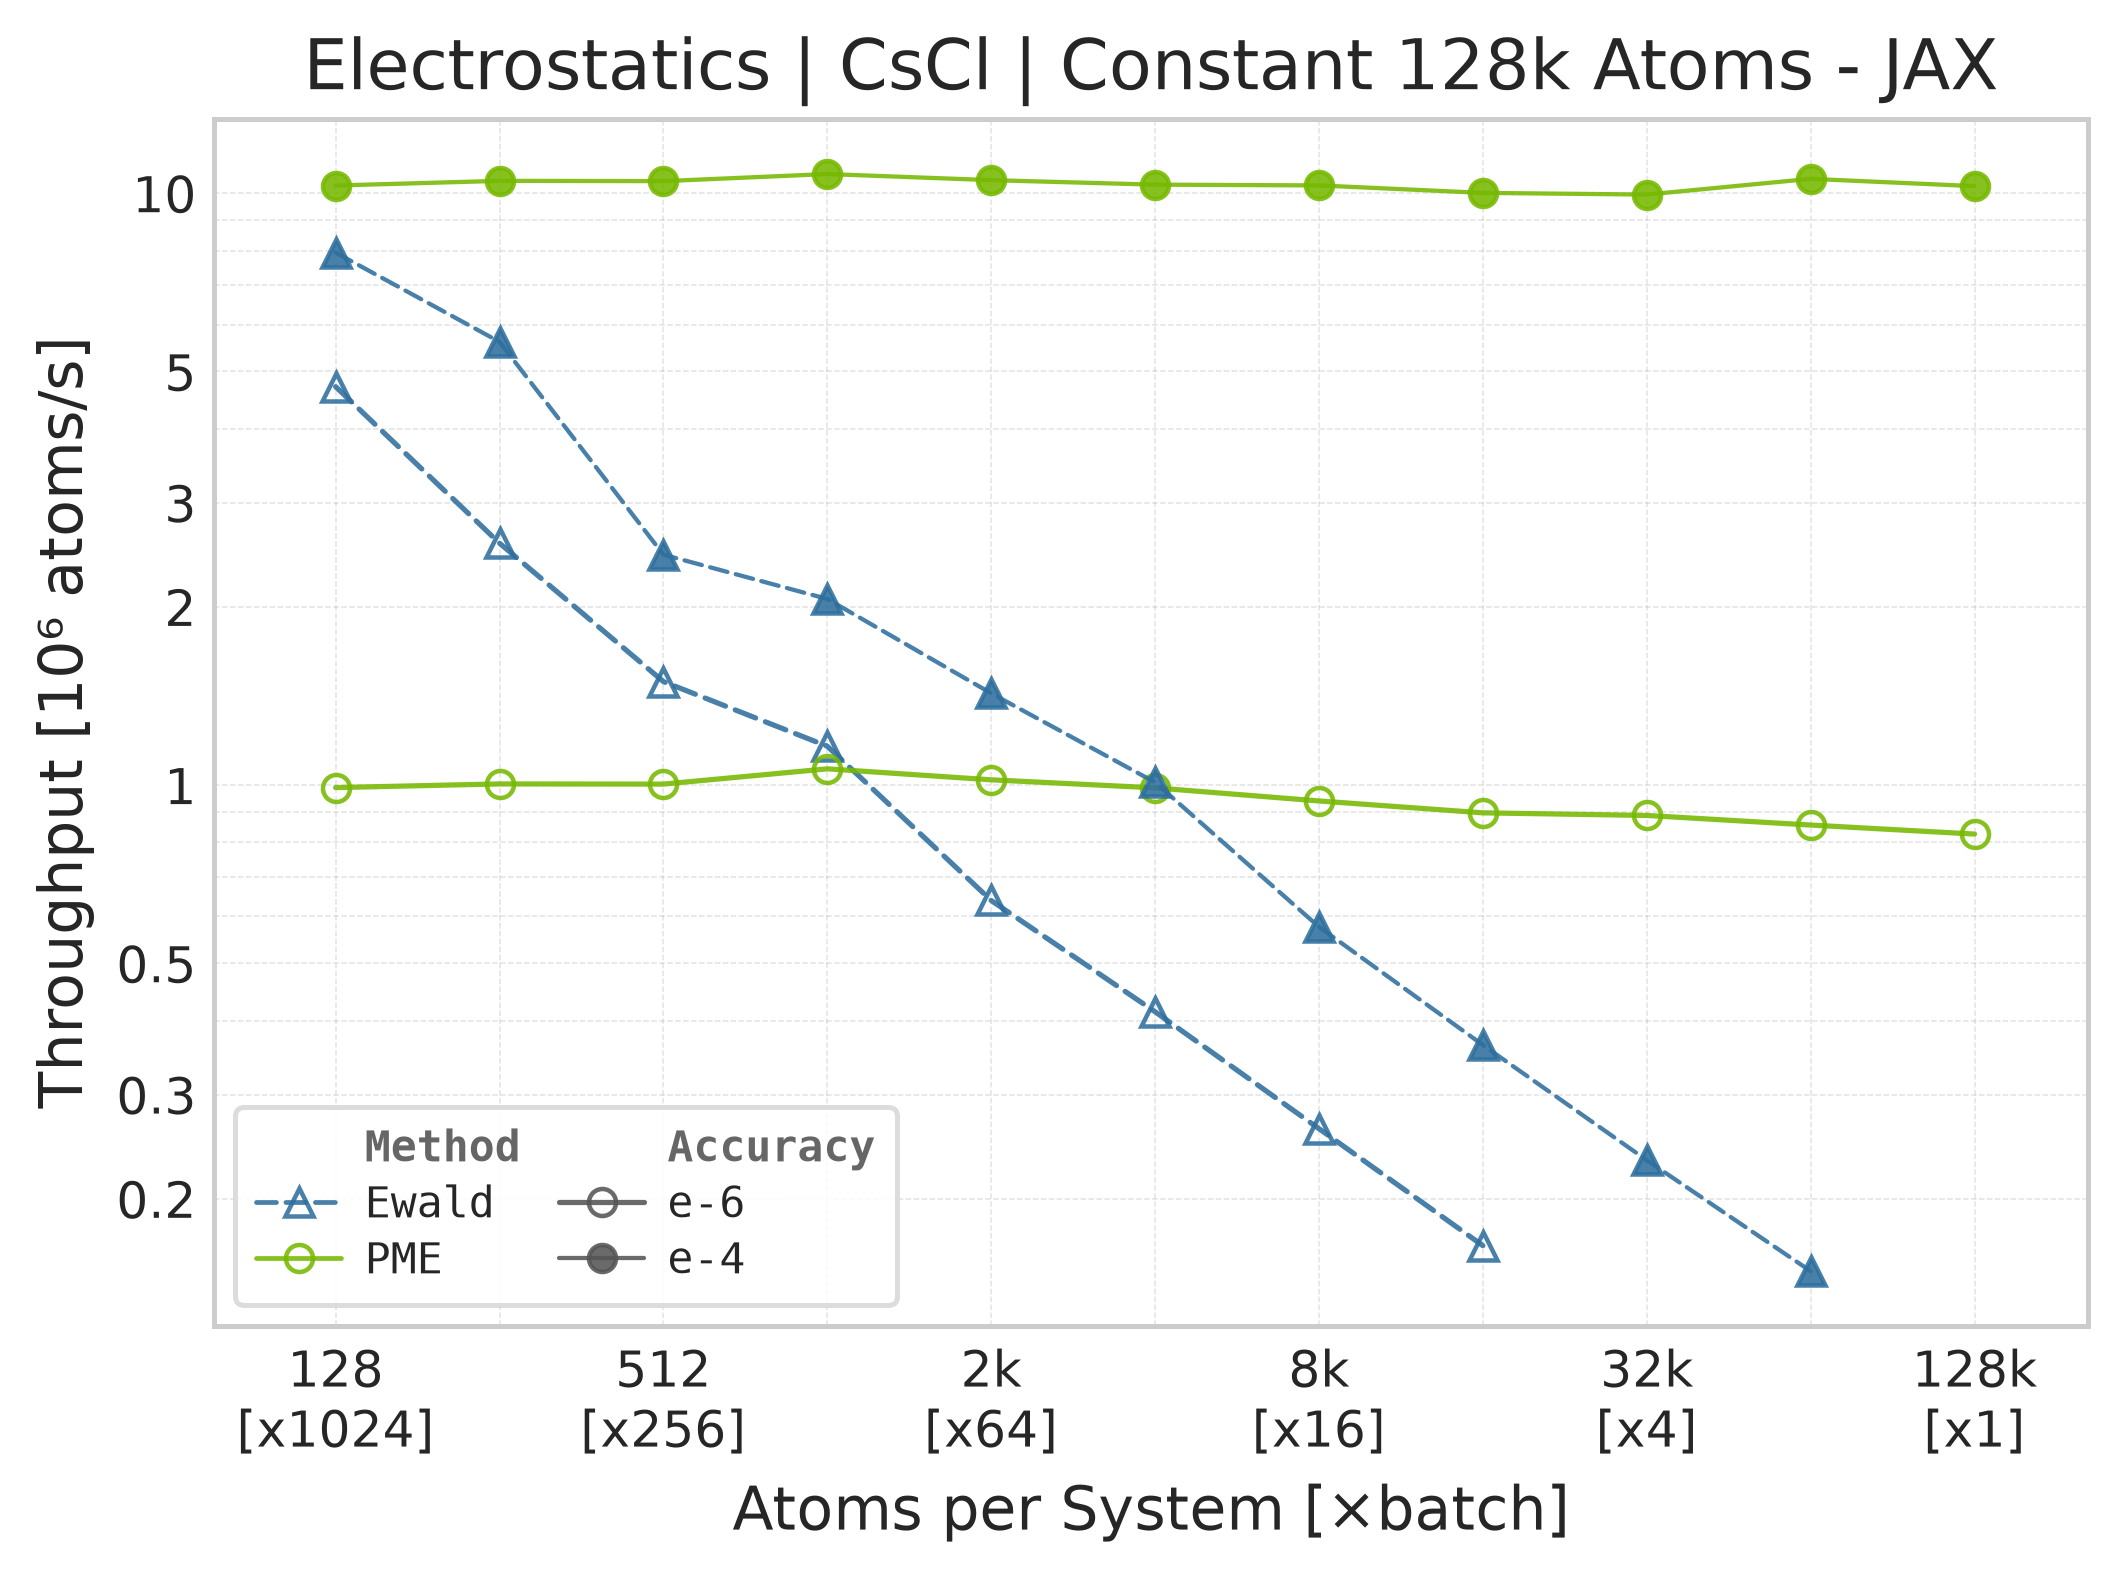
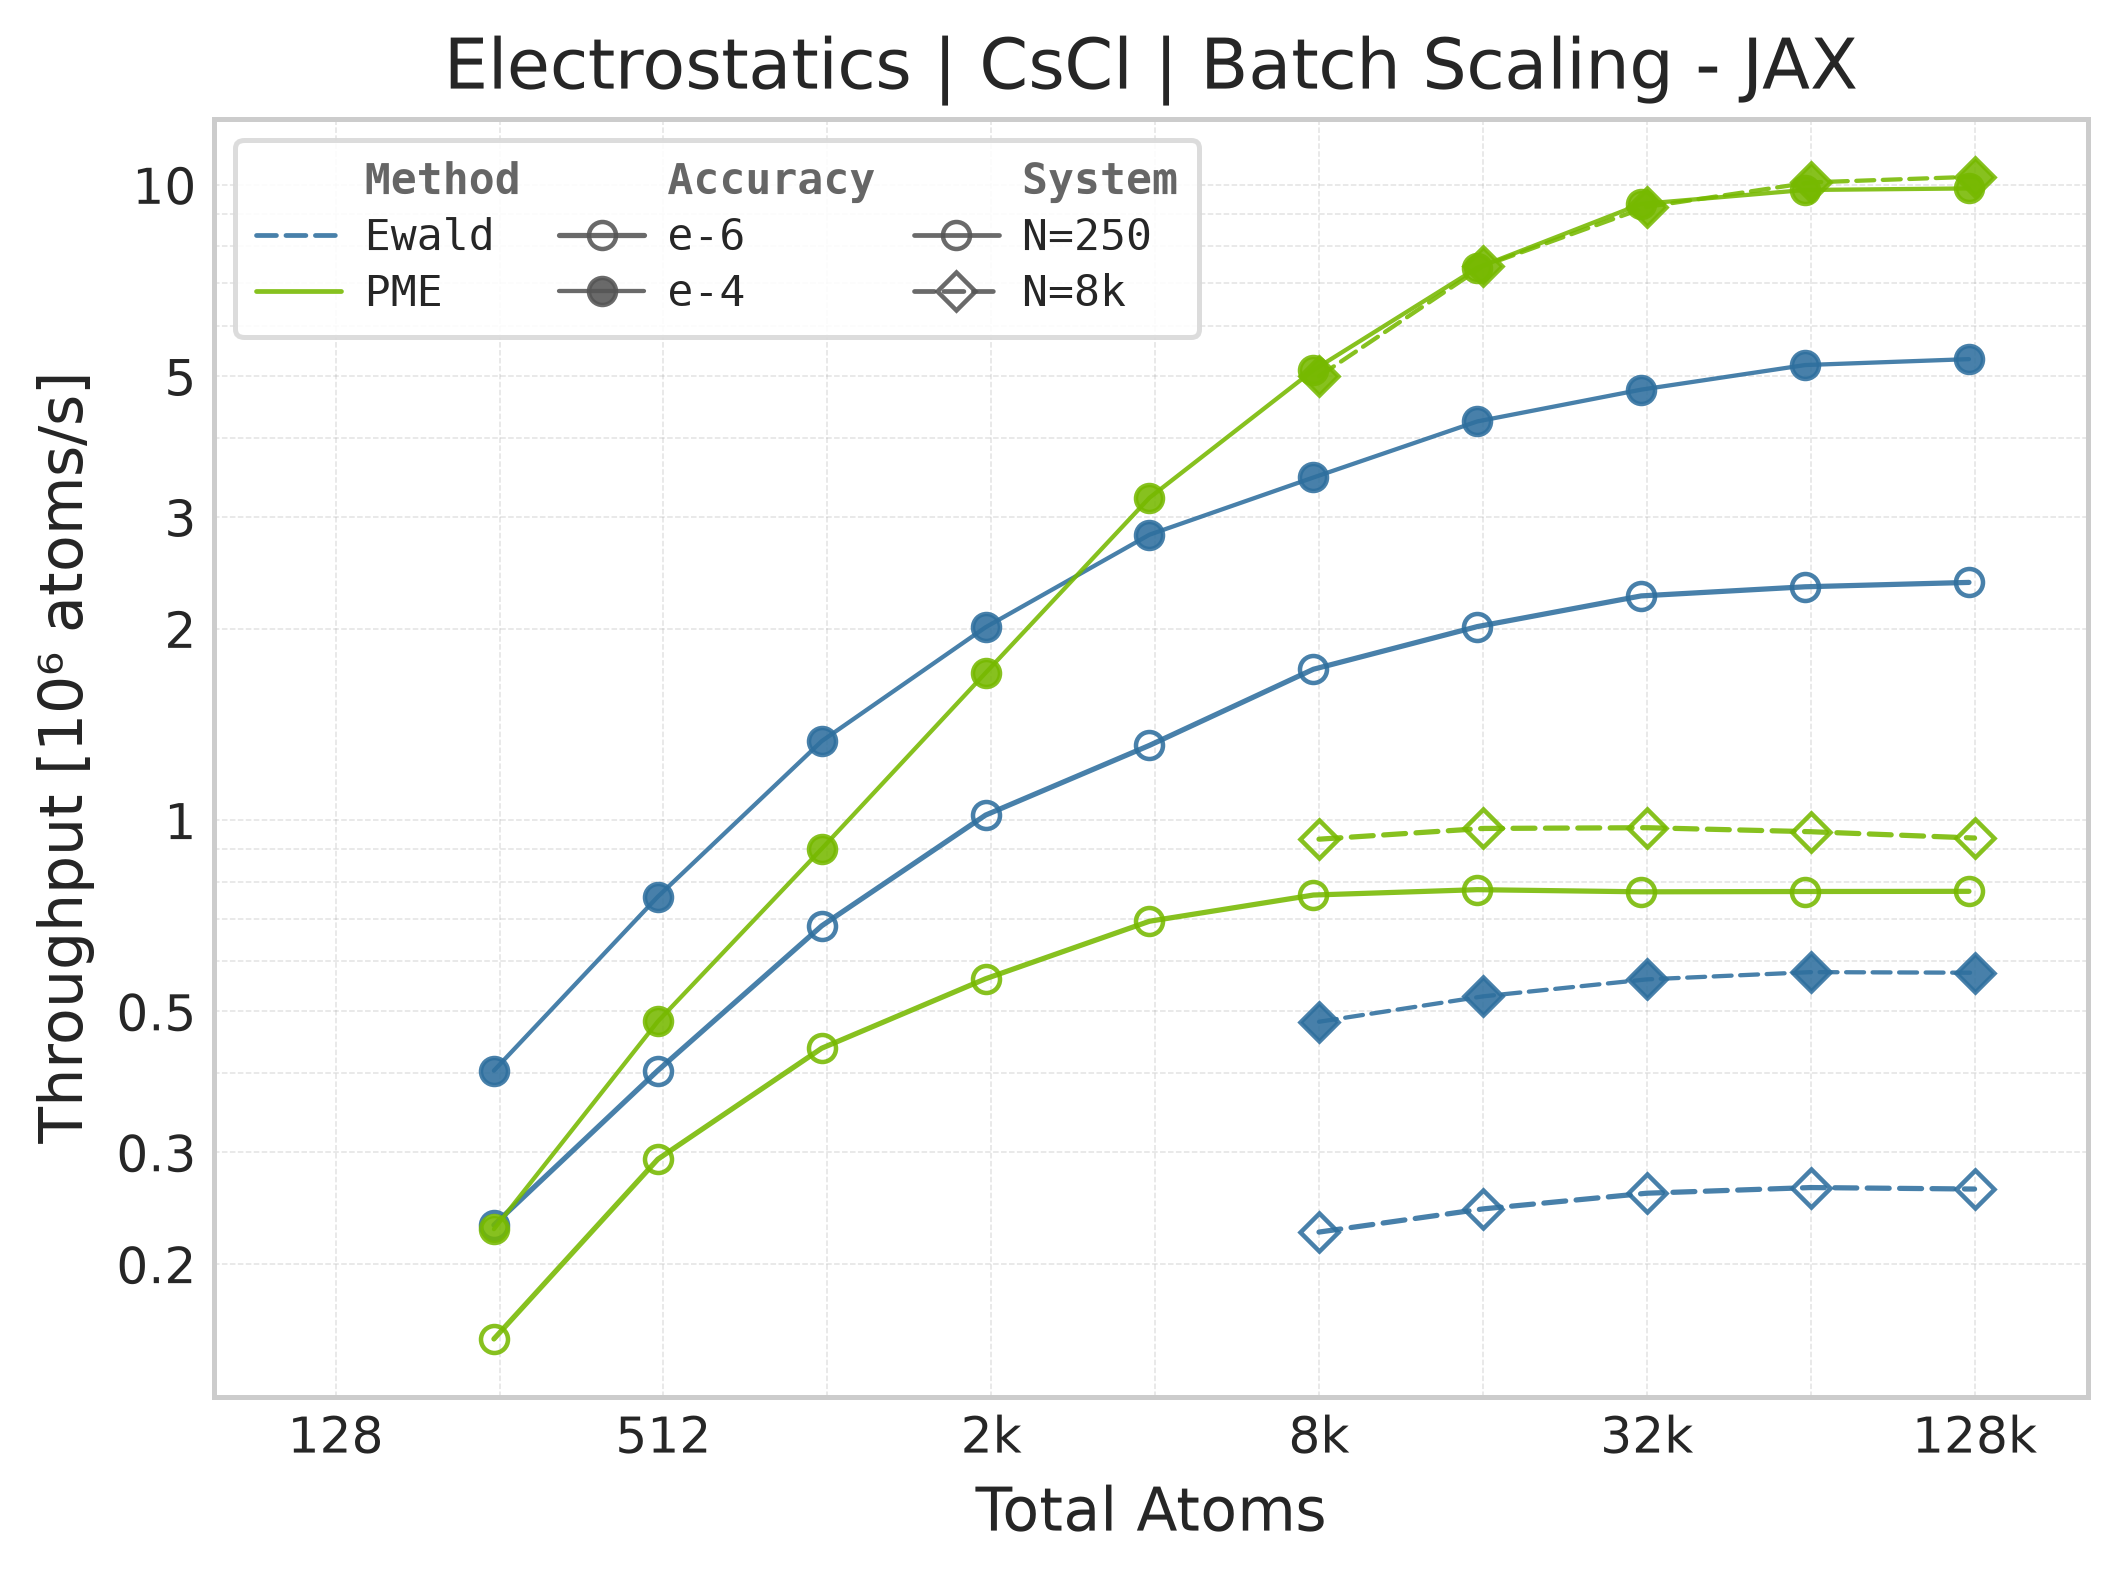
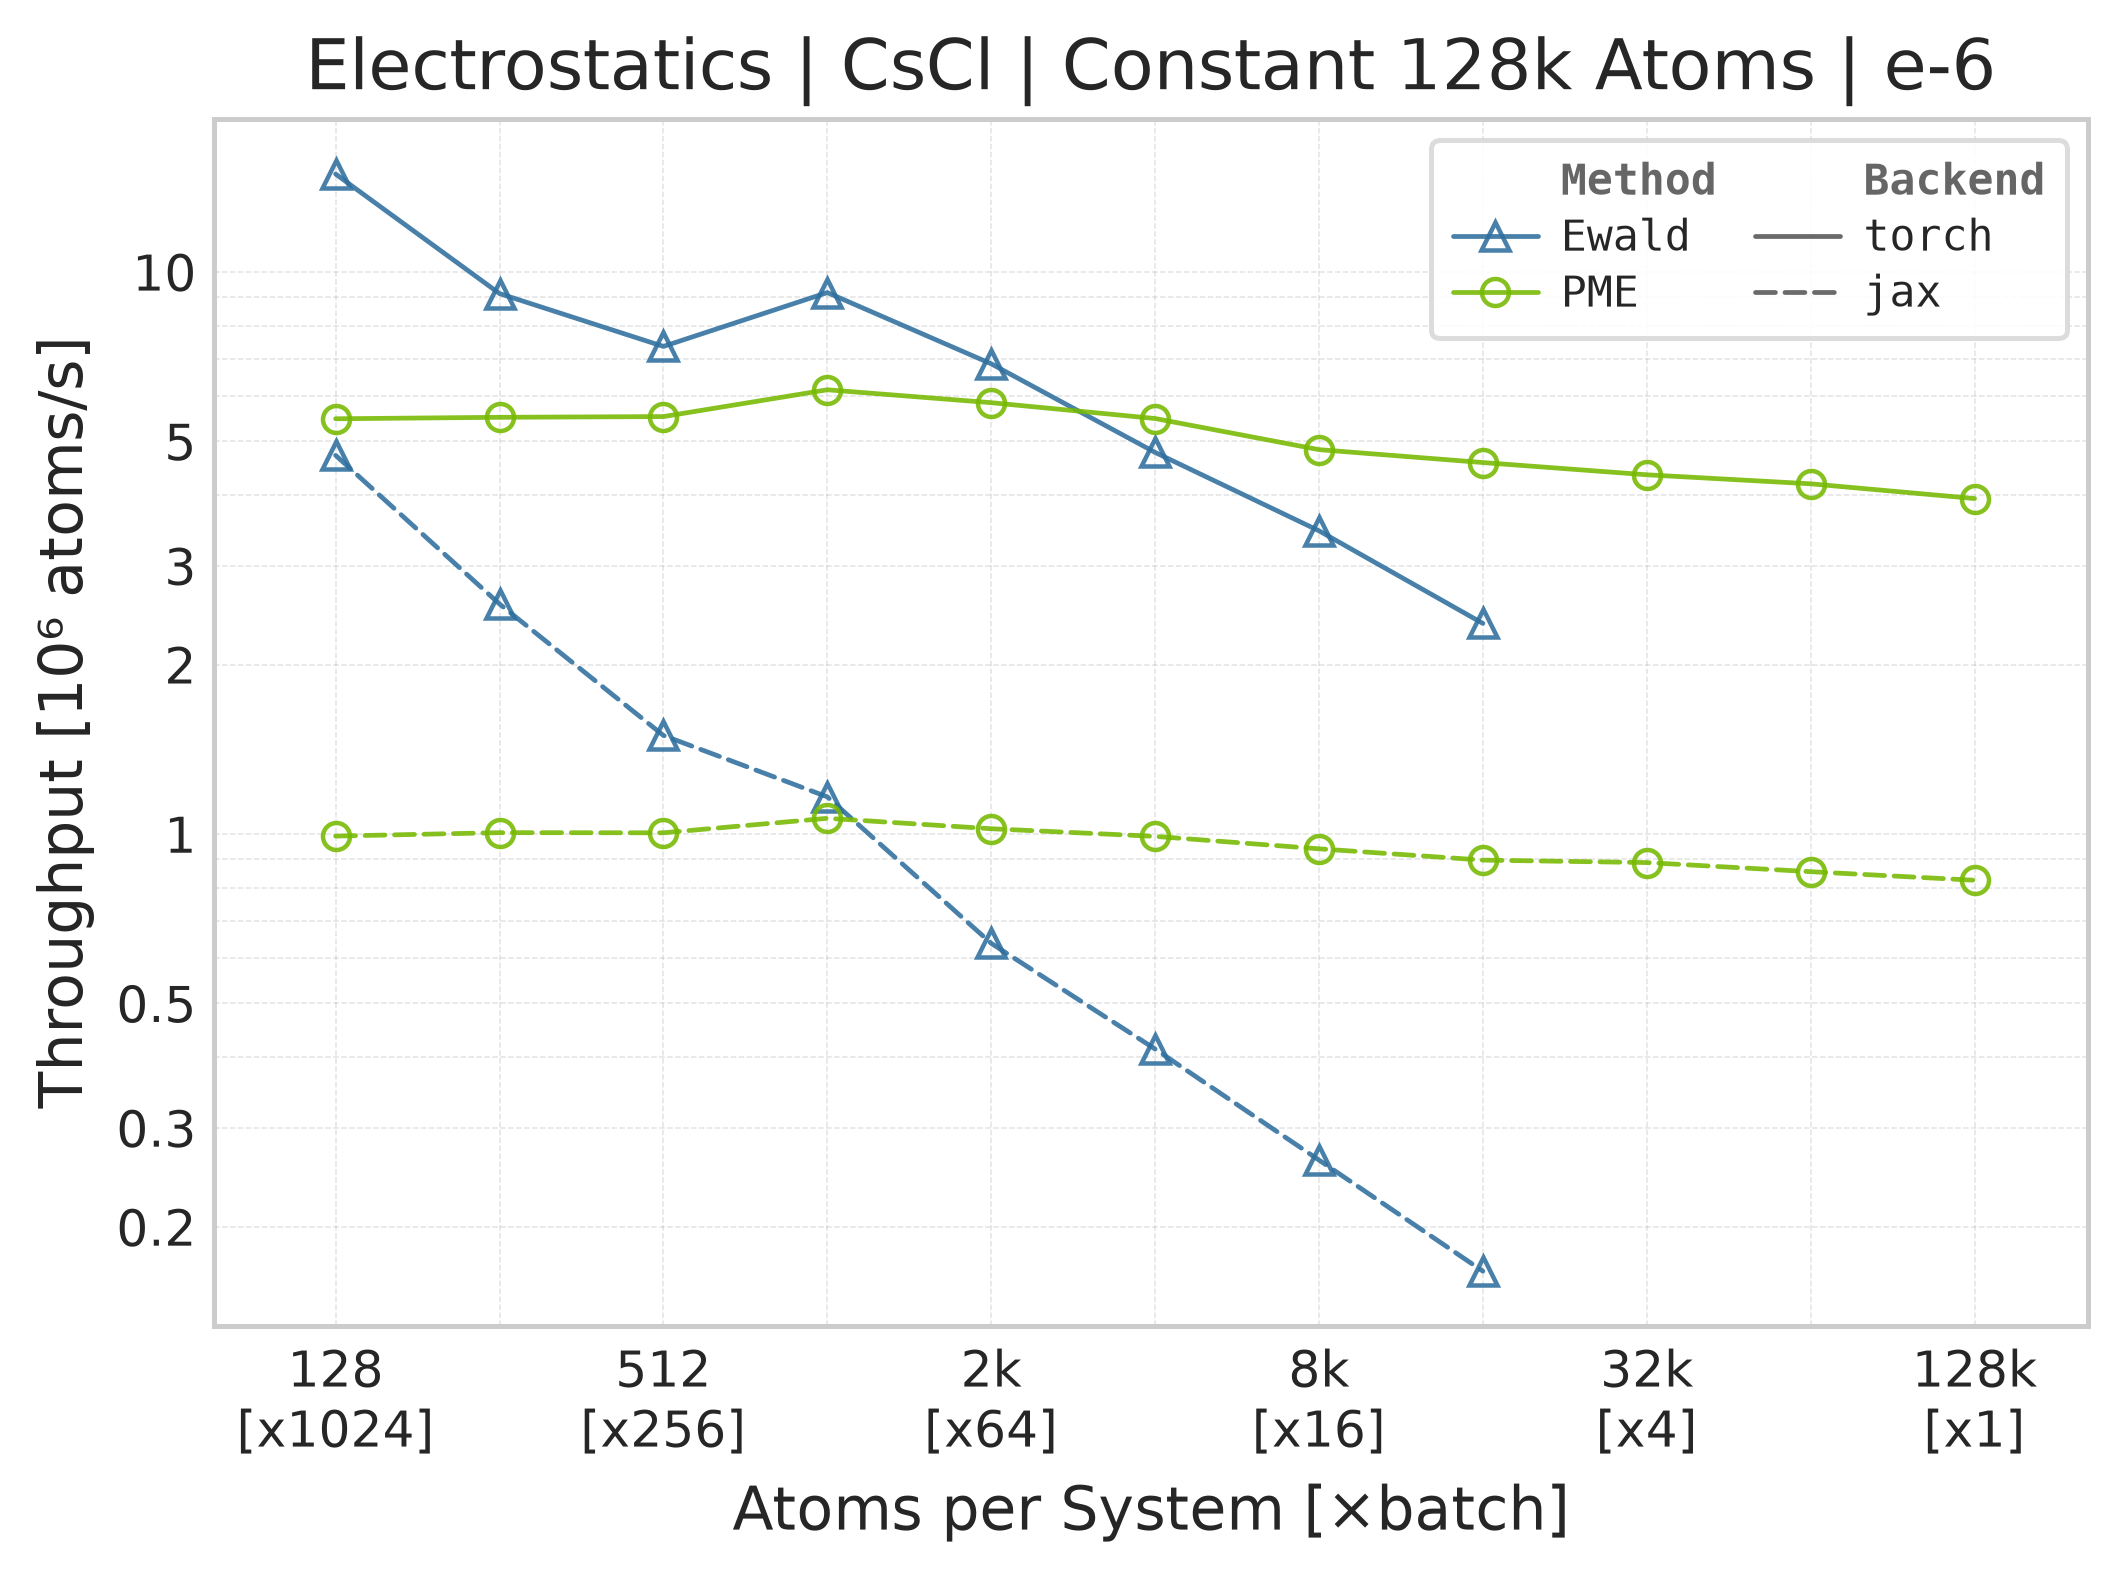
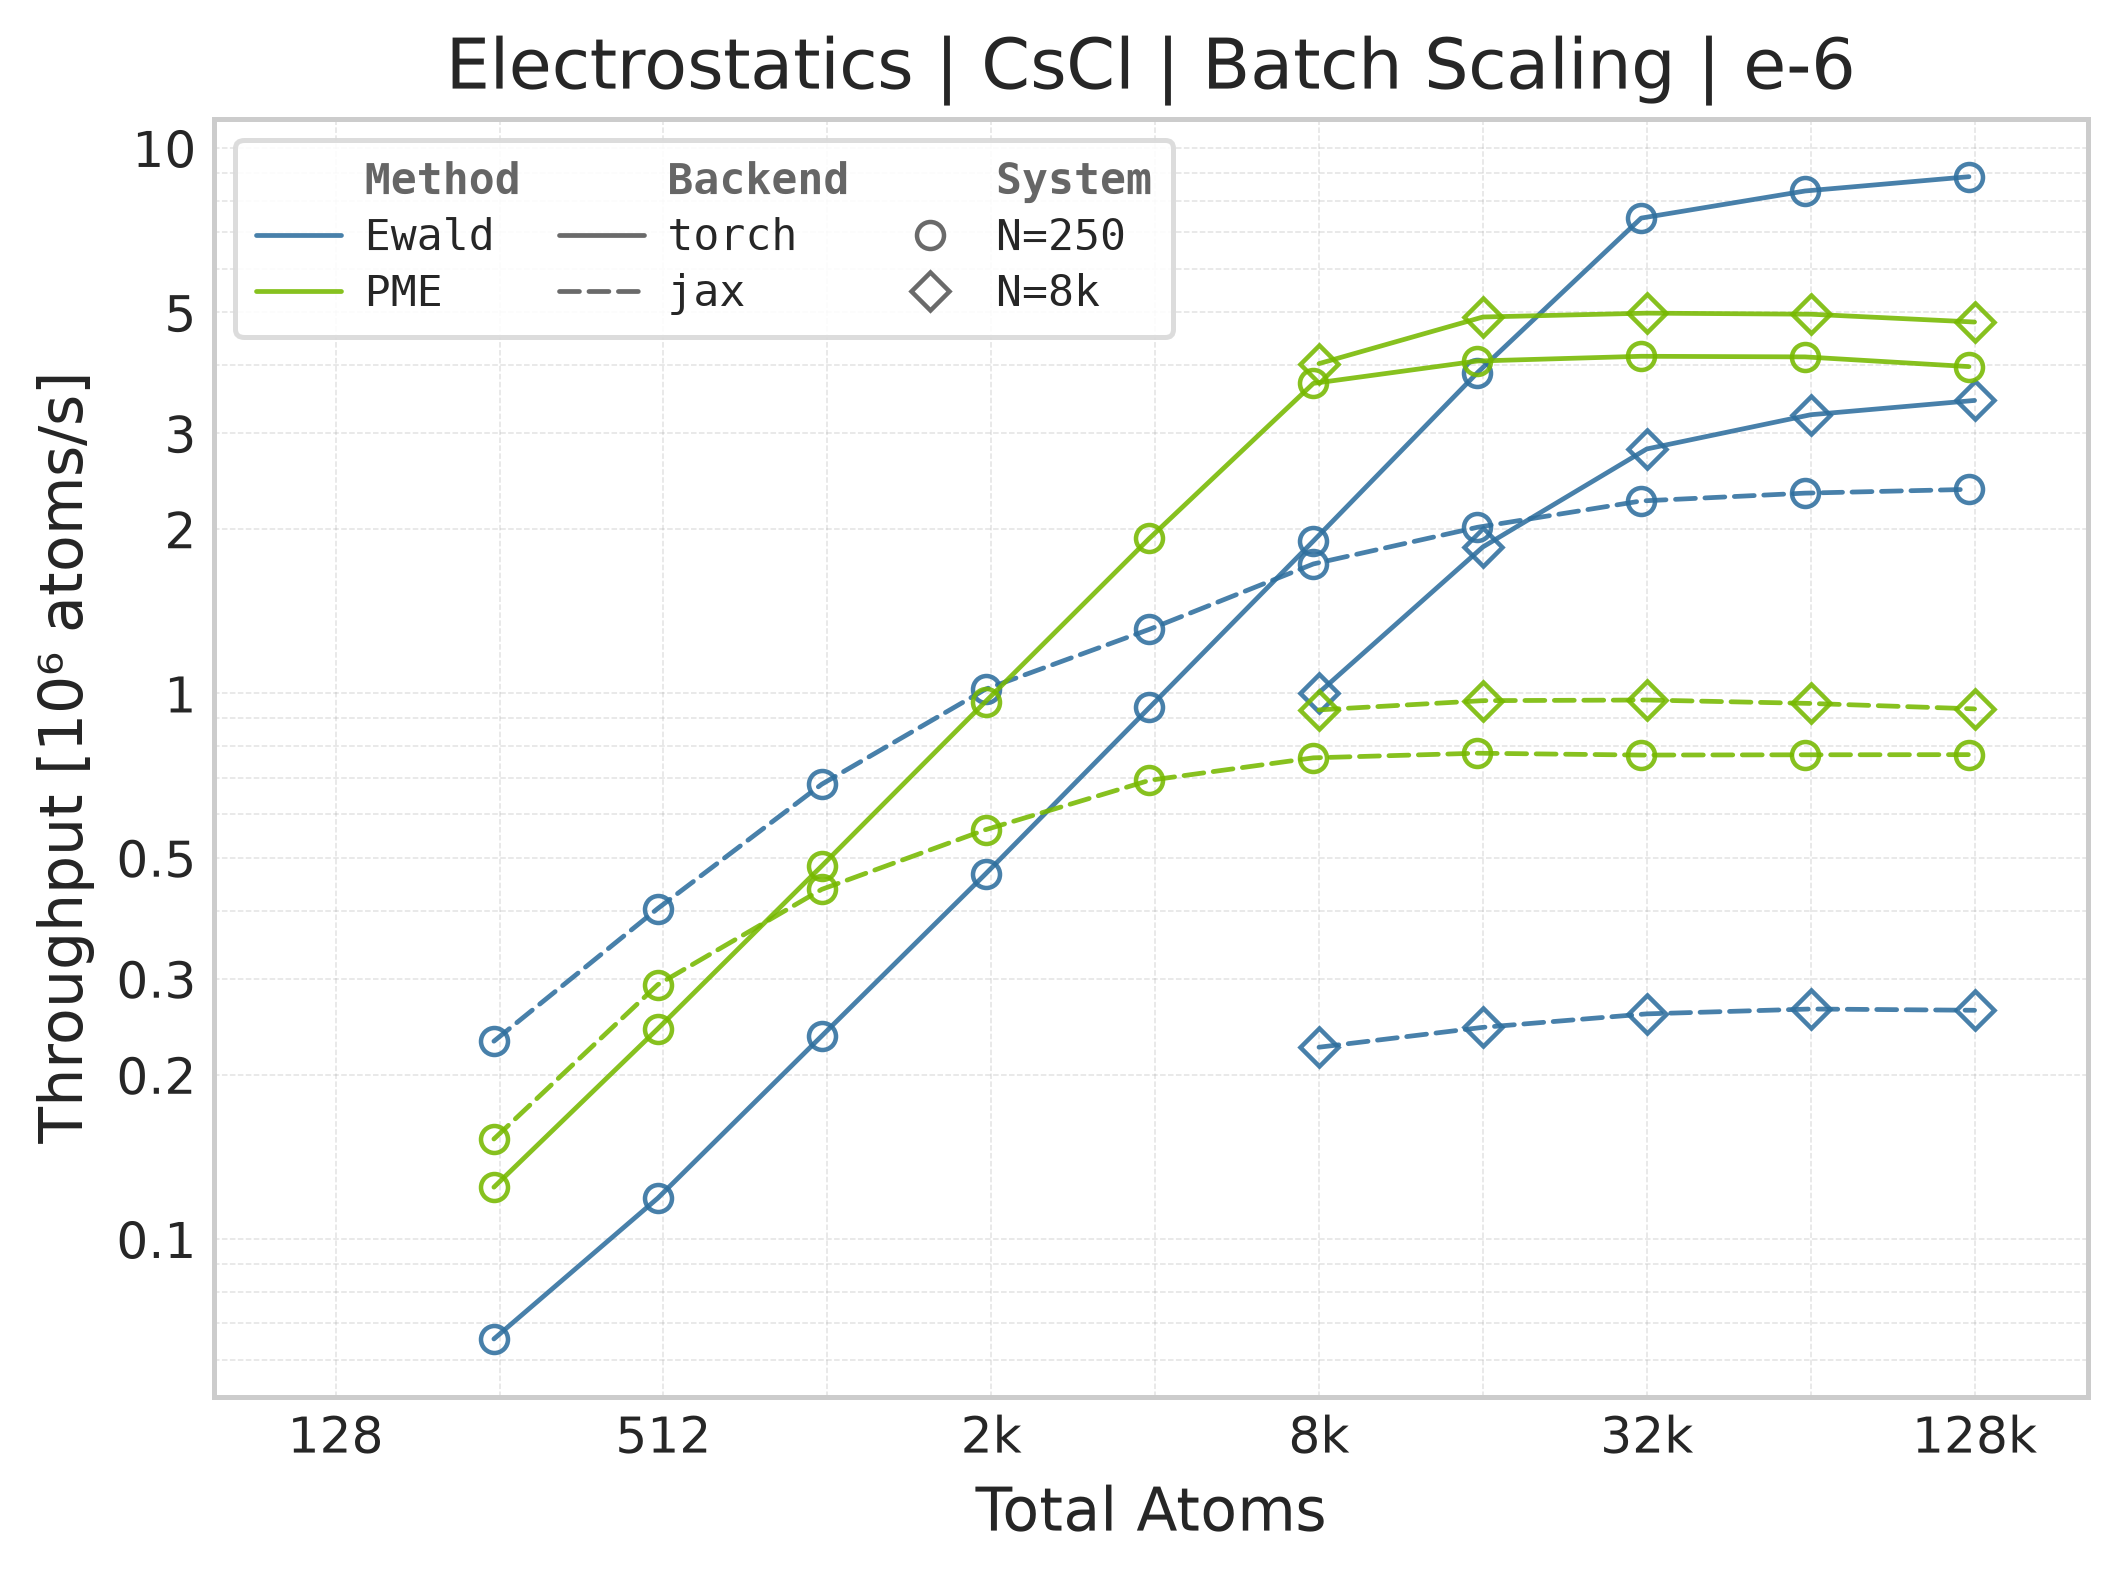
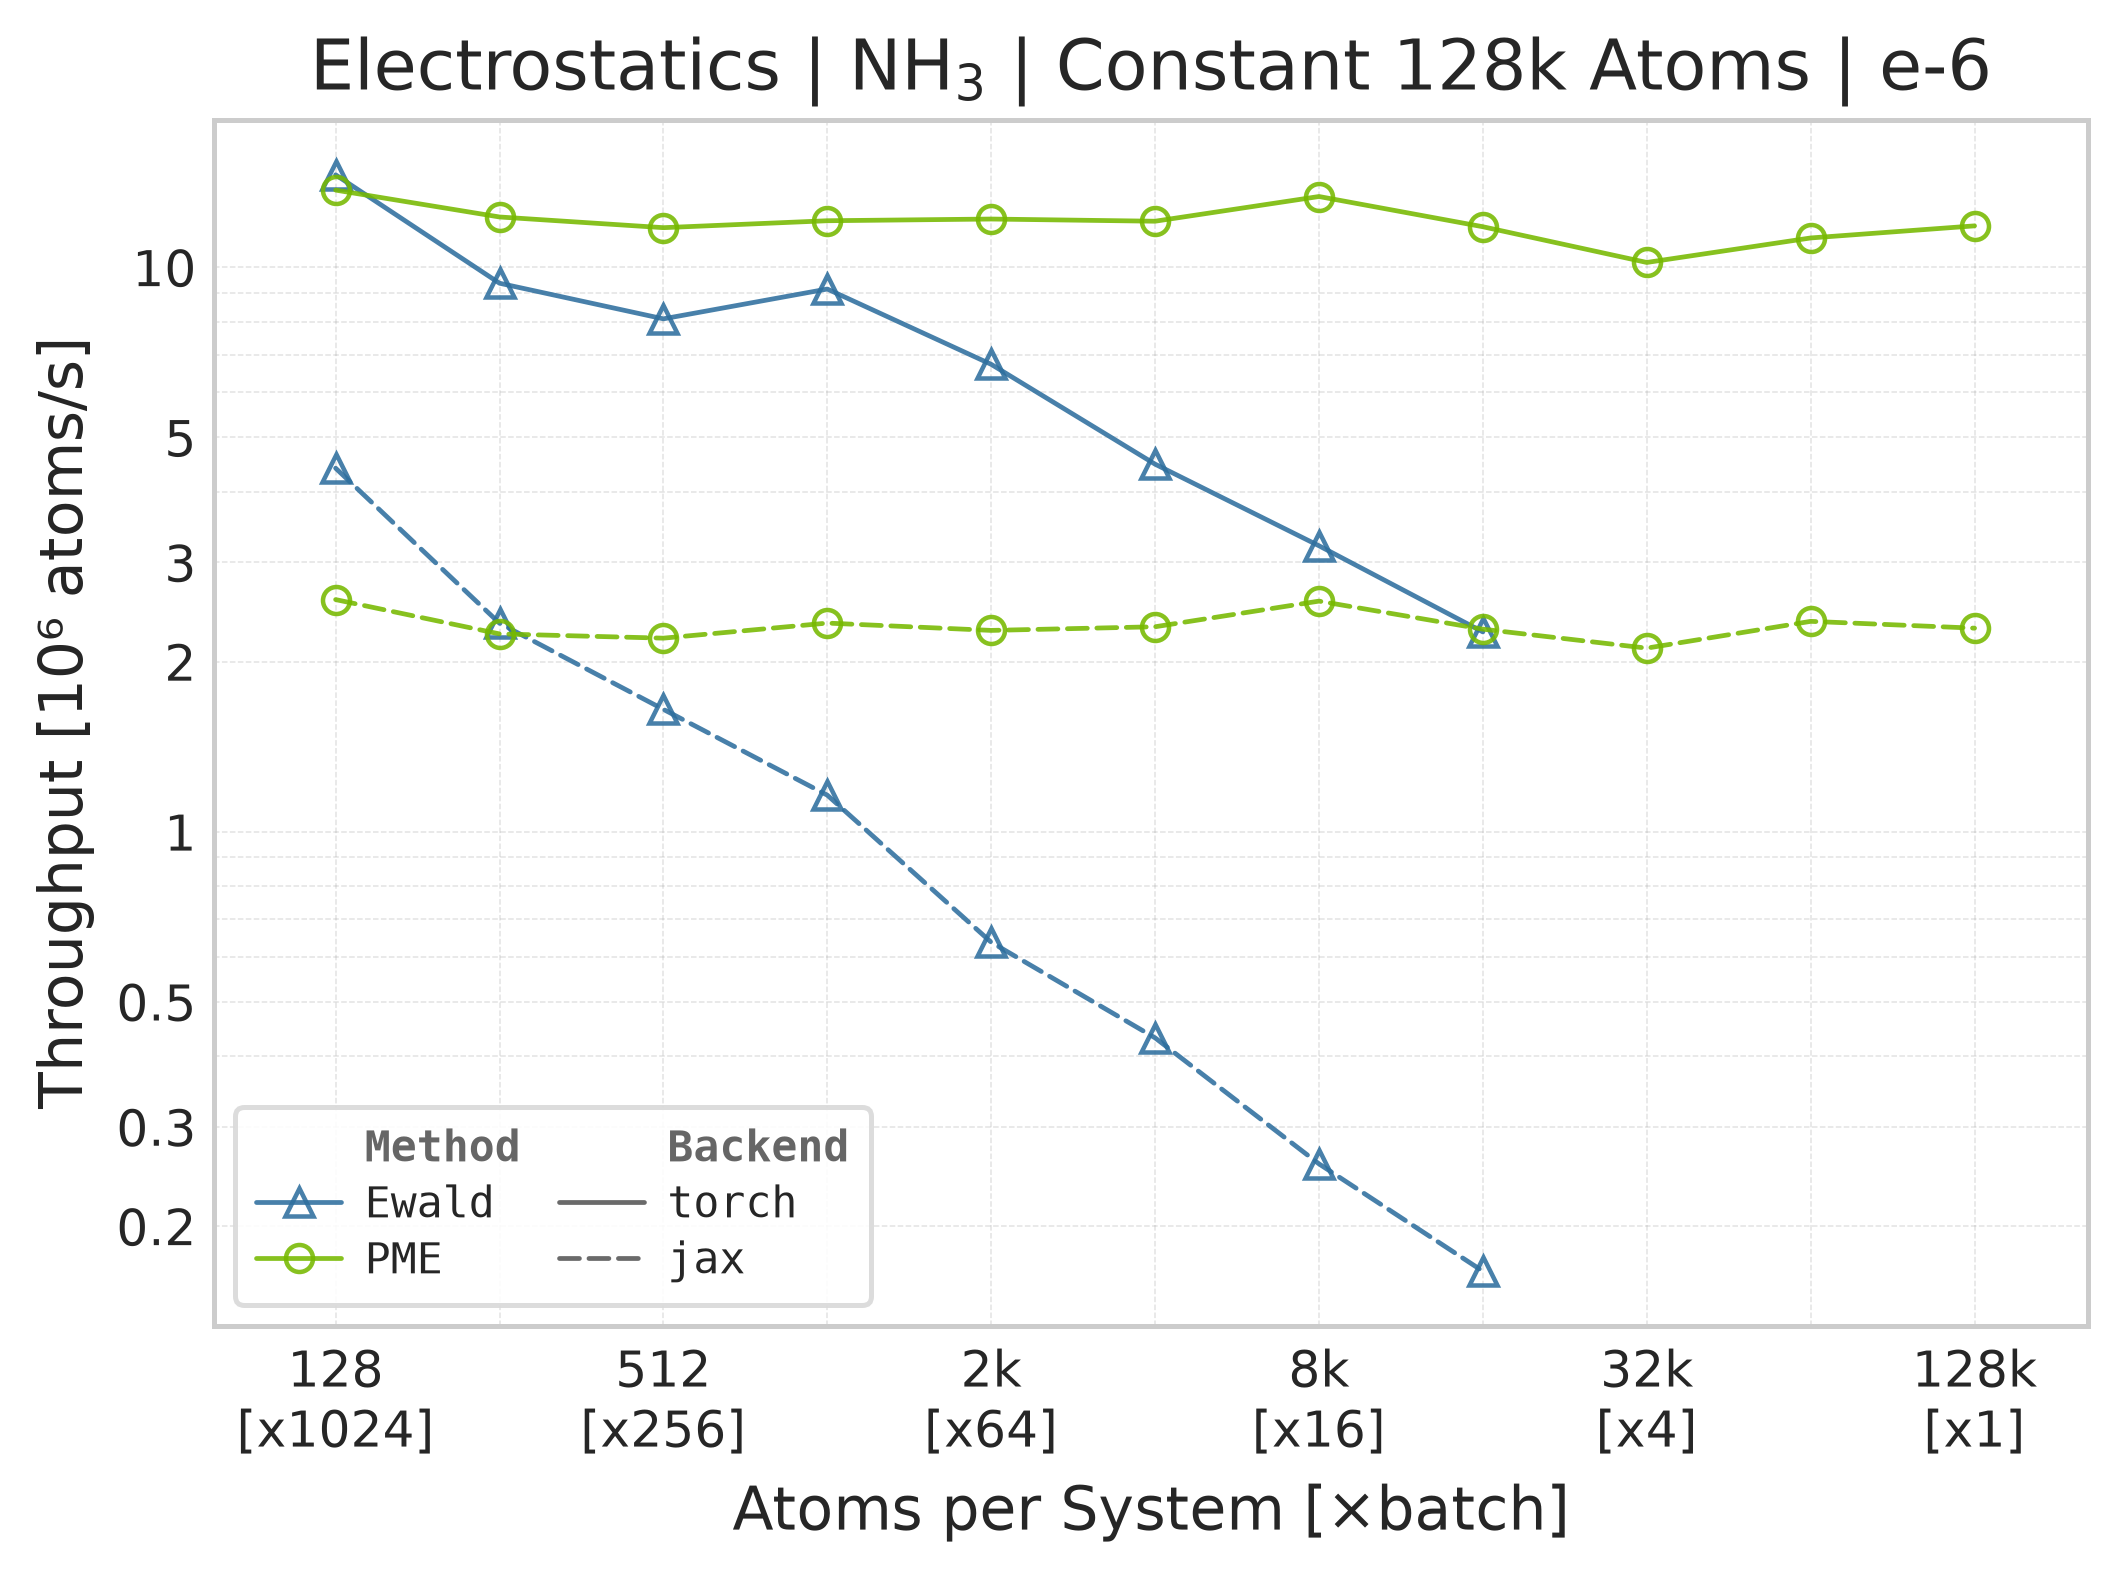
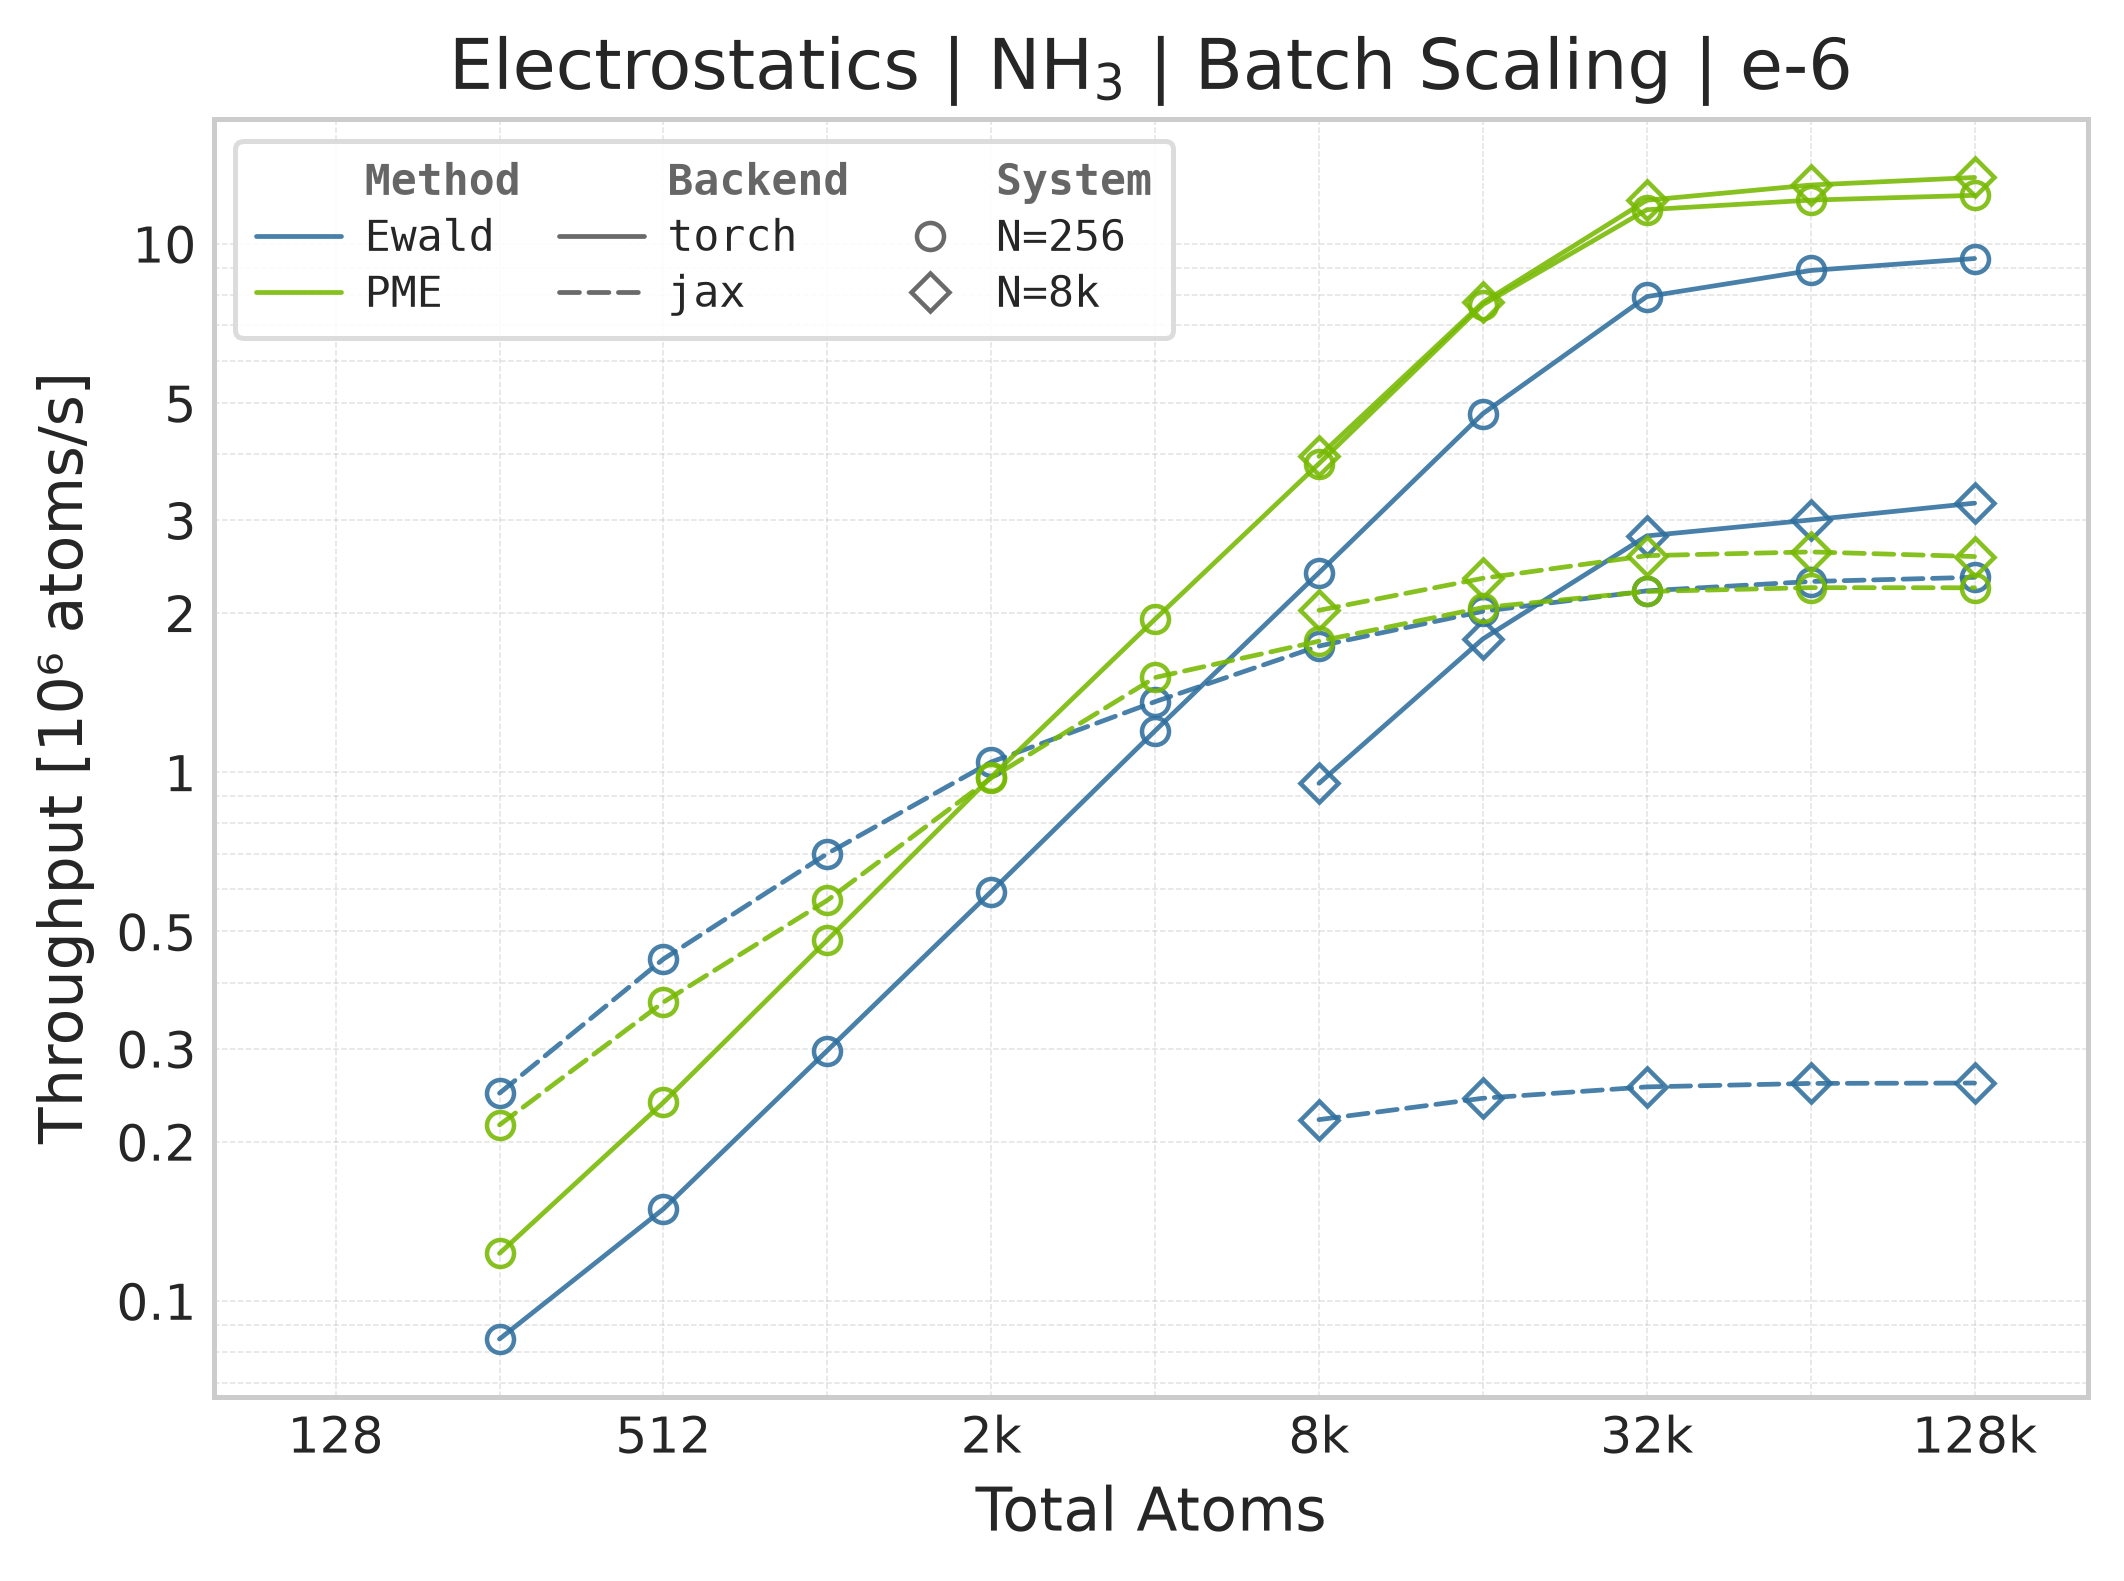
Throughput : Atoms processed per second (plotted as \(10^6\) atoms/s). Higher is better. This indicates the scaling point where the GPU saturates.
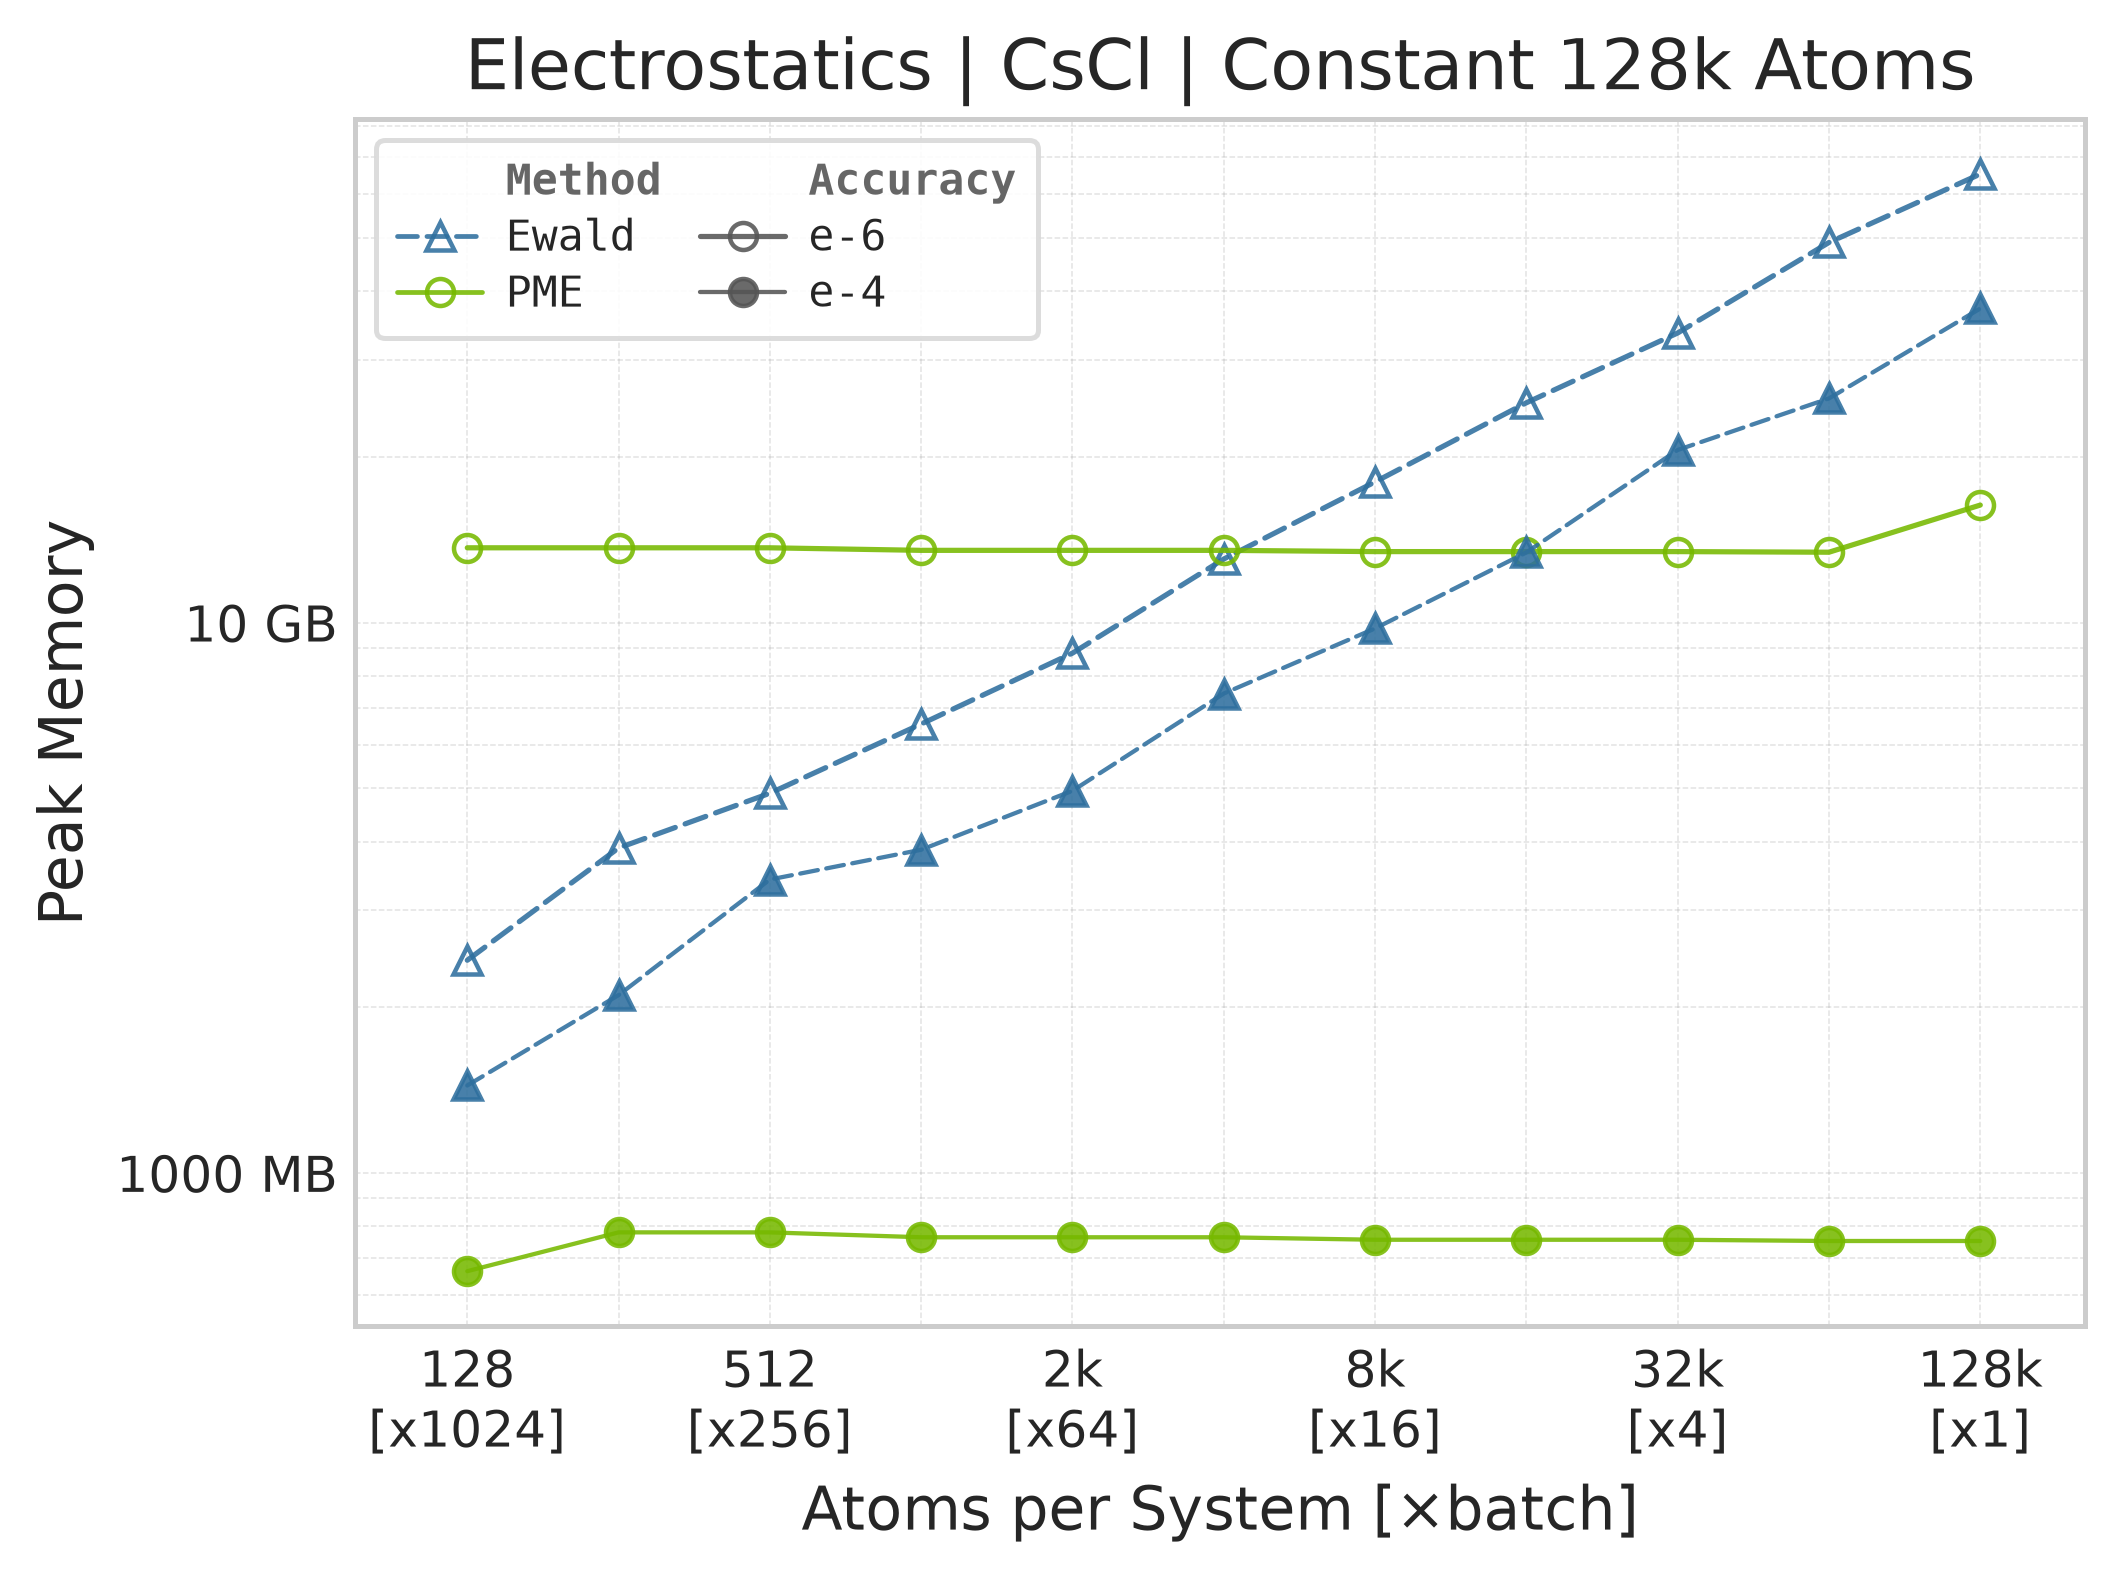
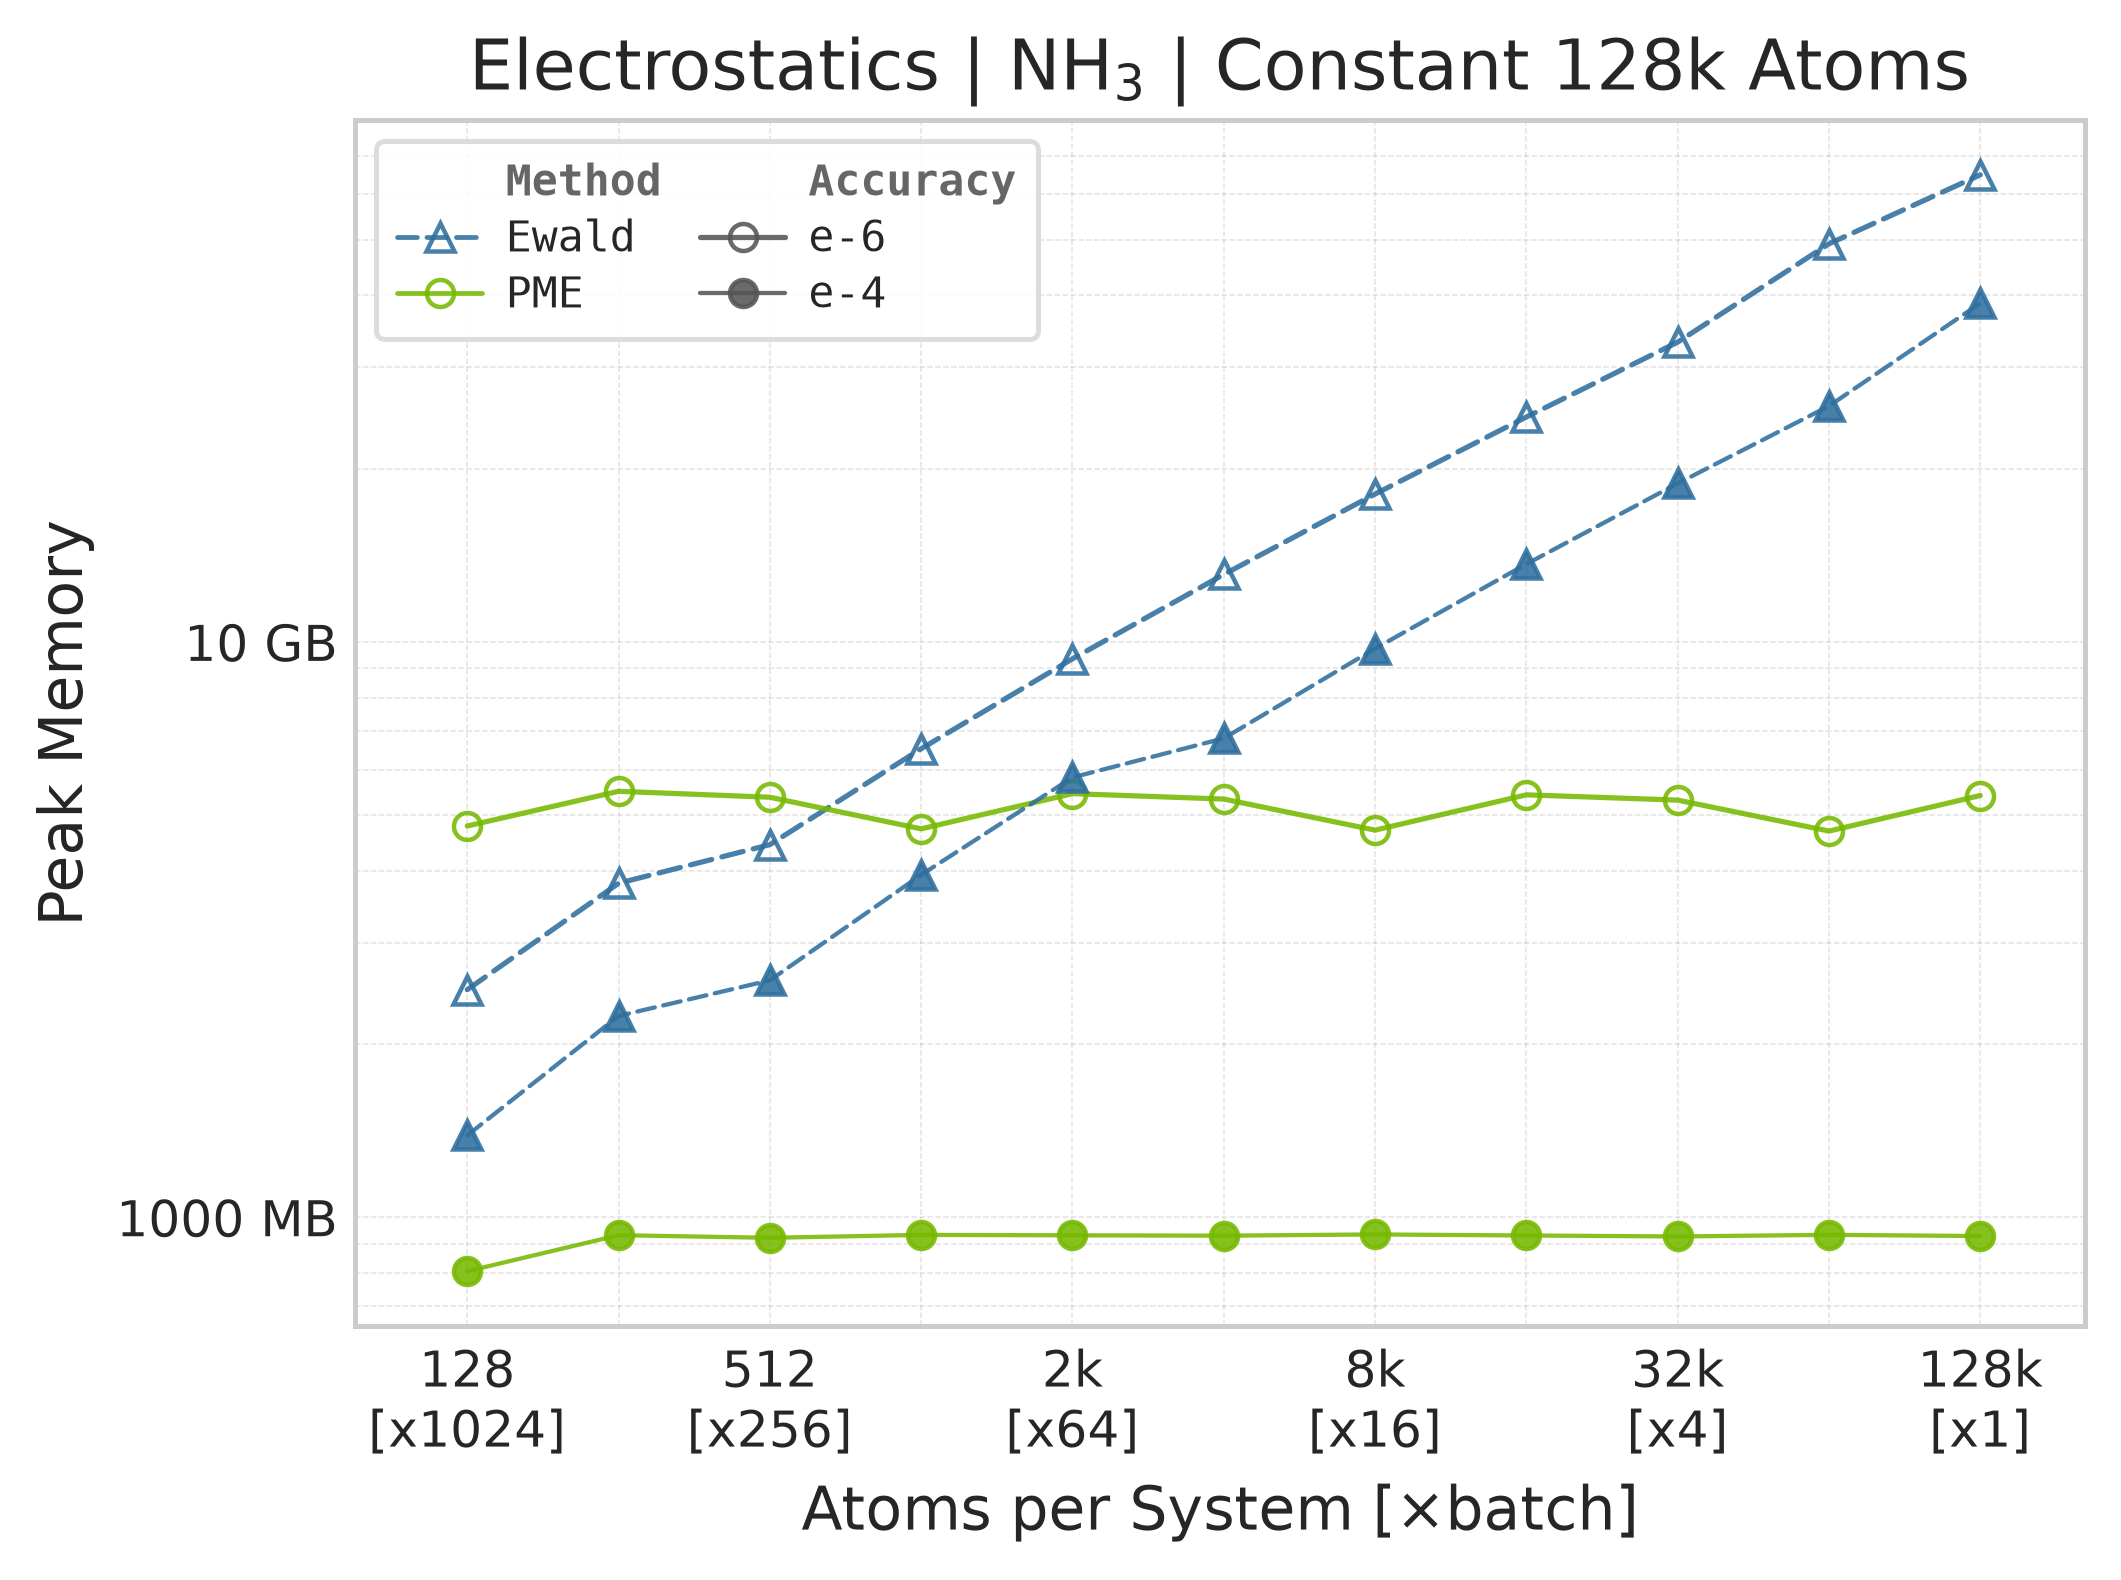
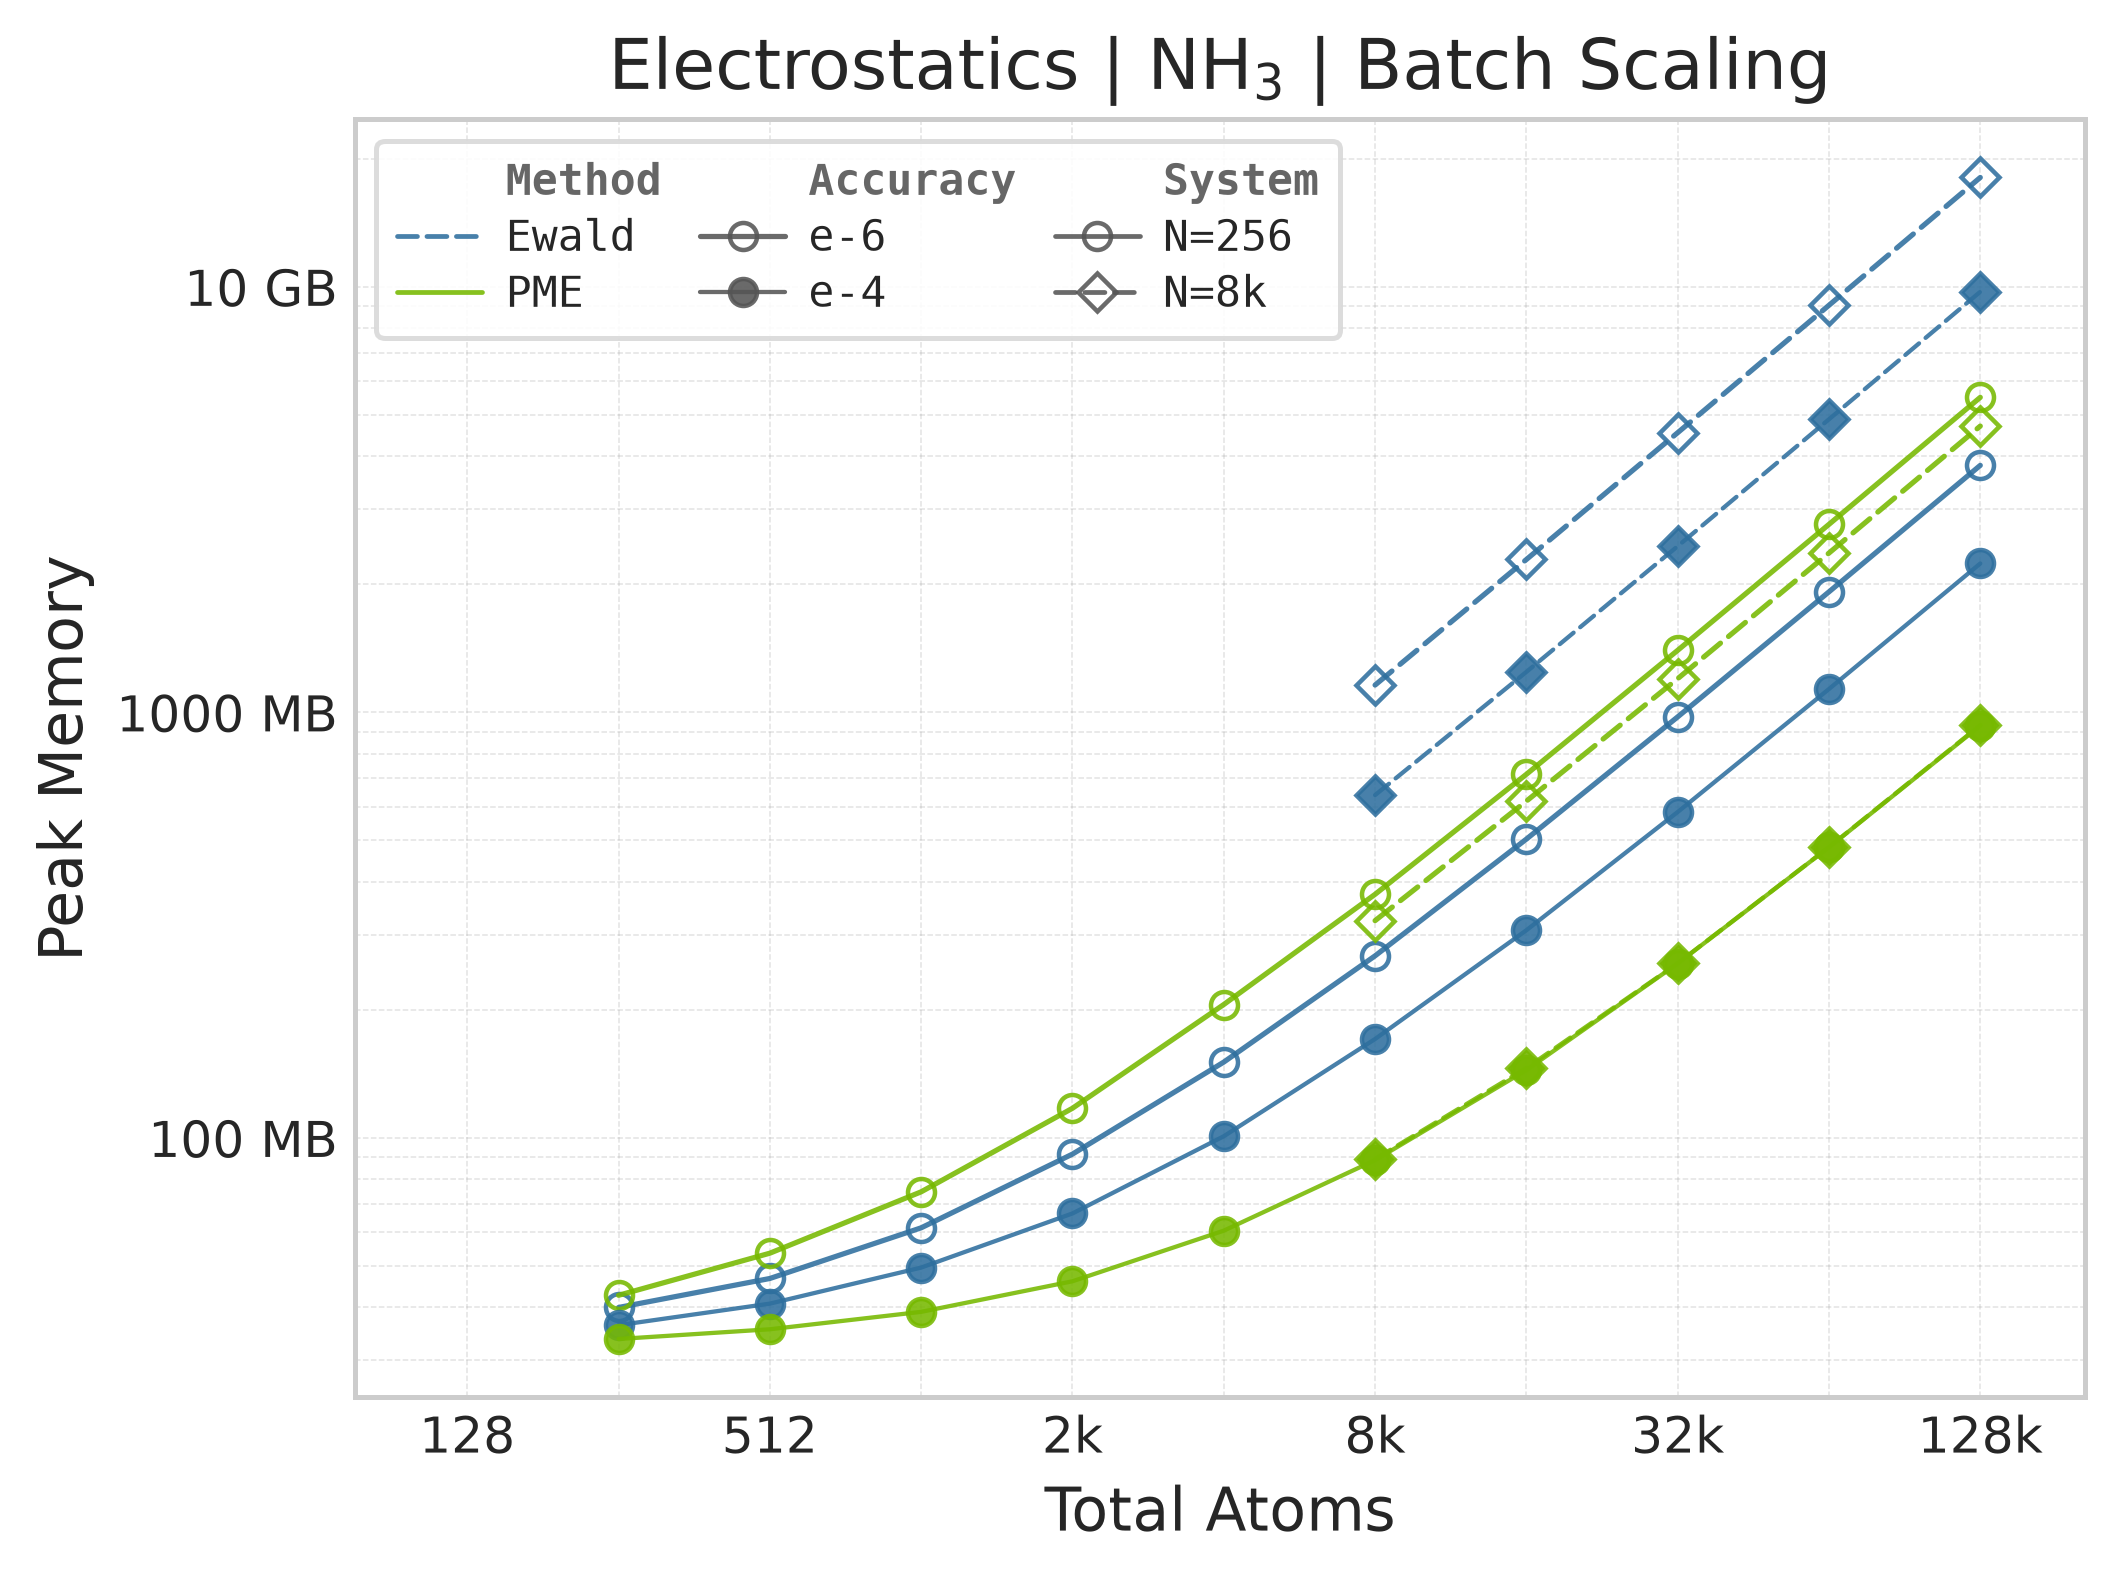
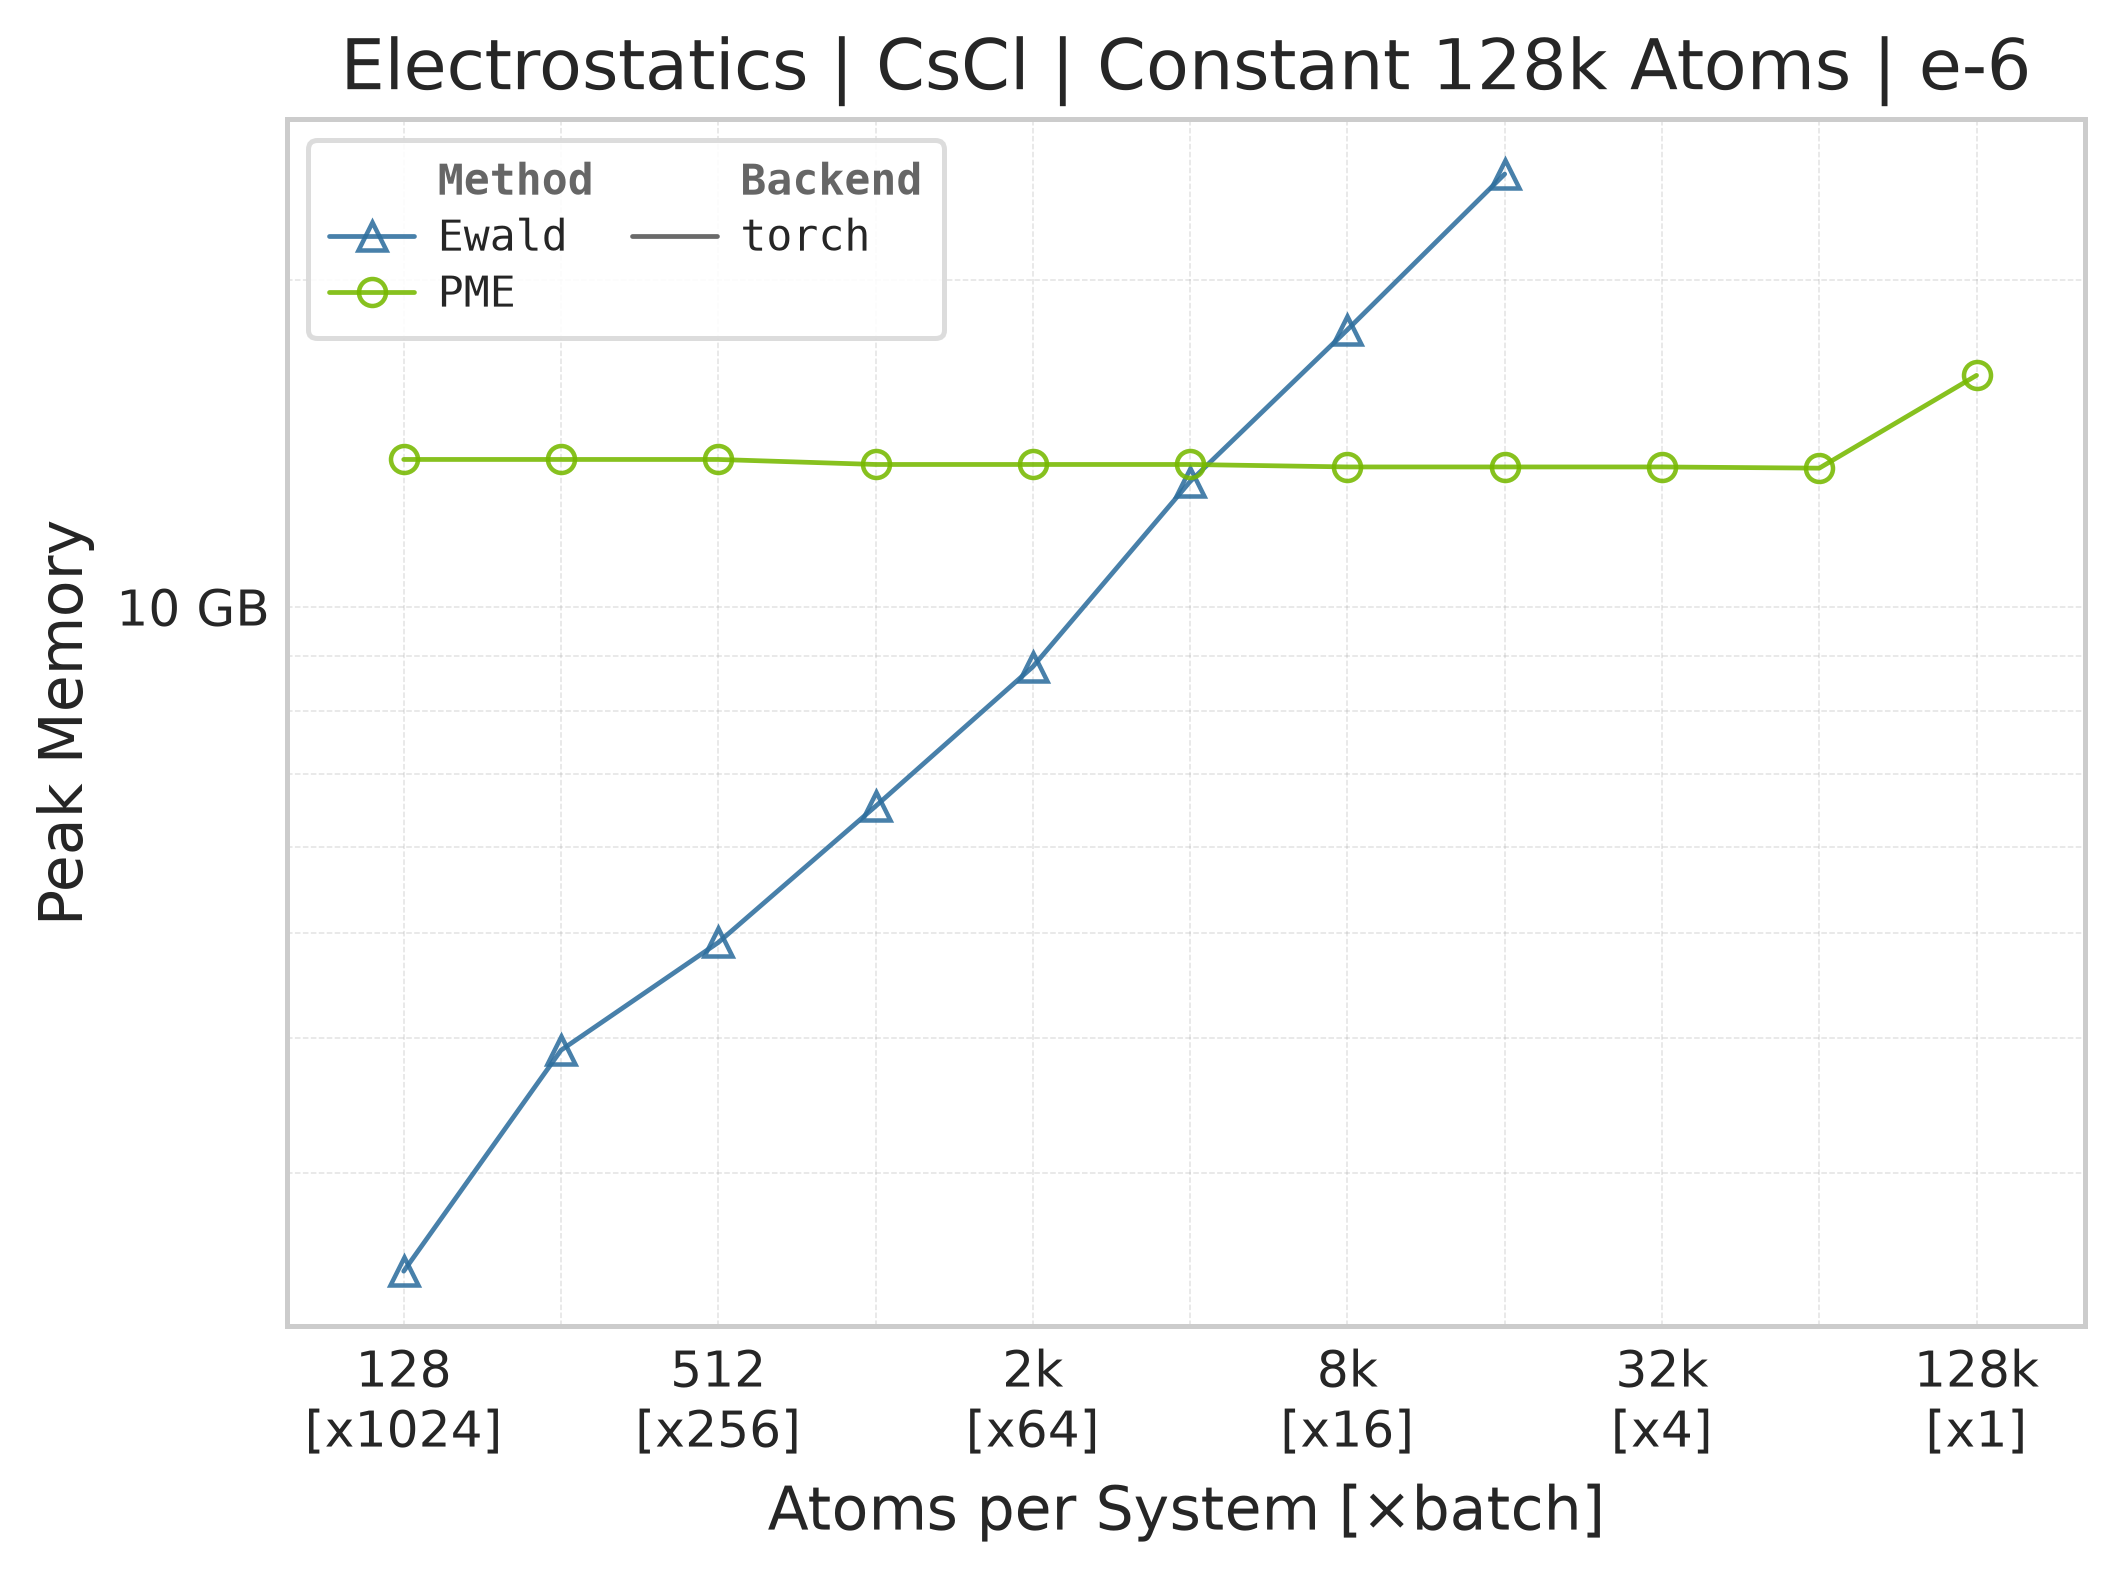
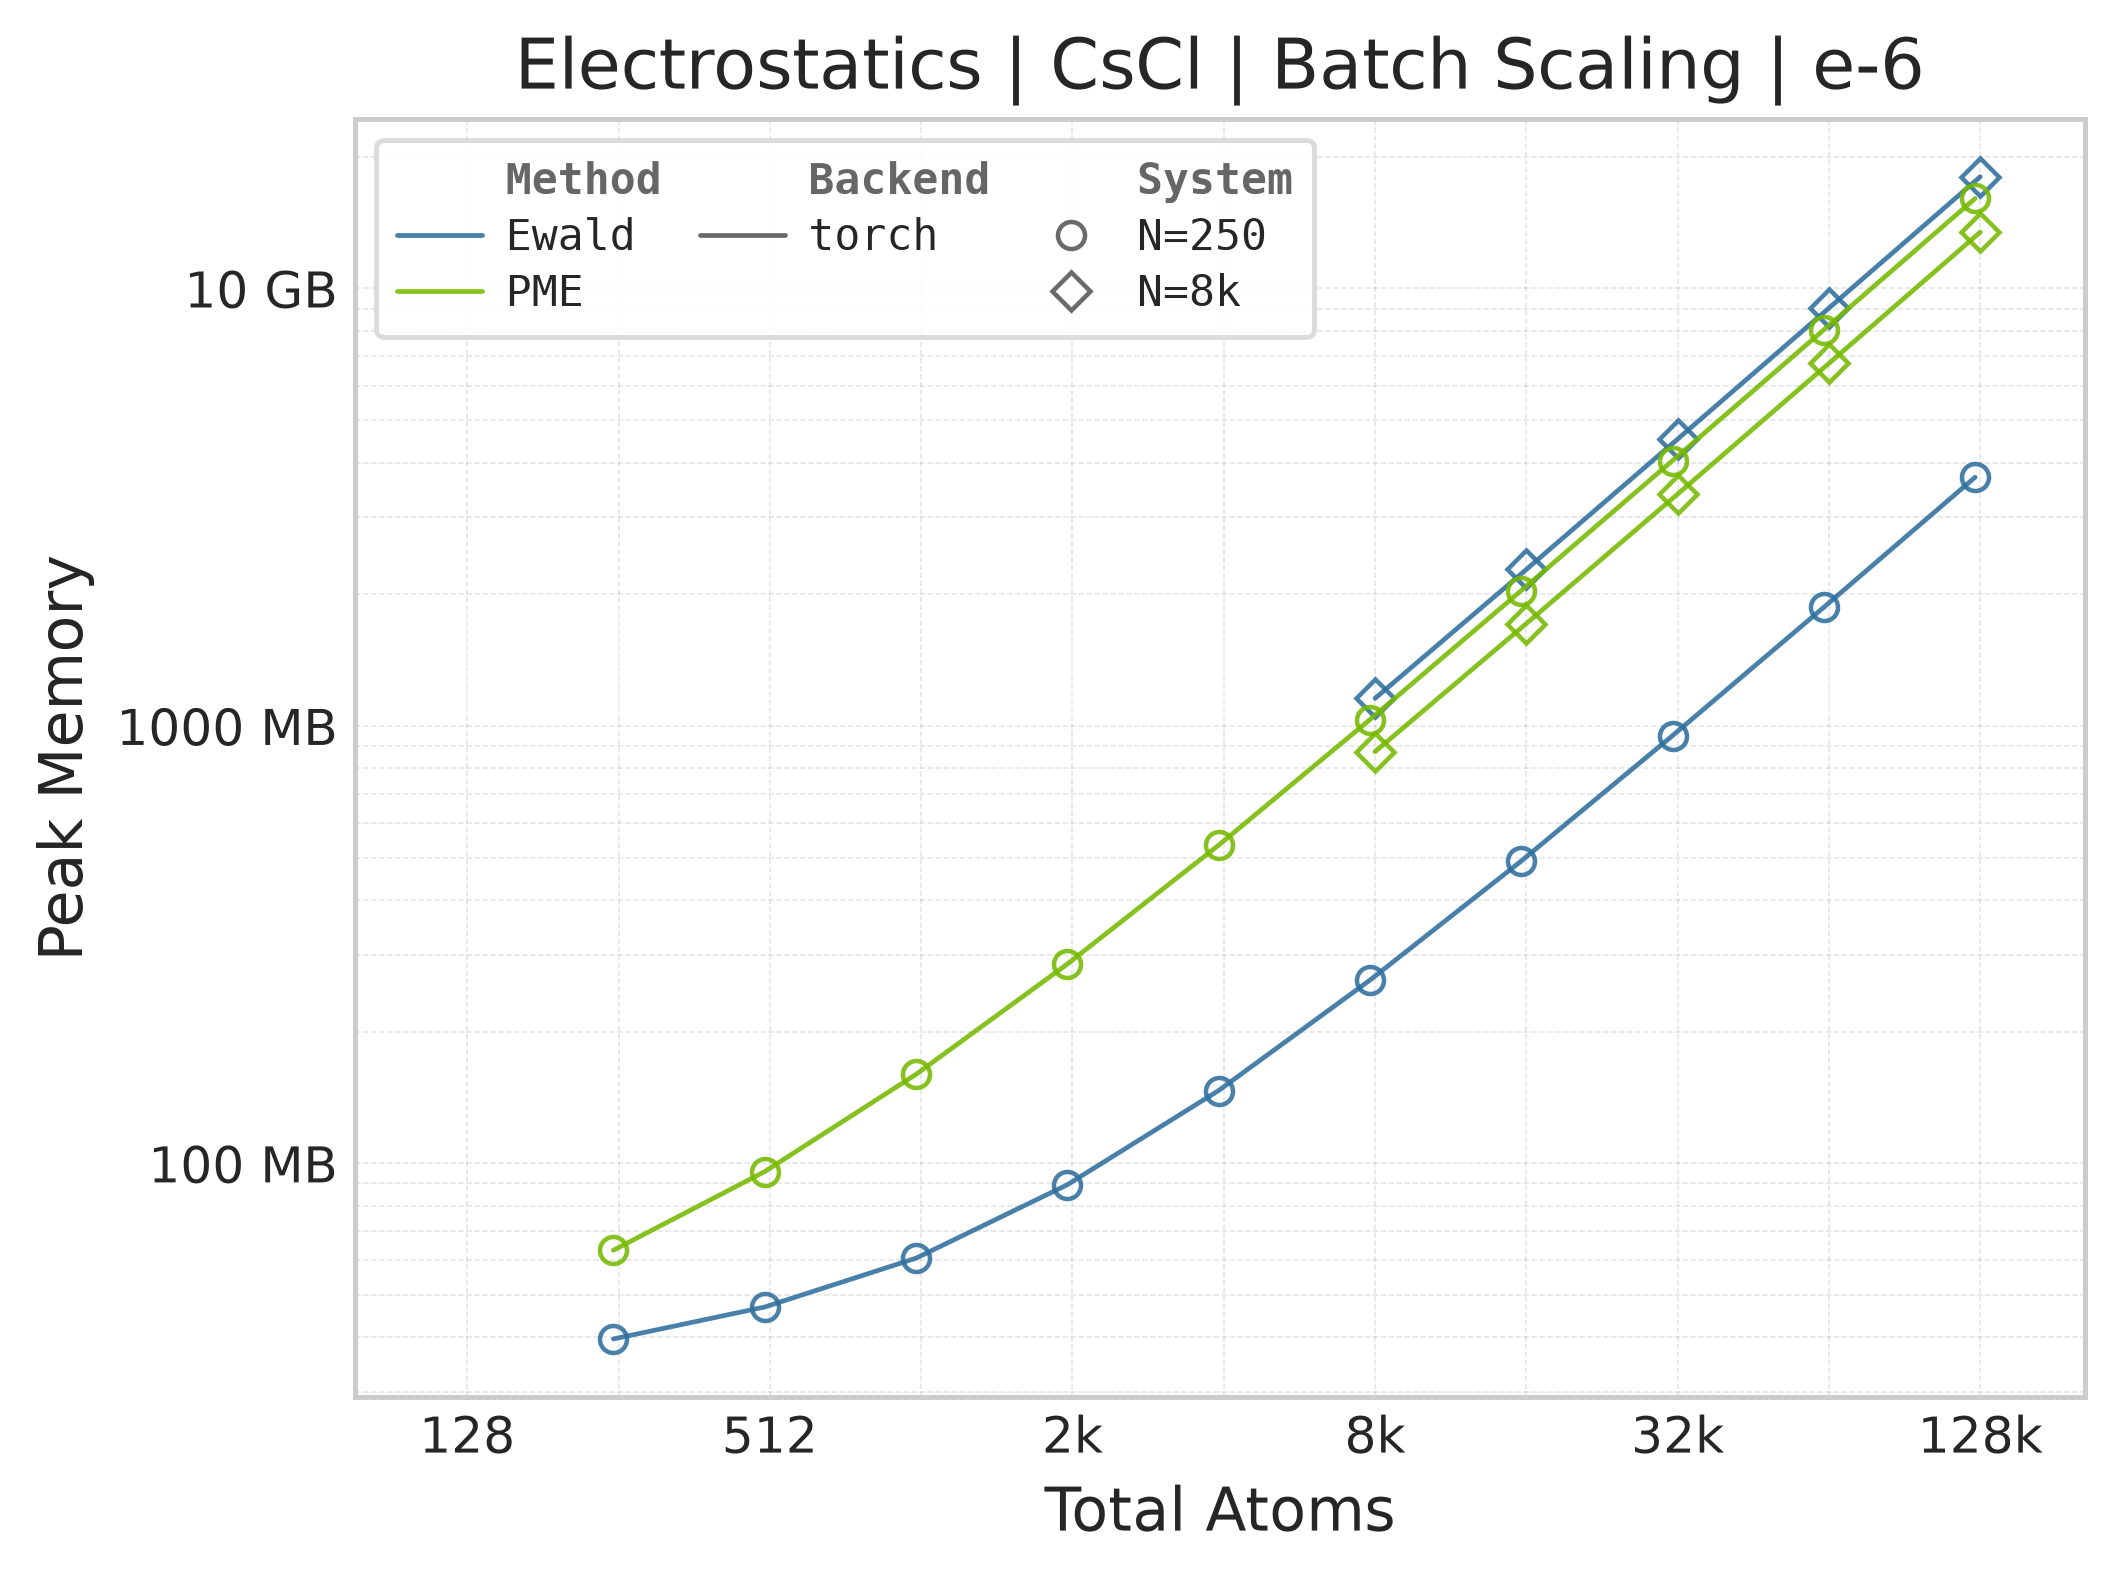
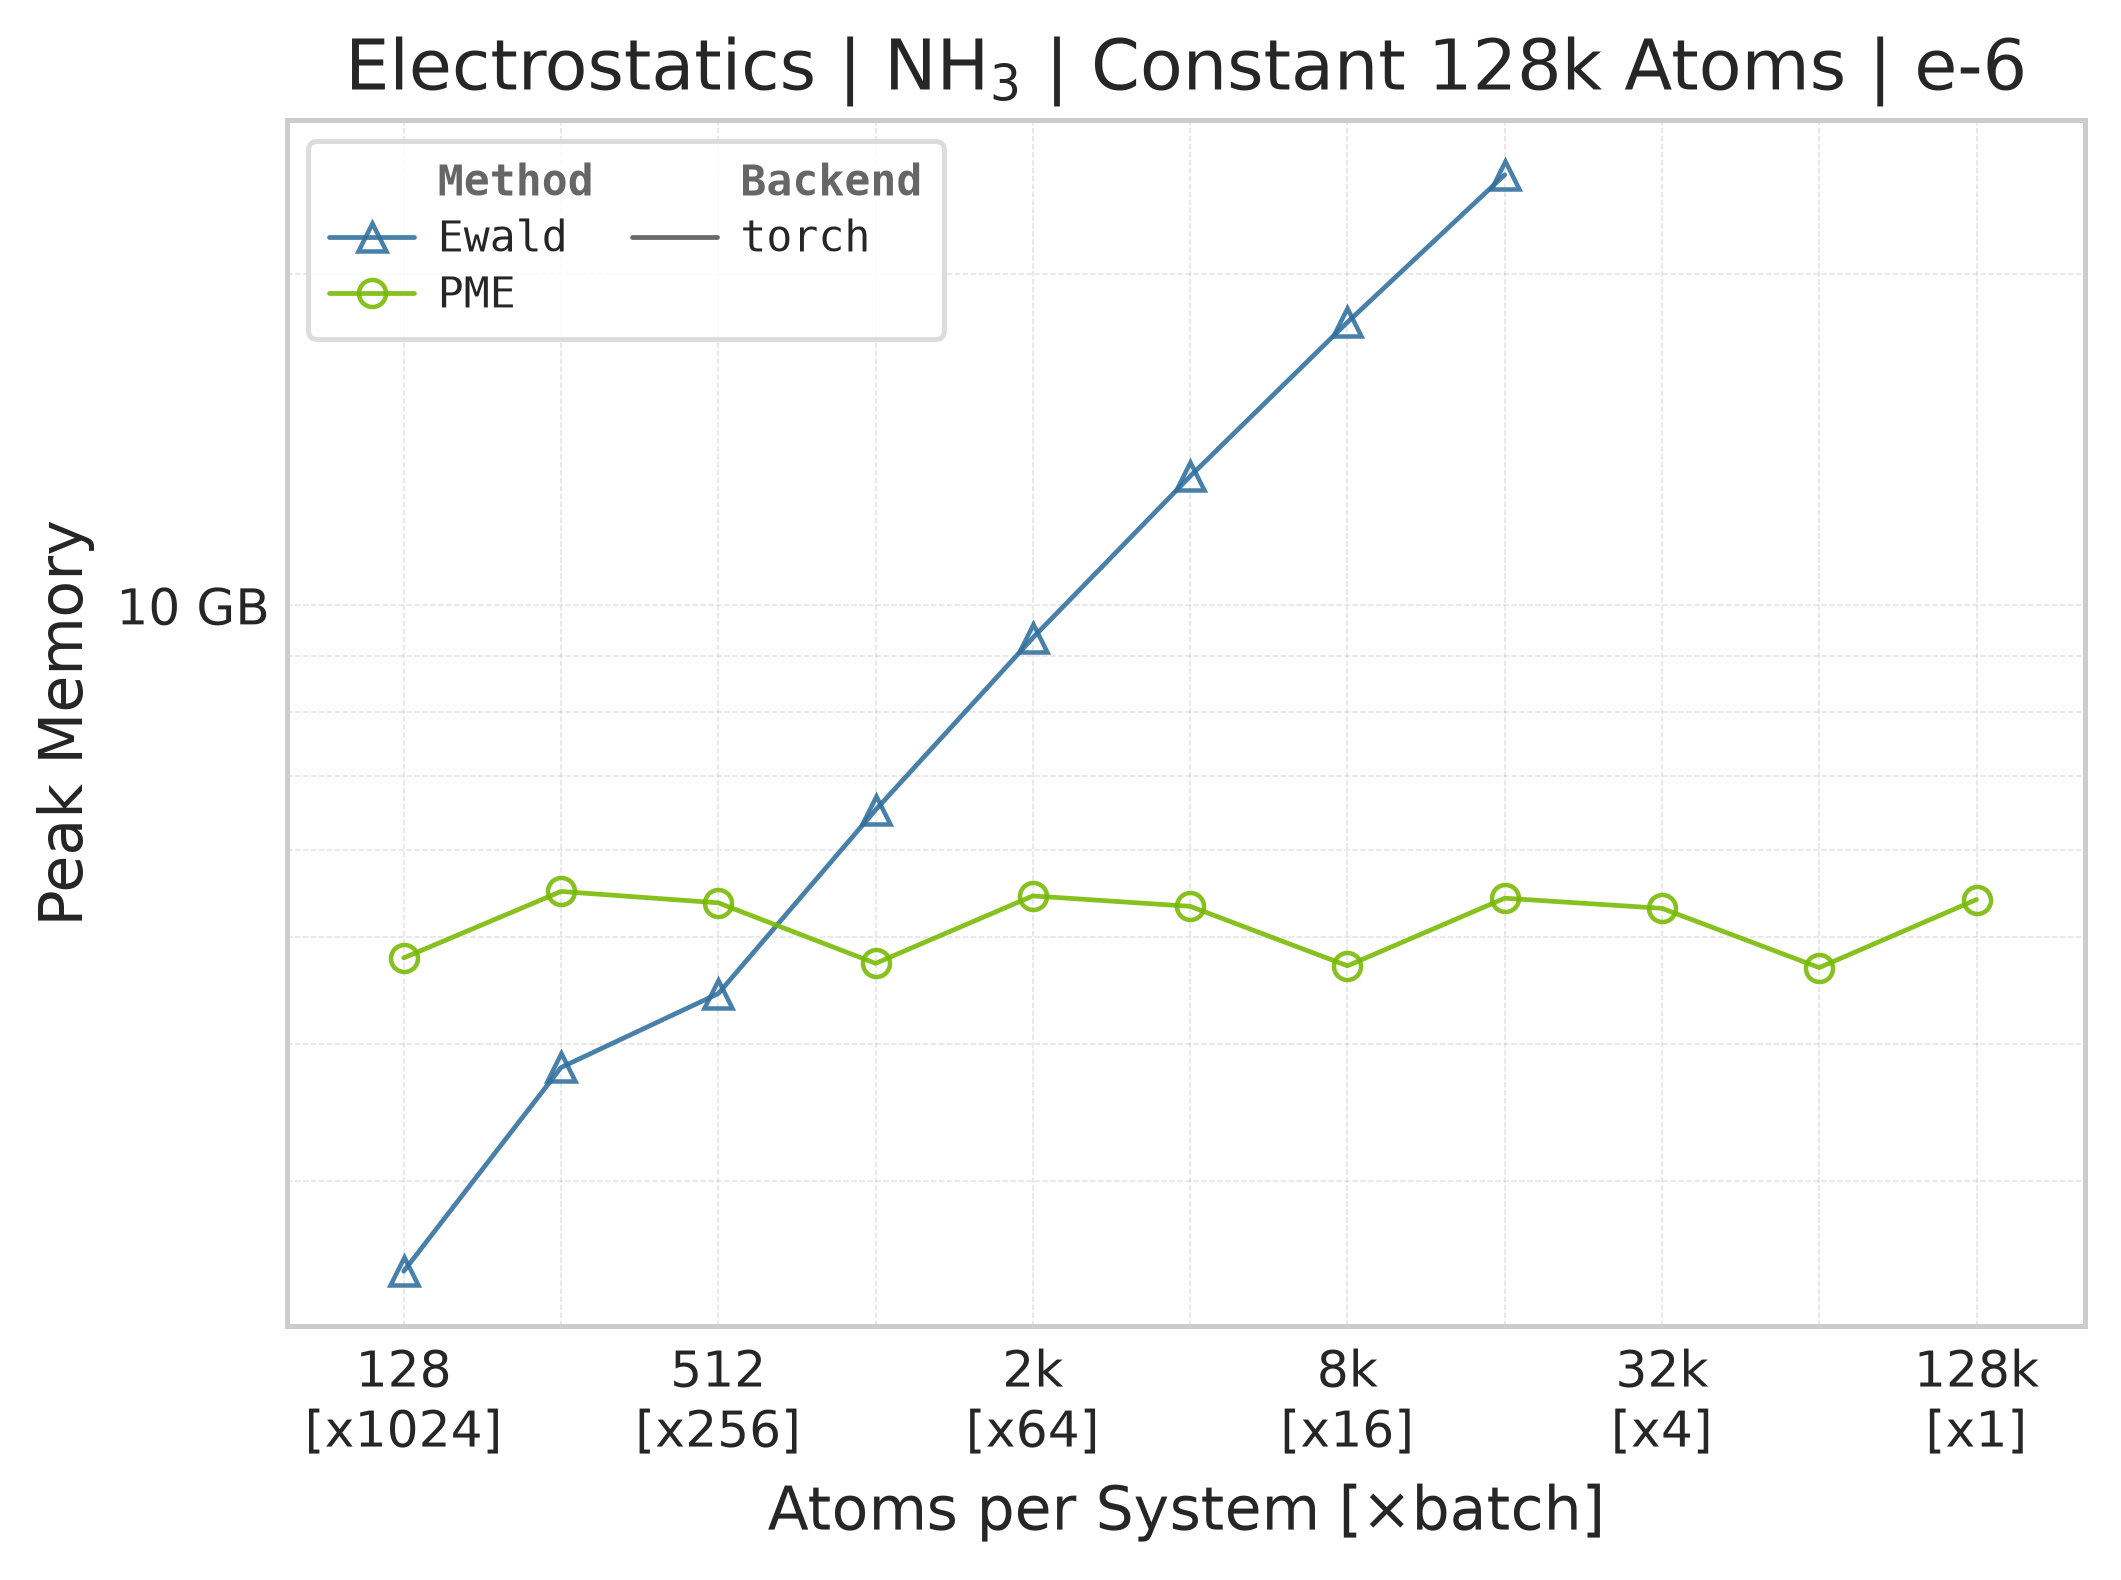
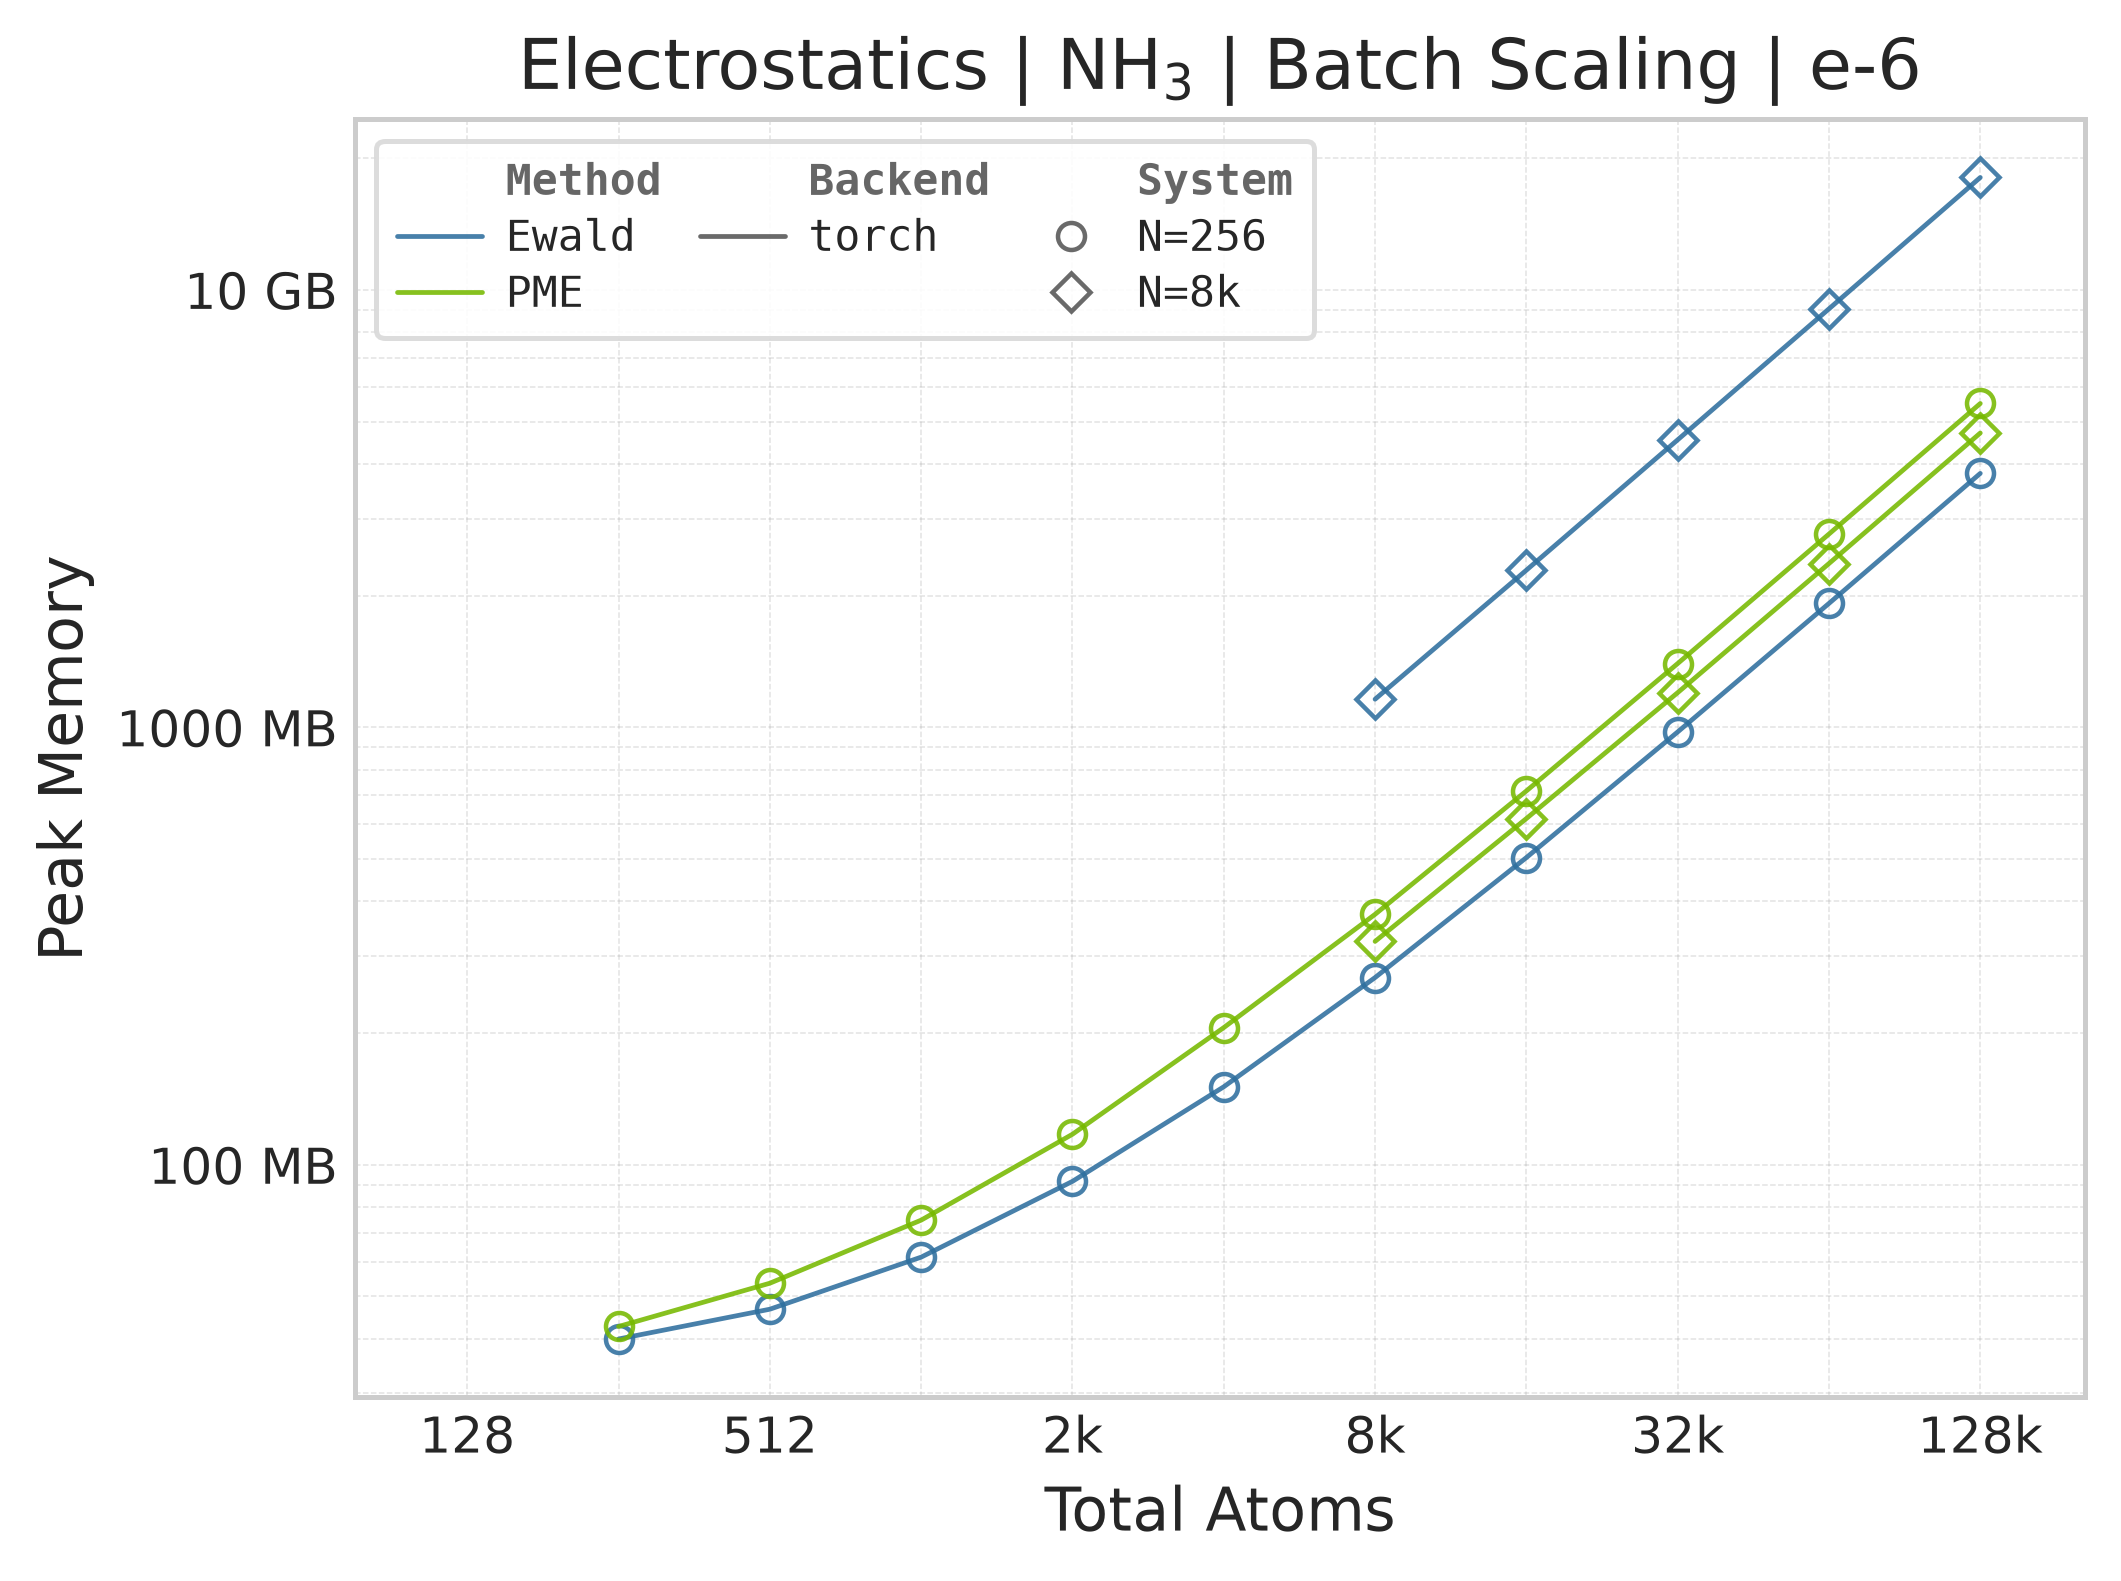
Memory : Peak memory reported by the Torch CUDA allocator vs. system size. Units switch between MB and GB automatically on the y-axis. JAX memory is not measured by this suite.
Performance Results#
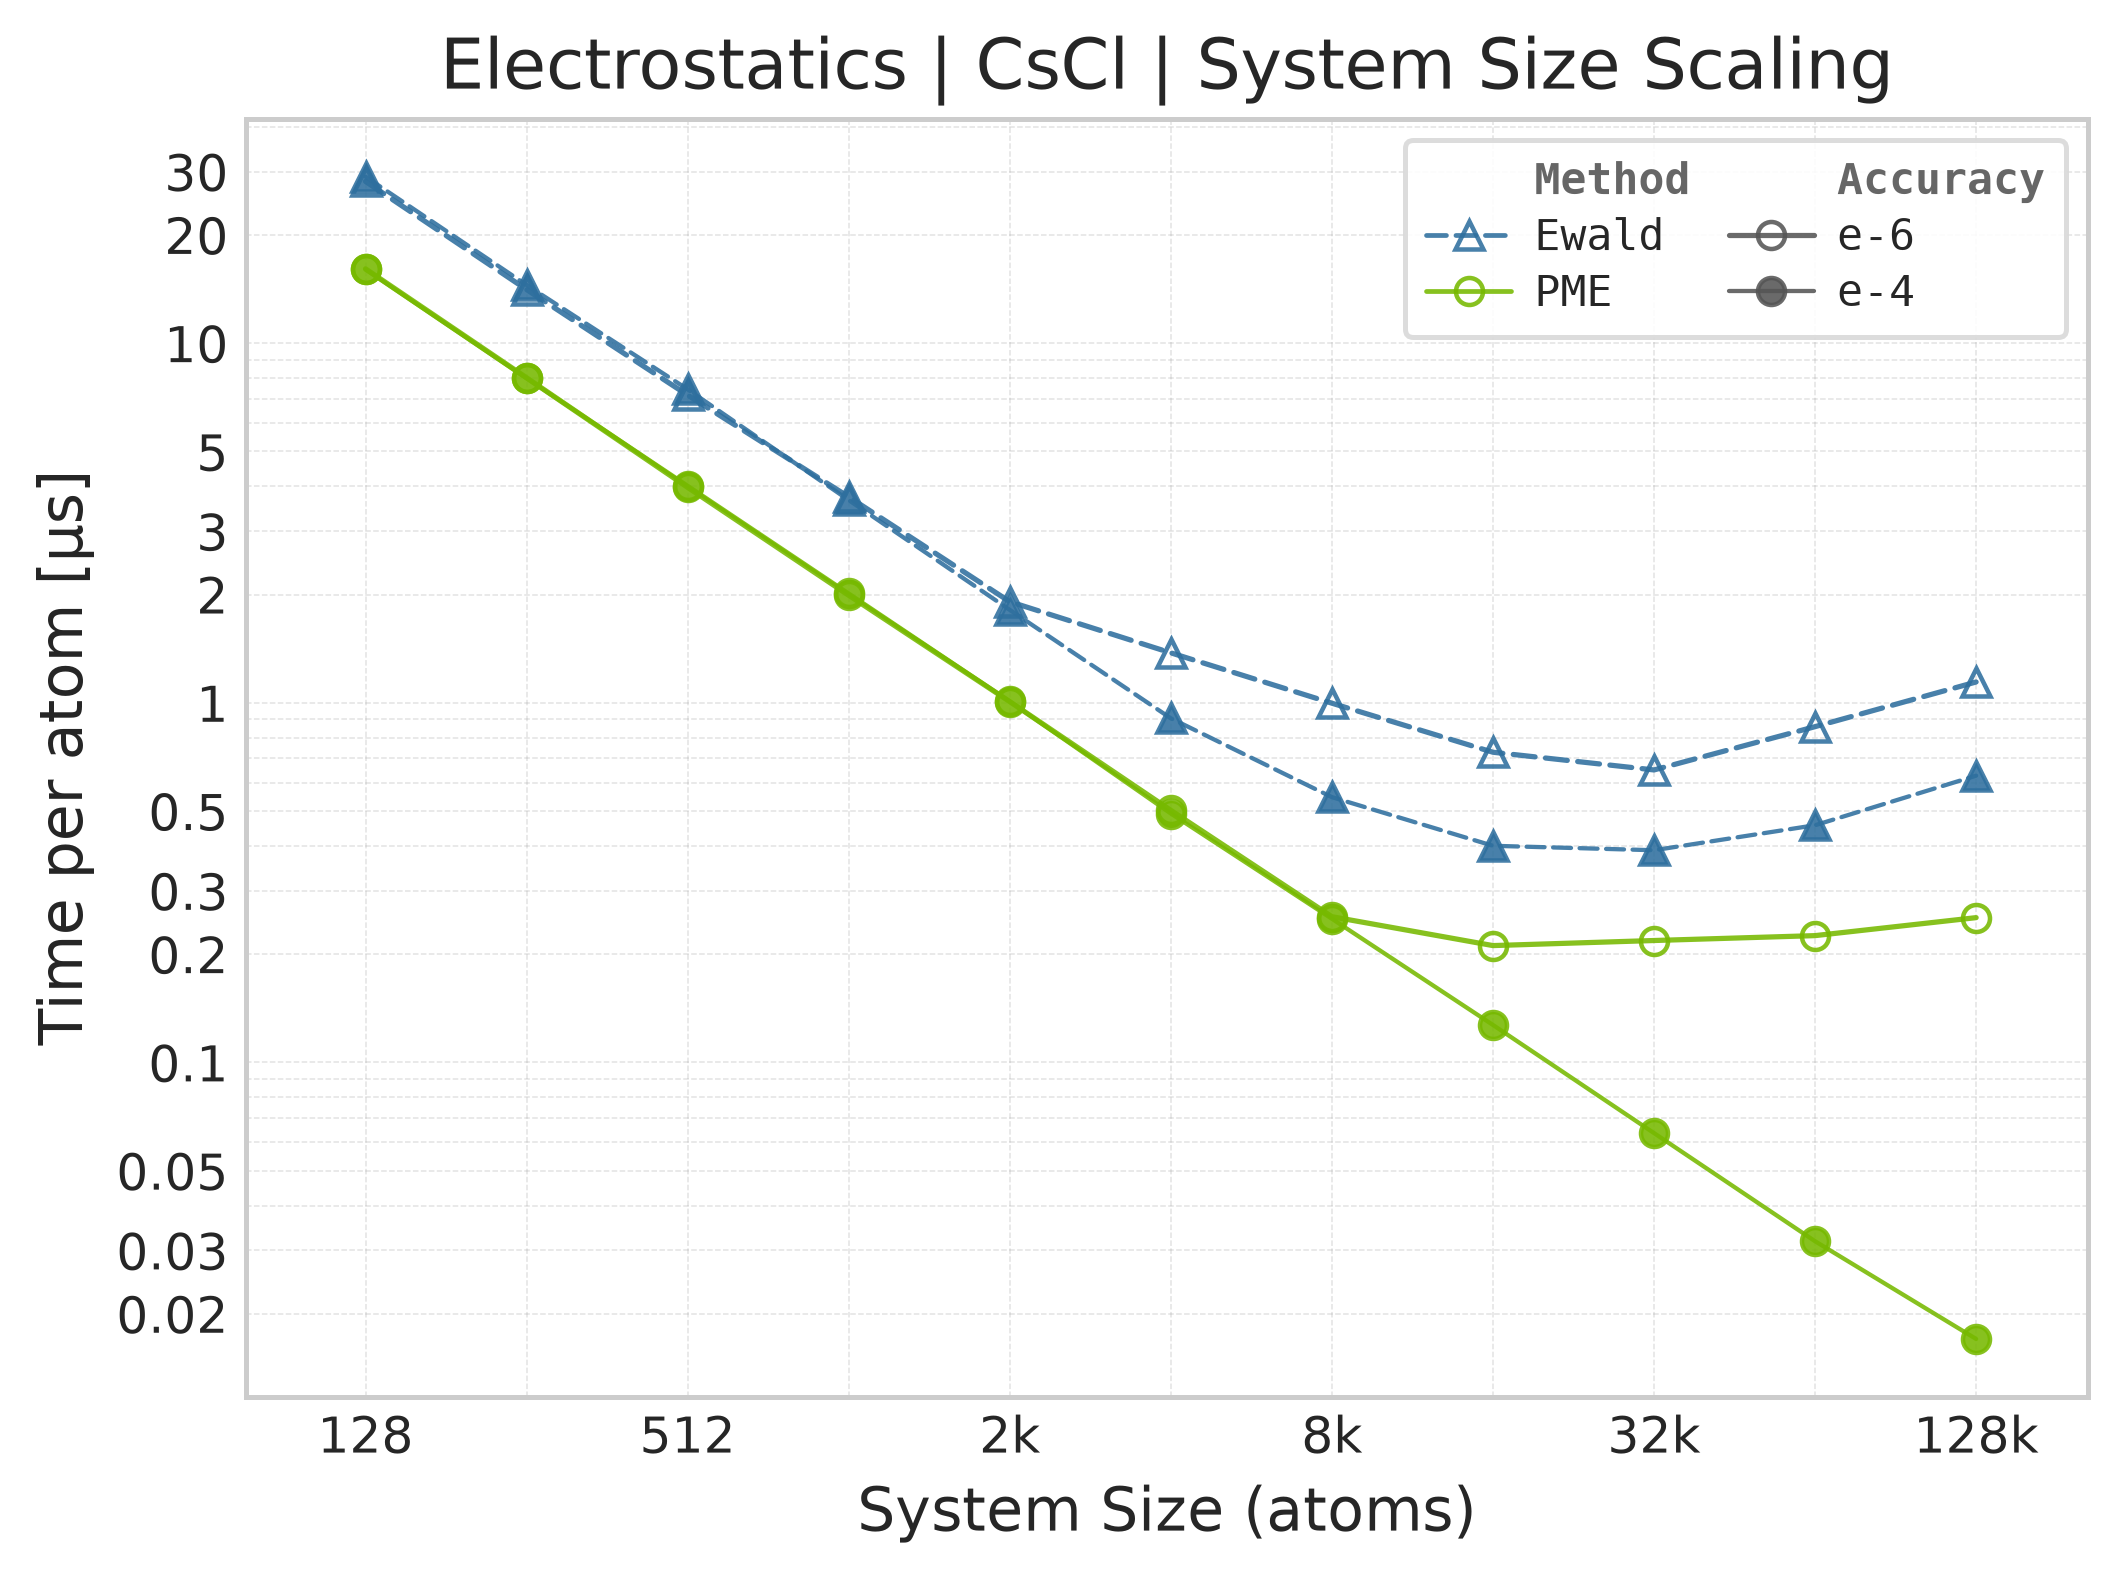
Mean execution time vs. system size (Torch: PME + Ewald, CsCl).#
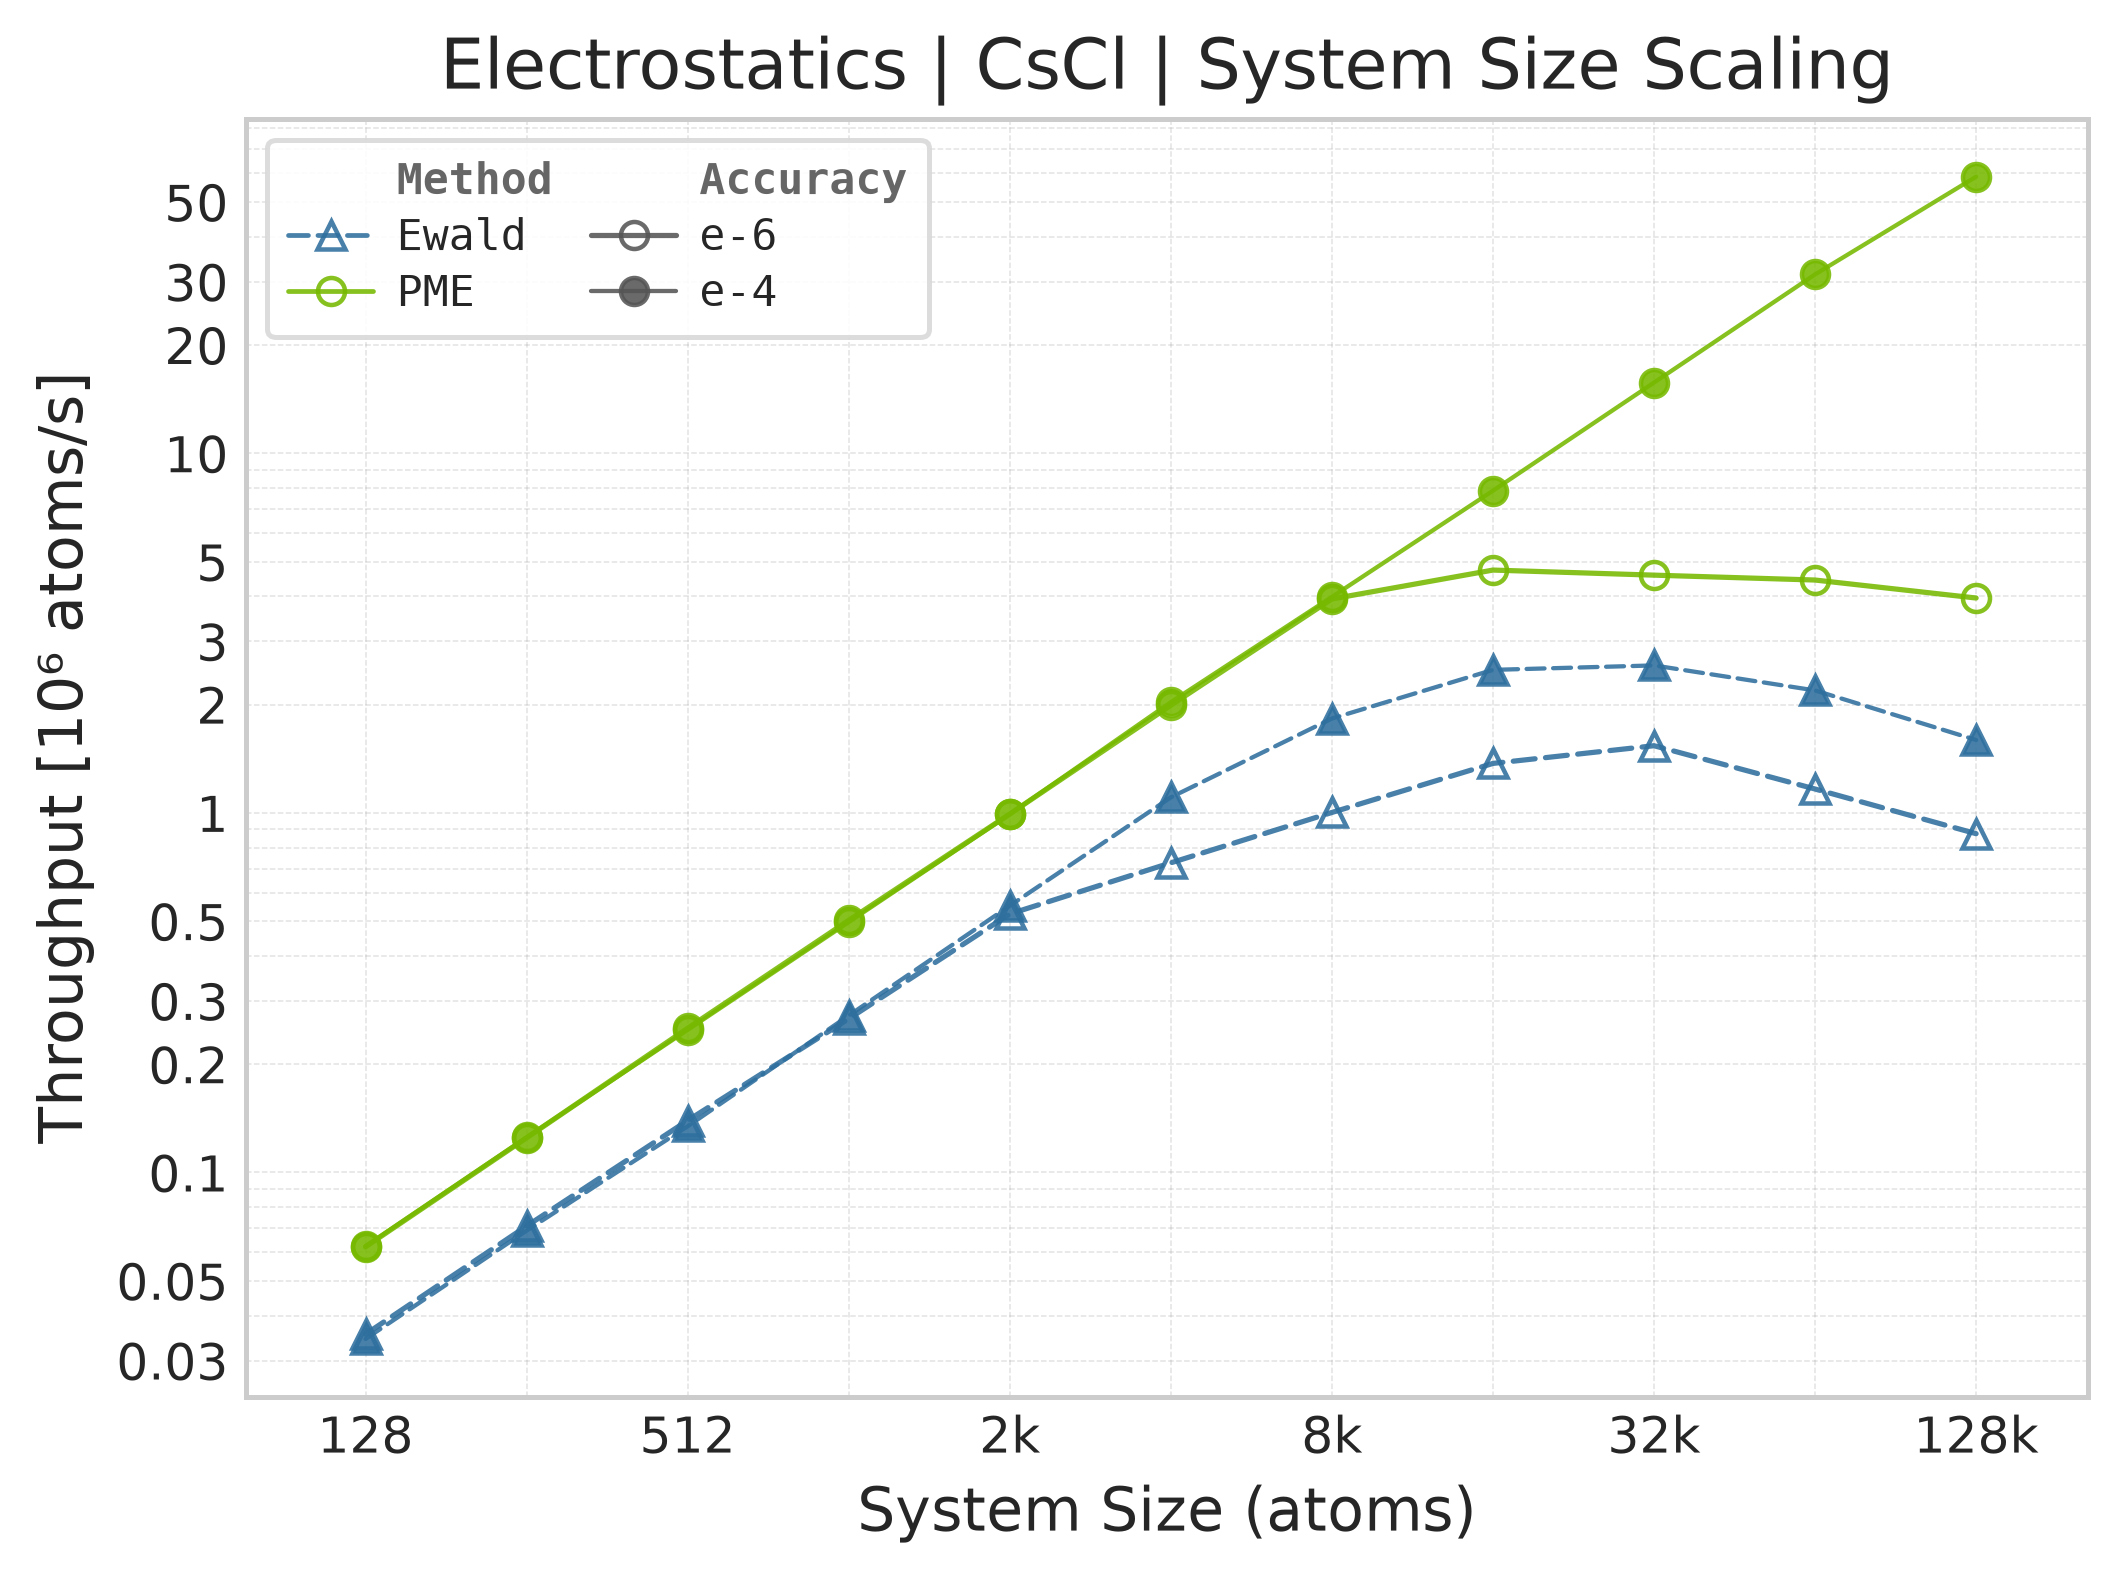
Throughput (\(10^6\) atoms/s) vs. system size.#
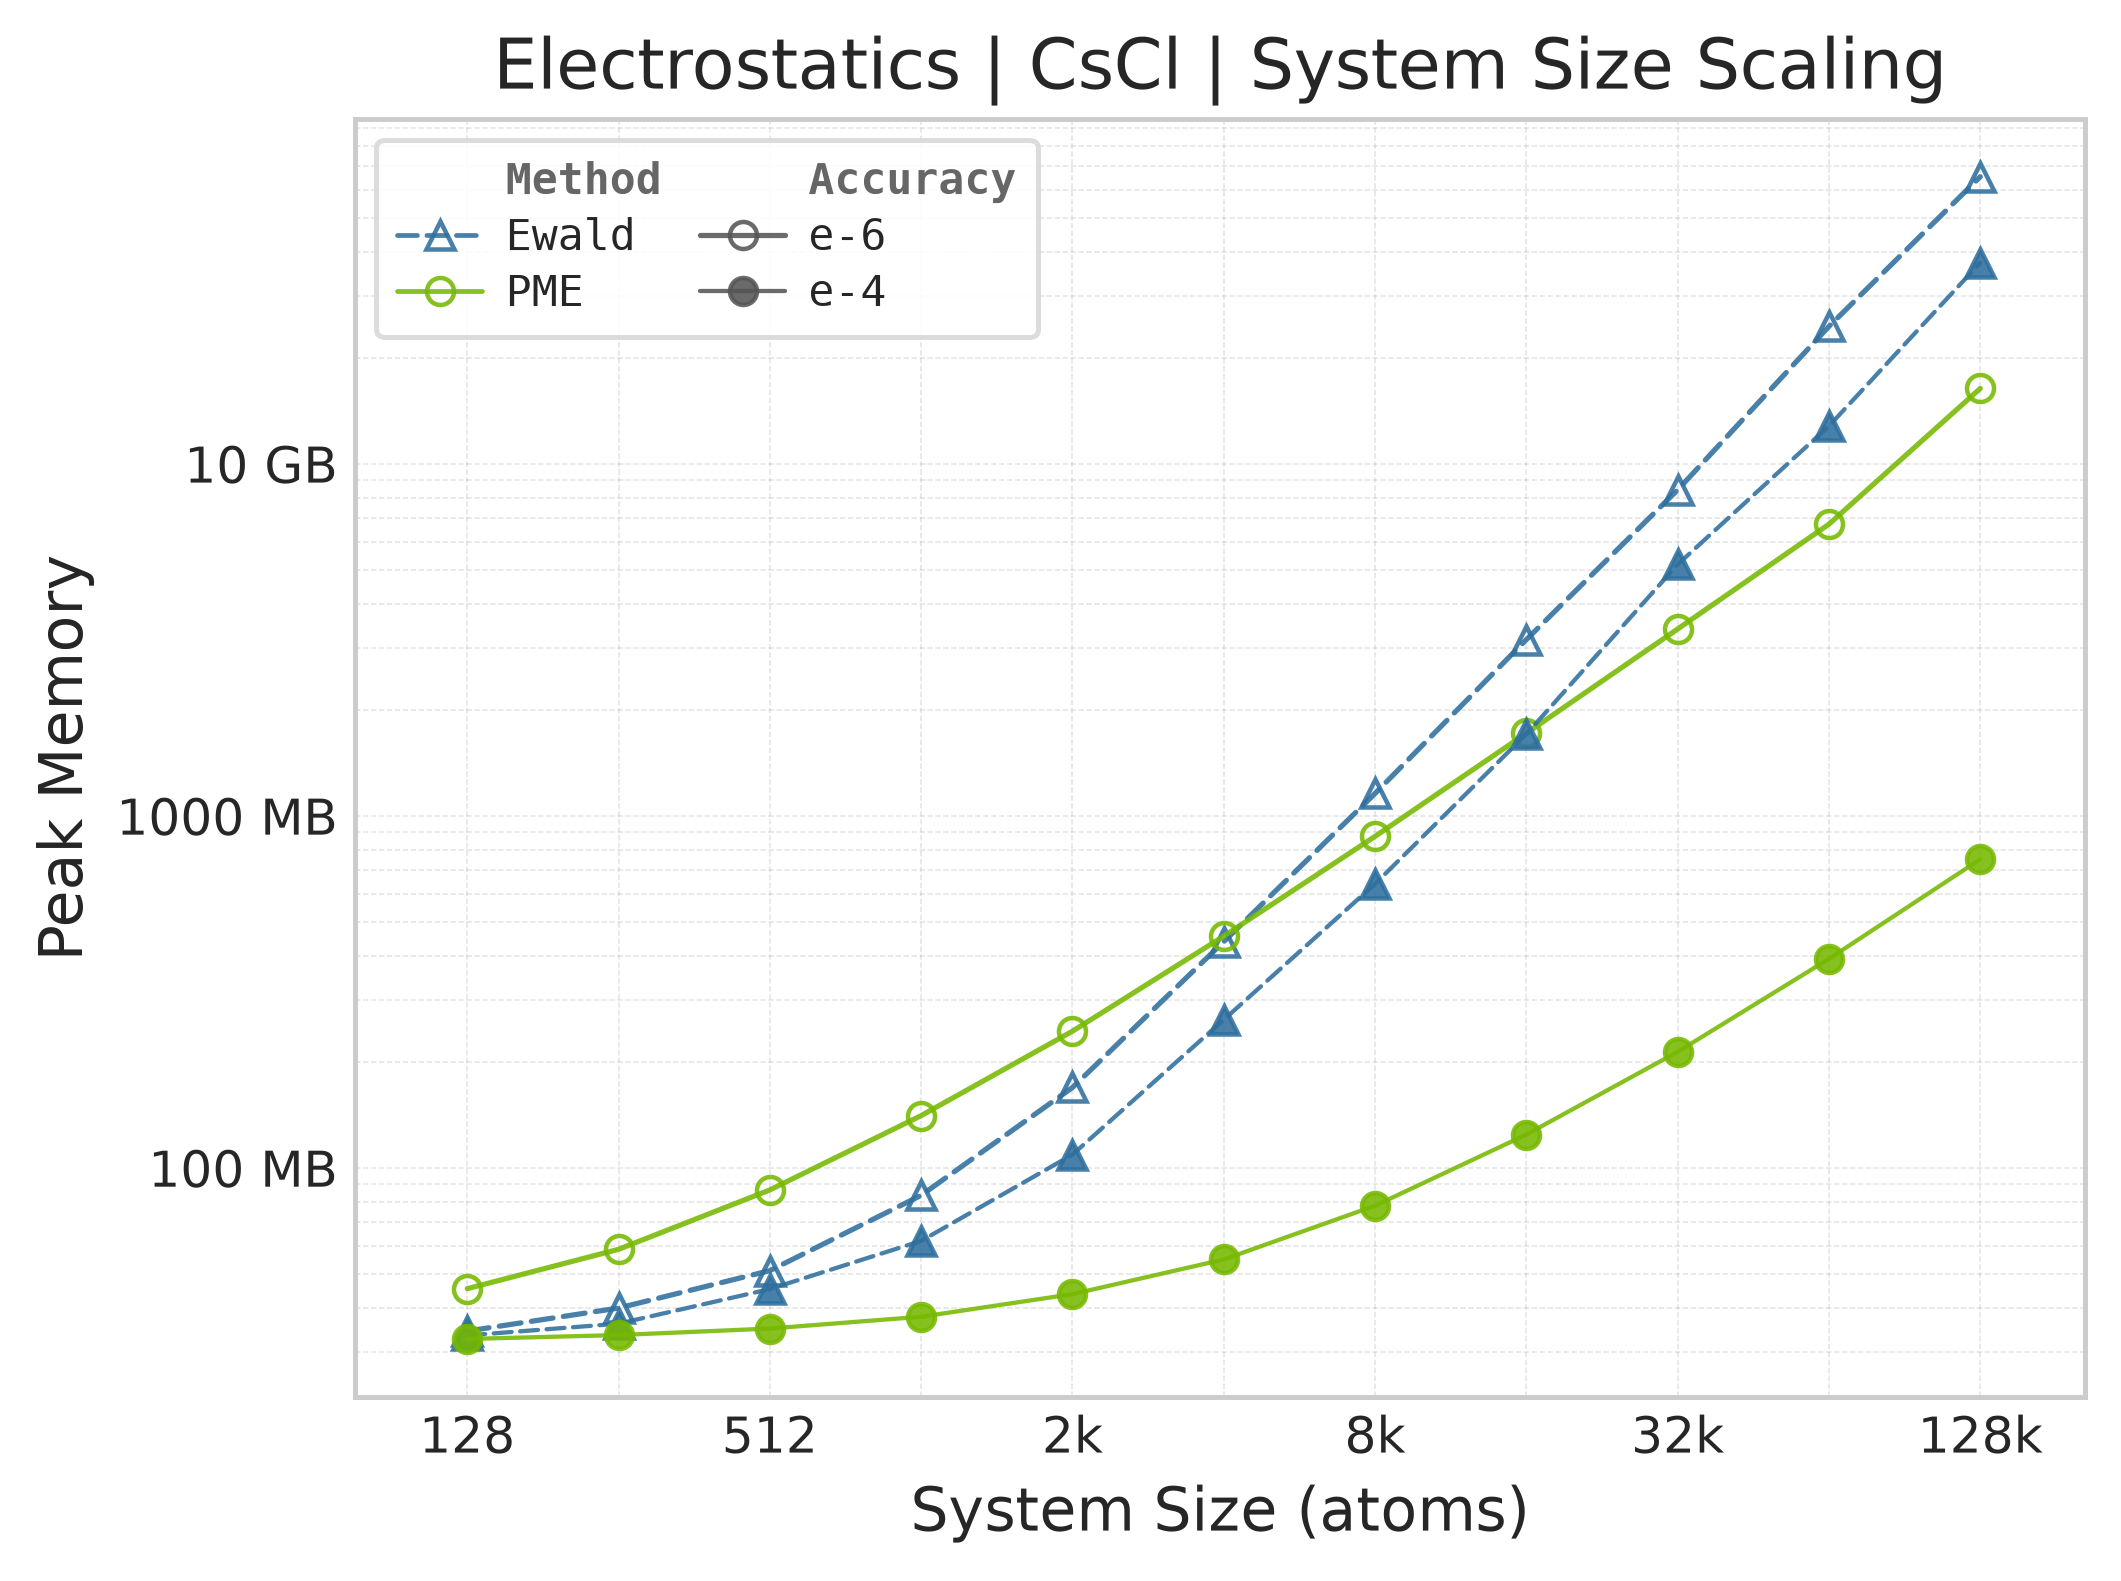
Peak GPU memory vs. system size.#
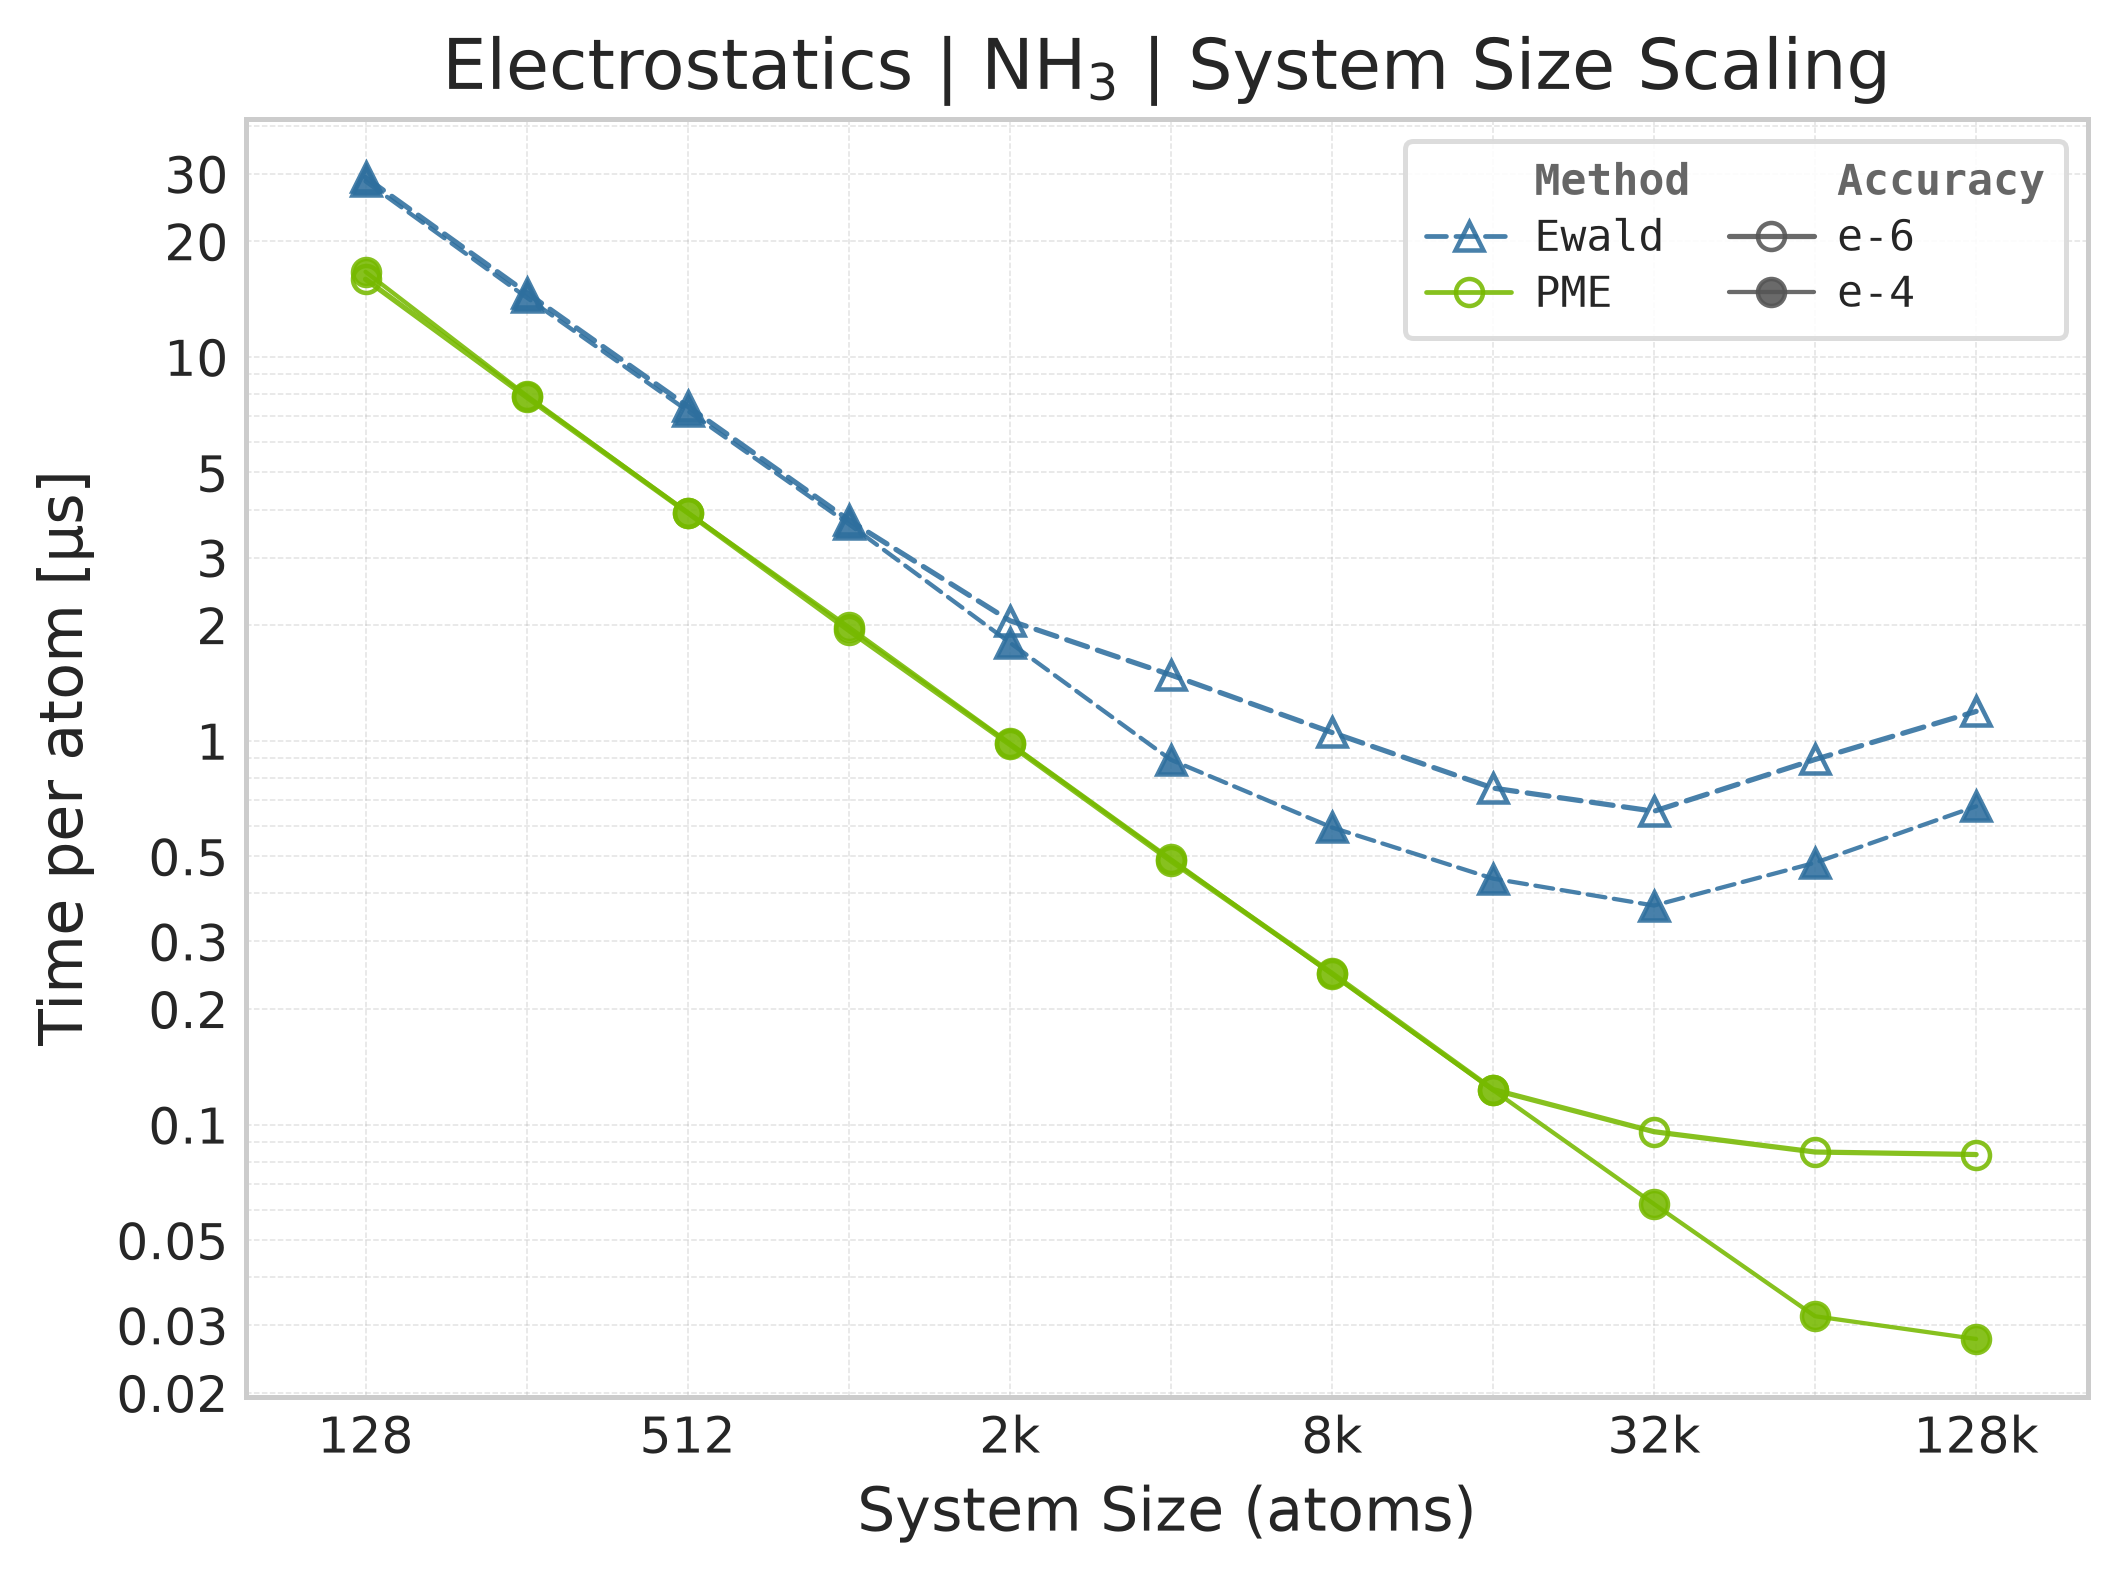
Mean execution time vs. system size (Torch, NH₃).#
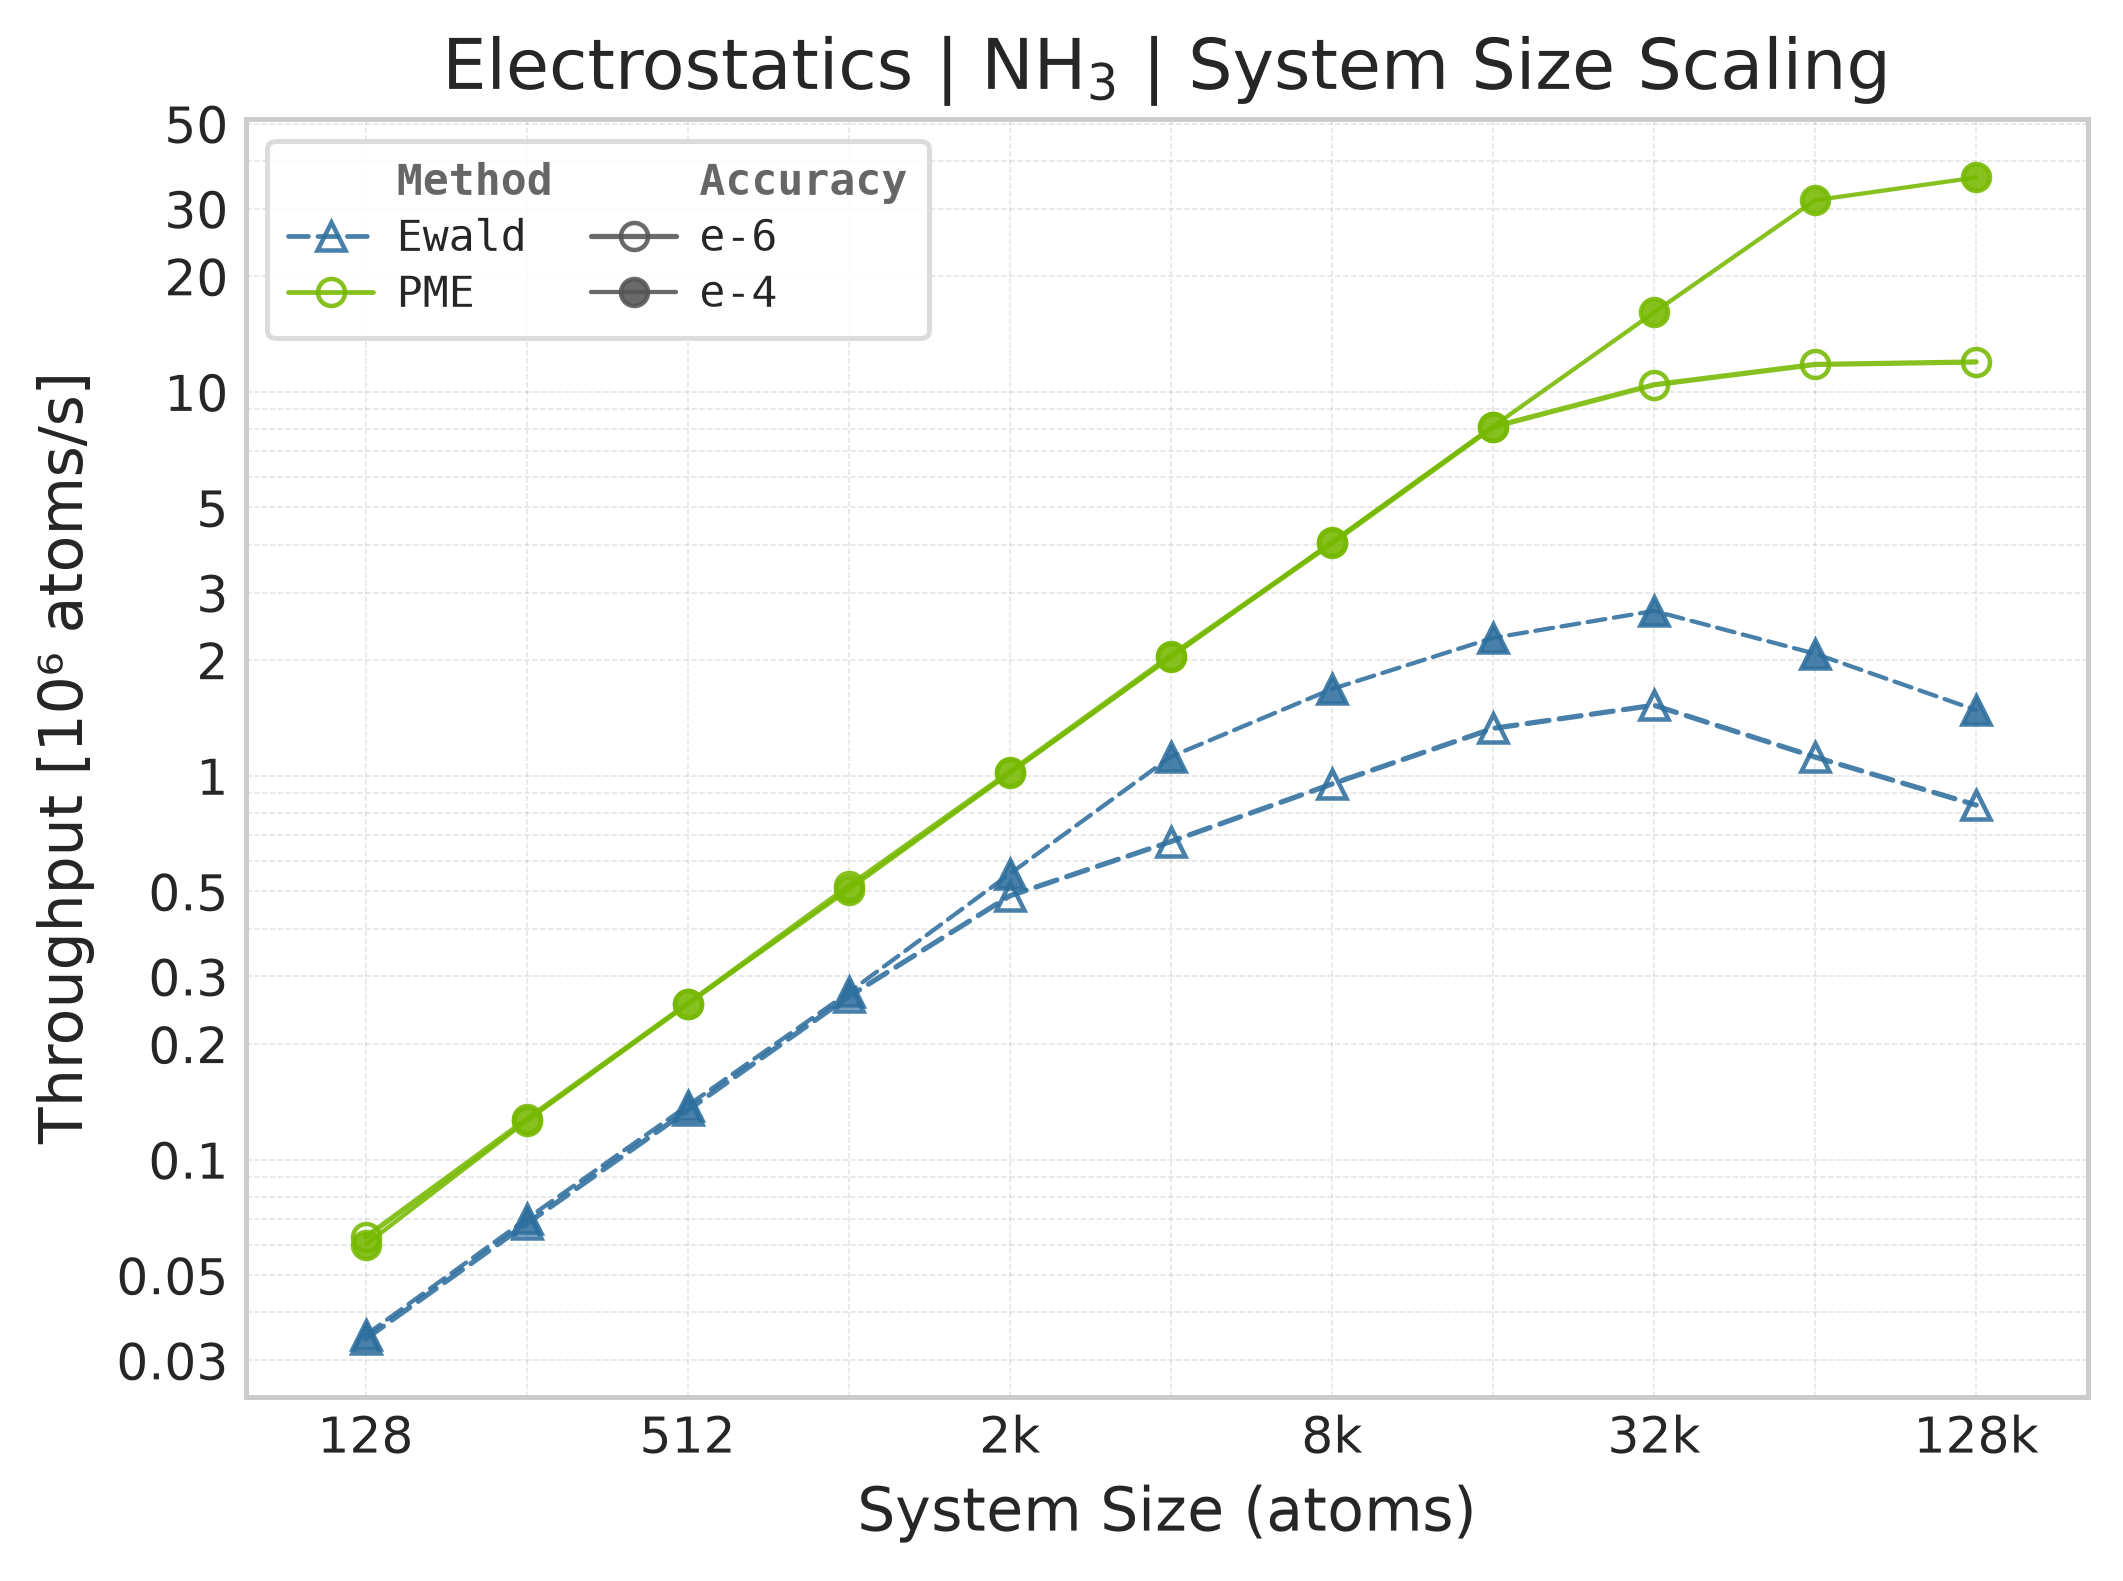
Throughput (\(10^6\) atoms/s) vs. system size (NH₃).#
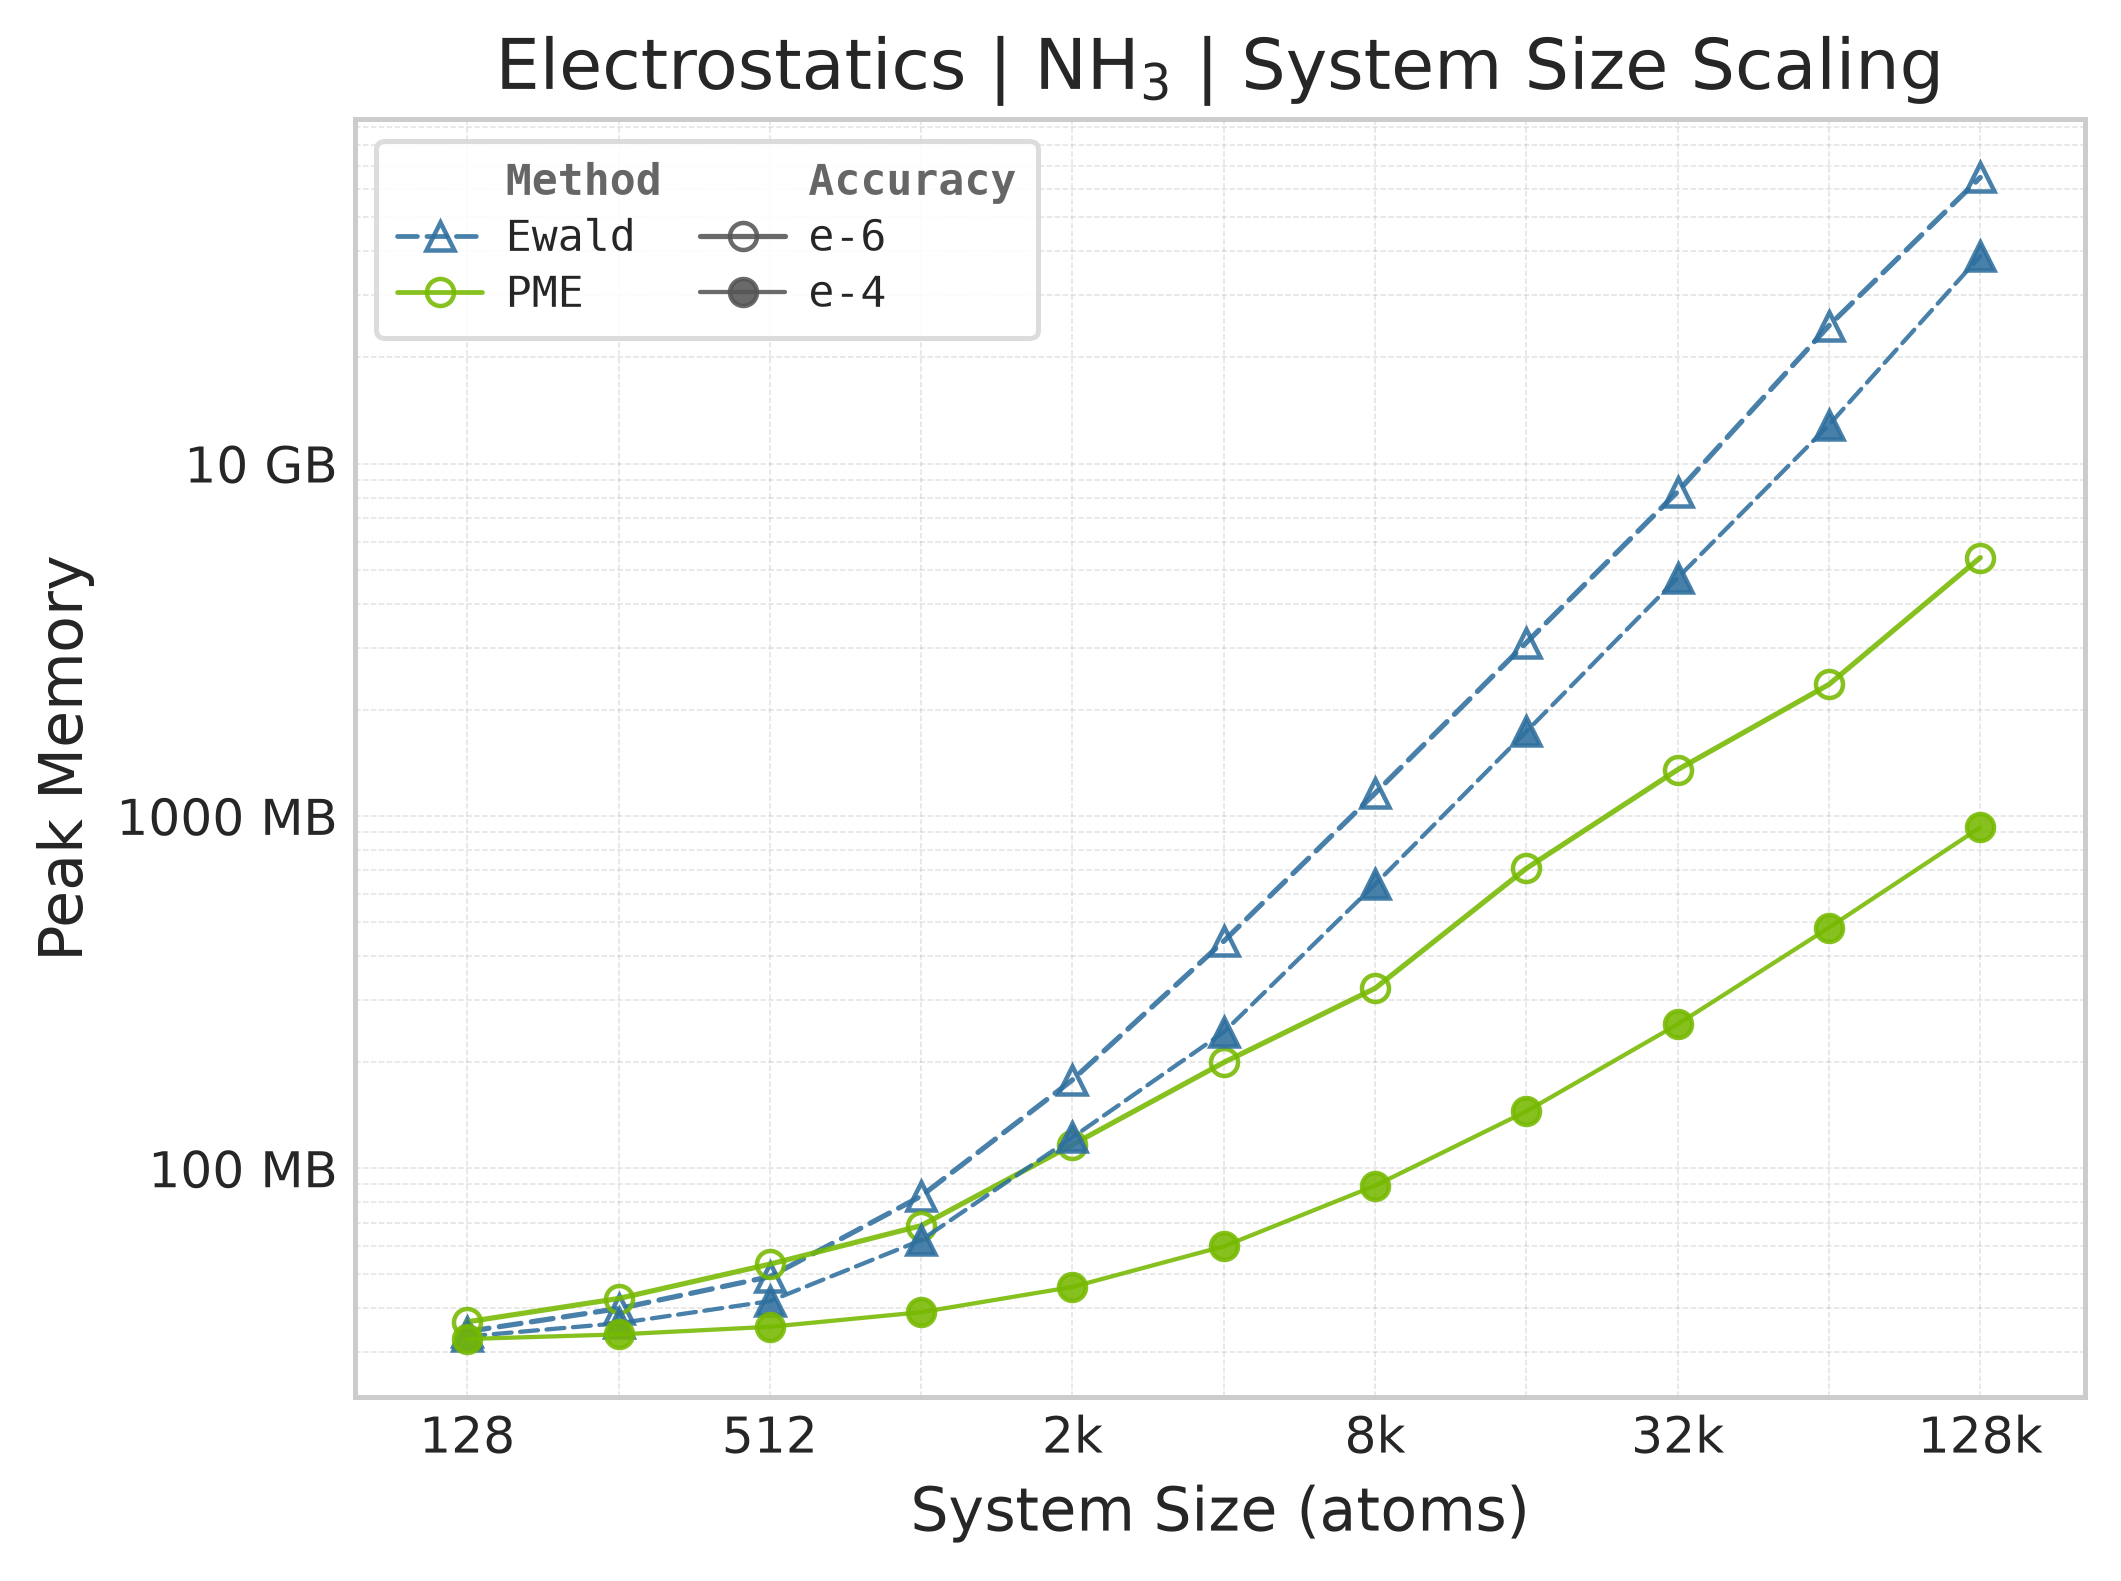
Peak GPU memory vs. system size (NH₃).#
Note
All 148 planned JAX Ewald cases were attempted: 135 measured, 13 reported
OutOfMemoryError. No unmeasured points remain. All OOM cases contain
131,072 total atoms: 12 failed during neighbor-list setup and one during the
Ewald timing call. JAX memory is unavailable because this suite records memory
through the Torch CUDA allocator, which does not measure JAX allocations.
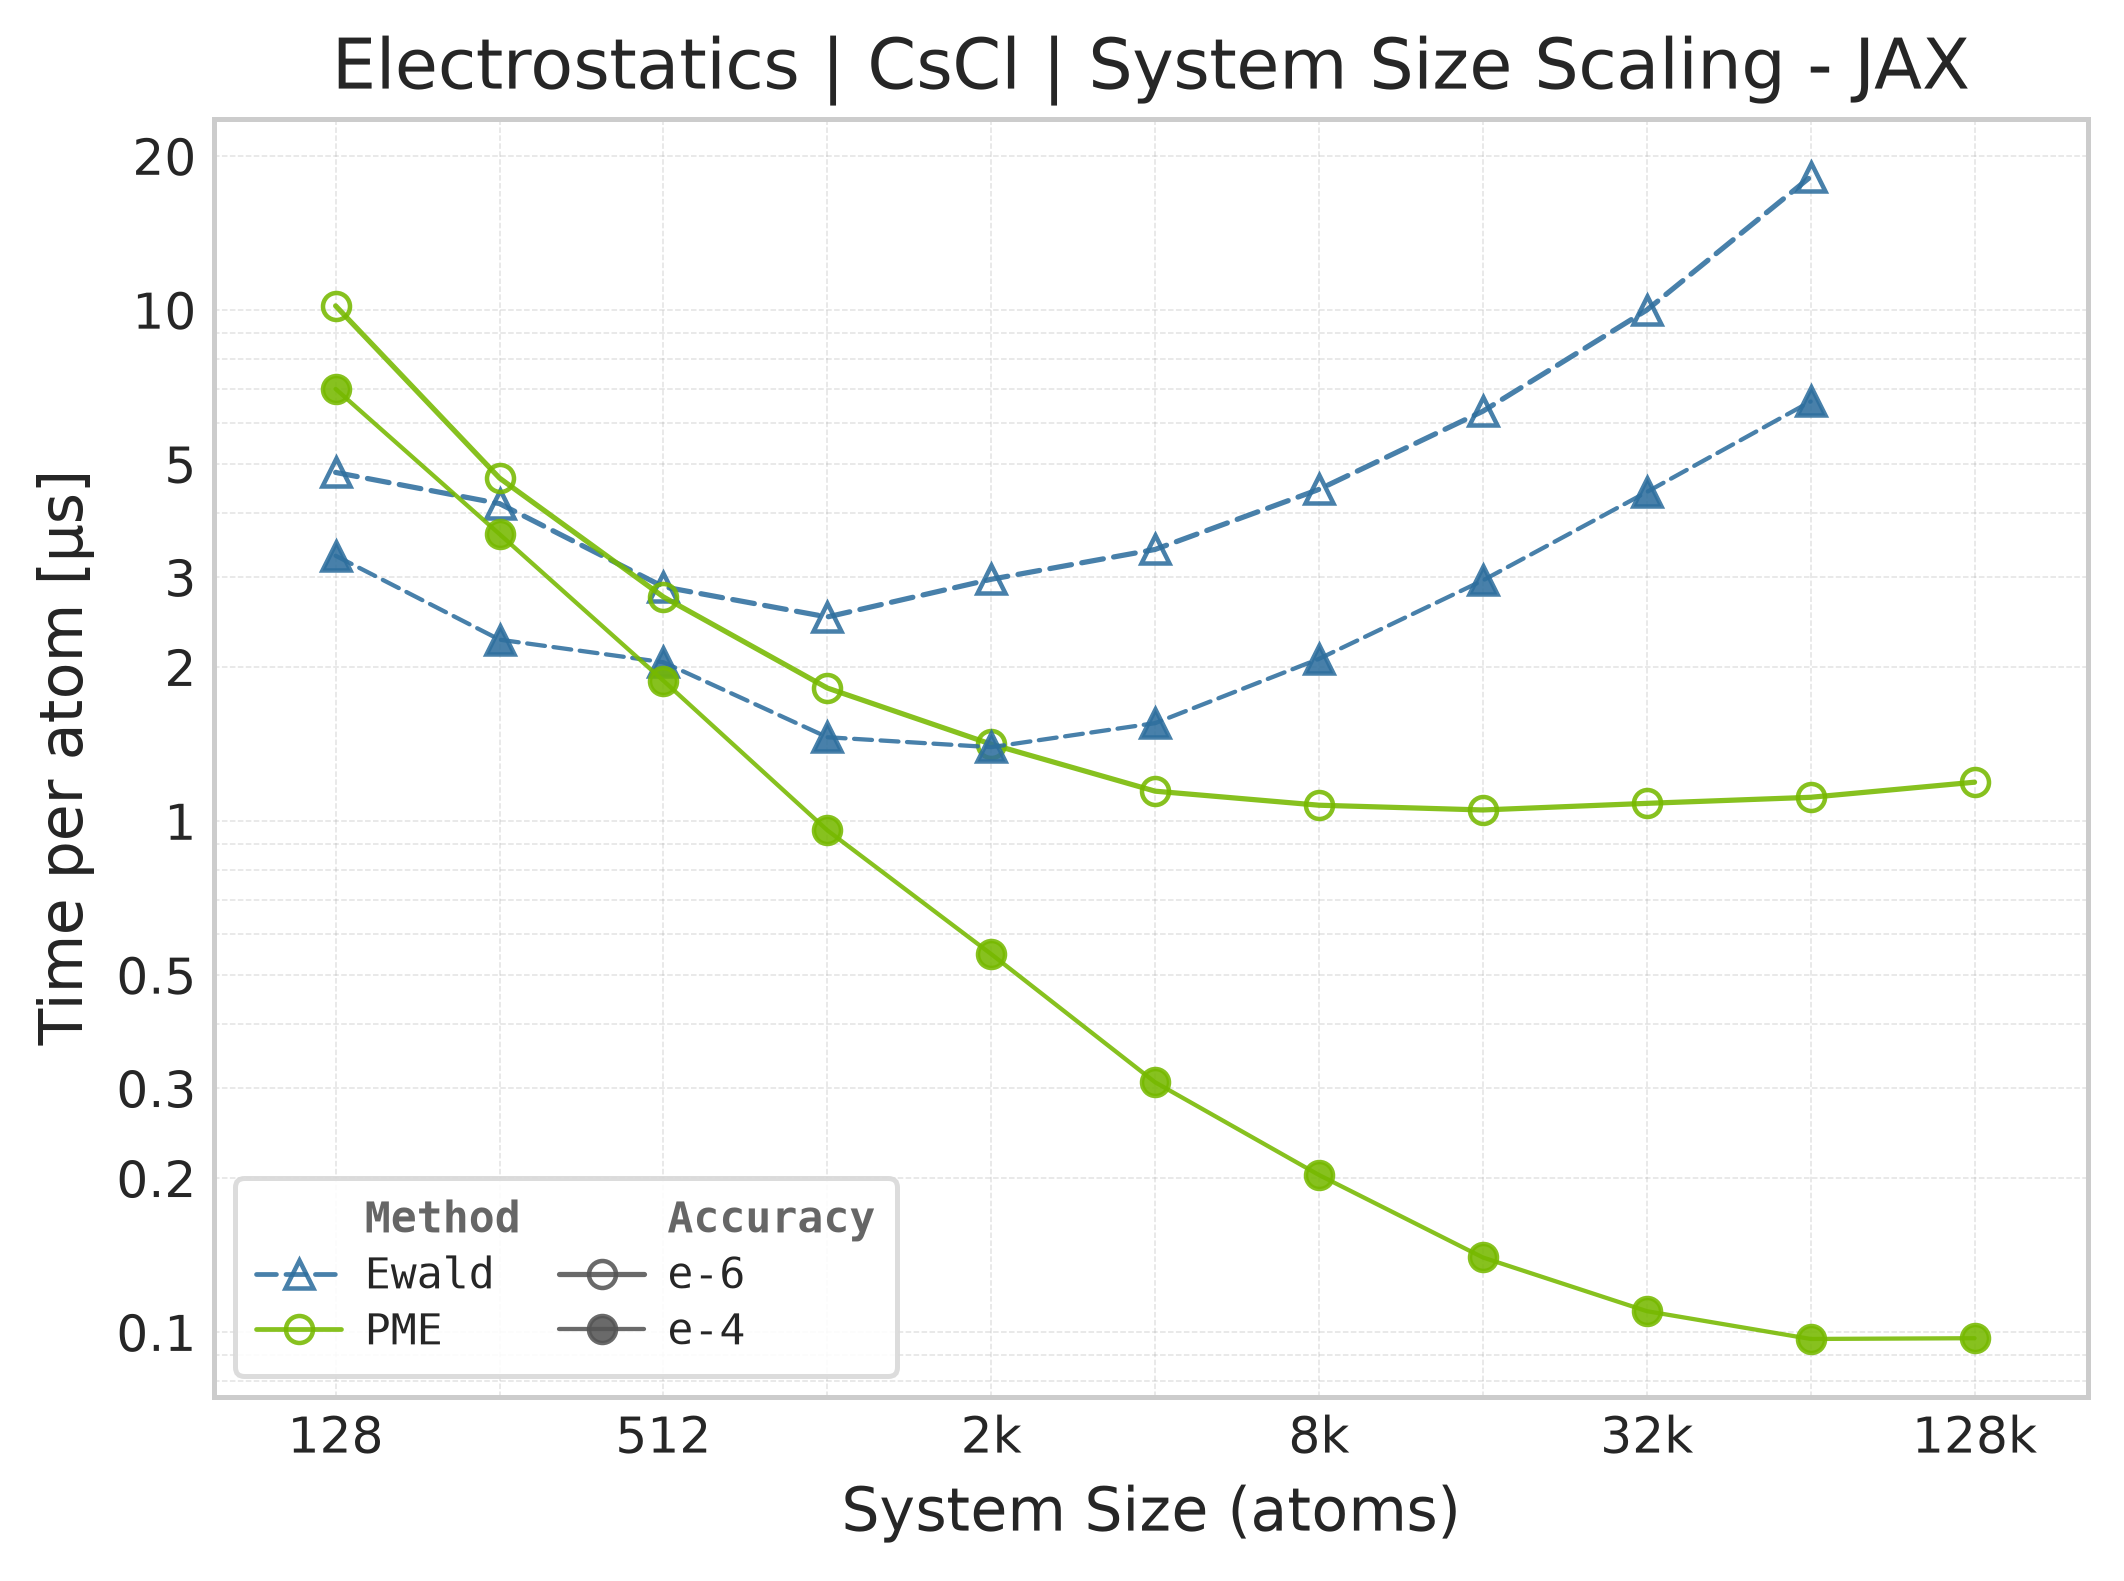
Mean execution time vs. system size (JAX, CsCl).#
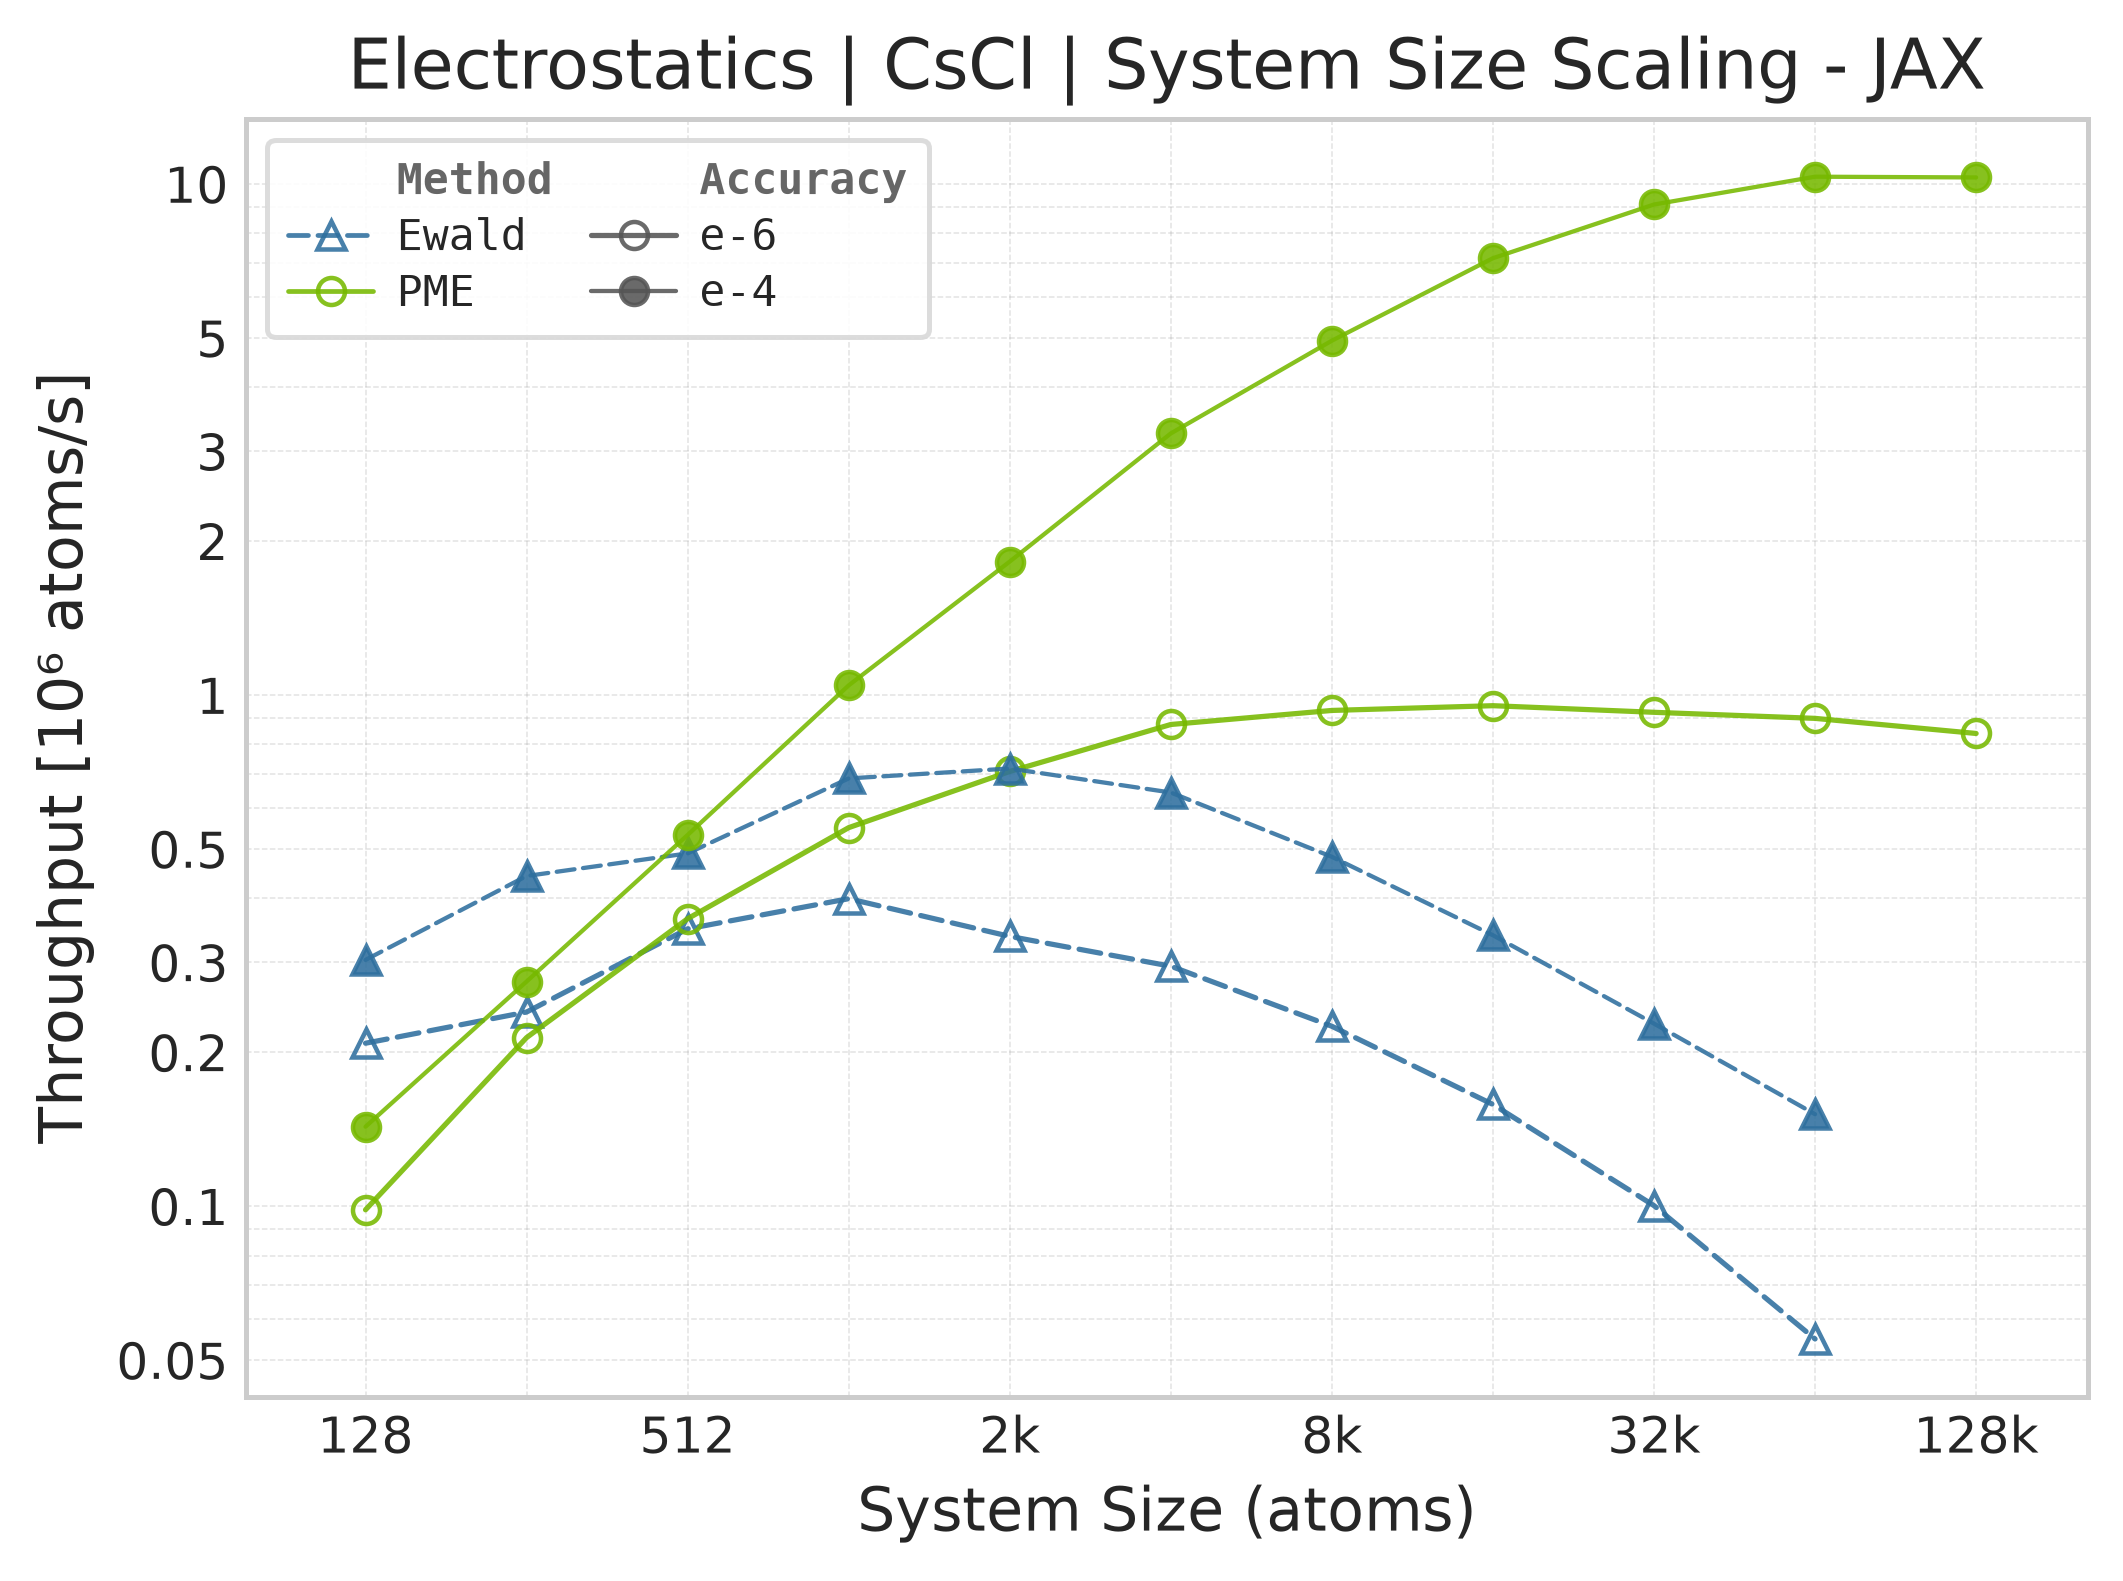
Throughput (\(10^6\) atoms/s) vs. system size (JAX).#
Note
JAX memory plots are omitted. The suite does not measure JAX memory: XLA’s allocator pool and buffer reuse make per-call allocation deltas unreliable. The Torch panels report the Torch allocator only; they are not a proxy for JAX memory because the framework wrappers, buffer lifetimes, and allocators differ.
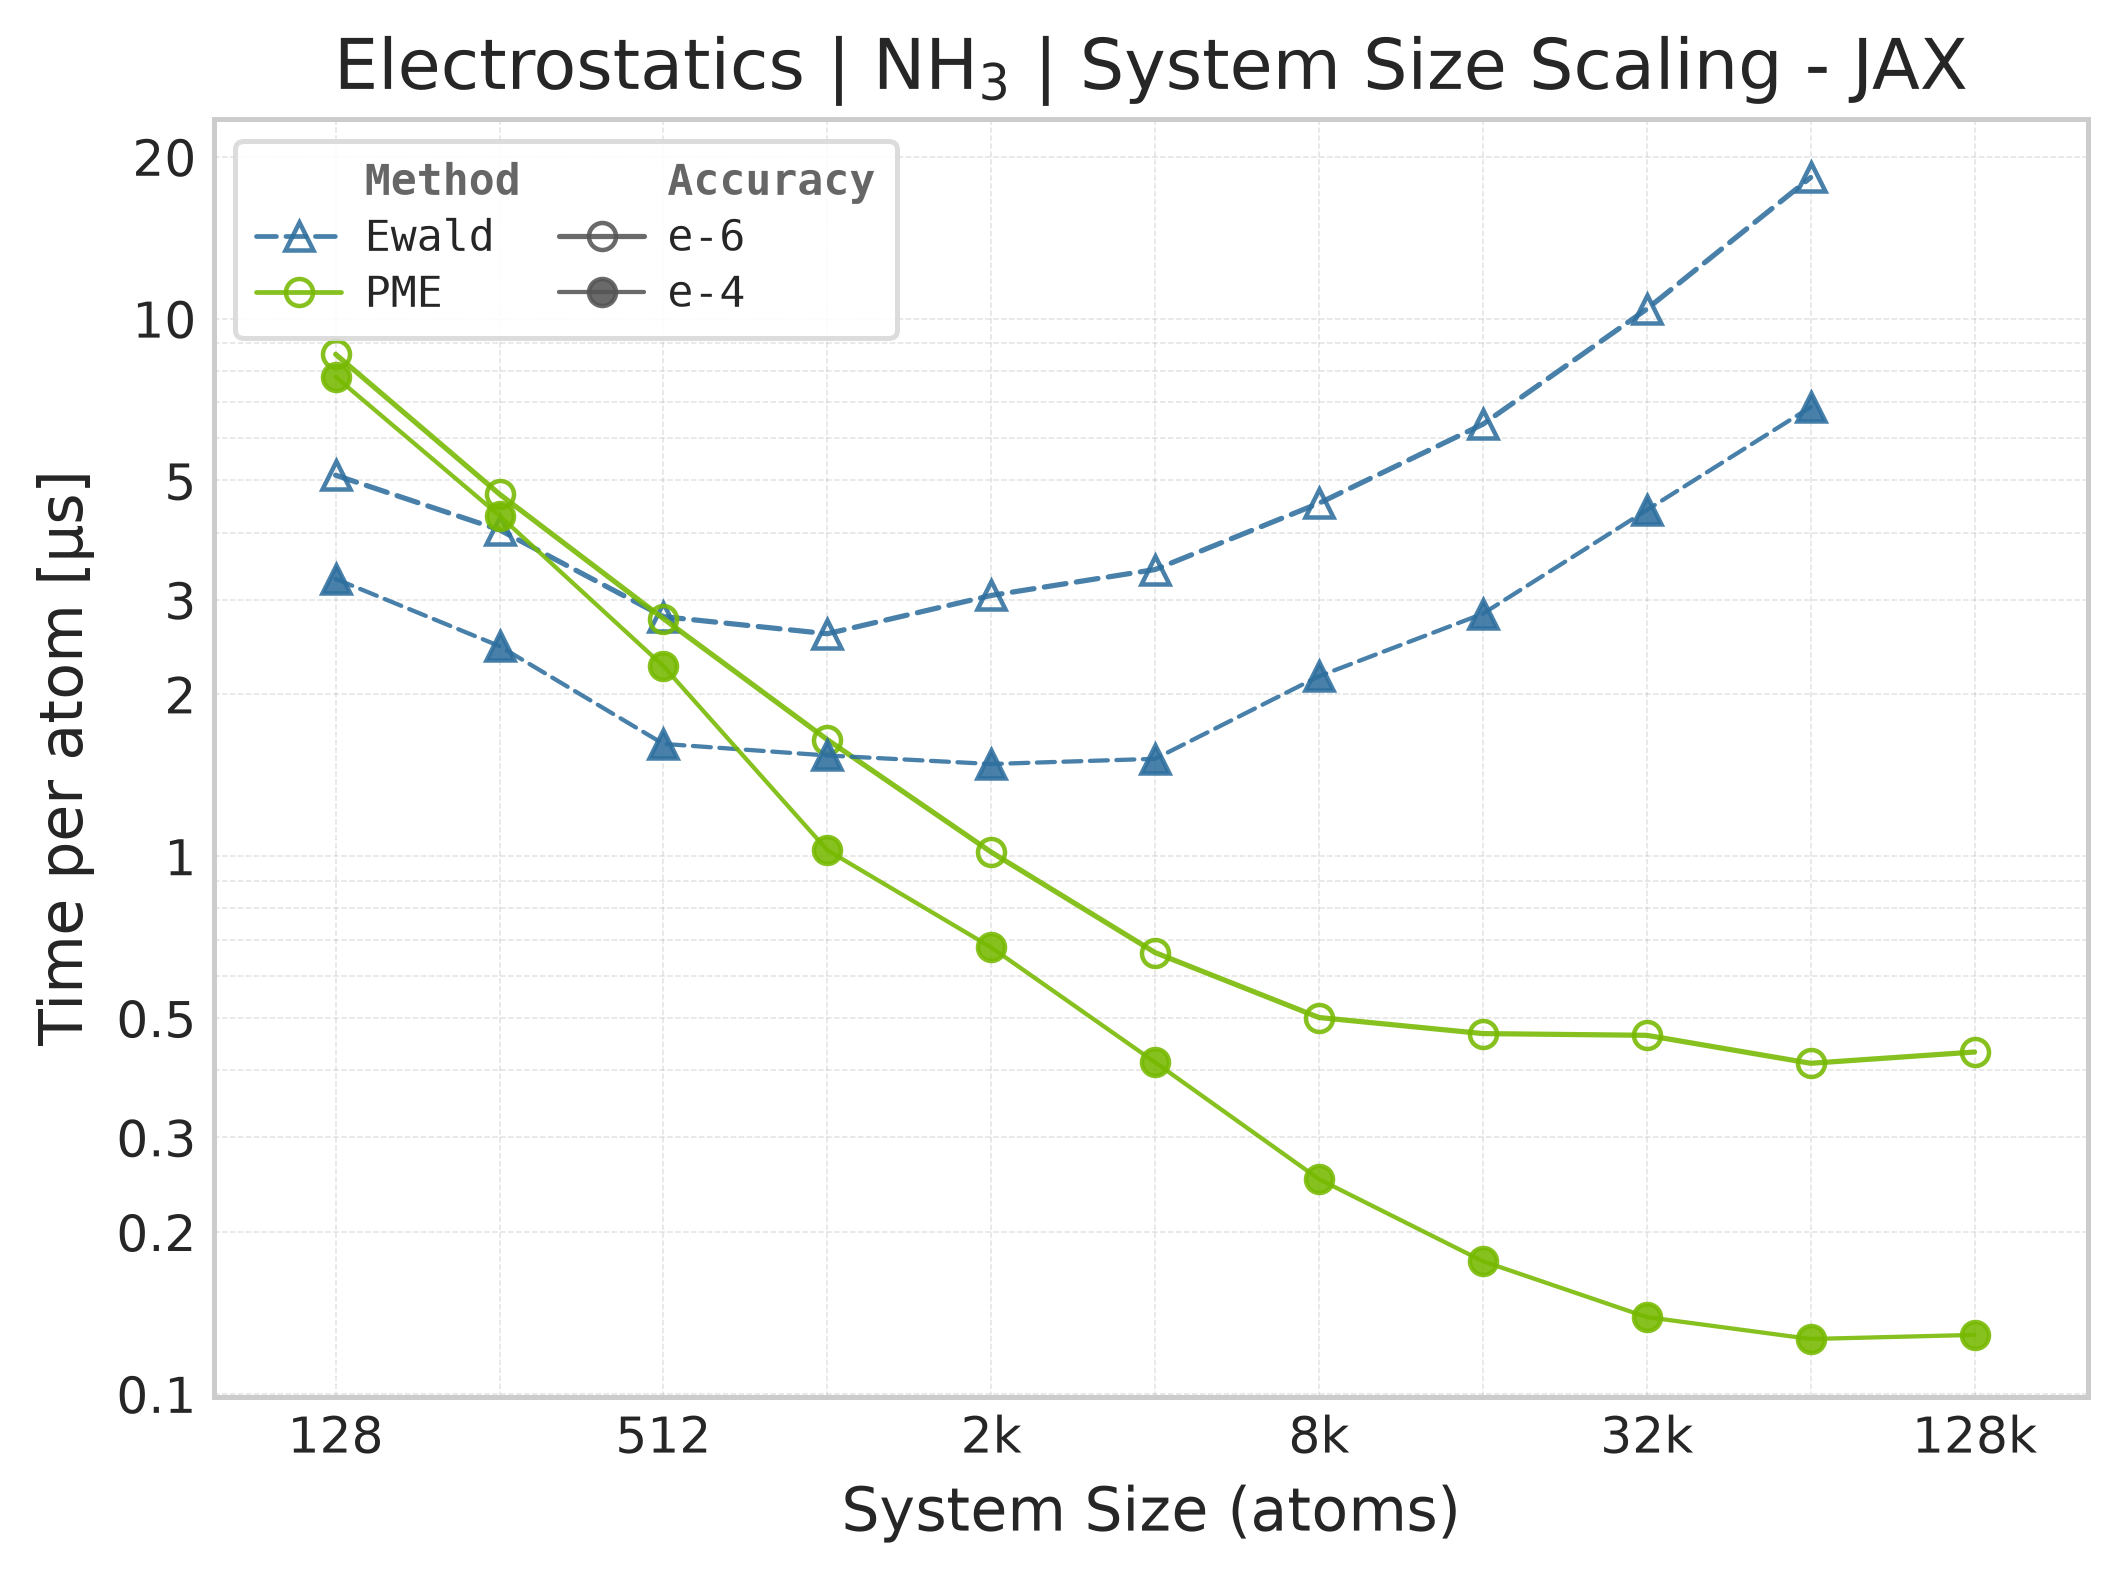
Mean execution time vs. system size (JAX, NH₃).#
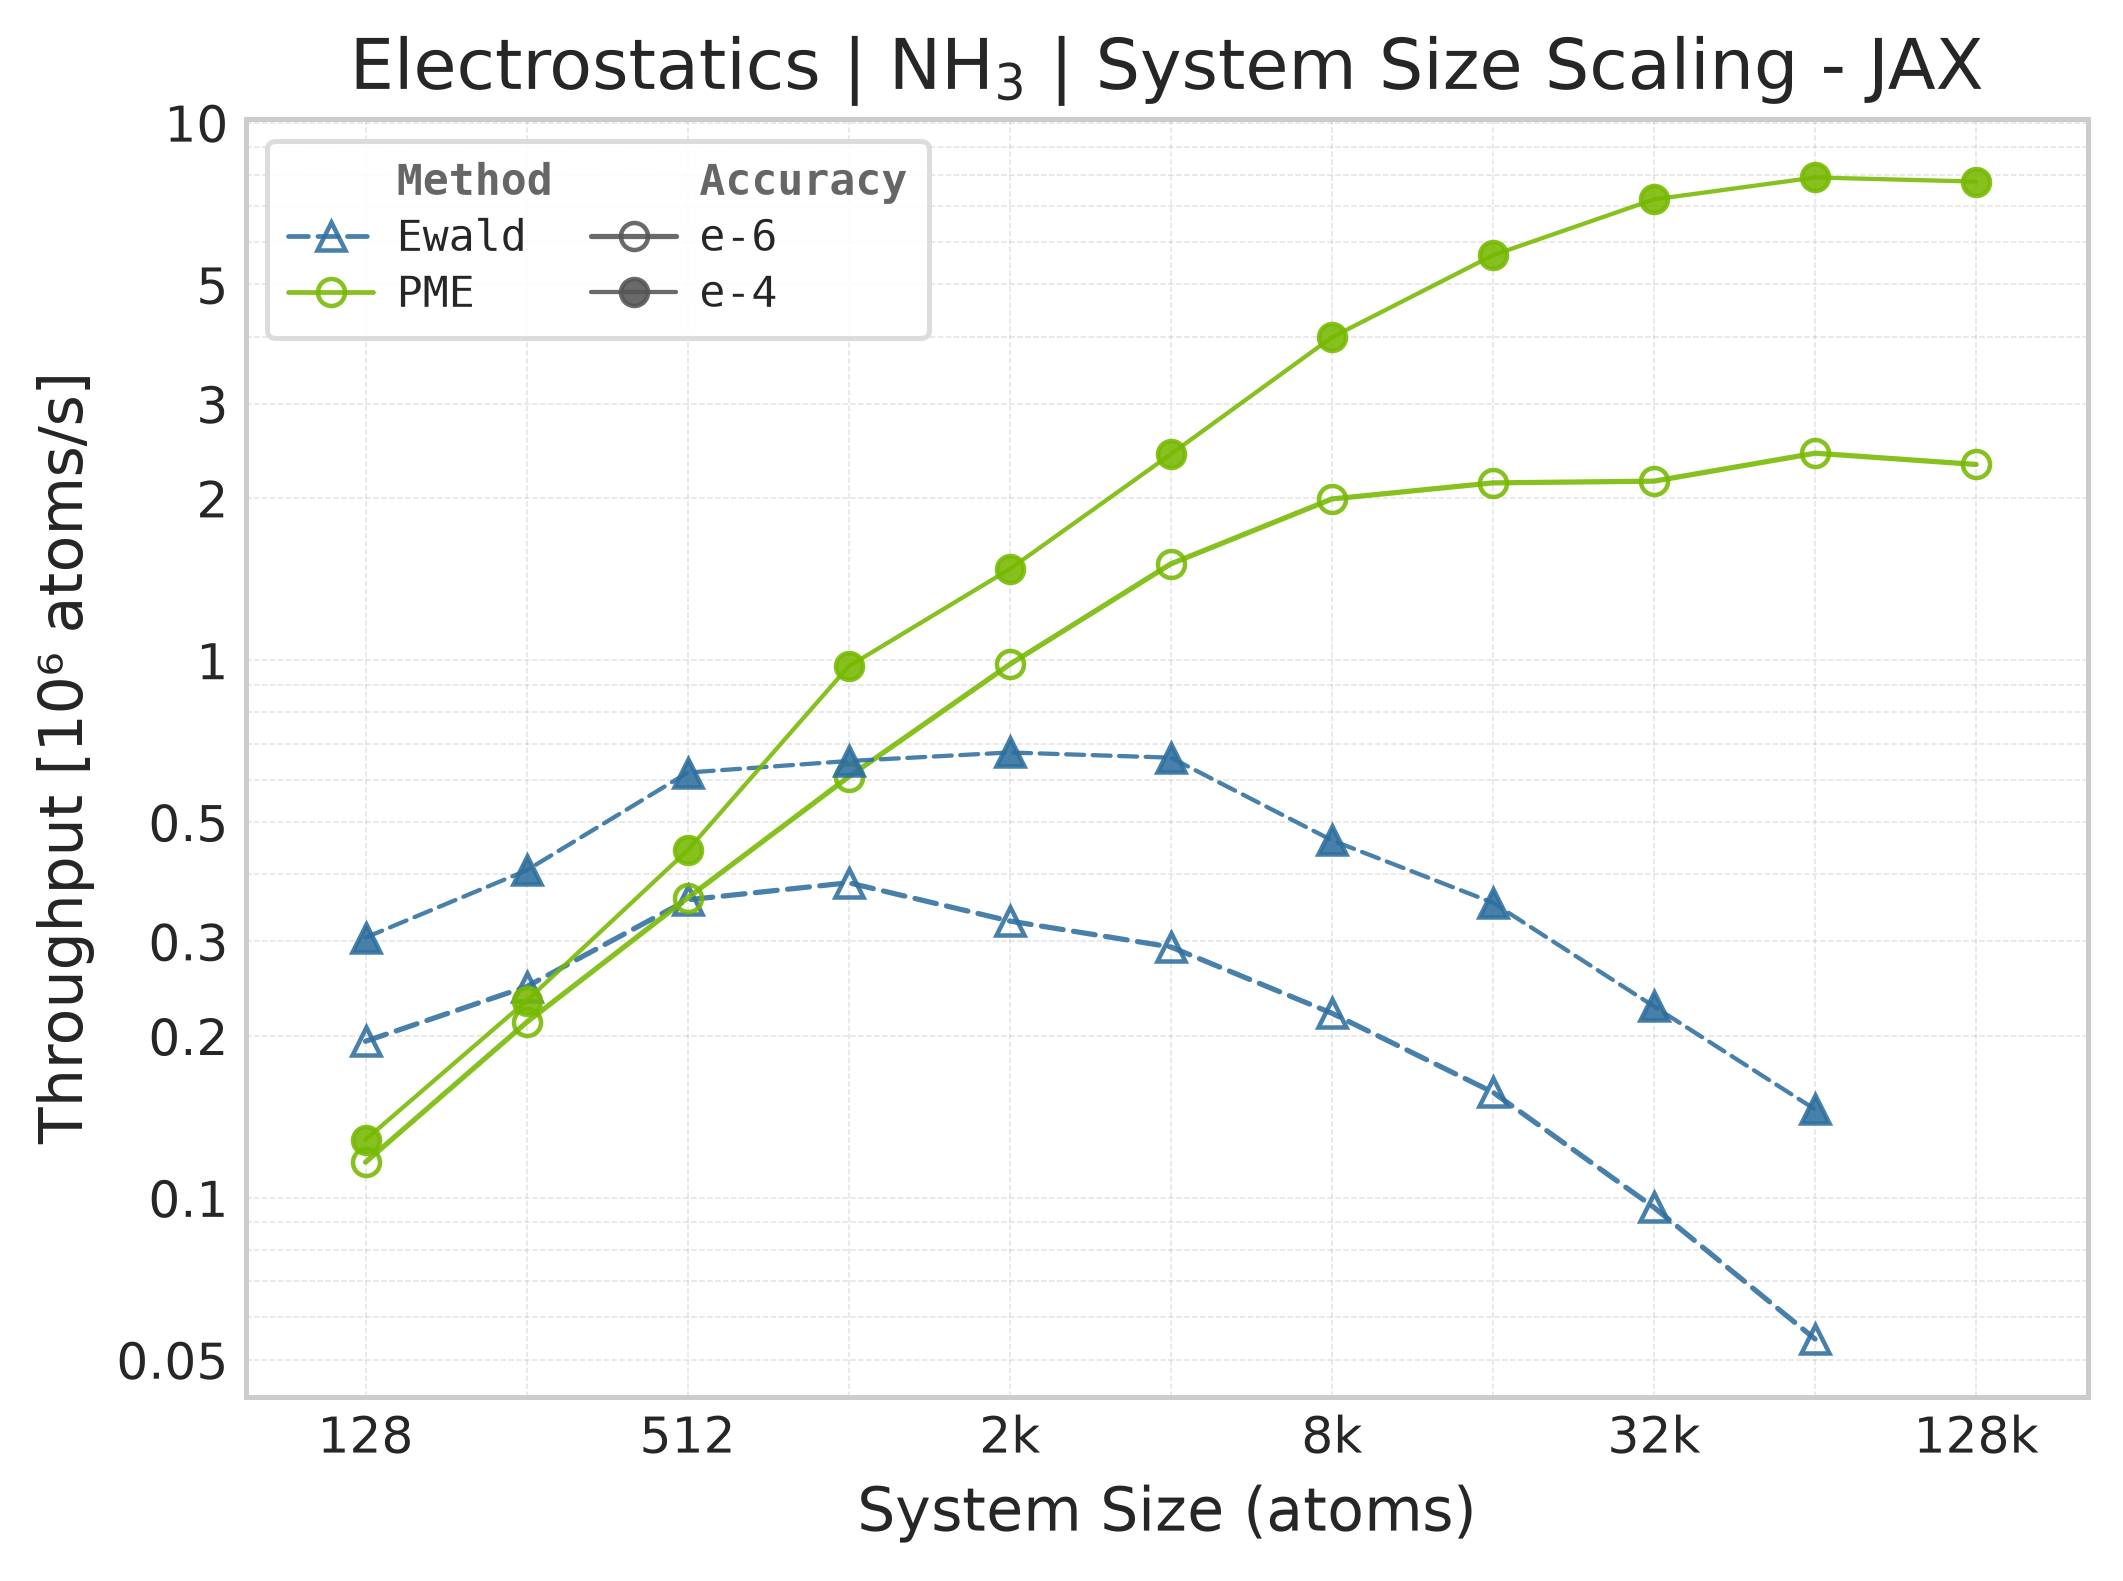
Throughput (\(10^6\) atoms/s) vs. system size (JAX, NH₃).#
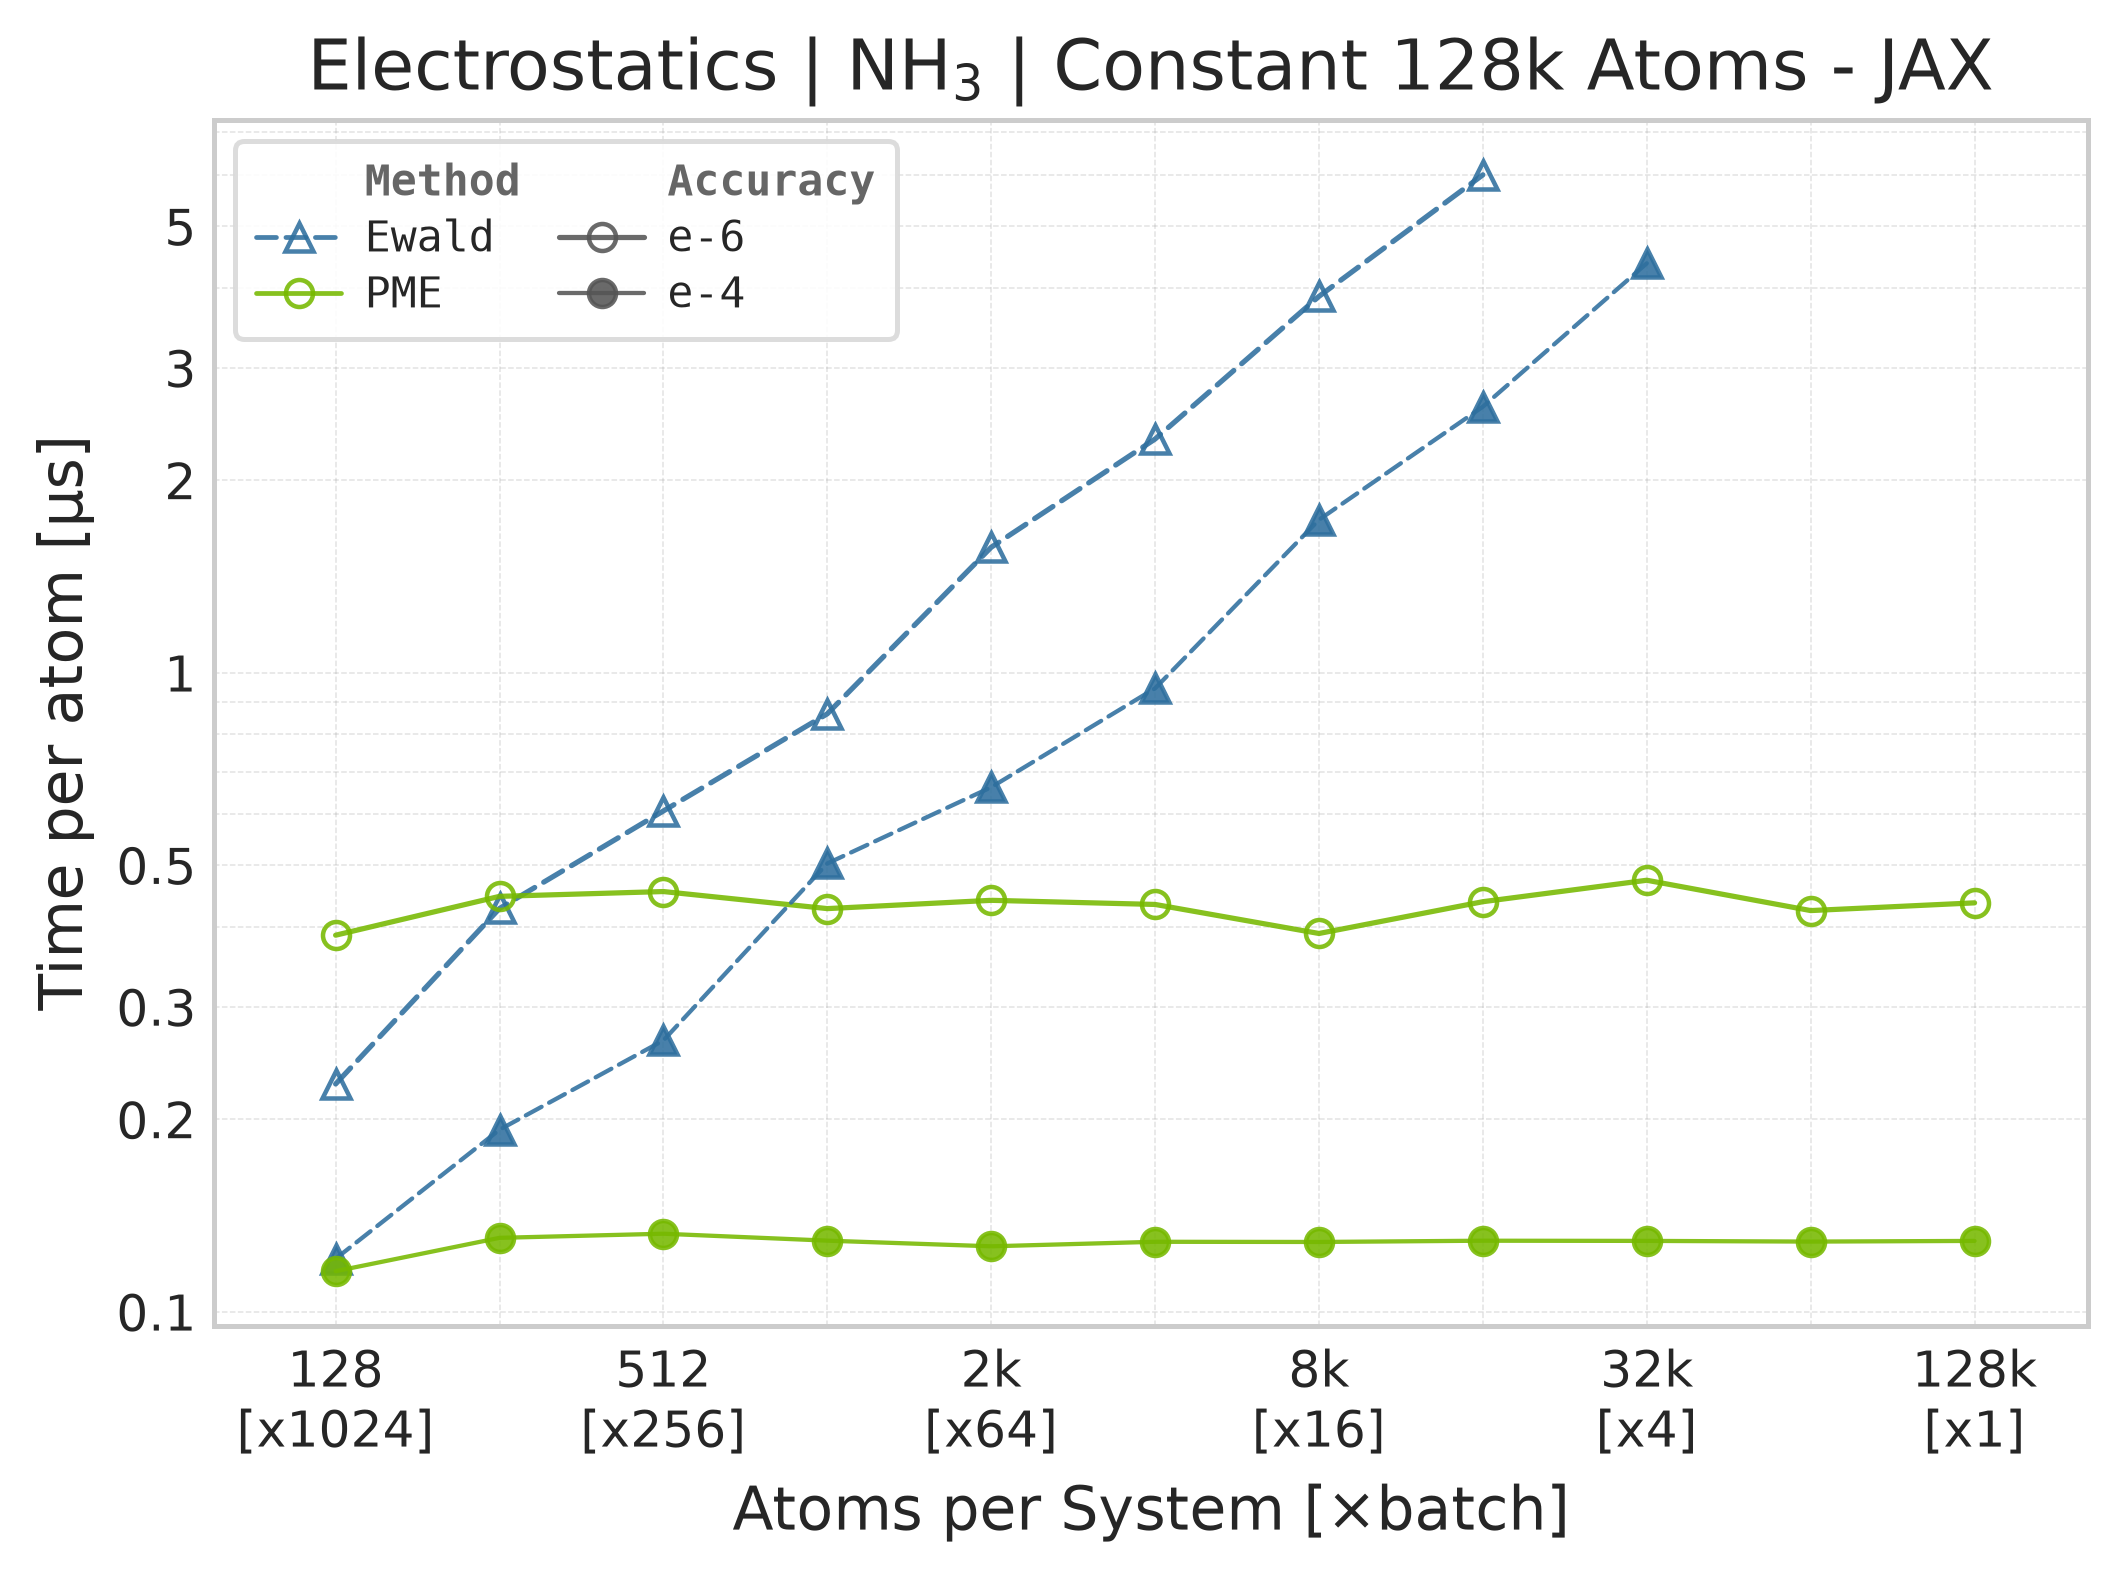
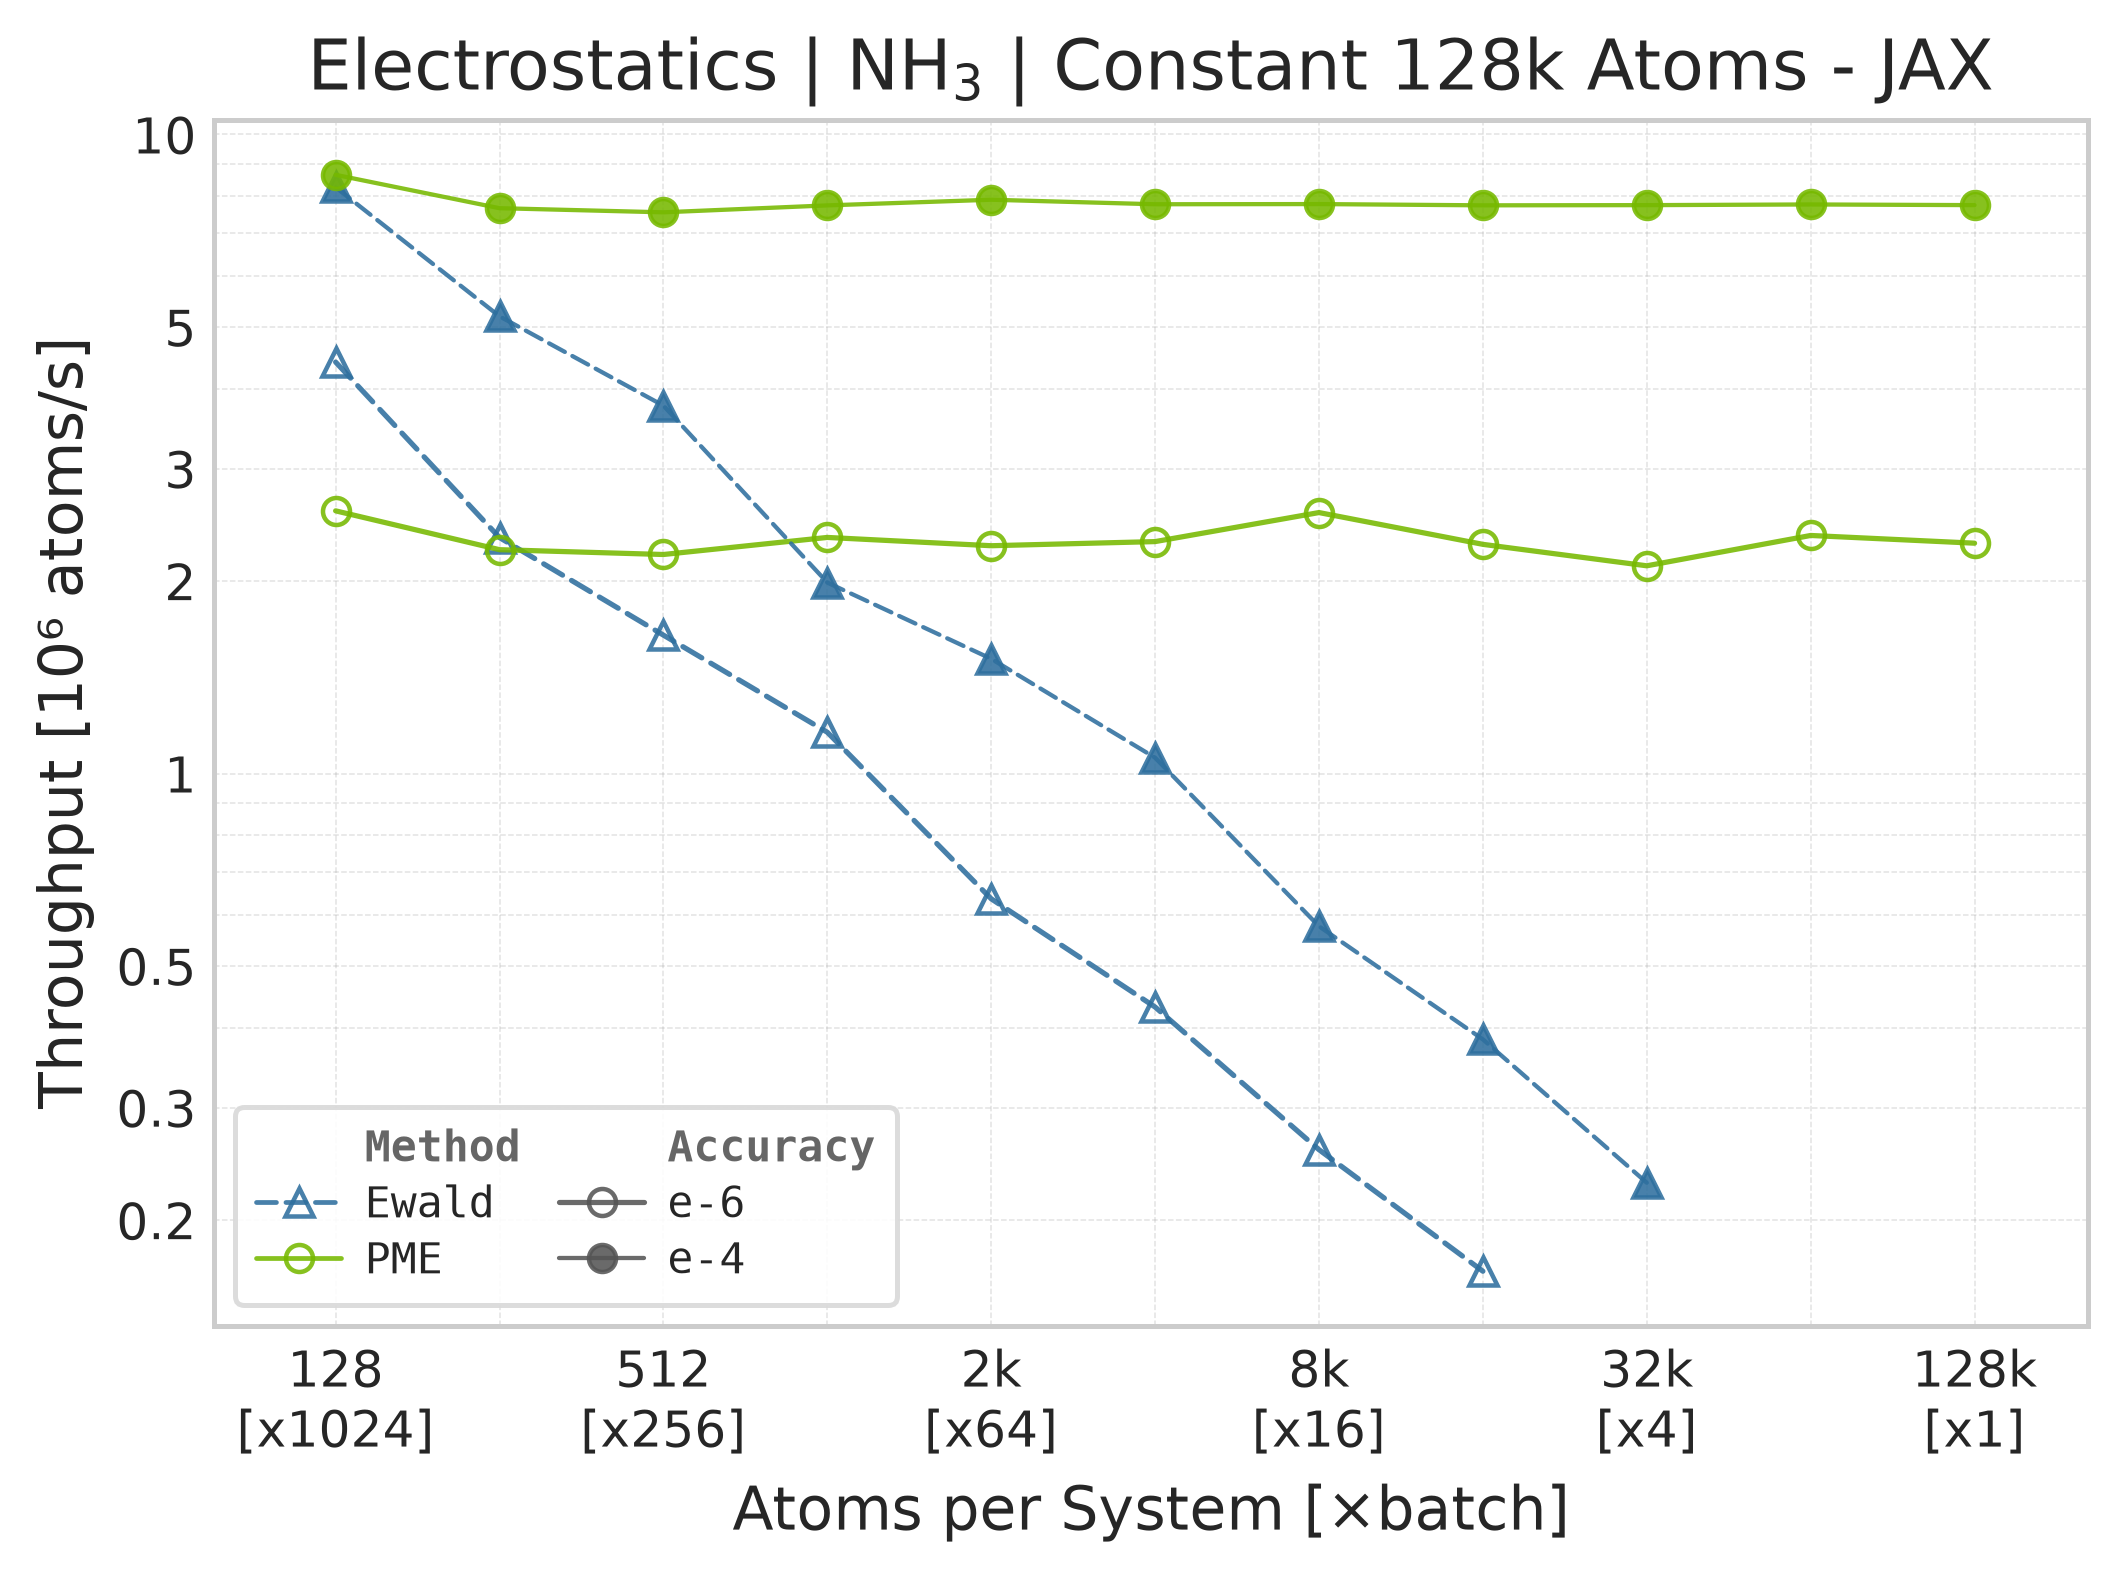
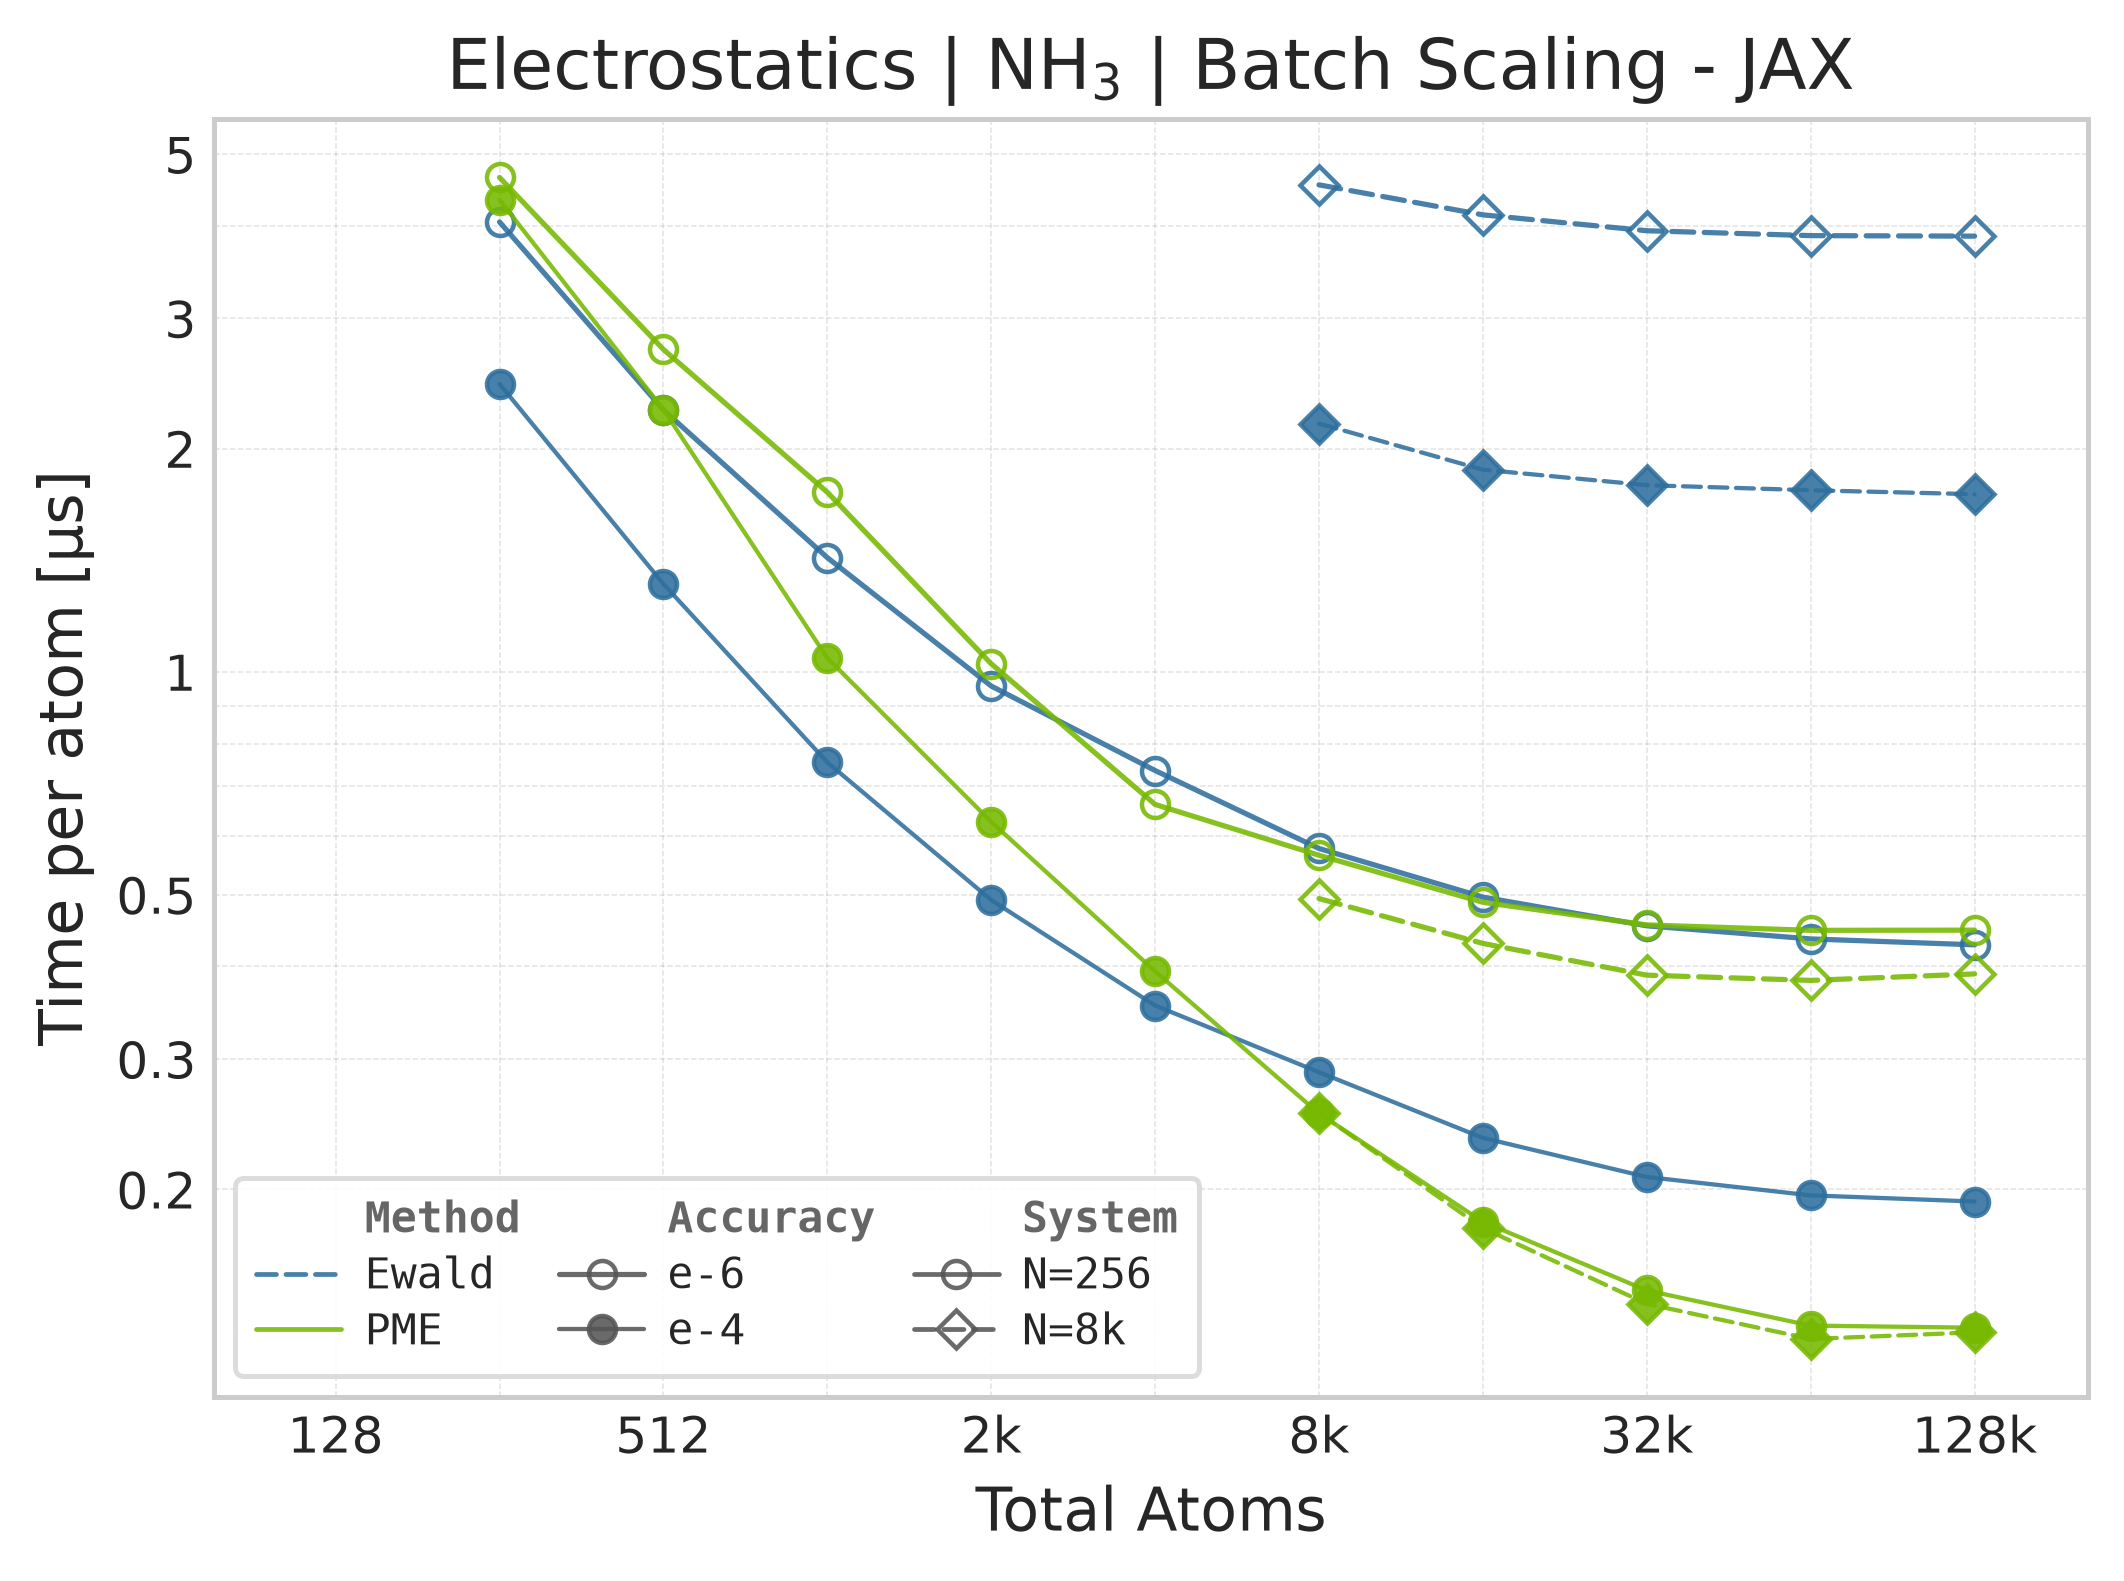
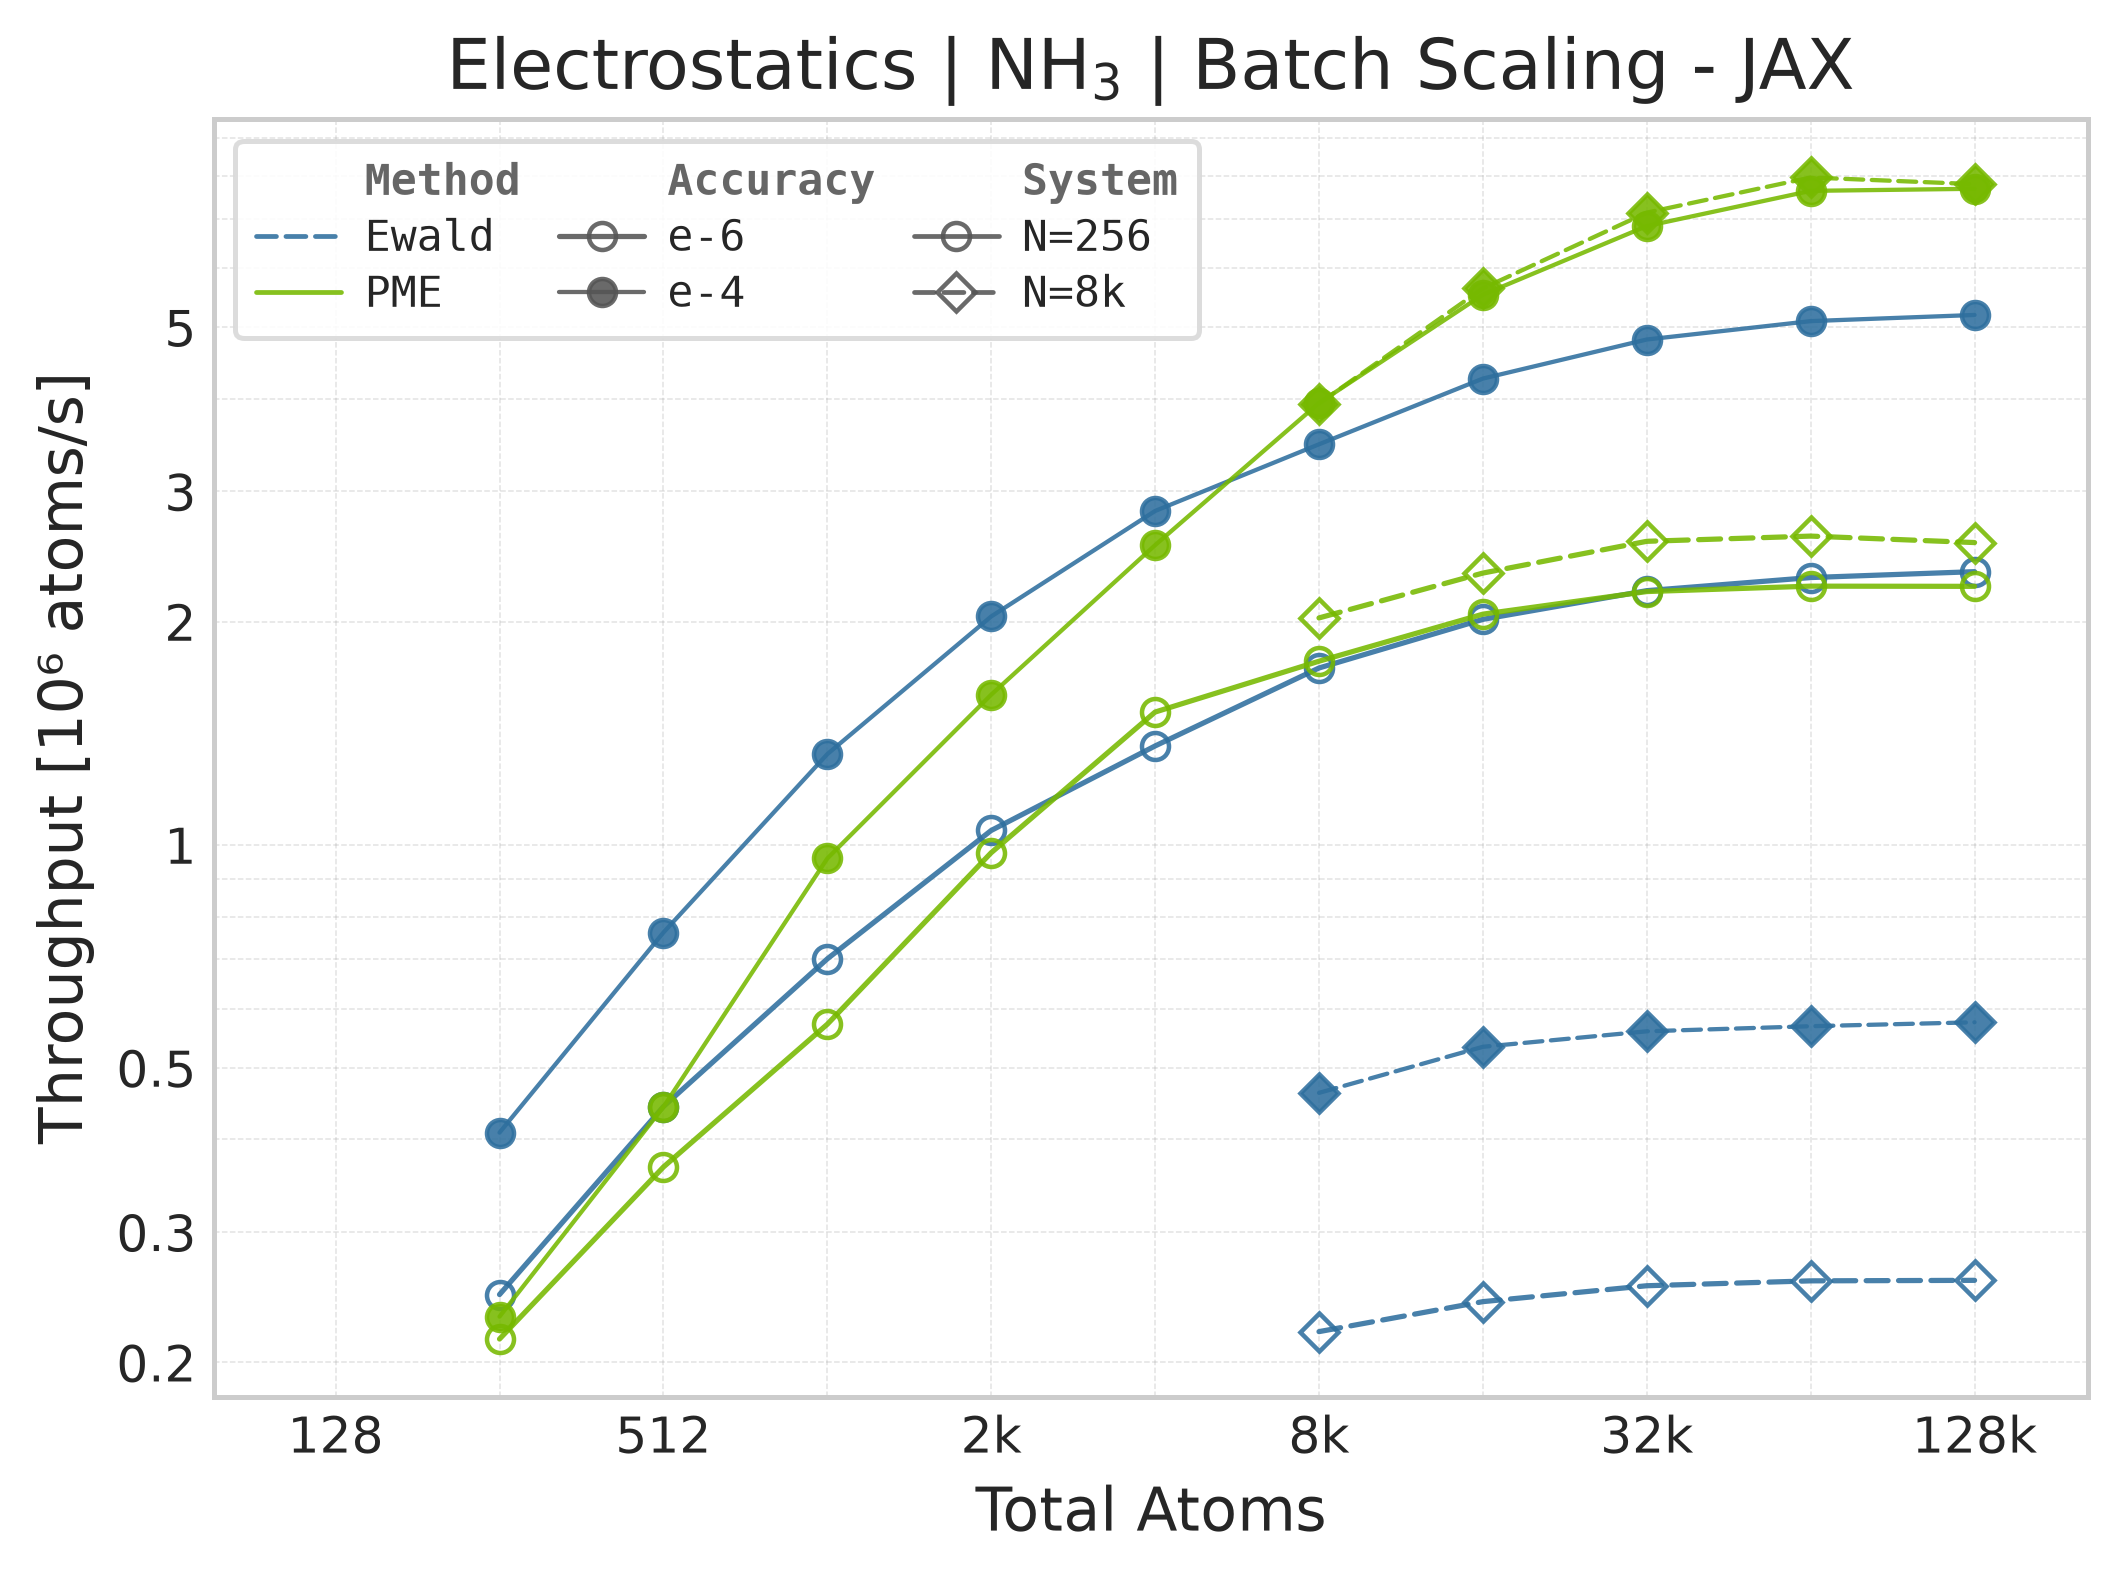
Note
JAX memory plots are omitted. The suite does not measure JAX memory: XLA’s allocator pool and buffer reuse make per-call allocation deltas unreliable. The Torch panels report the Torch allocator only; they are not a proxy for JAX memory because the framework wrappers, buffer lifetimes, and allocators differ.
These comparison plots use matched successful Torch and JAX points for PME and
Ewald. Each timed call includes the public energy API plus the reverse pass for
both forces and charge gradients. CSV metadata records
derivative_contract=energy_autograd and
workload=energy_forces_charge_gradients; compute_forces and
compute_charge_gradients are both True. There is no separate
energy-plus-forces row.
PME rows record pme_cache_mode=k_squared_only or
shared_cell_k_squared for repeated cells. Both backends precompute fixed-cell
volume, inverse-cell, squared reciprocal lengths, and spline moduli outside the
timed region. System construction, parameter selection, neighbor-list setup,
and fixed-cell metadata preparation are excluded from per-call timings.
The workload and configured accuracy are aligned, but the timing harnesses are not identical: Torch uses CUDA events around the high-level call, while JAX uses wall-clock timing around a JIT-compiled call and synchronizes its result. Use these panels for steady-state backend comparison, not as evidence that the framework or allocator overheads are equivalent.
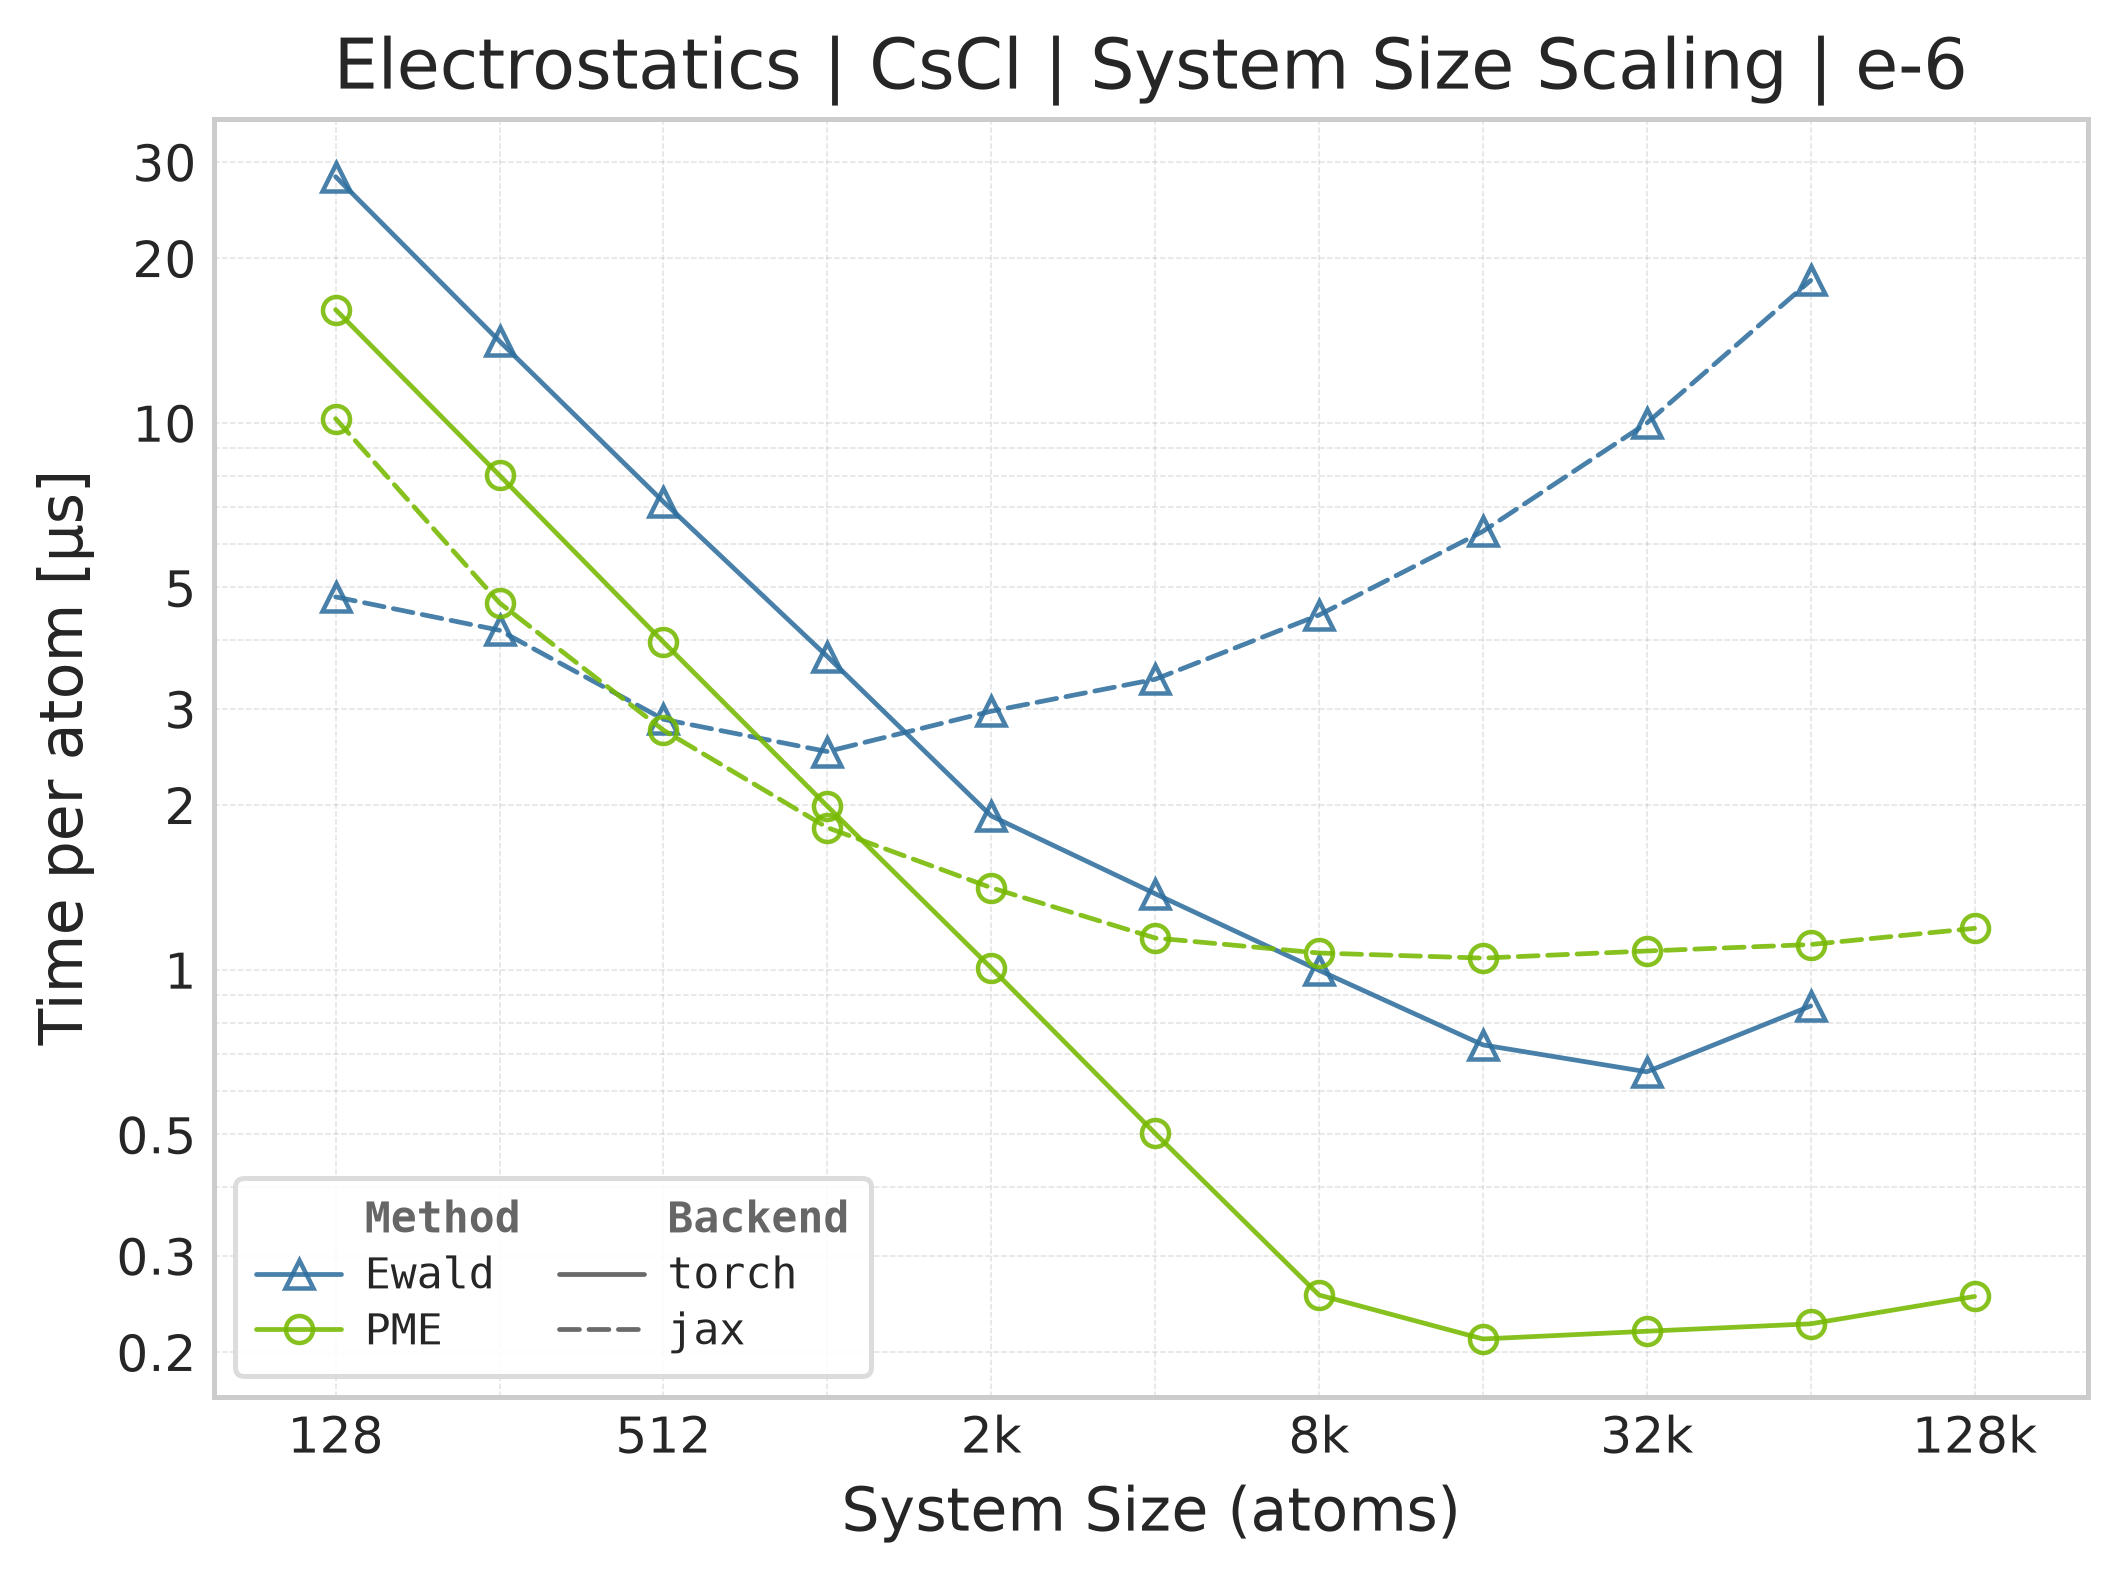
Torch vs. JAX execution time comparison (CsCl).#
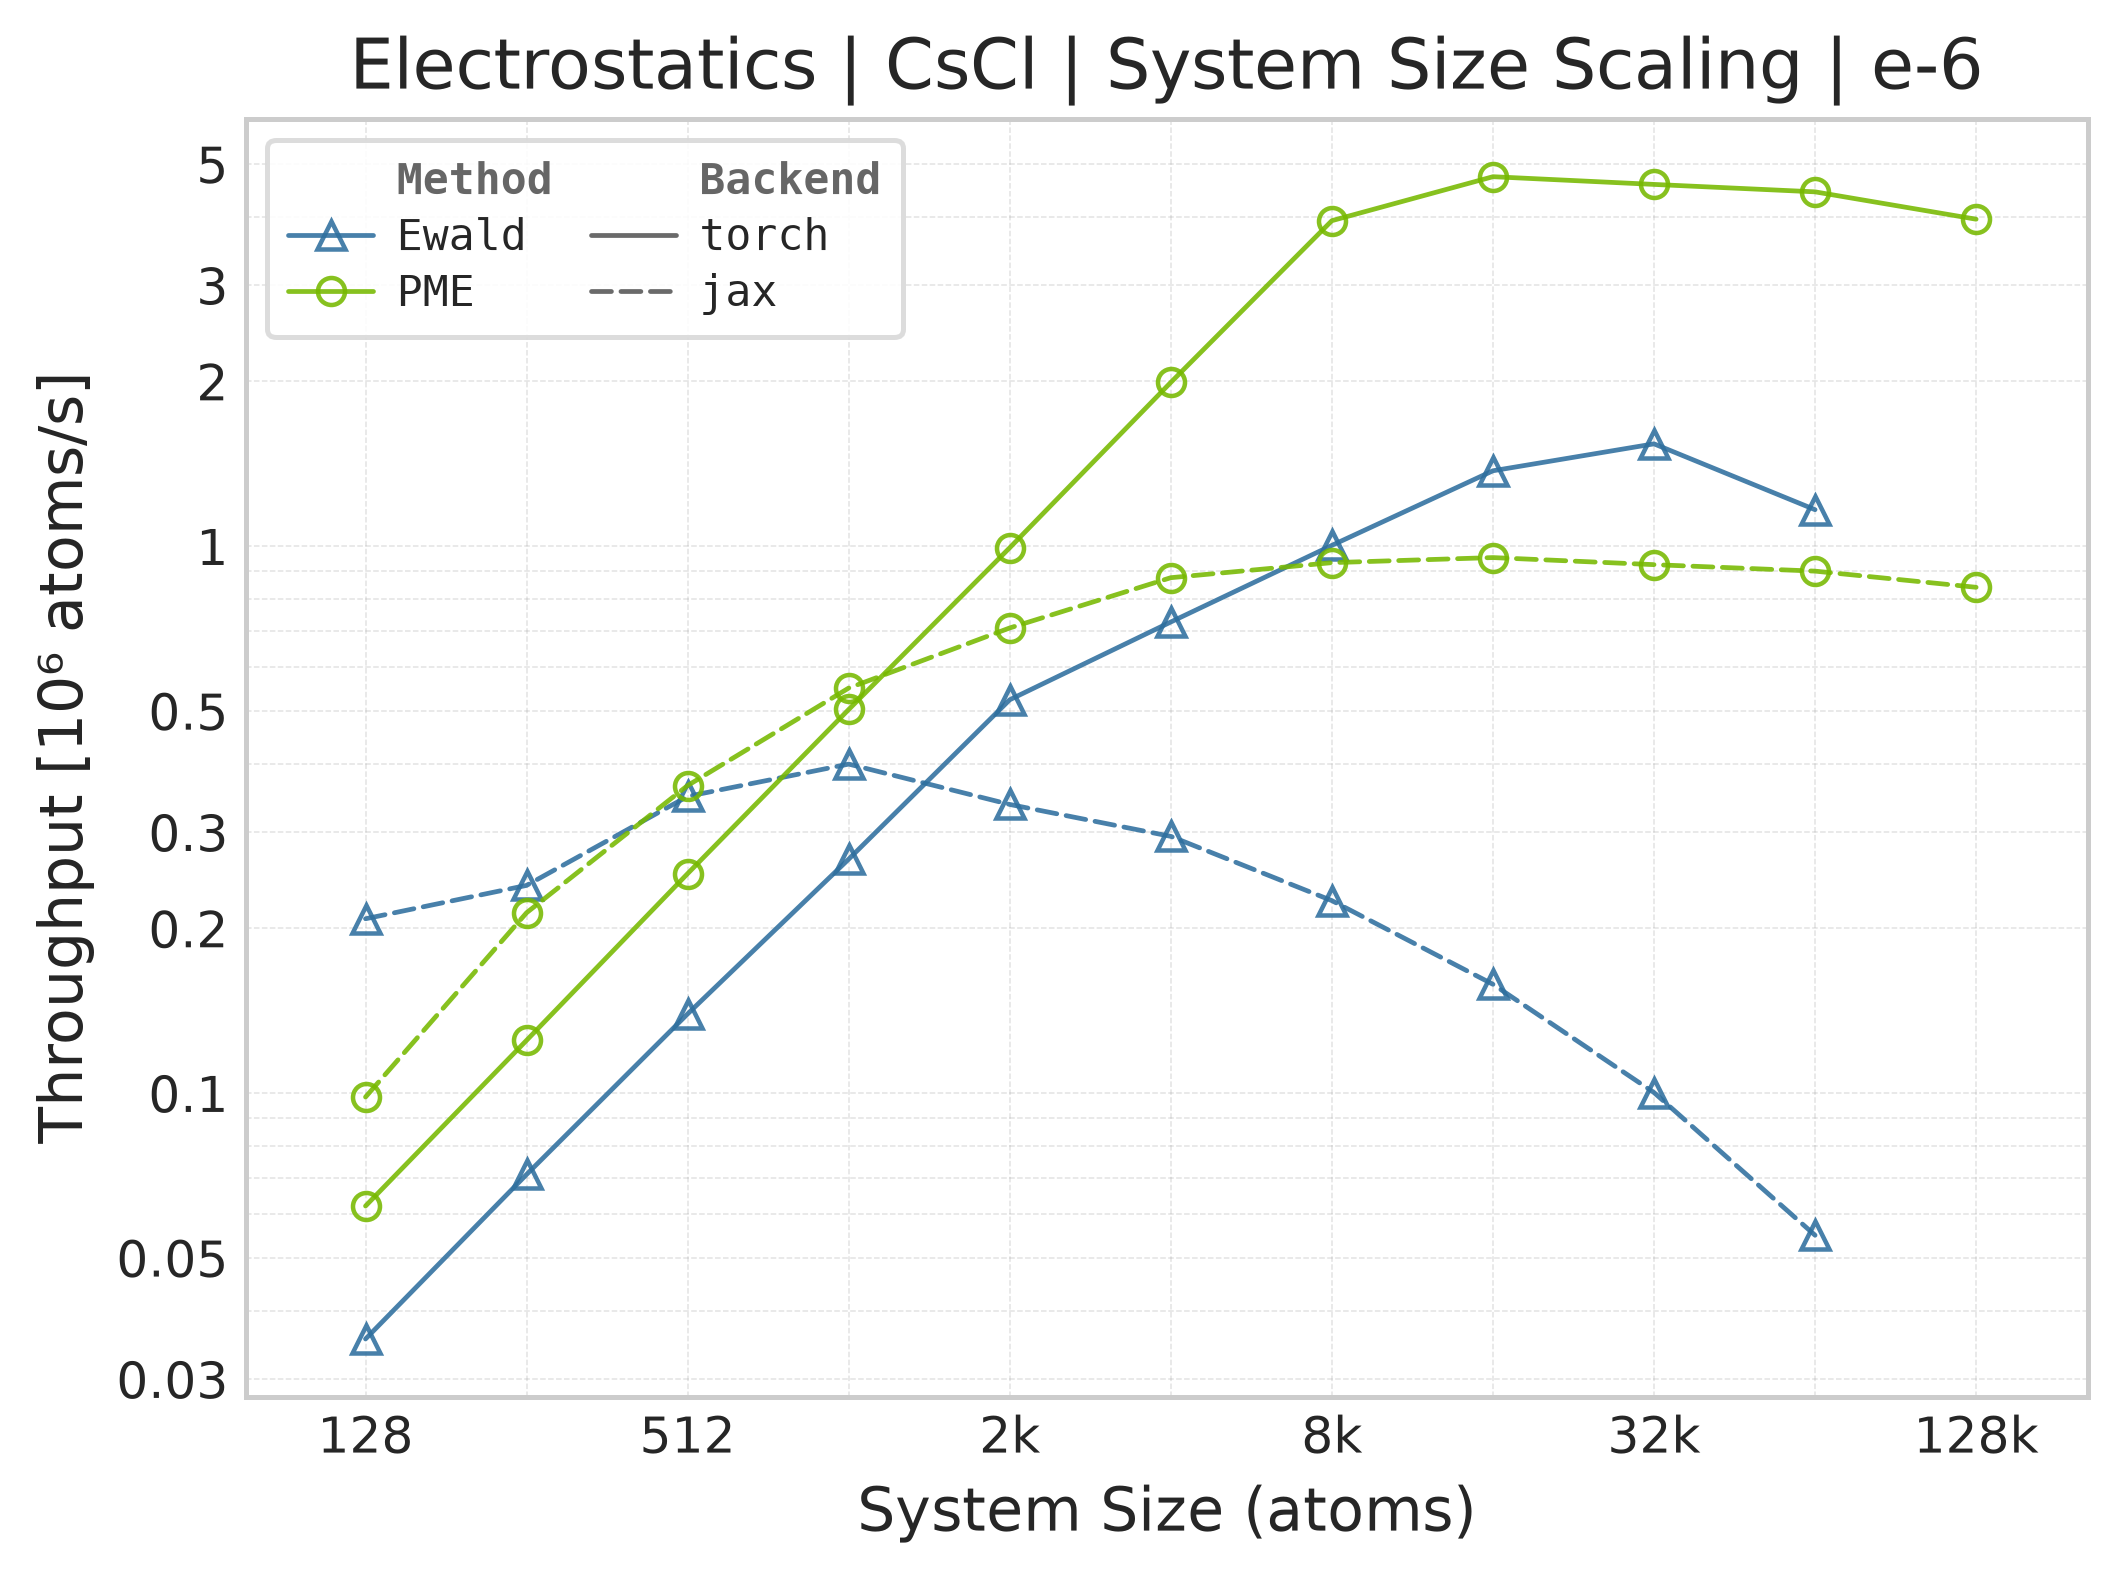
Torch vs. JAX throughput comparison.#
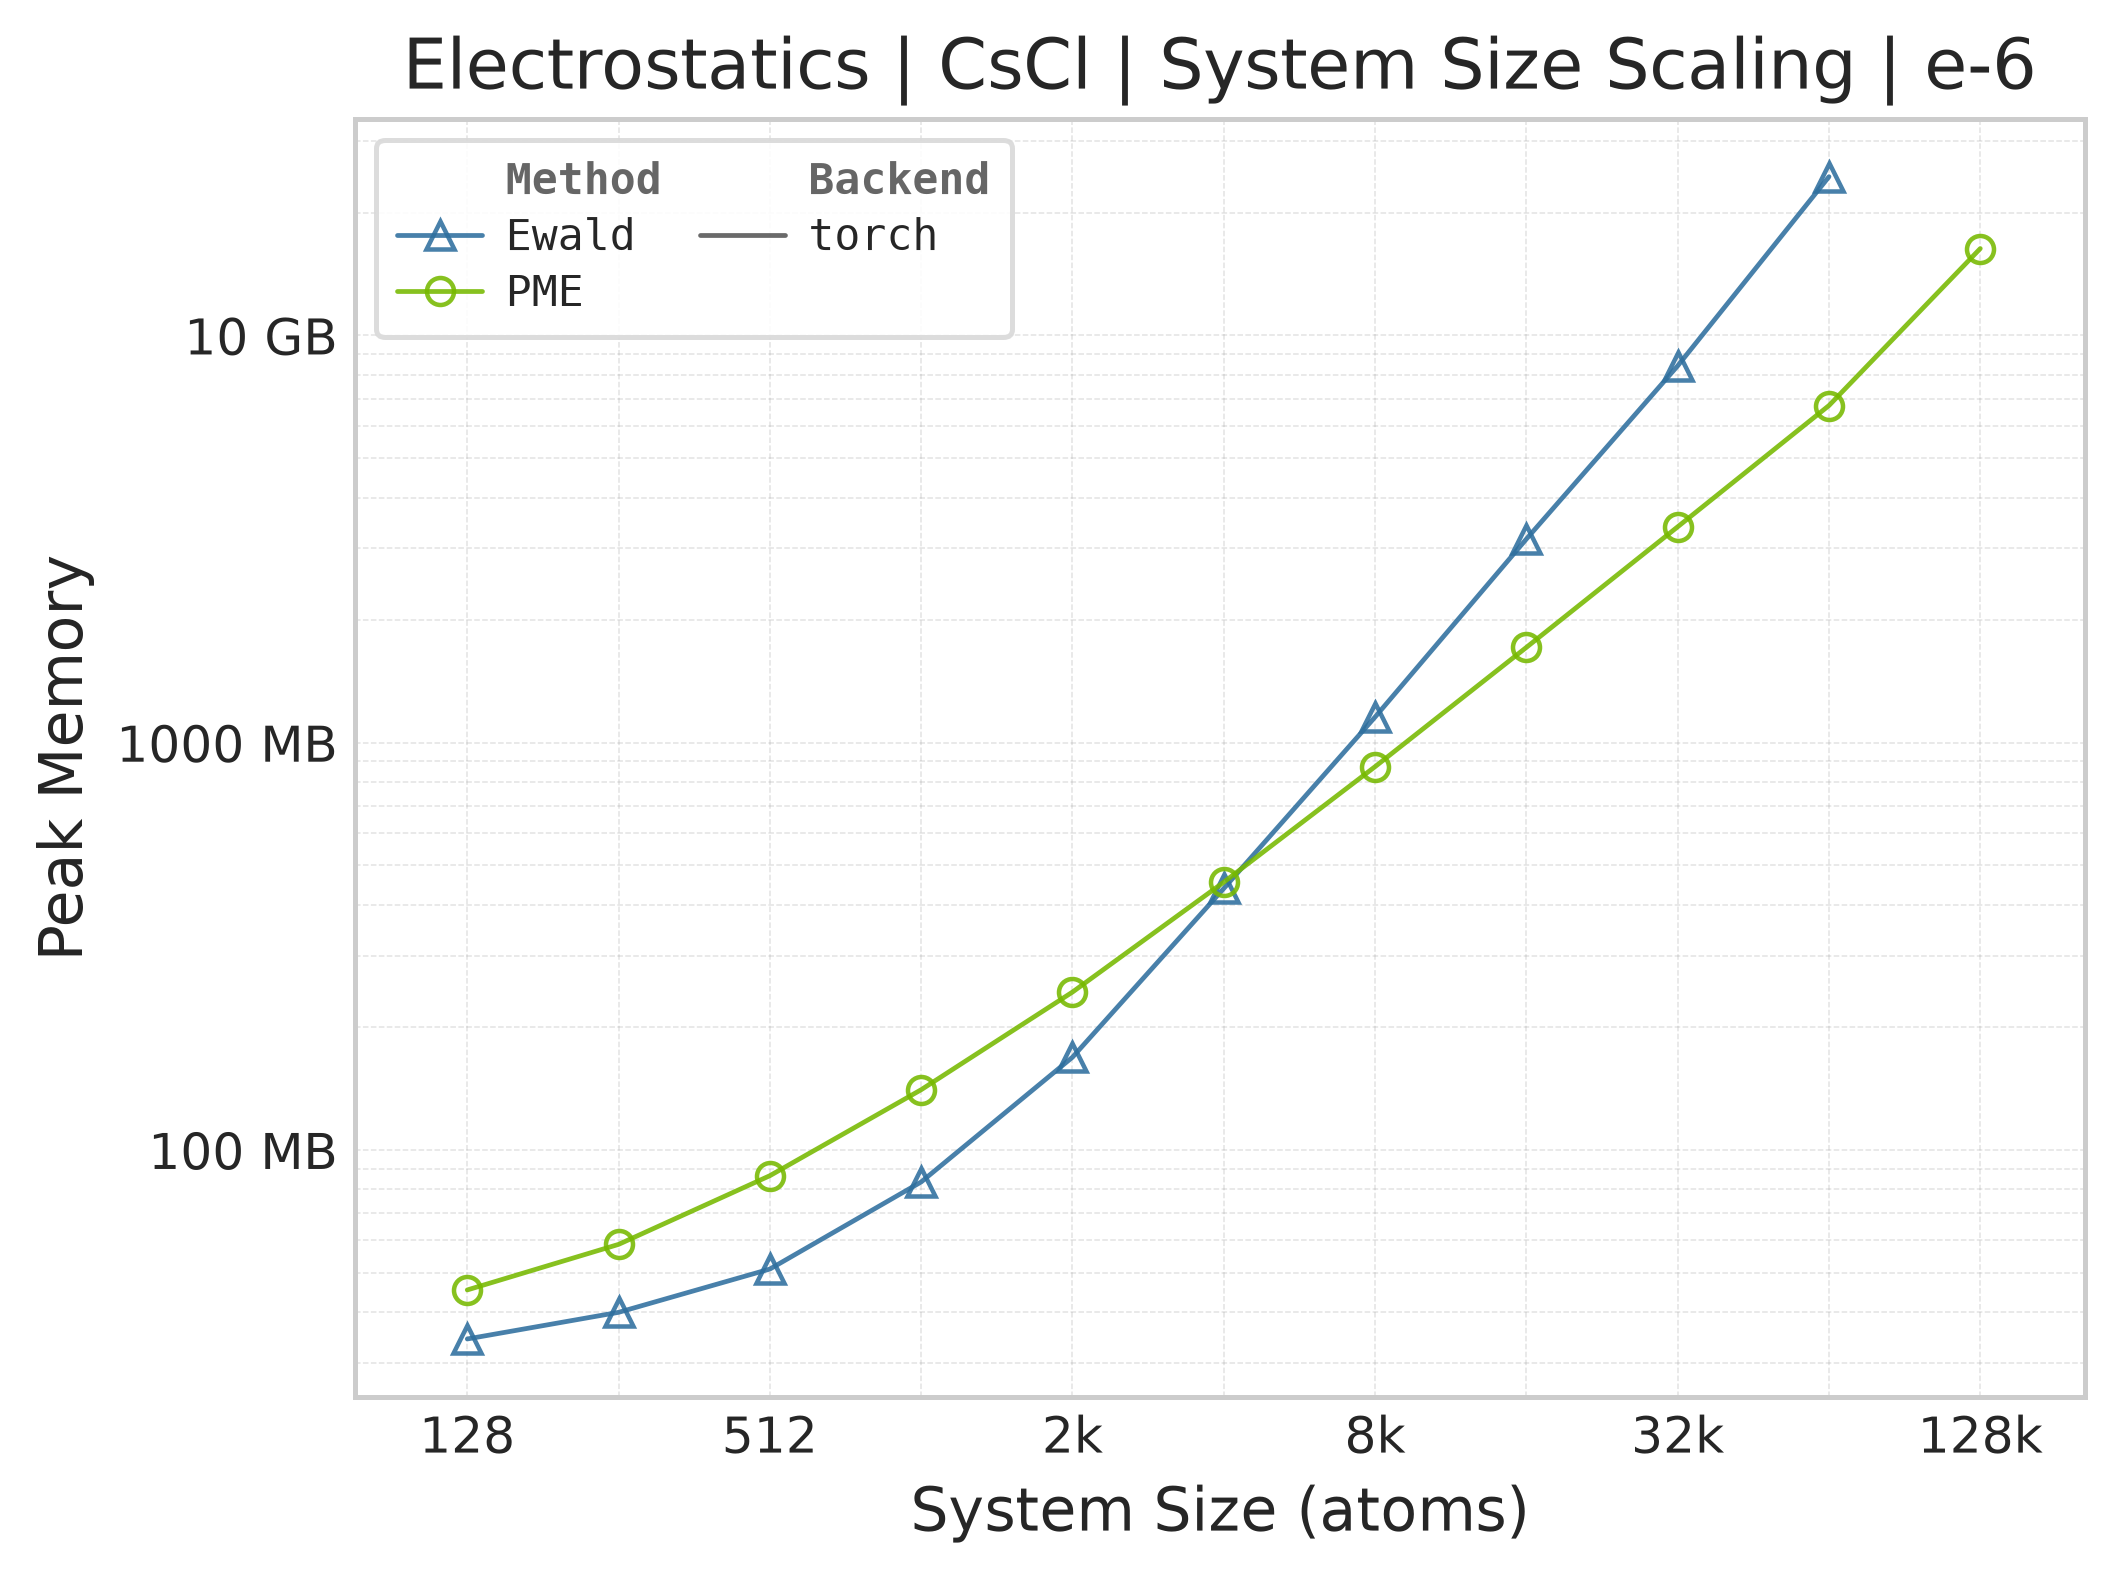
Memory vs. system size (Torch only — JAX memory not measured).#
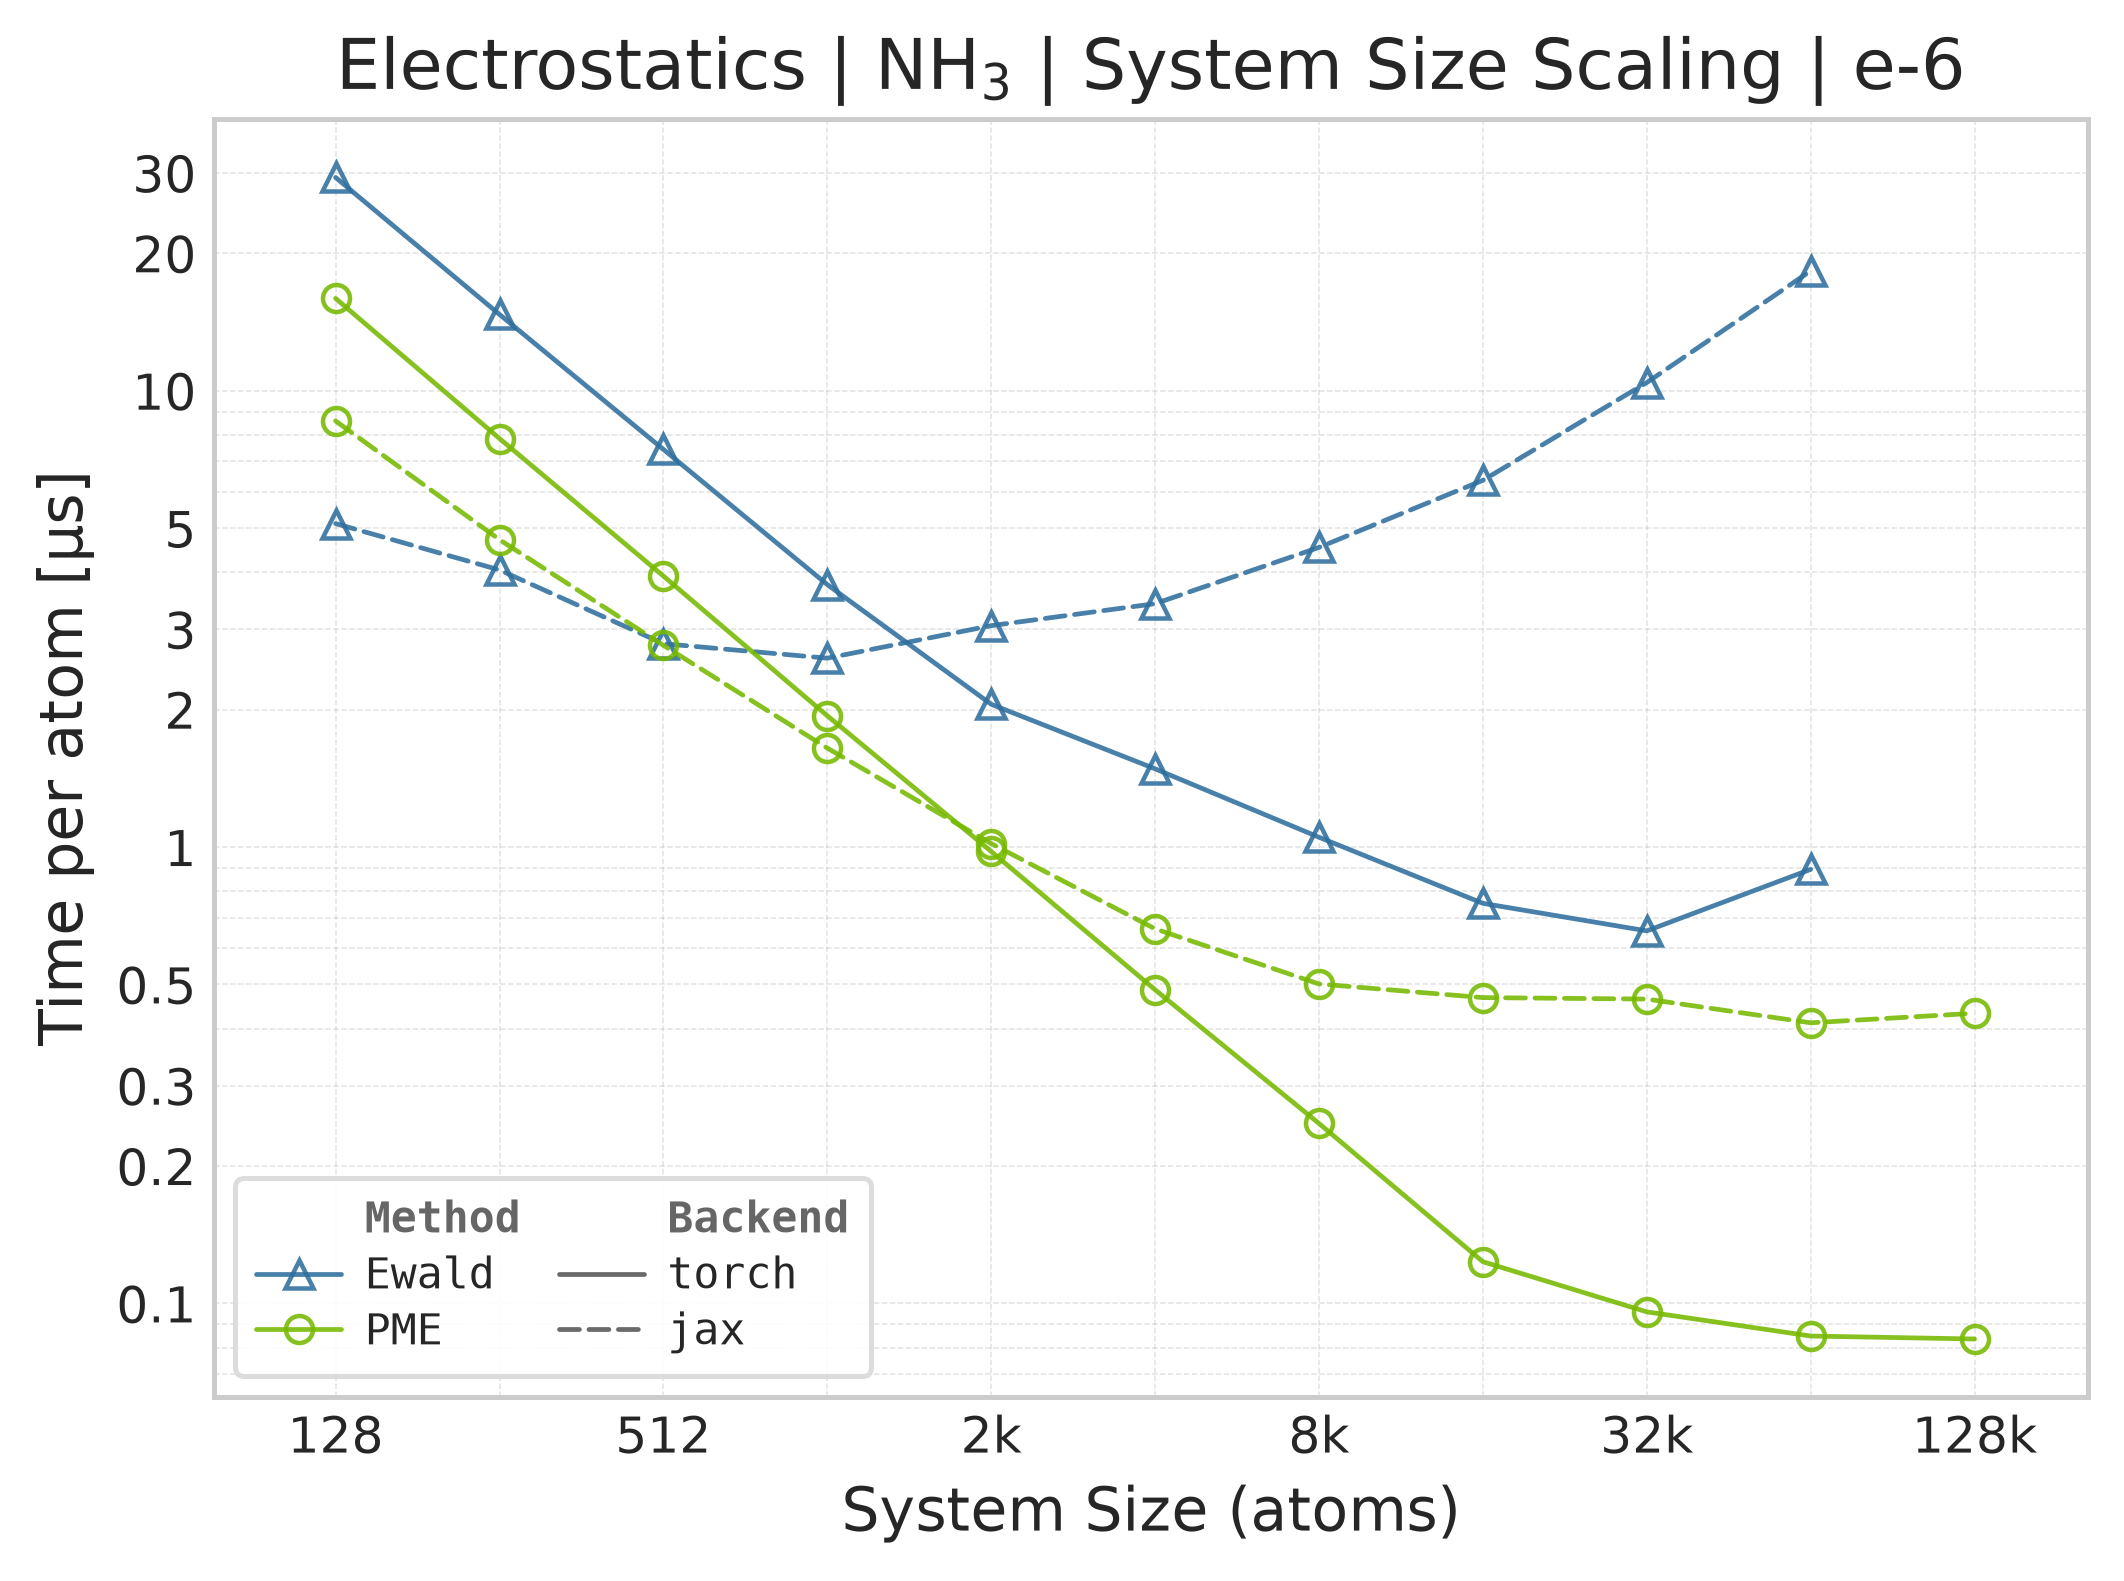
Torch vs. JAX execution time comparison (NH₃).#
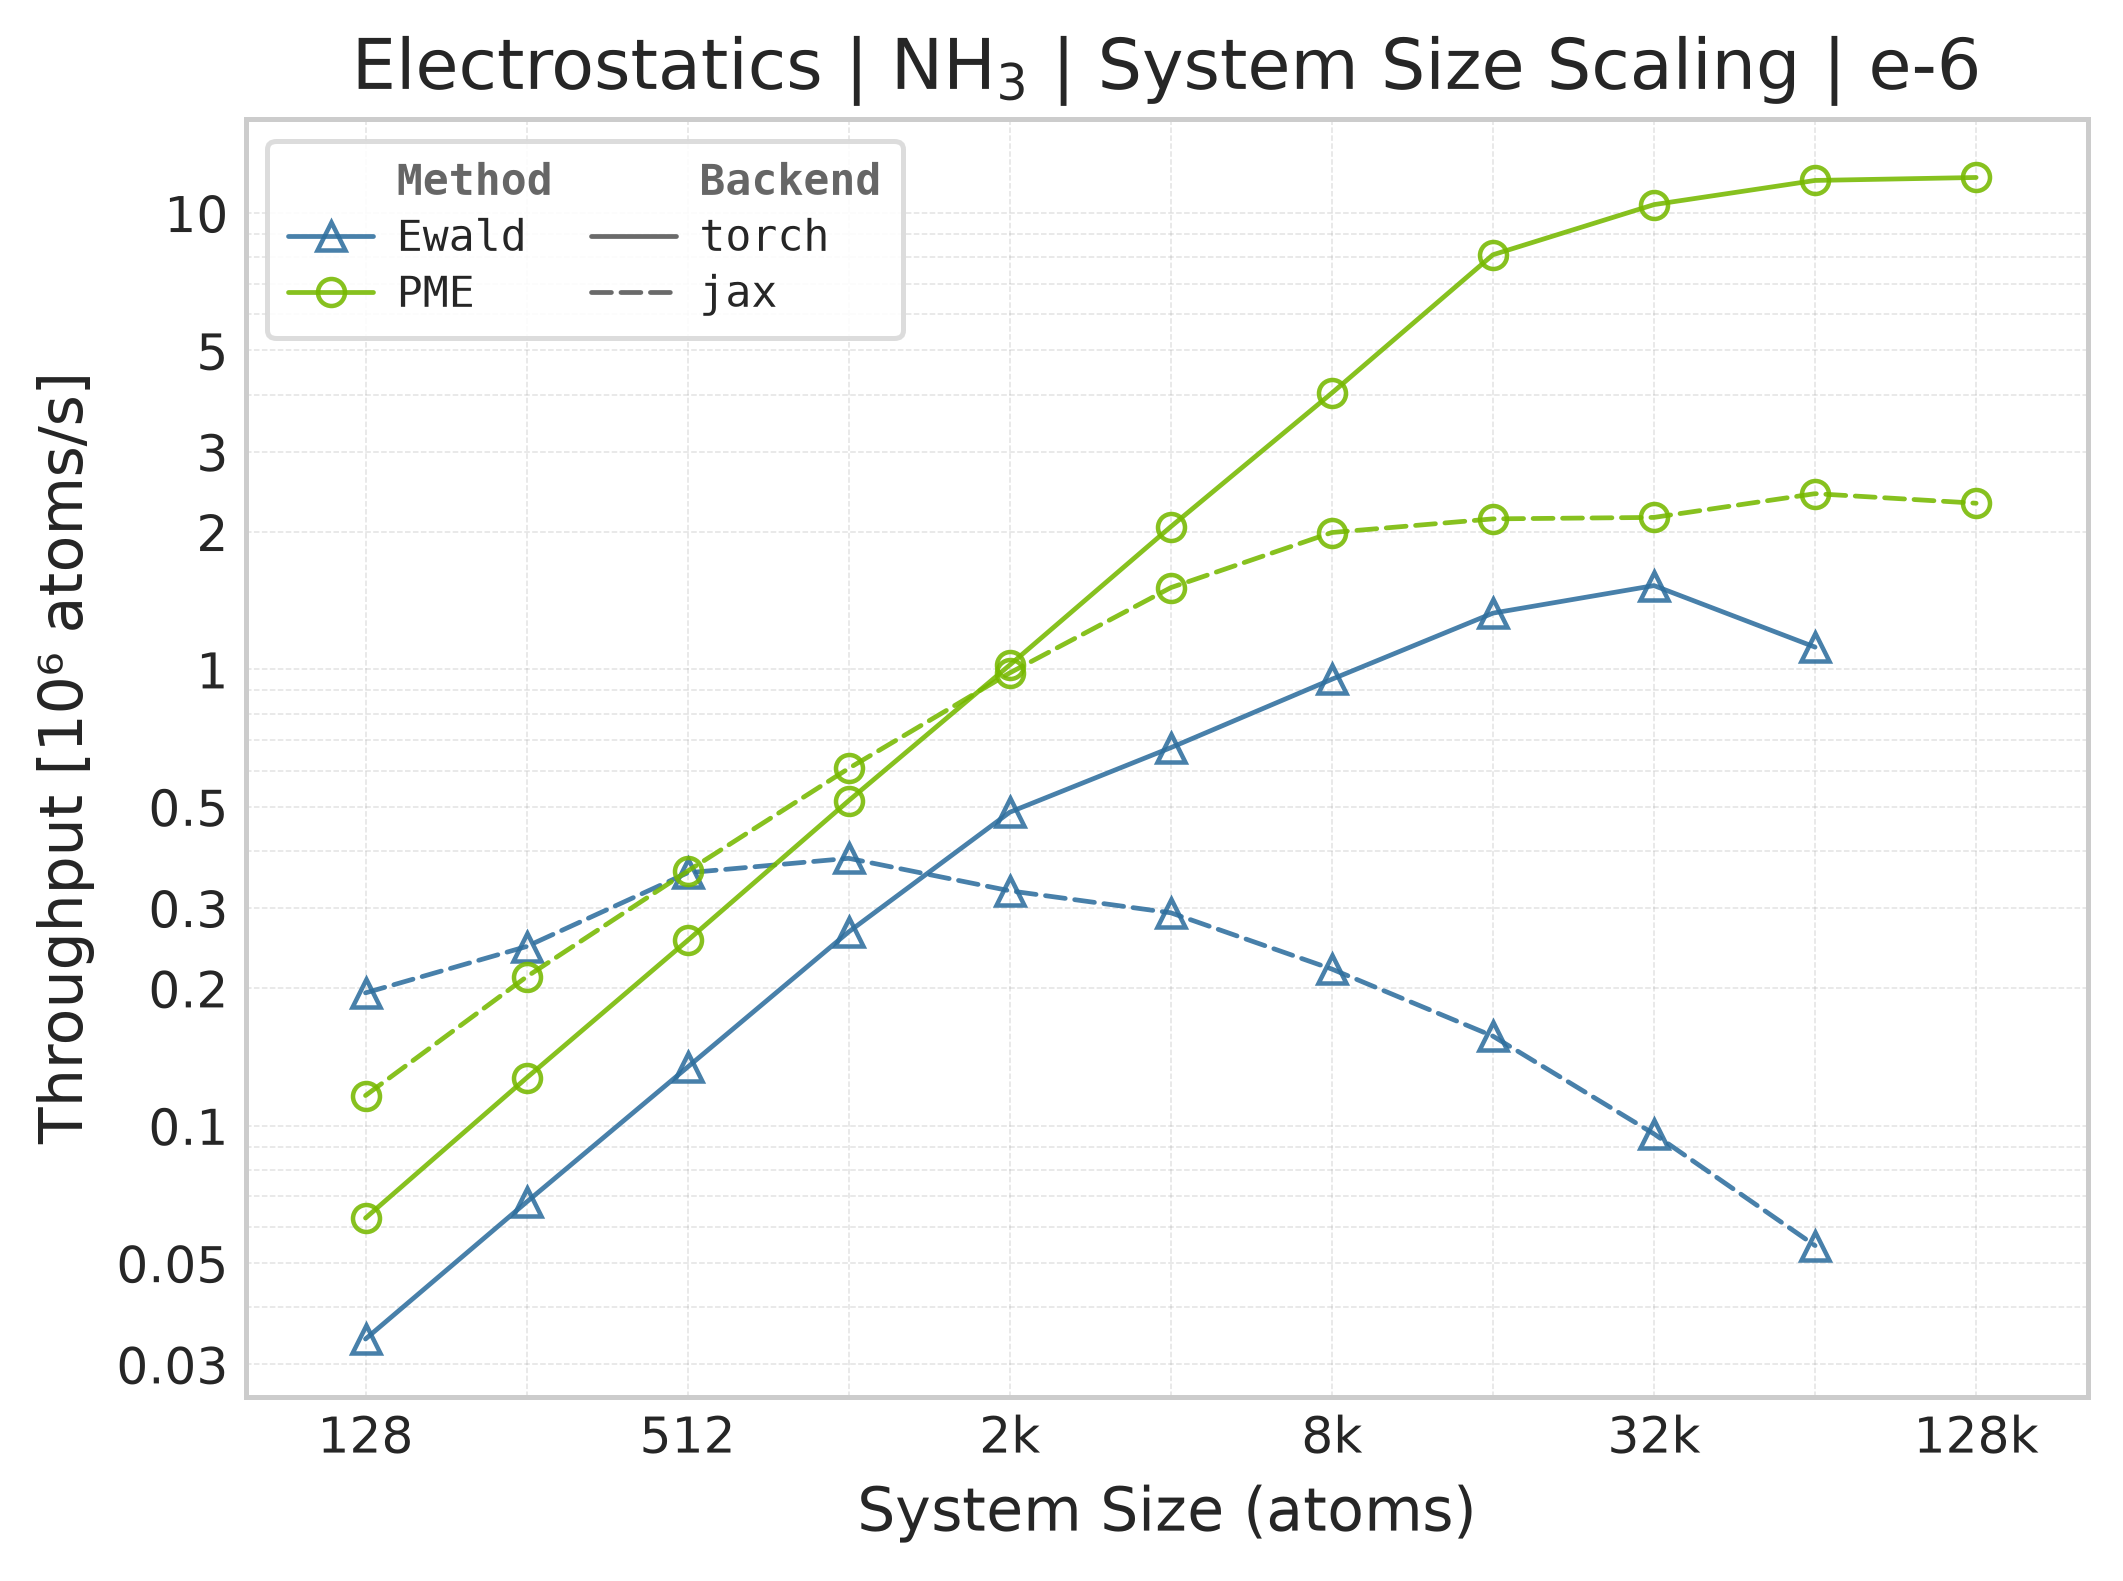
Torch vs. JAX throughput comparison (NH₃).#
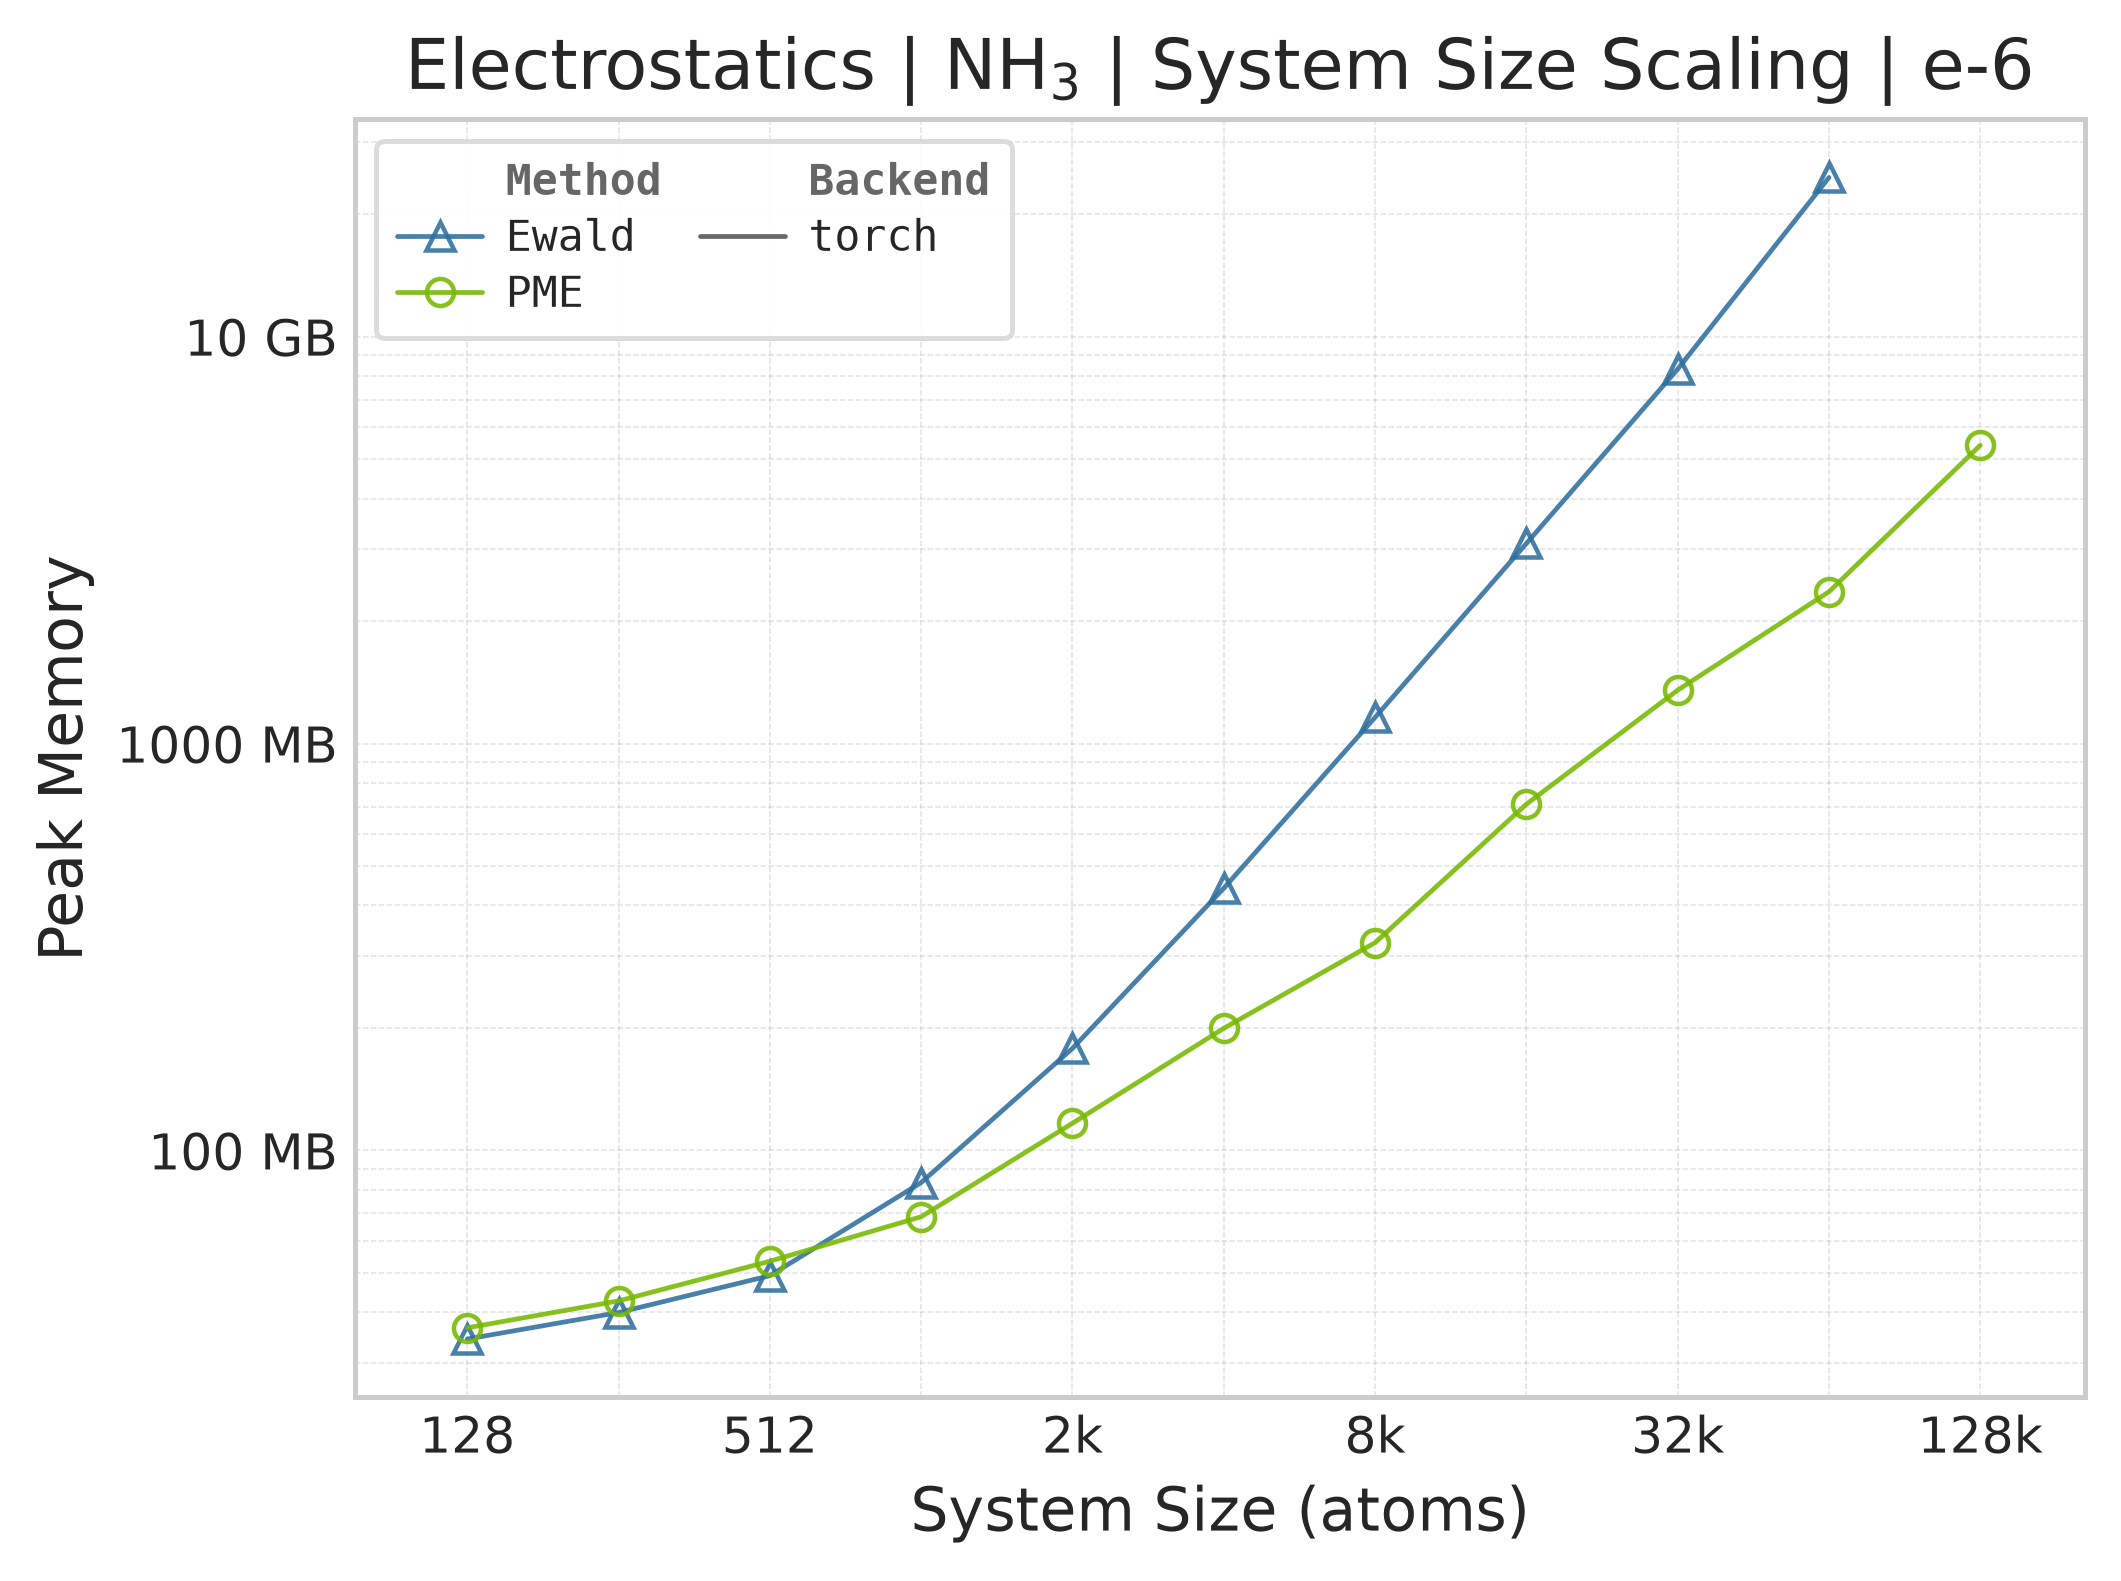
Memory vs. system size (NH₃; Torch only — JAX memory not measured).#
Benchmark Configuration#
Parameter |
Value |
|---|---|
Accuracies |
\(10^{-4}\) / \(10^{-6}\) |
Methods |
PME, Ewald summation |
System Type |
CsCl supercells (programmatic), NH₃ (PDB) |
Neighbor List |
|
Warmup Iterations |
3 |
Timing Iterations |
Five groups of 10 calls; arithmetic mean across groups |
Component Profiling |
Disabled for reportable runs |
Precision |
|
CSV rows always report the independently measured full workload in
time_us_per_atom. With --profile-components, the runner additionally fills
time_real_us_per_atom and time_reciprocal_us_per_atom; otherwise those
diagnostic fields are NaN and their timing methods are not_measured.
Ewald/PME Parameters#
PME uses the public parameter estimator before constructing the neighbor list.
The benchmark configuration caps the real-space cutoff at 9 Å and fixes the
B-spline order at 5. Each case resolves its alpha and mesh from the cell and
requested accuracy. Torch and JAX share the accuracy-based mesh rounding rule:
each axis first rounds upward to the least 2/3/5/7-smooth dimension that covers
the spline support. The selector then tries to snap to the grid: it prefers
power-of-two dimensions when the complete mesh adds at most 25% more points,
otherwise tries smooth dimensions divisible by four within the same budget,
then keeps the smallest smooth mesh. Public sizing APIs expose
fft_padding_fraction=0.25; 0 keeps the smallest smooth mesh. This setup uses
integer arithmetic and requires no runtime calibration or FFT planning.
CSV rows record the resolved parameters, input content hashes, source, and timing settings. Torch allocator peaks are measured separately. Direct Ewald retains its independent accuracy-based estimator.
Parameter |
Description |
|---|---|
|
Ewald splitting parameter |
|
Reciprocal-space cutoff for Ewald (auto-estimated) |
|
Estimated PME cutoff capped by configuration, or estimated direct-Ewald cutoff |
|
PME mesh dimensions selected from the accuracy-based sizing formula and FFT snap preferences |
|
Configured PME B-spline order (5 in the reportable suite) |
Running Your Own Benchmarks#
Run from the repository root. The reportable benchmark runner is
benchmark_electrostatics_suite.py with benchmark_config.yaml. The YAML
already enables PME and Ewald; pass --methods pme or --methods ewald
to benchmark only one.
Torch Backend (default)#
RESULT_DIR="$BENCHMARK_SCRATCH/results/manual-el-run"
python -m benchmarks.interactions.electrostatics.benchmark_electrostatics_suite \
    --config benchmarks/interactions/electrostatics/benchmark_config.yaml \
    --backend torch \
    --output-dir "$RESULT_DIR"
JAX Backend#
RESULT_DIR="$BENCHMARK_SCRATCH/results/manual-el-run"
python -m benchmarks.interactions.electrostatics.benchmark_electrostatics_suite \
    --config benchmarks/interactions/electrostatics/benchmark_config.yaml \
    --backend jax \
    --output-dir "$RESULT_DIR"
Extended / Optional Runner#
The benchmark_electrostatics.py extended runner is separate from the
reportable suite. It covers slab-corrected Ewald/PME, DSF, optional reference
backends, and multipoles, and writes a different GPU/dtype-specific CSV schema. It is not
invoked by benchmarks.benchmark_suite or by the reportable runner, and
its outputs are not inputs to the el-*.csv plots on this page.
This runner uses optional helpers imported through benchmarks.utils and
benchmarks.systems. Install its additional dependencies, including
pymatgen, rdkit, and loguru, with make docs-install-benchmarks
or directly from benchmarks/benchmark-requires.txt.
The shipped optional configurations are distinct protocols (the shared
benchmark_config_ prefix is omitted in the table):
Configuration |
Backends and methods |
Warmups / timings |
Precision |
Default work |
|---|---|---|---|---|
|
Toolkit-Ops Torch/JAX and optional |
5 / 10 |
|
Full, real, and reciprocal components; forces and virial; 12 Å real-space cutoff |
|
Torch multipole Ewald and PME, |
3 / 10 |
|
Compiled reciprocal component; forces only |
These settings describe the optional CSVs only. They must not be compared as if they were rows from the reportable energy/forces/charge-gradient protocol.
Use benchmark_config_extended.yaml for point-charge, slab, and DSF runs:
# Slab-corrected Ewald and PME (Torch + JAX when both are available)
python -m benchmarks.interactions.electrostatics.benchmark_electrostatics \
    --config benchmarks/interactions/electrostatics/benchmark_config_extended.yaml \
    --backend both --method ewald_slab
python -m benchmarks.interactions.electrostatics.benchmark_electrostatics \
    --config benchmarks/interactions/electrostatics/benchmark_config_extended.yaml \
    --backend both --method pme_slab

# DSF (nvalchemiops Torch + the pure-Torch reference)
python -m benchmarks.interactions.electrostatics.benchmark_electrostatics \
    --config benchmarks/interactions/electrostatics/benchmark_config_extended.yaml \
    --backend both --method dsf --neighbor-format both
Use the dedicated config for the Torch-only multipole sweep:
python -m benchmarks.interactions.electrostatics.benchmark_electrostatics \
    --config benchmarks/interactions/electrostatics/benchmark_config_multipole.yaml \
    --backend torch --l-max 1
Reportable Options#
See --help for the full list; the flags relevant to electrostatics
runs are:
--backend {torch,jax}
: Computational backend (default: whatever config['runtime']['backend']
is set to, else torch).
--methods {pme,ewald} [{pme,ewald} ...]
: Restrict to a subset of methods. Default: run every method marked
enabled: true in the YAML (PME + Ewald ship enabled).
--accuracies ACC [ACC ...]
: Override the list of relative error tolerances to sweep. Default:
values from config['accuracies'] (ships as [1e-4, 1e-6]).
--profile-components
: Also time real- and reciprocal-space differentiated components. This is a
diagnostic mode; it is disabled in the reportable configuration.
--system, --mode, --timing-runs, --warmup-runs, --output-dir
: Shared flags defined in benchmarks/config.py; see --help for details.