Shared Memory and Synchronization#
Every thread in a CUDA thread block has access to a small, fast scratch-pad called shared memory. It sits on-chip next to the SM’s execution units — roughly 100× faster than global memory and roughly 10× faster than the L1 cache. The catch is size: typically 48–228 KB per SM depending on architecture, shared across all blocks running on that SM.
cuda-oxide exposes shared memory through SharedArray and
DynamicSharedArray, both designed to feel like Rust arrays while compiling
to PTX address space 3. This chapter covers how to use them, when to
synchronize, and the tiling pattern that turns naive kernels into fast ones.
See also
CUDA Programming Guide — Shared Memory for hardware details on bank structure, broadcast rules, and capacity per architecture.
Why shared memory matters#
Consider the naive GEMM from the Async MLP Pipeline project. Each thread computes one output element by reading an entire row of A and an entire column of B from global memory. For a 64×64 matrix, that is 128 global loads per thread, and every other thread in the block loads many of the same elements. The hardware dutifully fetches each one from DRAM — or, if you are lucky, the L2 cache.
Shared memory changes the economics. A thread block cooperatively loads a tile of A and a tile of B into shared memory, synchronizes, and then every thread reads from the tile. Each global load is amortized across all threads that reuse the element. For a 16×16 tile, that is a 16× reduction in global memory traffic.
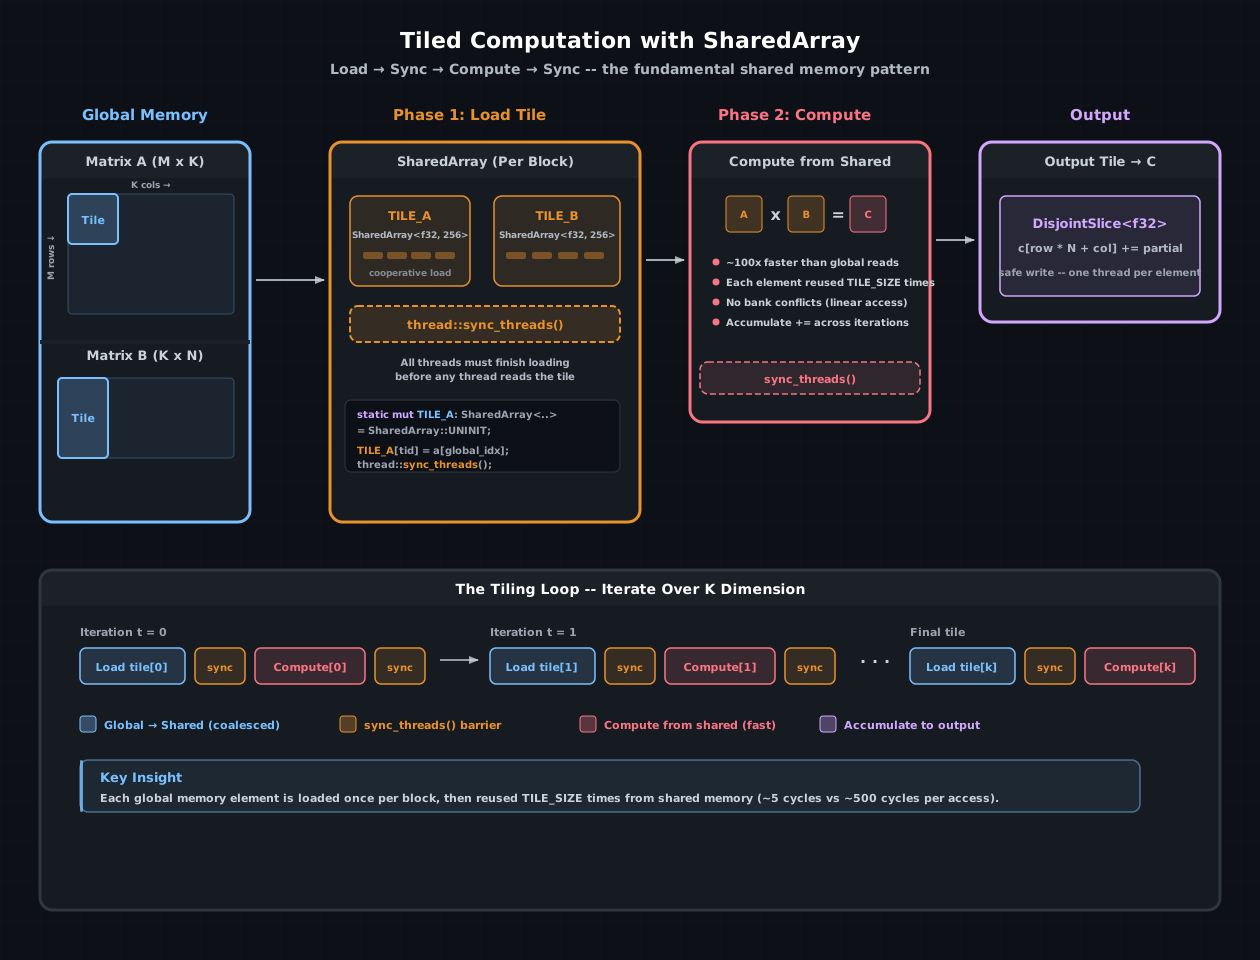
The tiled computation pattern. Threads cooperatively load tiles of A and B
from global memory into SharedArrays, synchronize, compute partial
products from the fast on-chip memory, synchronize again, and repeat for the
next tile along the K dimension.#
SharedArray — static shared memory#
SharedArray<T, N, ALIGN> is a fixed-size array allocated in shared memory
at compile time. You declare it as a static mut inside the kernel:
use cuda_device::thread::Runtime2DIndex;
use cuda_device::{DisjointSlice, SharedArray, kernel, thread};

const TILE: usize = 16;

#[kernel]
pub fn tiled_sgemm(
    m: u32, n: u32, k: u32,
    a: &[f32], b: &[f32],
    mut c: DisjointSlice<f32, Runtime2DIndex>,
) {
    static mut TILE_A: SharedArray<f32, 256> = SharedArray::UNINIT;
    static mut TILE_B: SharedArray<f32, 256> = SharedArray::UNINIT;

    let n_sz = n as usize;
    let row = thread::index_2d_row();
    let col = thread::index_2d_col();
    let tx = thread::threadIdx_x() as usize;
    let ty = thread::threadIdx_y() as usize;

    let mut sum = 0.0f32;
    let mut t = 0u32;

    while t < k / TILE as u32 {
        let tile_offset = t as usize * TILE;

        // Phase 1: cooperative load
        unsafe {
            TILE_A[ty * TILE + tx] = a[row * k as usize + tile_offset + tx];
            TILE_B[ty * TILE + tx] = b[(tile_offset + ty) * n_sz + col];
        }

        // All threads must finish loading before any thread reads
        thread::sync_threads();

        // Phase 2: compute from shared memory
        let mut i = 0usize;
        while i < TILE {
            unsafe {
                sum += TILE_A[ty * TILE + i] * TILE_B[i * TILE + tx];
            }
            i += 1;
        }

        // Must sync before overwriting the tile in the next iteration
        thread::sync_threads();

        t += 1;
    }

    // The row width comes from `c`, bound on the host to this same `n`.
    if let Some(c_idx) = thread::index_2d_runtime(&c) {
        if let Some(c_elem) = c.get_mut(c_idx) {
            *c_elem = sum;
        }
    }
}
Declaration rules#
SharedArray must be declared as static mut inside the kernel function
body. This tells the compiler to allocate it in PTX shared address space
(.shared). The UNINIT constant skips initialization — the contents are
undefined until threads write to them.
Parameter |
Meaning |
|---|---|
|
Element type ( |
|
Number of elements (fixed at compile time) |
|
Byte alignment: 0 (natural) or a power of two; use 128 for TMA destinations |
Tip
SharedArray is !Sync by design — it wraps UnsafeCell, which prevents
the compiler from assuming immutability across threads. This is correct:
shared memory is inherently mutable by all threads in the block, and the
programmer is responsible for synchronization.
Alignment rules#
ALIGN is 0 (natural alignment) or a non-zero power of two. Any other
value is a compile error that names the use site.
Storage is never declared below align_of::<T>(). A smaller request is
raised silently, the way #[repr(align(N))] raises a struct; a larger
request is honored. SharedArray<u64, 2, 1> is therefore declared at 8
bytes, and a #[repr(C, align(16))] element at natural alignment is
declared at 16. Without the raise, a u64 array declared at 1 byte could be
packed right behind a byte array and fault with misaligned address.
Aggregate, nested-array and f16 elements at natural alignment declare
their natural alignment in PTX (.align 4 for [f32; N], .align 2 for
f16). Older releases printed a blanket .align 8 for them.

Shared-memory storage alignment. The verifier rejects an ALIGN that is not a non-zero power
of two at the use site, and lowering declares every static array and the dynamic pool at the
larger of the request and the element’s ABI alignment. SharedArray<u64, 2, 1> is declared
.align 8 and a #[repr(C, align(16))] element at natural alignment .align 16, where older
releases declared .align 1 and .align 8 and the kernel could fault with misaligned address.#
The API surface#
impl<T, const N: usize, const ALIGN: usize> SharedArray<T, N, ALIGN> {
    pub const UNINIT: Self;
    pub const fn len() -> usize;
    pub fn as_ptr(&self) -> *const T;
    pub fn as_mut_ptr(&mut self) -> *mut T;
    pub unsafe fn as_raw_mut_ptr(shared: *mut Self) -> *mut T;
}

// Indexing (unsafe access via static mut)
impl Index<usize> for SharedArray<T, N, ALIGN> { ... }
impl IndexMut<usize> for SharedArray<T, N, ALIGN> { ... }
Indexing is bounds-checked in debug builds. In release (and on the GPU),
the bounds check is elided. If you index out of bounds, you get undefined
behavior — the same rules as any static mut access in Rust.
Synchronization: sync_threads()#
thread::sync_threads() is a block-wide barrier. It compiles to PTX
bar.sync 0 and guarantees two things:
All threads in the block have reached the barrier before any proceed.
All memory writes by those threads are visible to all threads after the barrier (it acts as a memory fence for shared memory).
Without sync_threads() between the load and compute phases, some threads
might read a shared memory location before another thread has written it.
The hardware does not guarantee any ordering within a warp for shared memory
stores — even threads in the same warp can see stale values without a
barrier.
When to sync#
The rule is simple: sync before reading what another thread wrote.
Situation |
Need sync? |
|---|---|
Thread A writes |
Yes |
Thread A writes |
No (same thread) |
Overwriting a tile for the next loop iteration |
Yes (before the new load overwrites data threads might still be reading) |
Reading from |
No |
The tiled GEMM above has two sync points per iteration: one after loading (before computing) and one after computing (before the next load overwrites the tile). Missing either one is a data race.
Tip
A common mistake is putting sync_threads() inside a conditional branch
that not all threads take. Every thread in the block must reach the same
sync_threads() call, or the kernel will deadlock. If you need divergent
control flow, restructure so the barrier is outside the branch.
Compiler ordering around the barrier#
The hardware guarantee above covers visibility between threads. A second question is whether the compiler keeps your own accesses on the side of the barrier where you wrote them. Both backends emit the barrier as an operation that the compiler treats as reading and writing all memory:
The LLVM NVPTX route calls
llvm.nvvm.barrier.cta.sync.aligned.all. The call isconvergentand has nomemory(...)attribute.The libNVVM route emits
bar.sync 0;asasm sideeffectwith a~{memory}clobber.
Access form |
Kept on its side of |
Notes |
|---|---|---|
|
Yes |
A plain load or store in address space 3. |
|
Yes |
The same instructions as indexing. Prefer it to |
|
Yes |
A plain load or store through the returned pointer. |
|
Yes |
The call is |
|
Yes |
Adds |
|
No |
The call has no |
|
Yes, but see below |
Issue, commit and wait stay in order. The barrier does not wait for the copy to land. |
A |
No |
rustc merges reads through it before either backend runs. See below. |
A |
Yes |
A plain load that is re-read after each barrier. Two adjacent reads with nothing between them may still become one load. |
A reference to a |
Yes |
Each |
The indexing, as_raw_mut_ptr, DynamicSharedArray and both side-effecting
ptx_asm! rows were checked on both backends with a producer and consumer
kernel: store, barrier, load, barrier, store, barrier, load. The PTX keeps that
order for each of them. It keeps the same order when the loads sit in a loop
whose trip count is a kernel argument. A run on an RTX 5060 Laptop (sm_120)
read the expected neighbour values. A register_only ld.shared whose result
is unused leaves no instruction in the PTX. The same snippet with no options
stays. The cp.async and reference rows have their own tests below.
The table covers compiler ordering only. The rule under “When to sync” still decides where the barriers belong.
Raw pointers across the barrier#
Each thread derives its pointer from the raw address of the allocation and creates no reference to the whole array. A thread writes its own slot before the barrier and reads a neighbour’s slot after it:
static mut TILE: SharedArray<u32, 128> = SharedArray::UNINIT;

let tid = thread::threadIdx_x() as usize;
let tile = unsafe { SharedArray::as_raw_mut_ptr(&raw mut TILE) };
unsafe { tile.add(tid).write(tid as u32 + 1) }; // this thread's slot
thread::sync_threads();
let next = unsafe { tile.add((tid + 1) % 128).read() }; // a neighbour's slot
A kernel built from this snippet read the neighbour’s value in all 128 threads on both backends.
cp.async needs a wait before the barrier#
bar.sync does not wait for a pending cp.async. Each thread waits for its
own copies and then every thread meets at the barrier:
unsafe {
    cp_async_ca_4(dst, src);
    cp_async_commit_group();
    cp_async_wait_group(0); // this thread's copies have landed
}
thread::sync_threads(); // other threads may now read `dst`
Reading the destination before the copy completes is undefined behaviour. A
test kernel that drops cp_async_wait_group(0) and reads a neighbour’s slot
after the barrier can return the stale value: in a plain run on sm_120 all 128
threads did, and under compute-sanitizer every copy had landed first. The same
kernel with the wait returned the copied value in all 128 threads.
Bank conflicts#
Shared memory is divided into 32 banks (one per warp lane). If two threads in the same warp access different addresses that map to the same bank, the accesses are serialized — a bank conflict. The penalty is 2× latency for a 2-way conflict, up to 32× for a 32-way conflict.
The mapping is straightforward: consecutive 32-bit words map to consecutive
banks. So TILE[0] is in bank 0, TILE[1] is in bank 1, …, TILE[32]
is back in bank 0. A common conflict-free access pattern is:
// Each thread reads a different column: thread k reads TILE[row + k]
// If TILE_WIDTH = 32 (or a multiple), add padding: SharedArray<f32, 33 * 16>
For the 16×16 tiled GEMM, there are no bank conflicts in the inner loop
because TILE_A[ty * 16 + i] reads a row (consecutive elements = different
banks) and TILE_B[i * 16 + tx] reads a column with stride 16.
See also
CUDA Programming Guide — Shared Memory Bank Conflicts for a detailed treatment of bank conflict rules and padding strategies.
Putting it all together#
Here is the progression from naive to tiled, applied to the GEMM from our MLP pipeline:
Version |
Global loads per thread (64×64) |
Shared loads per thread |
Speedup |
|---|---|---|---|
Naive ( |
128 |
0 |
1× |
Tiled (16×16 tiles) |
8 (4 iterations × 2 tiles) |
128 |
~4–10× |
Tiled + double buffering |
8 |
128 (overlapped) |
~6–15× |
The tiled version trades global memory bandwidth for shared memory bandwidth
and computation — a good trade when the kernel is memory-bound. The
double-buffered variant overlaps the next tile’s load with the current tile’s
computation, hiding even more latency, but requires two SharedArrays per
matrix and more complex synchronization.
See also
Warp-Level Programming — shuffle-based reduction as an alternative to shared memory for small reductions
Tensor Memory Accelerator — hardware- accelerated global→shared copies that replace the manual load loop