TMA Pipelines, Tensor Cores, and cutlass-primitives Interop#
The Blackwell kernels in this preview combine multi-stage TMA pipelines, swizzled shared-memory views, and tensor-core MMA operations. Depending on the workload, you can express the entire schedule in cute-rs (blockscale_gemm_cute) or pair cute-rs with cutlass-primitives instruction primitives in the same kernel (fp16_gemm_256x352_cute, sm100_fmha_prefill_cute, sm100_mla_decode_fp16_cute).
1. Block-Scaled MXFP4 GEMM in cute-rs (SM120a)#
In blockscale_gemm_cute, one producer warp (warp 8) fills a 3-stage TMA ring buffer in shared memory while eight compute warps (warps 0..7) load swizzled FP4 fragments and Float8E8M0FNU scales into Mxf4TiledMma:
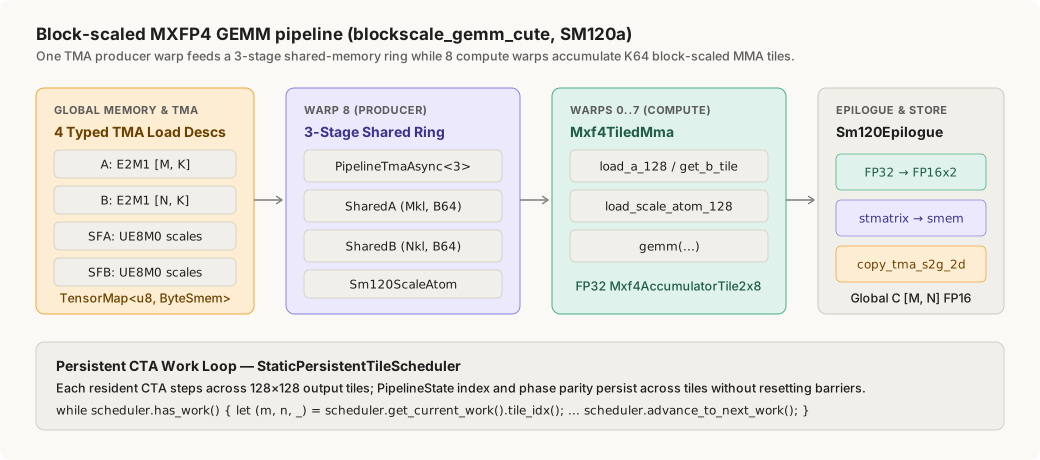
Data flow of blockscale_gemm_cute on SM120a: 4 typed TMA descriptors feed a 3-stage PipelineTmaAsync, consumed by 8 compute warps running Mxf4TiledMma and an Sm120Epilogue128x128 TMA store epilogue.#
// Shared-memory layouts and operand-role views (Mkl for A, Nkl for B)
type TileP    = Layout<(C<128>, C<32>), (C<32>, C<1>)>;
type SmemP    = ComposedLayout<Swizzle<2, 3, 3>, 0, TileP>;
type ByteSmem = ComposedLayout<Swizzle<2, 4, 3>, 0, RowMajor<128, 64>>;
type SharedA  = SharedTensor<Mxf4E2M1, f16, SmemP, Mkl>;
type SharedB  = SharedTensor<Mxf4E2M1, f16, SmemP, Nkl>;

// Compute warps (0..7) wait on the TMA slot, load fragments + scales, and accumulate:
pipeline.consumer_wait(&consumer);
let slot = consumer.index();
let s_a = unsafe { SharedA::from_raw_parts(smem_base.add(slot * STAGE_BYTES).cast()) };
let s_b = unsafe { SharedB::from_raw_parts(smem_base.add(slot * STAGE_BYTES + B_OFF).cast()) };

let scale_tile = unsafe { tiled_mma.load_scale_atom_128(&s_sfa, &s_sfb, wm, wn) };
let mut kk = 0usize;
while kk < 2 {
    let scales  = unsafe { scale_tile.pairs_at_unchecked(kk) };
    let a_frags = unsafe { tiled_mma.load_a_128(&s_a, wm, kk) };
    let b_frags = unsafe { tiled_mma.get_b_tile_k64(&s_b, wn, kk) };
    accumulators.gemm(&tiled_mma, a_frags, b_frags, scales);
    kk += 1;
}
pipeline.consumer_release(&consumer);
consumer = consumer.advance();
2. Two-CTA GEMM and TMEM Epilogues on SM100a#
On datacenter Blackwell (sm_100a), two CTAs cooperate on a 256×352 output tile (256×192 + 256×160 N-partitions sharing the A collector) and accumulate into Tensor Memory (TMEM).
fp16_gemm_256x352_cute expresses its cluster TMA, 5-stage PipelineTmaUmma, accumulator PipelineUmmaAsync, paired Sm100TiledMma, collective Sm100Tmem::<512>, and Sm100TmemEpilogue slices directly through cute-rs (dialect-cute):
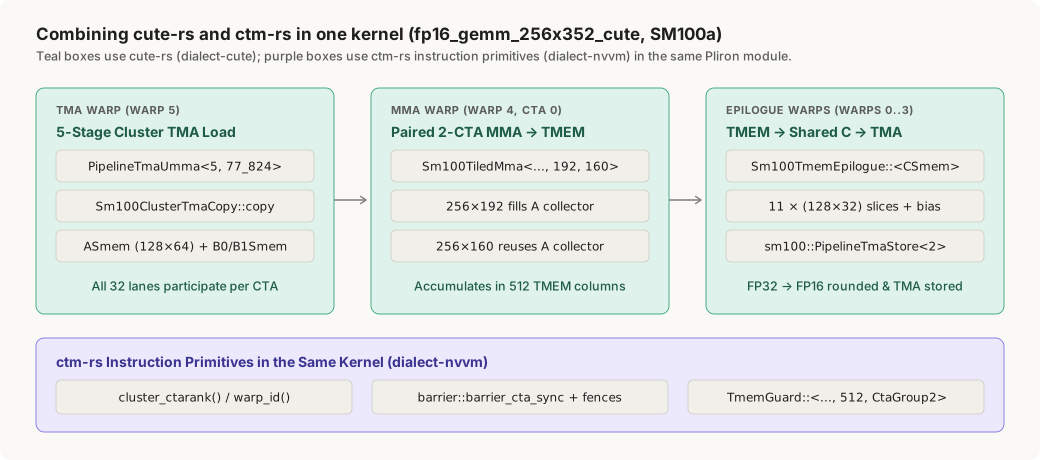
In fp16_gemm_256x352_cute, cute-rs owns the 5-stage cluster TMA pipeline, paired 2-CTA MMA, collective Sm100Tmem lifecycle, and TMEM epilogue, while cute_rs::arch supplies cluster rank, barriers, and warp elections.#
// Producer warp (warp 5): acquire the stage, let one elected lane post the
// expected bytes, then all 32 lanes issue the cluster TMA copies via cute-rs
pipeline.producer_acquire(stage as u32, phase);
if rank == 0 && elect_one_sync() {
    pipeline.producer_expect_tx(stage as u32);
}
let barrier = pipeline.producer_get_barrier(stage as u32);
Sm100ClusterTmaCopy::copy(a, &mut a_tile, row, kt * 64, barrier, rank);
Sm100ClusterTmaCopy::copy(b0, &mut b0_tile, col, kt * 64, barrier, rank);
Sm100ClusterTmaCopy::copy(b1, &mut b1_tile, col + 192, kt * 64, barrier, rank);

// MMA warp (warp 4, CTA rank 0): paired 2-CTA MMA into TMEM
pipeline.consumer_wait(stage as u32, phase);
if elect_one_sync() {
    mma.gemm(tmem, &a_tile, &b0_tile, &b1_tile, accumulate);
    pipeline.consumer_release(stage as u32);
}

// Epilogue warps (warps 0..3): allocate 512 TMEM columns and drain 11 slices via cute-rs
if warp_id == 0 {
    Sm100Tmem::<512>::alloc(tmem_token);
}
3. Vera Rubin (sm_107a): K = 64 MXFP8, B-Collector Reuse, and PDL#
Vera Rubin (sm_107a) keeps the same tcgen05 and TMEM programming model as SM100, and adds two hardware upgrades that cute-rs exposes directly in types:
Deeper
K = 64MXFP8Tensor Cores (SM107BlockScaledMmaMXF8F6F4Op): Every 32Float8E4M3FNvalues share one power-of-twoUE8M0scale byte (Sm1xxBlockScaleKMajor<32>). OneK = 128TMA stage holds a single 512-byte scale atom and feeds twoK = 64MMA instructions (sub_k = 0and1).Hardware B-collector reuse (
CollectorFill+CollectorLastUse): When a CTA computes a tall256x128output tile from two128x128Ahalves (a0,a1) and one shared128x128Btile, the first MMA stashesBinside the Tensor Core’s B-collector so the second MMA reusesBwithout touching shared memory again:
type ATileSmem = ComposedLayout<Swizzle<3, 4, 3>, 0, RowMajor<128, 128>>;
type BTileSmem = ComposedLayout<Swizzle<3, 4, 3>, 0, RowMajor<128, 128>>;
type MmaBKeep  = SM107BlockScaledMmaMXF8F6F4Op<ATileSmem, BTileSmem, 128, 128, 1, CollectorFill>;
type MmaBReuse = SM107BlockScaledMmaMXF8F6F4Op<ATileSmem, BTileSmem, 128, 128, 1, CollectorLastUse>;

// Copy each 512-byte UE8M0 scale atom into 4 TMEM columns, then run both K=64 steps:
MmaBKeep::copy(sfa0_col, &sfa0_tile, 0);
MmaBKeep::copy(sfa1_col, &sfa1_tile, 0);
MmaBKeep::copy(sfb_col,  &sfb_tile,  0);
mma_keep.gemm(tmem,       &a0_tile, &b_tile, sfa0_col, sfb_col, 0, accumulate); // stashes B
mma_reuse.gemm(tmem + 128, &a1_tile, &b_tile, sfa1_col, sfb_col, 0, accumulate); // reuses B
Both Rubin GEMM examples (sm107_bf16_gemm_cute and sm107_mxfp8_gemm_cute) also show Programmatic Dependent Launch (PDL) via cute_rs::arch::{griddepcontrol_wait, griddepcontrol_launch_dependents}, which lets the next kernel in a chain start prefetching weights while the previous kernel finishes writing its last output tiles.
Where to Go Next#
Workload |
Location |
Highlights |
|---|---|---|
Elementwise / SwiGLU / RMSNorm |
|
1D tiling, register transforms, warp reductions, and ragged tails. |
FFN & RoPE KV-Cache Attention |
|
BF16 tensor-core projections, typed weight roles, and 128-wide GQA. |
MXFP4 GEMV & Block-Scaled GEMM |
|
Packed FP4 + |
SM100a 2-CTA GEMM & Attention |
|
Two-CTA cluster TMA, TMEM ping-pong, FMHA/MLA, and fused QKV + FP8 KV. |
Vera Rubin ( |
|
2-CTA BF16 ( |
Nemotron-3 NVFP4 ReLU² MoE |
|
Block-scaled NVFP4 ( |
Qwen3-8B (BF16 & NVFP4) |
|
36-layer |
End-to-End Qwen3-TTS Model |
|
Complete Talker + Predictor speech synthesis on SM120a ( |